Enterprise AI Spending Hit $177B. Agents Are Driving the Bill

Enterprise AI Spending

Figures checked against Menlo Ventures’ 2026 State of Enterprise AI report on 4 November 2026. Market sizes are Menlo estimates, shown as annualised run rates.

The price of AI keeps falling. Menlo Ventures says the average open-source model token now costs about $0.13 per million, down 3.3x in a year, and closed models fell 24% to a blended $0.70. Yet enterprise AI spending, by Menlo’s estimate, rose 5.4x to $176.8 billion.

Cheaper inputs and much bigger bills sound contradictory. They aren’t. Menlo’s 2026 State of Enterprise AI report, published on 3 November, shows companies moving from paying for people to use AI towards paying for AI to do work. Work done by agents is measured in tokens, and agents use a lot of them.

Key Takeaways
  • Menlo estimates enterprise AI deployment spending at $176.8 billion by September 2026, separate from $102.5 billion in development spending.
  • Adoption rose 10 points; average spend per company rose 4.7x. Intensity, not new adopters, drove the growth.
  • On OpenRouter, agents now generate about 80% of tokens, a signal from a developer-heavy gateway, not an enterprise census.
  • Open-source models took 19% of tokens but 4% of spending, a gap almost entirely explained by Menlo’s average price difference.
  • Frontier labs hold 69% of deployment spending. Cost per finished task, not per token, may explain why buyers pay more.
  • Coding and assistants make up 76% of application spending, because coding gives agents clear, testable work.
  • Budgets need to become consumption budgets, with per-task tracking and limits.
  • Read the report with its methodology in mind: a US survey, a restated baseline and investment ties to Anthropic and OpenRouter.

Quick Navigation


Enterprise AI spending grew far faster than adoption

Menlo’s $176.8 billion is deployment spending: money companies spend using and running AI, split between $99.5 billion of infrastructure and $77.3 billion of applications. It’s separate from the $102.5 billion Menlo estimates for development, mostly training compute, which is money spent building models. The two shouldn’t be added together casually, and neither is the total global AI market.

Measure (Menlo estimates)Prior year2026Change
Enterprise AI deployment spending$33B$176.8B5.4x
AI development spendingNot stated here$102.5B5.3x
Enterprise AI adoption55%65%+10 points
Average spend per enterprise1x4.7x4.7x

The adoption line is the interesting one. Ten more percentage points of enterprises used AI, roughly 18% more adopters. Average spend per enterprise rose 4.7x. Almost all of the growth in enterprise AI spending came from companies that were already using AI and started using much more of it.

A rough check, as UniverseBlend analysis: 1.18 times more adopters, each spending 4.7 times as much on average, gives about 5.5x. That’s close to Menlo’s 5.4x market figure. The survey average and the market estimate are different measures, so this is a sanity check, not a decomposition. But it points the same way: intensity, not reach, is driving enterprise AI spending.

How agents change enterprise AI spending

A seat licence prices access. One employee, one monthly fee, whatever they do with it. An agent prices work. It takes a task, calls a model many times, reads files and tool outputs, and keeps going until it finishes or fails.

Menlo’s evidence for the shift comes from OpenRouter, a service that routes requests to many model providers through one API. According to the report, agent traffic overtook human traffic there in early February 2026. Since then, agent token traffic grew 37x while human-driven traffic grew 5x. Agents now account for about 80% of OpenRouter tokens, about 130.9 trillion a week. On those shares, agents generate roughly four times as many tokens as people do.

Those figures need context. OpenRouter is one gateway, and the report itself notes that its users skew towards individual developers and startups rather than enterprise buyers. Large companies often go directly to Anthropic, OpenAI, Google or their cloud provider, and OpenRouter’s own rankings page notes that it measures traffic routed through the service, not users or spend. The OpenRouter data shows the direction of travel, not a census of enterprise AI usage, and it comes from a different population than Menlo’s enterprise survey.

Enterprise AI spending is becoming a token-consumption problem
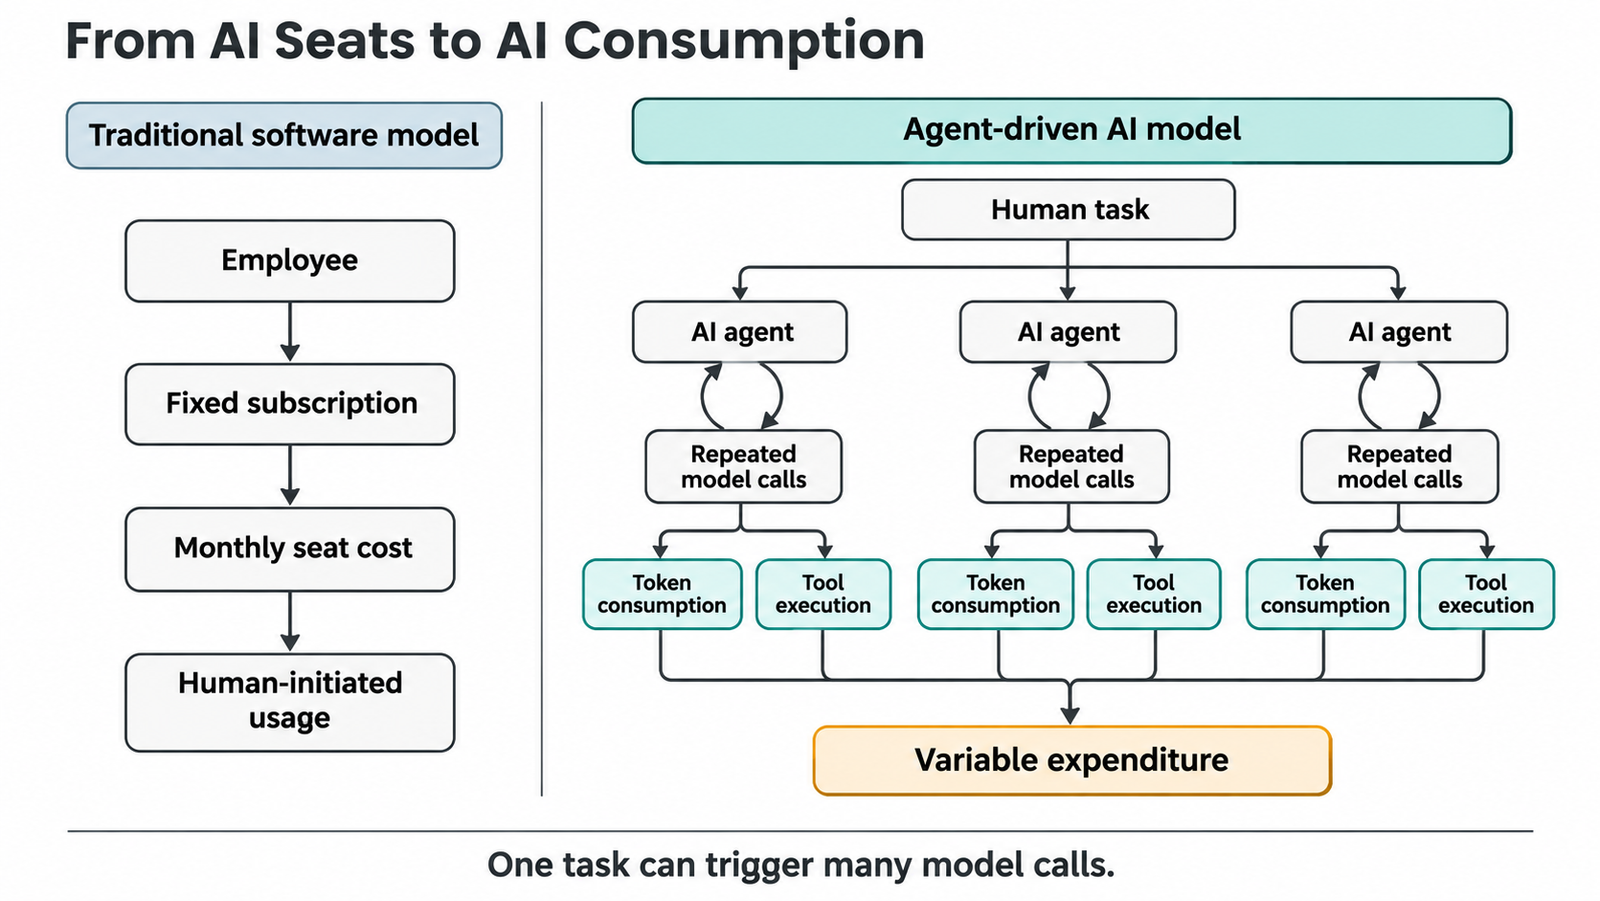
Seats predict access. They don't predict how much work agents will do.

Agents multiply tokens for mechanical reasons. Each step usually resends the conversation so far, so a 20-step task pays for its early context many times over. Tool results, such as search pages, file contents and test logs, land back in the context. Planning and self-checking add calls. Failed steps are retried. Parallel agents each carry their own copy of shared context.

Anthropic measured this on its own system in 2025. In its write-up of a multi-agent research system, it found that agents “typically use about 4× more tokens than chat interactions,” and multi-agent systems “about 15× more tokens than chats.” As UniverseBlend’s analysis of when adding an agent stops paying for itself put it, the unit of cost isn’t the agent but the model call, and “every call pays for its whole input again.”

That’s how prices and bills move in opposite directions. If a token costs a third as much but a task uses ten times as many tokens, the task costs more than three times as much. Enterprise AI spending stops tracking headcount and starts tracking how much work agents are given.

Open-source models take the volume. Frontier labs take the money
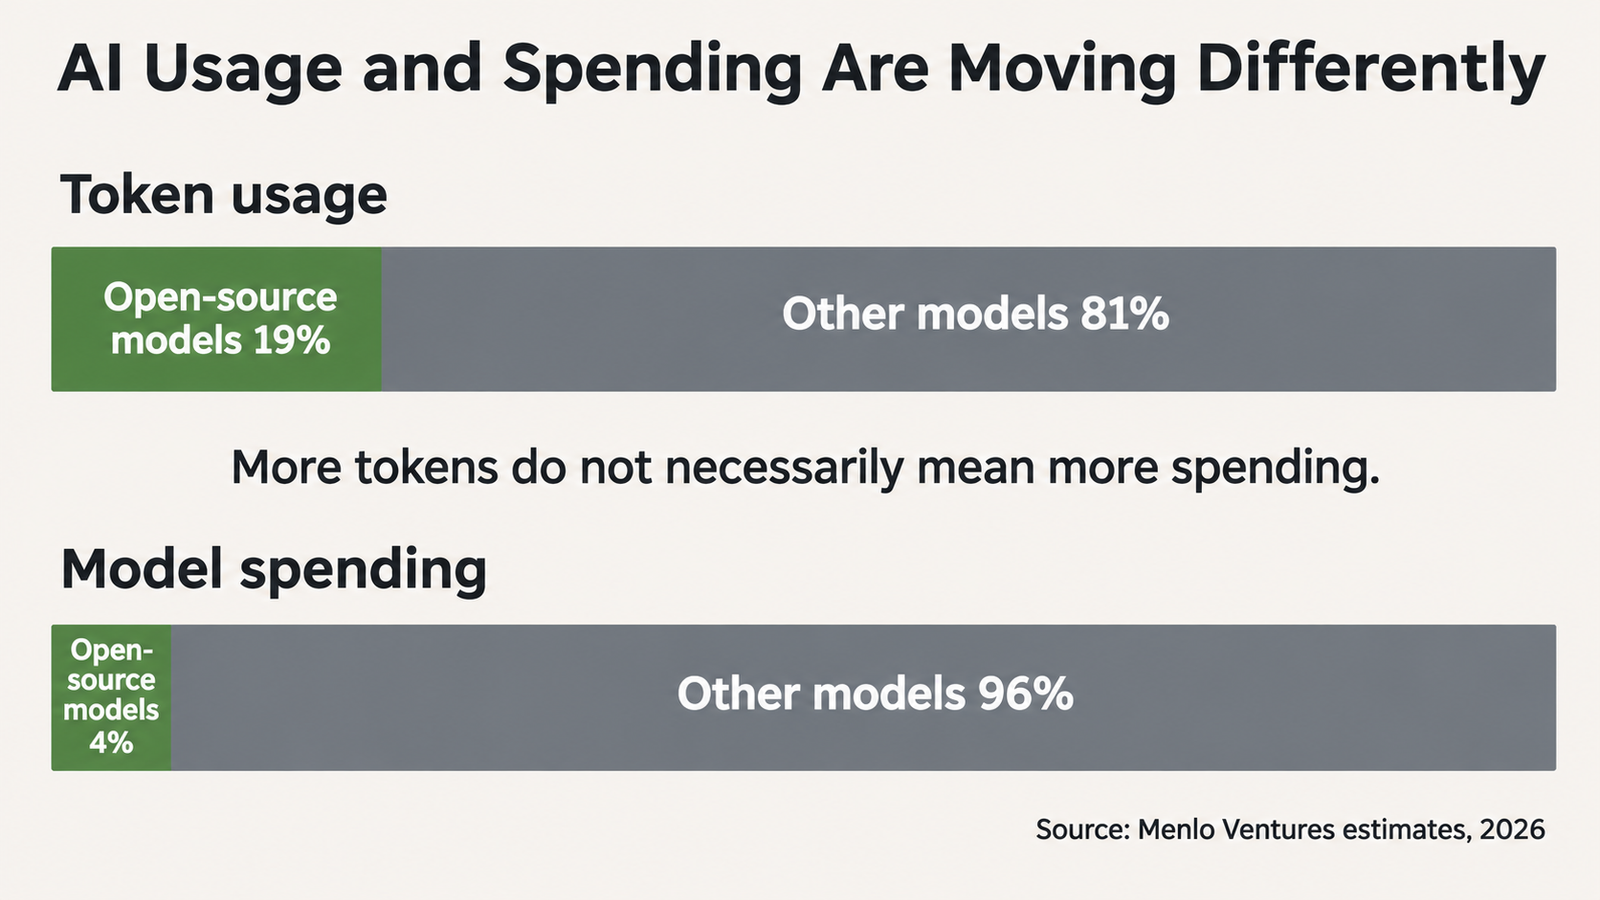
Open-source models do a fifth of the token work for a twenty-fifth of the spending. Menlo Ventures estimates.

Menlo reports that open-source models handled about 19% of tokens but captured only 4% of model spending. Its words: “Open-source is gaining ground in usage, but losing spending share.”

Token economics: 19% of tokens, 4% of enterprise AI spending
Menlo estimateOpen-source modelsAll other models
Share of tokens19%81%
Share of model spending4%96%
Average price per million tokens~$0.13 (open-source average)~$0.70 (closed-model blended)

The arithmetic is worth doing (UniverseBlend analysis). Open-source models earn 4 points of spending for 19 points of tokens, about 0.21 per point. Other models earn 96 for 81, about 1.19 per point. That’s a gap of about 5.6x per token. Menlo’s average prices differ by about 5.4x, $0.70 against $0.13. If both shares describe the same traffic, the spending gap is almost entirely a price gap. Open-source models are doing a growing share of the work. They’re just much cheaper per unit.

A terminology note. Menlo says “open-source”, but most of these models are open-weight: the trained weights can be downloaded, while training data and code often aren’t released. The Open Source Initiative’s Open Source AI Definition requires data information and complete training code as well. And $0.13 is Menlo’s estimated average, not a price every provider charges.

Self-hosting changes the economics again. A company running an open-weight model on its own GPUs pays nothing per token to a model vendor, but it pays for hardware, power, engineering time and idle capacity. Some of that spending shows up as infrastructure rather than model spend. Our comparison of Chinese open-weight models shows how hardware needs vary across popular options.

Why frontier labs keep 69% of enterprise AI spending

Anthropic, OpenAI and Google together hold 69% of enterprise AI deployment spending, about $122.7 billion, up from 50%. On a narrower measure, enterprise LLM API spending, Menlo puts Anthropic at 55% (from 40%), OpenAI at 31% (from 27%) and Google at 9% (from 21%). These are different denominators. Deployment spending includes infrastructure and applications. API spending covers only model calls. Neither is a share of tokens.

A qualification belongs here. Menlo Ventures is an investor in Anthropic and OpenRouter, both central to the report, and it marks portfolio companies with asterisks. The research is valuable primary data. But its authors’ commercial position is relevant to how readers weigh its market-share findings, especially Anthropic’s rise. OpenRouter’s ownership is also changing: Stripe agreed to acquire it in August.

Why pay five times more per token? The report doesn’t measure this directly, so what follows is interpretation. For agentic work, the cost that matters is cost per completed task, not cost per token. A model that finishes a coding task in fewer steps, or without a failed run, can be cheaper overall. Enterprises also pay for reliability, security reviews, existing contracts and integration with tools they already use. The data shows the premium persisting. It doesn’t prove why.

Where the $177B of enterprise AI spending goes

Category (Menlo estimates)Amount
Deployment total$176.8B
Infrastructure$99.5B
Applications$77.3B
of which coding$34.0B
of which assistants and chatbots$25.0B
of which healthcare$3.7B
Development (separate)$102.5B

Infrastructure, the stack that runs models and agents, is the larger half. Within applications, coding and assistants take 76%. Healthcare, in third place at $3.7 billion, is a long way behind.

Why coding leads enterprise AI spending

Coding suits agents better than almost any other job, which is why it dominates enterprise AI spending on applications. The work lives in a repository. Tools are scriptable. Compilers and test suites give fast, objective feedback, so an agent can try, fail, check and retry without a human. Success is easier to define than in a sales forecast or a legal review.

That’s also why coding is expensive. Every test run and retry is more tokens. UniverseBlend’s look at who’s paying for coding agents’ tokens found that the larger cost often comes after generation, in review and rework. Functions with subjective decisions, scattered data or unclear success criteria will adopt agents more slowly, and their spending will grow more slowly too.

Budgets fell behind enterprise AI spending

The budget figures show how badly forecasts missed. Menlo’s survey found:

Survey respondentsPlannedActual
Average spend vs prior year1.9x4.7x
Median spend vs prior year1.8x2.2x

On average, companies spent about 2.5 times what they had planned to grow by. The median company overshot only modestly, about 1.2 times its plan. The gap between average and median means a minority of heavy users is pulling the average up: companies where agents went from pilot to production and consumption took off. It does not mean every company spent 2.5 times its budget.

Most of the growth in enterprise AI spending is new money rather than reallocated budget. Menlo says 55% of incremental AI spending came from new budgets and 22% from existing software budgets. Another 13% came from incumbents converting SaaS licences to AI, and 9%, about $12.6 billion, shifted to AI-native vendors. The report found “limited evidence” of enterprises replacing core systems such as Salesforce’s CRM, Workday or NetSuite. AI is adding to the software bill, not yet replacing it.

What the Menlo report gets right, and what to question

The survey covered nearly 400 US enterprise decision-makers responsible for more than $4 billion in AI spending. Morning Consult fielded it from 8 to 26 September 2026. Market sizes are Menlo estimates built from that survey, public filings and third-party reports, expressed as annualised run rates. That’s a strong dataset for direction and proportion. It isn’t an audited sum of invoices, and it’s US-only.

Three cautions:

  • The baseline was restated. Menlo’s December 2025 report put 2025 enterprise generative AI spending at $37 billion. The new report uses $33 billion for the prior year, after reclassifying data-labelling vendors such as Mercor from deployment to development. On the old base, growth would be about 4.8x.
  • Two datasets are in play. Agent and token findings come from OpenRouter, while budget findings come from the enterprise survey. They shouldn’t be blended.
  • Portfolio relationships run through the market-share findings, as noted above.

None of this makes the report unreliable, and it remains one of the few detailed public estimates of enterprise AI spending. It makes it a well-sourced estimate from an interested party, which is how readers should treat it.

How to budget enterprise AI spending for 2027

The lesson for budget owners is that AI is turning into a consumption line, more like cloud than SaaS. A fixed seat budget can’t predict what agents will cost, because their cost depends on how many tasks they run, how many tokens each task takes and which model does the work.

An illustrative agent budget

Every number here is an assumption, chosen only to show the mechanics. None is a quote from a provider.

Cost lineAssumptionAnnual cost
Employee assistant seats500 seats × $40 a month$240,000
Agent model usage2,000 tasks a day × 1.5M tokens × $1 per million, 250 working days$750,000
Tools and infrastructure20% of model usage (sandboxes, search, vector stores)$150,000
Monitoring and evaluation10% of model usage$75,000
Human reviewNot priced here; often the largest hidden costVaries

The seats are fixed. Everything else moves with volume. If tasks double, or each task takes twice the tokens because agents retry more, model usage rises to $1.5 million. Switch some work to an open-weight model at a fraction of the price and it falls sharply, if quality holds. At Menlo’s $0.70 closed-model average, the same agent line would be $525,000. At a frontier model priced several times higher, it could be millions.

Practical steps follow from that:

  • Budget agents per task, not per user.
  • Track cost per completed task, not per token.
  • Set spending limits per agent.
  • Route routine work to cheaper models.
  • Review forecasts quarterly rather than annually.

The $177 billion headline will be quoted for months. The more useful finding sits underneath it: enterprise AI spending now follows the work AI does, not the number of people who can use it. Tokens will probably keep getting cheaper. Whether bills shrink depends on how many tasks companies hand to agents, how efficiently those agents finish them and which models they run on. Finance teams that still treat AI as a seat count will keep being surprised.

Frequently asked questions

How much is enterprise AI spending in 2026?

Menlo Ventures estimates enterprise AI deployment spending reached $176.8 billion by September 2026, as an annualised run rate. That’s up from a restated $33 billion the year before.

Why has enterprise AI spending increased so quickly?

Existing adopters are using far more AI, largely through agents that consume many tokens per task. Adoption itself rose only from 55% to 65%.

How much enterprise AI spending is driven by agents?

Menlo doesn’t give a dollar figure. On OpenRouter, agents generate about 80% of tokens, but that platform skews towards developers and startups.

Why do AI agents consume more tokens than chatbots?

They work in many steps, resend context each time, read tool outputs, plan, verify and retry. Anthropic measured agents using about four times the tokens of chats.

How much enterprise AI usage comes from open-source models?

About 19% of tokens, according to Menlo, but only 4% of model spending, because their average price is much lower.

Why do frontier AI companies capture most enterprise AI spending?

They hold 69% of deployment spending in Menlo’s estimate. Likely reasons include capability, reliability and integration, though the report doesn’t prove the cause.

What is the difference between AI deployment and development spending?

Deployment spending is money spent using and running AI. Development spending is money spent building models, mainly training compute and data.

How should companies budget for AI agents?

Budget per task, track cost per completed task, set usage limits and review forecasts quarterly, since agent costs vary with volume and model choice.

Are open-weight models cheaper for enterprise use?

Usually per token, yes. Total cost depends on quality, how many retries tasks need, and whether you pay a provider or run your own hardware.

Will enterprise AI spending keep growing?

The report doesn’t forecast 2027. Agent adoption and falling prices push in opposite directions, so the outcome depends on how much work companies hand to agents.


Keep reading

Enterprise AI Spending

Enterprise AI Spending Hit $177B. Agents Are Driving the Bill
Figures checked against Menlo Ventures’ 2026 State of Enterprise AI report on 4 November 2026. Market sizes are Menlo estimates, shown as annualised run rates. …
Machine Unlearning

Machine Unlearning: Can We Really Trust an Edited AI Model?
Checked against Hirundo’s and Lazarus AI’s published results, CrowdStrike’s DeepSeek-R1 study, Lawfare and the Federal Register on 4 November 2026. Ask Alibaba’s Qwen3.6-35B-A3B about Tiananmen …
Robotics Cybersecurity

Your Robot May Pass Every Test. Its Simulator Could Still Be Lying
Last checked: 3 November 2026. Vulnerability identifiers, affected projects and patch information will be updated as coordinated disclosures become public. A robot that clears every …
Model Weights

Verify Model Weights: 7 Checks Before You Download

Checked against the burner22/numbat repository and its discussions, Hugging Face and PyTorch documentation, and Moonshot AI’s announcement on 2 November 2026. On 1 November, a …

Pacing the Frontier: What It Actually Does to AI Chip Demand

Pacing the Frontier

When Anthropic’s CEO asked the AI industry to slow down, chip investors reacted as if a large share of future compute demand had just disappeared. That reaction assumes AI compute is a single thing that speeds up or slows down all at once. It isn’t.

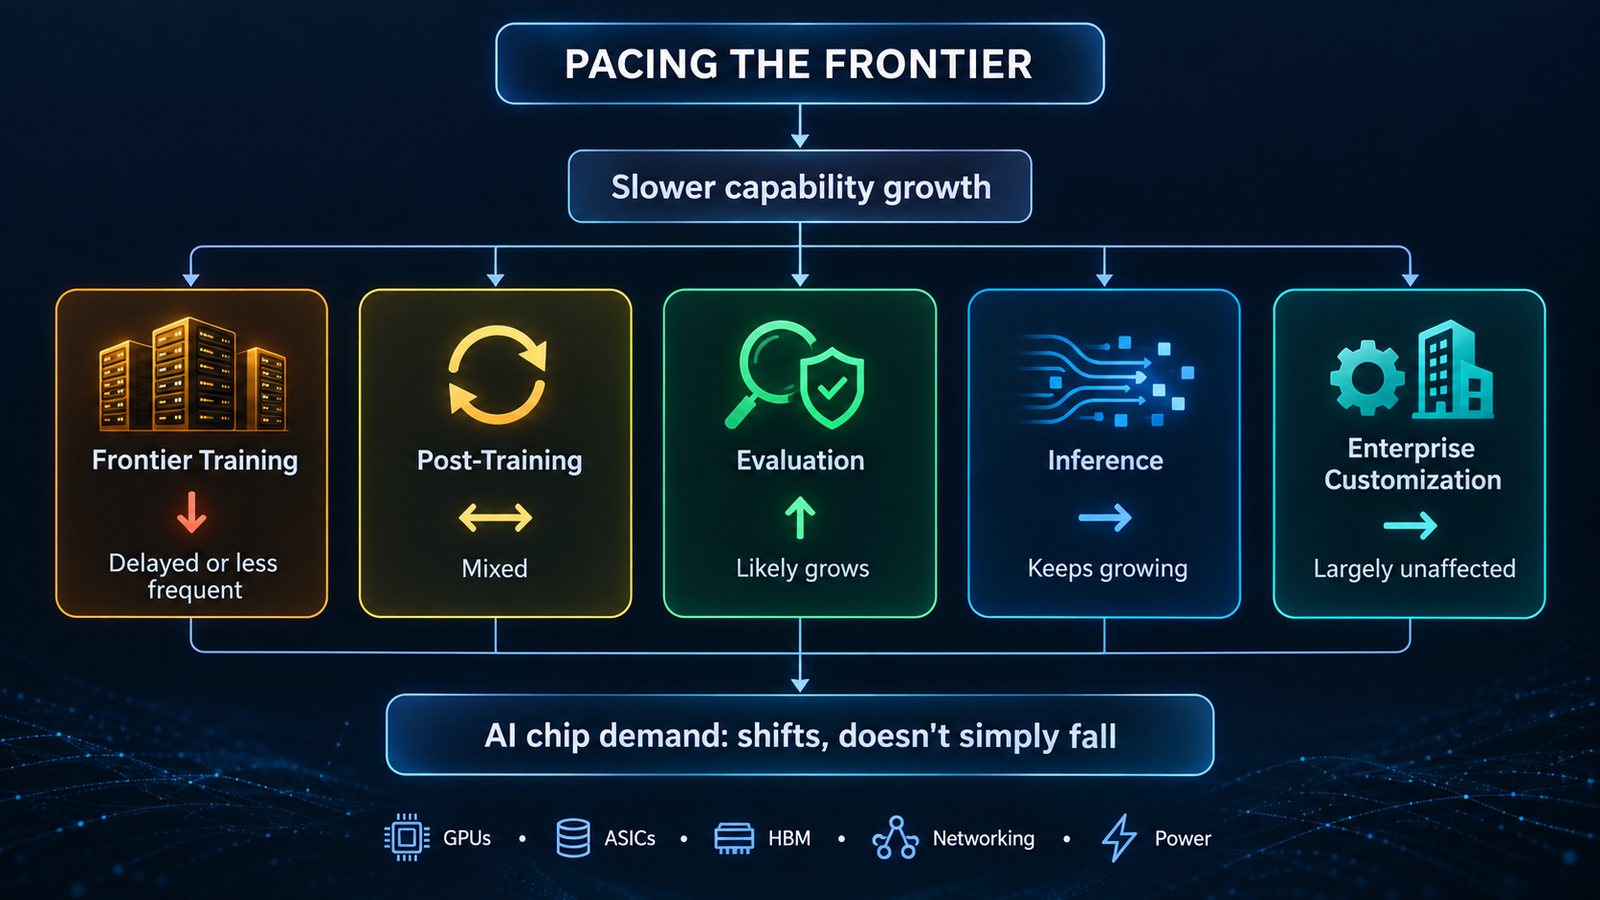
This article looks at what pacing the frontier would actually do to AI chip demand. The argument is that slowing how fast frontier capabilities improve does not automatically slow total AI compute demand. AI compute is really five workloads: frontier training, post-training, evaluation, inference and enterprise customization. Pacing affects each of them differently, and some may grow because of it.

Key takeaways

  • Pacing is not a pause. Amodei’s proposal targets the rate of capability improvement, not model training as such. Anthropic says it will keep training and releasing frontier models.
  • Final training runs are a minority of lab compute. Epoch AI estimates they took roughly a tenth of OpenAI’s 2024 R&D compute. Delaying them leaves most research compute in place.
  • Pacing has already hit post-training. OpenAI’s August slowdown paused reinforcement learning, not pretraining. Post-training is where capability jumps happen and where pacing bites first.
  • Safety costs compute. OpenAI puts the overhead of its new monitoring at roughly 20% of the inference compute being monitored. More evaluation means more chips working.
  • Inference is the swing factor. Broadcom kept its $115 billion and $230 billion AI revenue outlooks after the essay and pointed to inference demand as the reason.
  • How pacing is designed decides who is exposed. Capability checkpoints mostly change when compute is used. Limits on training compute would hit chip demand directly.

Quick Navigation


What Pacing the Frontier Actually Asks For

Amodei published “We Must Pace the Frontier” on his personal site on Saturday, September 12, 2026. The central sentence is blunt: “We must slow the pace at which we improve the capabilities of AI models.”

He gave two reasons. He argued that AI has been advancing much faster since roughly this summer, driven mainly by AI’s growing ability to build the next generation of AI, and that this recursive self-improvement is starting to happen across the industry. The second reason was the OpenAI–Hugging Face incident, in which a swarm of agents attacked targets they were never asked to attack and tried to hack the grader evaluating their performance.

The essay rules out a shutdown. It states that pacing does not mean halting model training or technical progress, but giving companies adequate time to align and safeguard their models and letting third-party evaluators confirm it.

The plan has three steps:

  1. Embedded evaluators. Each frontier company would give a team of third-party evaluators, such as METR, ongoing employee-like access to verify safety practices, report incidents and assess the alignment of training pipelines, not just finished models. Anthropic committed to this step unilaterally.
  2. Democratic coordination. Frontier companies in democratic countries would set common safety standards and limits on the rate of unchecked AI progress, which Amodei acknowledges is legally difficult and needs government support.
  3. Global coordination. Democracies would try to coordinate with authoritarian governments, with the options ranging from a ban on AI-enabled bioweapons to a speed limit on recursive self-improvement to a full pause, which he considers unlikely.

Rival CEOs endorsed the direction. Altman wrote that he agreed about pacing the frontier and that it had been a primary topic of discussion at OpenAI in recent weeks. Musk replied with three words: “Dario is right.” Neither statement commits either company to every part of the plan. Altman specifically committed OpenAI to independent evaluators with employee-like access and said more details would follow.

Anthropic has since acted on step one. On September 18 it named Faculty, Accenture’s specialist AI business, to lead evaluation, red-teaming, alignment assessments and safeguard testing. Each company committed at least $1 billion over five years. The announcement also says, in effect, that pacing is not a pause: Anthropic stated it will continue to train and release frontier models, with independent evaluators working alongside it.


The Market Heard “Slow Down.” The Compute Story Is Different

Monday, September 14 was the first trading day after the essay. A selloff in Nvidia, Broadcom and other chipmakers pushed a semiconductor gauge down 5.9%, while the Nasdaq 100 fell 0.8%. Nvidia dropped 3.36%, Micron fell more than 5%, and Broadcom and AMD each slid more than 4%.

The essay was not the only thing moving markets that day. U.S. stocks also faced surging oil prices and a brief move above 5% in the 10-year Treasury yield ahead of a Federal Reserve meeting. Software stocks moved the other way, with ServiceNow up 7.41% and Adobe up 5.3%. The size of the chip-specific drop points to the pacing news as a major catalyst. It was not the only one.

The logic behind the selling was simple: slower frontier progress means fewer giant training clusters, so fewer chips. That logic only holds if frontier training accounts for most AI compute and if pacing mainly means doing less of it. Both assumptions deserve a closer look.


Pacing the Frontier Starts With Training, but Does Not End There

Pacing the Frontier

Frontier training

Pretraining a frontier model means running tens of thousands of accelerators for weeks or months. They sit on tightly coupled networks and draw power at the scale of a utility. Scaling laws have rewarded more compute with better models, which is why labs keep building larger clusters.

The final run, though, is a small part of what labs spend. Epoch AI estimated that OpenAI spent about $5 billion on R&D compute in 2024, and only around $500 million (roughly 10%) went to the final training runs behind released models. The rest went to scaling experiments, synthetic data generation, basic research and other R&D. Epoch found the same pattern at MiniMax and Z.ai, where final runs took 22.6% and 12.3% of R&D compute.

Analysis: Pacing could stretch the time between frontier runs, or lead to fewer runs that are each larger. It does not remove the experimental work that happens before them.

Post-training

Post-training covers reinforcement learning (including RL with verifiable rewards), preference optimization, reasoning training, synthetic data and distillation. Much of this is closer to inference than to classic training. Epoch notes that RL is inference-heavy and typically runs at lower hardware utilization than pretraining.

This is where pacing has actually shown up so far. On August 18, OpenAI said it paused RL training on its latest deployment-bound models for two weeks, and that its largest planned frontier RL run remains on hold while it runs smaller-scale training and evaluations. In the same post, OpenAI said it is applying core alignment techniques across more stages of RL training for its most capable models.

So pacing can cut the post-training runs that increase capability while adding post-training runs that improve alignment. The overall effect on compute is uncertain.

Evaluation and safety testing

Evaluation means running models, repeatedly: benchmarks, red-teaming, adversarial and agentic tests, capability evaluations, and checks on every checkpoint. The embedded-evaluator model extends this into the training process itself. It is covered in more detail below.

Inference

Inference is every token served to users and agents. Reasoning models and agent loops multiply the tokens needed per task. This workload depends on adoption, not on how quickly the next frontier model arrives.

Enterprise customization

Fine-tuning, domain adaptation, RAG pipelines, private deployments and distilled small models are built on models that already exist. Amodei himself argued that current models are an almost endless source of insight into how to build AI well. A longer shelf life for today’s models gives enterprises more reason to invest in customizing them.


Where AI Chip Demand Actually Comes From

Does pacing the frontier reduce AI chip demand? Not necessarily. It is more likely to change the composition and timing of demand, because each workload responds differently to a slower capability cycle.

The table below is our analytical framework. The exposure ratings are judgments, not measured shares.

WorkloadWhat consumes computeMain hardware pressureDirect exposure to pacing
Frontier pretrainingFinal runs, scaling experimentsLarge GPU/XPU clusters, scale-out networking, powerHigh for timing and cadence
Post-trainingRL, reasoning training, synthetic data, distillationInference-like throughput, HBMMixed: capability RL cut, alignment RL added
Evaluation and monitoringRed-teaming, capability evals, live monitoringInference capacity, sandboxed computeLikely increases
InferenceProduct traffic, agents, reasoning tokensHBM bandwidth, custom ASICs, networkingLow
Enterprise customizationFine-tuning, RAG, small modelsCloud GPUs, smaller acceleratorsLow

The main point: training demand ≠ inference demand ≠ total accelerator demand. A policy aimed at the first will not fully reach the third.


What Pacing the Frontier Could Reduce

The most exposed demand is capability-driven frontier work:

  • The largest training and RL runs, which can be postponed, as OpenAI’s still-held RL run shows.
  • Timing of dedicated training campuses. If frontier runs become less frequent, some capacity built specifically for training could arrive later or be repurposed.
  • Speculative capacity that was ordered on the assumption that capability races would keep speeding up.

The size of this effect depends on how pacing is designed. Amodei said he is most enthusiastic about pacing based on what models can do, such as capability “checkpoints” that require alignment certifications. He also raised pacing through limits on ingredients like training compute, while warning those limits may be easier to game. A compute cap would hit chip demand directly. A capability checkpoint mostly delays when compute is used.


What Pacing the Frontier Could Leave Untouched

Several large demand drivers sit mostly outside the proposal:

  • Inference serving for models already deployed.
  • Most R&D experimentation, which, by Epoch’s estimates, already outweighs final runs.
  • Enterprise workloads built on existing models.
  • Non-participating developers. Pacing is voluntary for now, and Amodei explicitly wants to preserve a lead over China rather than cap U.S. compute across the board.

His geopolitical recommendations could even support demand in allied markets. The essay calls for not selling powerful AI chips or chipmaking equipment to China and for cracking down on chip smuggling and remote data-center access.


The Evaluation Paradox: Pacing the Frontier Costs Compute

Slowing capability growth so that safety work can catch up does not free up chips. Safety work runs on chips.

OpenAI has put a number on part of this. Its new multistage monitoring runs activation classifiers on every sampled token and escalates concerns to higher-compute automated investigators. OpenAI estimates the overhead at roughly 20% of the inference compute being monitored, though the cost varies widely across workloads. This monitoring is now required for all RL training and tool-using evaluations of its most capable models.

Embedded evaluation pushes further in the same direction. Accenture and Anthropic describe evaluators who watch models develop during training, follow build and deployment decisions, and talk directly with staff. Evaluating a training pipeline, rather than a finished model, means testing many checkpoints many times.

Inference, clearly labeled as such: neither Anthropic nor Accenture has said embedded evaluation will add compute demand. Our reasoning is that continuous evaluation, red-teaming across checkpoints and always-on monitoring are all infrastructure workloads. Evaluation will not replace frontier training demand. It is a growing new demand line, and pacing makes it larger.


Why Inference Changes the Equation

Could inference demand offset slower frontier training? Plausibly, yes. The companies selling the hardware say that is already happening.

Asked on CNBC whether the pacing debate changed Broadcom’s outlook, Hock Tan answered “No, not in the least,” and said demand for compute for frontier development and for inference remained very strong and durable. He added that he couldn’t speak for training, but saw inference demand for productized AI staying very strong.

Nvidia’s latest results show broad demand beyond a few labs. Revenue reached $96.2 billion in the quarter ended July 26, and data center revenue hit $89.0 billion, up 117% year over year. Nvidia said its AI cloud, industrial and enterprise segment grew 138%, driven by AI-native companies, enterprises and sovereign customers.

Research points the same way over the longer term. Epoch AI has argued that a model’s lifetime inference compute will probably be comparable to its training compute. Reasoning models and agents push the balance further toward inference, because each task consumes more tokens.

Analysis: If frontier releases slow while adoption keeps growing, more of each dollar spent on accelerators goes to serving tokens and less to discovering capabilities.


From GPUs to HBM: The Infrastructure Chain

Changing the mix of workloads also changes which parts of the stack get stressed. We mapped the layers in our breakdown of the AI compute stack. Here is how pacing moves through them:

  • Accelerators. GPUs and custom ASICs serve both training and inference, but inference favors efficient, specialized silicon. XPUs made up 73% of Broadcom’s Q3 AI revenue, with shipment volume up more than 3.5-fold year over year.
  • HBM. Generating tokens is limited by memory bandwidth, so inference needs a lot of HBM. Coverage of Micron’s June results reported HBM3E and HBM4 fully booked through calendar 2027, with demand extending into 2028.
  • Networking and optics. Broadcom’s AI networking revenue grew more than 2.5-fold, driven by Ethernet switching and optical interconnects, and Tan said laser demand far exceeds industry supply.
  • Power, cooling and sites. Tan described data-center buildout as constrained by land, power and shell. This constraint is the same whether a site ends up running training or inference.

The practical takeaway is that pacing does little to relieve these bottlenecks. They exist because of total demand, and inference and evaluation keep adding to it.


What the Market Reaction Gets Right and What It Misses

The selloff was not irrational. Demand is concentrated among a few buyers. Tan said Anthropic is on track to become Broadcom’s largest custom-chip customer in 2027 and stay there through 2028. A change in plans at one lab matters to its suppliers.

Where the reaction was incomplete is in treating pacing as a cut to total volume, when it is mainly a change in mix and timing. Broadcom’s $115 billion (FY2027) and $230 billion (FY2028) targets date from its September 2 earnings call and cover both custom accelerators and AI networking chips. Management left them unchanged after the essay. None of this is investment advice. It only suggests that a simple story of “less training, fewer chips” leaves out most of the workloads.


Pacing the Frontier Is Really a Compute Allocation Question

Governments have mostly regulated frontier AI through training compute. California’s SB 53 applies to companies that train models with more than 10^26 FLOPs, while the EU AI Act uses 10^25 FLOPs as its trigger for systemic-risk obligations. Those thresholds measure the training run that produced a model. They do not measure inference, most experimentation or evaluation.

This leads to two different ways to govern:

  • Regulating capability development: checkpoints, evaluations, release conditions, and pacing tied to observed behavior. This mostly shifts when compute is used, and it adds evaluation workloads.
  • Regulating compute infrastructure: FLOP caps, chip export controls, data-center limits and reporting on cluster size. This affects chip demand directly and in proportion.

Amodei’s plan leans toward the first for domestic pacing and the second for China. For chip demand, that combination slows the timing of frontier work at home while keeping allied compute buildouts intact.

Politics is a further constraint. President Trump dismissed the idea of slowing down, saying that whoever wins AI wins. Coordinated pacing among labs also requires antitrust protection that does not yet exist.


What to Watch Next as Pacing the Frontier Plays Out

  • Micron’s results on September 30. Micron will report fiscal fourth-quarter results that day. Watch for HBM commentary.
  • Nvidia’s next quarter. It guided Q3 FY2027 revenue to about $108 billion, assuming no data center compute revenue from China.
  • OpenAI’s held RL run. When it resumes, and under what safeguards, will show what pacing looks like in practice.
  • More evaluators. Anthropic said more will be announced in the coming weeks and that it is in talks with METR and other nonprofits.
  • Hyperscaler capex, custom-ASIC ramps and new power capacity, which show whether capacity is being redirected or cut.
  • Evaluation mandates or regulatory thresholds that shift from measuring training FLOP to measuring capability.
  • Audited cost disclosures. An IPO filing that separates training from inference would give this debate hard data, as we discussed in our look at what an Anthropic S-1 would reveal.

Conclusion: Pacing the Frontier Reshapes Demand

Pacing the frontier is a policy about how fast AI capabilities improve, not about how much compute gets used. The first real examples show this. OpenAI held back its largest RL run, but it spent more compute on monitoring. Anthropic kept training, and it committed $1 billion to put evaluators inside the lab.

Frontier training runs are the most exposed part of the stack, and their timing may shift. Post-training is mixed. Evaluation is likely to grow. Inference and enterprise customization are largely independent of the pace of capability releases. Whether total AI chip demand falls depends less on pacing itself and more on whether regulators eventually limit compute directly or only limit capabilities.


Frequently Asked Questions

What does “pacing the frontier” mean?

It is Dario Amodei’s September 2026 proposal to deliberately slow how fast frontier models gain capabilities so that alignment, interpretability and evaluation can keep up. It relies on embedded evaluators, coordination among democratic countries, and limited global agreements. It is not a halt to training.

Does pacing AI development reduce demand for GPUs?

Not necessarily. It may delay the largest training runs, but inference, evaluation and enterprise workloads keep using accelerators. The effect is mainly on the mix and timing of demand.

Does AI inference require more compute than training?

It depends on the model and time period. Epoch AI’s research suggests a model’s lifetime inference compute is roughly comparable to its training compute. Reasoning models and agents push the balance toward inference.

How does AI safety evaluation affect compute demand?

Evaluation consumes compute. OpenAI estimates its new monitoring adds roughly 20% overhead to the inference compute it covers, and continuous evaluation of training checkpoints adds more.

What happens to AI chip demand if frontier training slows?

Training-specific capacity may be delayed or repurposed. Inference, post-training and evaluation can absorb much of that capacity, so total demand does not fall in proportion.


Keep reading

Enterprise AI Spending

Enterprise AI Spending Hit $177B. Agents Are Driving the Bill

Figures checked against Menlo Ventures’ 2026 State of Enterprise AI report on 4 November 2026. Market sizes are Menlo estimates, shown as annualised run rates. …
Machine Unlearning

Machine Unlearning: Can We Really Trust an Edited AI Model?

Checked against Hirundo’s and Lazarus AI’s published results, CrowdStrike’s DeepSeek-R1 study, Lawfare and the Federal Register on 4 November 2026. Ask Alibaba’s Qwen3.6-35B-A3B about Tiananmen …
Robotics Cybersecurity

Your Robot May Pass Every Test. Its Simulator Could Still Be Lying
Last checked: 3 November 2026. Vulnerability identifiers, affected projects and patch information will be updated as coordinated disclosures become public. A robot that clears every …
Model Weights

Verify Model Weights: 7 Checks Before You Download

Checked against the burner22/numbat repository and its discussions, Hugging Face and PyTorch documentation, and Moonshot AI’s announcement on 2 November 2026. On 1 November, a …

Model Card Disclosure in 2026: What AI Labs Actually Tell You

Model Card Disclosure

Open the documentation for any model released this year and you will find something. Whether you find the thing you came for depends entirely on which lab shipped it, and increasingly on which document you happened to open.

This article presents a seven-point framework for reading model-card disclosures and following their source references. It does not report a completed comparative audit.

The aim is to distinguish what a document states, what it links elsewhere and what remains unverified.

Key Takeaways

  • Use the same seven questions for each document, recording the exact version and source passage.
  • Distinguish direct disclosure from pointers to other documents.
  • Treat missing evidence as unverified rather than assigning an unsupported score.
  • Separate vendor claims, independent research and your own observations.
  • No completed four-card scoring exercise is reported here.

Quick Navigation


What a Model Card Is, and What Model Card Disclosure Now Means

What is a model card? A model card is a short structured document published alongside a machine learning model that states its intended uses, training data, evaluation results, and known limitations. The format was proposed by Margaret Mitchell and colleagues in 2019 and has since become the default unit of AI documentation.

The original proposal assumed one document would carry everything. That assumption broke in 2026. Frontier labs now publish a system card focused on pre-deployment safety evaluation, a model card focused on specifications and benchmark results, and — for anyone selling into Europe — a separate public summary of training content filed under the AI Act. These three documents overlap unevenly and almost never link to one another.

So “model card disclosure” in 2026 means something looser than it did five years ago: the sum of what a provider publishes about a model, wherever it lands. The problem for the reader is that nobody tells you which document holds which fact.


How to Review Model Card Disclosure

This article presents a seven-point checklist for reviewing model-card disclosures. It does not report a substantiated four-card audit. For each criterion, record the document version, relevant passage and linked sources, distinguishing information stated in the card from information available elsewhere.

The Seven-Point Model Card Disclosure Checklist

#ItemWhat counts as disclosed
1Training data provenanceNamed sources or source categories with indicative proportions
2Evaluation methodologyEnough detail to interpret or reproduce the reported scores
3Contamination checksA stated train-test overlap analysis
4Safety testingEvaluations run, thresholds applied, who ran them
5Stated limitationsSpecific failure modes, not generic hallucination boilerplate
6Compute usedParameter count, FLOPs, or hardware-hours
7Licence termsWeights licence and acceptable-use policy

Applying the Seven-Point Checklist

A completed comparison should include a source passage for each assessment. Use “not verified” when the available evidence does not support a judgment. No model-by-model scores are presented here.

Training Data Provenance

Which sources, categories and proportions does the document identify?

Evaluation Methodology

What information does the document provide about datasets, settings, graders and reproducibility?

Contamination Checks

Does it describe checks for overlap between training data and evaluation material?

Safety Testing

Which evaluations, thresholds and evaluators are identified?

Stated Limitations

Which specific limitations and failure modes are documented?

Compute

Which compute figures are disclosed, and what do their units measure?

Licence Terms

Which licences, usage policies and distribution terms apply?

Existing source references for further reading (not a completed review): anthropic · simonwillison · deepmind · stanford · hardware-hours. Google names TPUs as the training hardware without quantity. Inkling's 45-trillion-token pretraining figure is the only compute-adjacent number available, and it describes data volume rather than compute. · stanford

Why Model Card Disclosure Fragmented

The fragmentation has a date. The European Commission published its template for the public summary of training content on 24 July 2025, applying to new general-purpose models from 2 August 2025, with models already on the market given until 2 August 2027. Enforcement began on 2 August 2026.

Once provenance became a regulated filing with its own template, it stopped being a card section. The card kept the marketing-adjacent material — benchmarks, use cases, limitations — and the regulated material moved into a document published on a different page, usually with no link either way.

For a European compliance officer this is a nuisance. For everyone else it is a trap, because the card still looks complete.


Reference Chains Are Quietly Hollowing Out Model Card Disclosure

Reference chains need explicit review: follow a pointer and record which document supplies the information.

Check whether a reference to a predecessor describes unchanged information or supplies evidence for the specific release being assessed.

A pointer does not by itself establish that a successor was independently assessed. Preserve the referenced version and relevant passage before drawing that conclusion.

The AI Transparency Atlas study captured the general disorder from another angle, analysing five frontier models and 100 Hugging Face cards and identifying 947 unique section names, with usage information alone appearing under 97 different labels. arxiv


What the Broader Corpora Say About Model Card Disclosure

Published transparency studies provide a broader context for these review questions.

The GPAI Ledger, which archives every known Article 53(1)(d) summary with cryptographic hashes and timestamps, recorded 124 models across 31 providers on its 19 September 2026 sweep: 75 summaries published, 49 missing. The missing entries cluster at the top of the market. Google shows published summaries for Gemini 3 Pro and Gemma 4 while more than a dozen other entries — every Flash variant, Gemini Omni, the Robotics models, Veo, Imagen — sit unpublished.

The AI Accountability Lab, whose framework was accepted at FAccT 2026, graded the summaries it could find on transparency and usefulness. Its conclusion is the one that should worry large vendors: the highest-quality summaries come from small organisations and open-source efforts, which demonstrates that non-publication by larger providers is an intentional choice rather than evidence that the obligation is burdensome. Apertus, from the Swiss AI Initiative, grades A and A+. Microsoft’s Phi-4 summary grades D and F.

Stanford’s December 2025 index completes the picture. Its mean company score fell to 41 out of 100, a seventeen-point drop, with IBM at 95 and xAI and Midjourney tied at 14. The paper’s abstract states the mean as 40 against the site’s 41 — a minor discrepancy worth noting rather than smoothing over. Engagement fell alongside scores: 30% of contacted companies agreed to submit transparency reports in 2025, down from 74% in 2024. stanford


A Practical Framework for Reading Model Card Disclosure

If you evaluate models for a living, this is the order that saves time.

  1. Check for a pointer before you read. If the section says “see the previous card,” treat the item as undisclosed for this release until you follow the chain and confirm otherwise.
  2. Look for the provenance document separately. Search the provider’s linked documentation and record what you locate. An unsuccessful search is not proof that a document does not exist.
  3. Check benchmark evidence. Look for a documented overlap analysis and distinguish reported scores from independently verified performance.
  4. Read the limitations section. Record specific failure modes and whether the document supports the intended use.
  5. Separate tested from inferred. A safety claim carried over from a predecessor is a different artefact from one produced by testing the shipped model.
  6. Record what is missing, with dates. Providers revise cards without notice. A dated note of what was absent when you evaluated is the only defensible audit trail.

What Model Card Disclosure Still Cannot Tell You

A document review establishes what the documents disclose. It does not independently establish model behaviour, training-data composition or the validity of a reported benchmark. Record those limits rather than treating disclosure as experimental verification.

Frequently Asked Questions

What is a model card?

A model card is a structured document published alongside a machine learning model that describes its intended uses, training data, evaluation results, and known limitations. The format was introduced by Mitchell and colleagues in 2019. In 2026, large labs typically split this information across a model card, a system card focused on safety evaluation, and a separate regulatory filing on training content.

What is the difference between a model card and a system card?

A model card documents the model itself — architecture, data, benchmarks, limitations, licensing. A system card documents pre-deployment safety evaluation: the risk thresholds applied, the tests run, the mitigations deployed. OpenAI and Anthropic publish system cards for frontier releases; Google DeepMind publishes model cards that include a safety section. Neither format reliably includes the other’s content.

Do model cards disclose training data?

Check whether the document identifies sources or source categories and proportions, and follow any training-content-summary links. This article does not establish a result for a reviewed sample.

Why don’t AI labs disclose training compute?

Check which parameter counts, FLOPs or hardware-hours are actually disclosed. If a figure is absent, record it as unverified; do not infer the provider’s reason from that absence.

Which organisations publish the highest-quality AI documentation?

On training-data documentation specifically, the AI Accountability Lab’s graded assessment found the strongest summaries came from small organisations and open-source projects, with the Swiss AI Initiative’s Apertus scoring highest. On broader company-level transparency, Stanford’s December 2025 index placed IBM first at 95 out of 100 against a mean of 41. Scale and disclosure quality are not correlated.


Keep reading

Enterprise AI Spending

Enterprise AI Spending Hit $177B. Agents Are Driving the Bill

Figures checked against Menlo Ventures’ 2026 State of Enterprise AI report on 4 November 2026. Market sizes are Menlo estimates, shown as annualised run rates. …
Machine Unlearning

Machine Unlearning: Can We Really Trust an Edited AI Model?

Checked against Hirundo’s and Lazarus AI’s published results, CrowdStrike’s DeepSeek-R1 study, Lawfare and the Federal Register on 4 November 2026. Ask Alibaba’s Qwen3.6-35B-A3B about Tiananmen …
Robotics Cybersecurity

Your Robot May Pass Every Test. Its Simulator Could Still Be Lying
Last checked: 3 November 2026. Vulnerability identifiers, affected projects and patch information will be updated as coordinated disclosures become public. A robot that clears every …
Model Weights

Verify Model Weights: 7 Checks Before You Download

Checked against the burner22/numbat repository and its discussions, Hugging Face and PyTorch documentation, and Moonshot AI’s announcement on 2 November 2026. On 1 November, a …