Research cutoff: 20 October 2026. Prices, licences and legal status were checked on that date and change often.
On 19 October, MiniMax priced its new M3.1 Flash at $0.15 per million input tokens and $0.60 per million output tokens. Those are, to the cent, the off-peak rates DeepSeek charges for V4.1 Flash. The next day, the US Department of Homeland Security published an order removing DeepSeek products from federal civilian IT systems. That pairing sums up where Chinese open-weight models stand: quality at the top has converged enough that licence terms, serving cost, hardware and the identity of your customer now decide the purchase.
This comparison covers the current release from DeepSeek, Alibaba’s Qwen, Moonshot AI’s Kimi, MiniMax and Zhipu AI’s GLM (sold internationally as Z.ai). It does not name a winner, because the evidence does not support one.
Key Takeaways
- “Open-weight” covers five different licences. Only DeepSeek V4.1 Flash (MIT) and Qwen3.8-27B (Apache 2.0) come with standard permissive licences. Kimi K3, GLM-5.3, MiniMax-M3 and Qwen’s 2.4-trillion-parameter model all add custom conditions.
- The downloadable model is not always the model you tested. Qwen3.8’s open-weight flagship is text-only and lacks the hosted Max model’s 1M-token context. MiniMax’s newest model, M3.1 Flash, has no weights yet.
- Hosted prices for the same workload differ by about 25×. On the example workload below, the bill runs from roughly $167 a month (DeepSeek, off-peak) to $4,110 (Kimi K3).
- Self-hosting the flagships is a cluster decision. The largest checkpoints need 1.4–4.9 TB of accelerator memory for weights alone. Only the 27B Qwen model fits on a single GPU.
- Vendor benchmark tables are not mutually comparable. DeepSeek’s and MiniMax’s October tables report different Humanity’s Last Exam scores for the same Anthropic model.
- The US order on DeepSeek is narrow but real. It covers federal civilian agency systems and procurement, including third-party products “developed using DeepSeek implementations”. The public notice does not extend it to private companies.
Quick Navigation
- What this comparison measures
- Master comparison of Chinese open-weight models
- What the benchmark tables establish
- Five families, five different trade-offs
- Licences: what "open-weight" permits
- Hosted API versus self-hosting economics
- Government restrictions and procurement
- Which model fits which workload
- Conclusion
- Frequently asked questions
- What are Chinese open-weight models?
- Are DeepSeek and Qwen models open source?
- Can Chinese open-weight models be used commercially?
- Which of these models can run on a single GPU?
- Is DeepSeek banned in the United States?
- Is self-hosting cheaper than using an API?
- How should I compare benchmark results across vendors?
What this comparison measures
“Open-weight” means the trained parameters can be downloaded. It does not mean the training data or training code is public (none of the five publishes its training data), and it does not mean the licence permits every commercial use. Each family is assessed on its current release, with the downloadable checkpoint and the hosted API treated separately where they differ. Vendor-reported figures are labelled as such.
Master comparison of Chinese open-weight models
Table 1 — Release, weights and licence (checked 20 October 2026)
| Family | Current release assessed | Weights | Licence | Commercial use |
|---|---|---|---|---|
| DeepSeek | V4.1-Flash-1017 (Oct 2026) | Downloadable | MIT | Permitted |
| Qwen | Qwen3.8-27B; Qwen3.8-2.4T-A95B (Aug 2026) | Downloadable | 27B: Apache 2.0 (reported). 2.4T: custom “Qwen3.8-Max License” | Permitted; conditions above stated thresholds for the 2.4T model |
| Kimi | Kimi K3 (late July 2026) | Downloadable | Custom “Kimi K3 License” (MIT-derived) | Permitted; conditions above thresholds |
| MiniMax | MiniMax-M3 (June 2026); M3.1 Flash (Oct 2026) | M3: downloadable. M3.1 Flash: not yet released | M3: “MiniMax Community License” | M3: commercial use requires notice or written authorisation |
| GLM | GLM-5.3 (weights 28 Aug 2026) | Downloadable | Custom “GLM-5.3 License” | Permitted; security review for hosts above $10 billion revenue |
Table 2 — Architecture, context and price
| Model | Total / active parameters | Context | Inputs | API price per 1M tokens (input / output) |
|---|---|---|---|---|
| DeepSeek V4.1 Flash | 552B reported; 763B in repository metadata / 8B–16B active (reported) | 1M | Text, image | $0.15 / $0.60 off-peak; double at peak |
| Qwen3.8-27B | 27B dense | 262K native, 1M with YaRN | Text, image, video | Not verified |
| Qwen3.8-2.4T-A95B | 2.4T / 95B | Below the hosted model’s 1M (exact figure not published) | Text only | Hosted Max: $2 / $6 (reported, not verified) |
| Kimi K3 | 2.8T / 104B | 1M | Text, image, video | $3.00 / $15.00 ($0.30 cached input) |
| MiniMax-M3 | ~428B / ~23B | 1M | Text, image, video | Not published |
| MiniMax M3.1 Flash | Not disclosed | Not stated officially | Text, image (reported) | $0.15 / $0.60 ($0.015 cached input) |
| GLM-5.3 | ~744–753B / ~40B | 1M | Not confirmed (GLM-5.2 was text-only) | $1.40 / $4.40 |
Every model except Qwen’s 27B has converged on a very large mixture-of-experts design with a 1M-token context, so architecture no longer separates them. Hosted prices do: they span more than an order of magnitude, from the two Flash models to Kimi K3.
What the benchmark tables establish
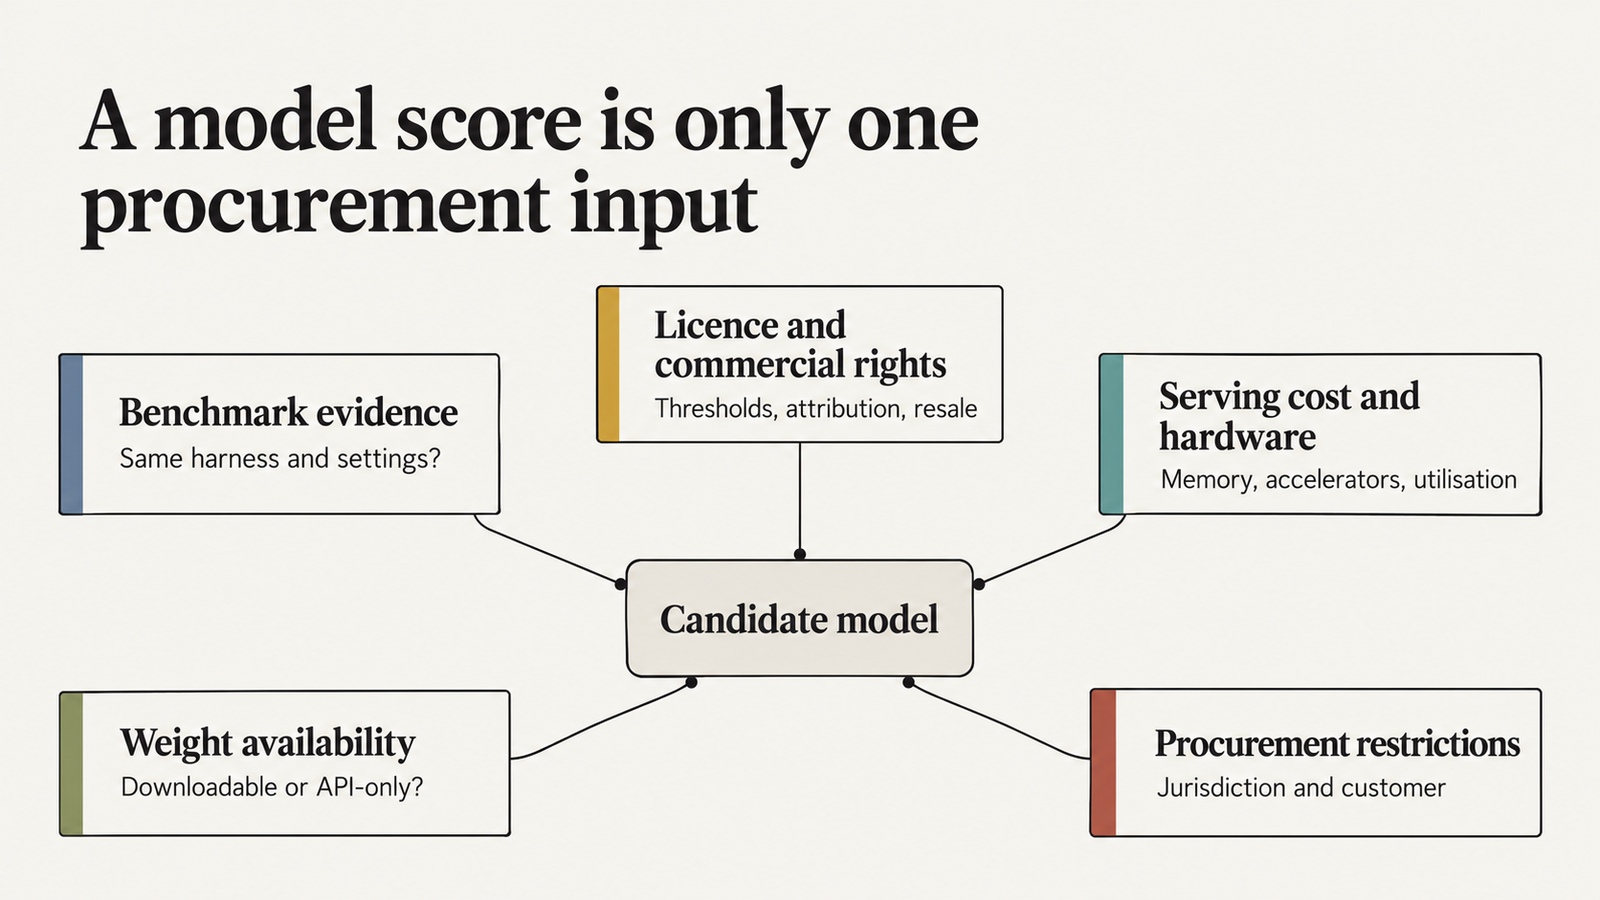
Less than they appear to. The October model cards from DeepSeek and MiniMax both compare against Kimi K3, GLM-5.3 and Anthropic’s Claude Opus 5, and both use some of the same benchmarks: DeepSWE v1.1, Terminal-Bench 4.0, NL2Repo-Bench and Humanity’s Last Exam (HLE).
Table 3 — Vendor-reported scores on shared benchmarks (October 2026)
| Benchmark | DeepSeek V4.1-Flash-1017 | MiniMax M3.1 Flash | Kimi K3 (in DeepSeek’s table) | GLM-5.3 (in DeepSeek’s table) |
|---|---|---|---|---|
| DeepSWE v1.1 | 77.0 | 73.7 | 67.5 | 66.9 |
| Terminal-Bench 4.0 | 42.3 | 38.1 | 12.6 | 37.9 |
| NL2Repo-Bench | 68.2 | 61.2 | 58.0 | 58.0 |
| HLE (no tools) | 42.6 | 43.4 | 43.5 | 42.0 (text-only subset) |
Sources: DeepSeek V4.1-Flash-1017 model card; MiniMax M3.1 Flash announcement. DeepSeek ran DeepSWE with the Mini-SWE-V2 harness and Terminal-Bench with the Claude Code harness; MiniMax’s footnotes cite several harnesses. All figures are company-reported.
DeepSeek’s table lists Claude Opus 5 at 56.3 on HLE without tools; MiniMax’s lists the same model at 55.6. The gap is small, but it shows that run conditions differ even when the labels match, and the four HLE scores above sit within 1.5 points of each other.
The Kimi row is the clearest warning. In DeepSeek’s table, Kimi K3 scores 12.6 on Terminal-Bench 4.0. Moonshot’s own card reports 88.3 on Terminal-Bench 2.1, an earlier version. Neither figure is necessarily wrong, but they cannot be compared, and a reader skimming two announcements could draw opposite conclusions.
Independent measurement helps a little. Artificial Analysis, as reported by The Decoder, puts DeepSeek V4.1-Flash-1017 at 45 on its Intelligence Index and M3.1 Flash at 42; its own page lists GLM-5.3 at 45. It also found that M3.1 Flash answered 56% of AA-Omniscience questions correctly but was confidently wrong in 93% of the cases it missed, a reliability signal absent from MiniMax’s table. None of this is your codebase or your latency budget. Use benchmarks to decide what to test.
Five families, five different trade-offs
DeepSeek: lowest price, cleanest licence, biggest procurement question
DeepSeek released V4.1 Flash on 10 September and an updated checkpoint, V4.1-Flash-1017, on 17–18 October, under the MIT licence with FP8 weights and a 1M-token context. SiliconANGLE’s launch report describes a 552B-parameter mixture-of-experts model activating 8B parameters on prompts and 16B when generating; the repository metadata shows 763B. DeepSeek has not explained the gap, and the higher figure is the one that sets your memory budget.
Price is DeepSeek’s strongest argument. Since 17 August, rates double during weekday peak hours (09:00–12:00 and 14:00–18:00 Beijing time). Off-peak, V4.1 Flash costs $0.15 per million uncached input tokens and $0.60 per million output tokens, and since 14 September calls to V4-Pro have been served and billed as V4.1 Flash. Two caveats: a nearly five-hour API outage on 15 October, and the US federal order covered below.
Qwen: the only realistic single-GPU option, and a split flagship
Qwen3.8-27B is the only strong small model in any family’s current generation. It is dense and multimodal, handles 262K tokens natively (1M with YaRN scaling), and The Decoder reports an Apache 2.0 licence. Its weights need about 54 GB in BF16 or 27 GB at FP8, so it fits on one 80 GB accelerator.
The flagship, Qwen3.8-2.4T-A95B (2.4 trillion total, 95 billion active parameters), is a different product from the hosted Qwen3.8-Max. Its model card says Max offers “more features, such as vision input & non-thinking support, 1M context length by default, official built-in tools”. The download is text-only, with a shorter context, under a custom licence whose thresholds appear in Table 4.
Kimi: the largest model, the highest price
Kimi K3 is the biggest model in the group: 2.8 trillion total parameters, 104 billion active, a 1M-token context, and text, image and video input. Moonshot trained it with quantisation-aware training, so the released weights are natively MXFP4, which is why a 2.8T model downloads at about 1.56 TB rather than 5.6 TB.
On Moonshot’s platform, K3 costs $3.00 per million input tokens ($0.30 cached) and $15.00 per million output tokens, 20 to 25 times DeepSeek’s off-peak rates. Moonshot reports strong agentic and multimodal results at maximum reasoning effort, including 91.2 on BrowseComp and 84.8 on OSWorld-Verified. Agent and computer-use workloads are where the premium could pay off; only your own tests can confirm it. The MIT-derived licence adds conditions for large resellers and very large products (Table 4).
MiniMax: two models, two different deals
MiniMax currently offers two different things under one brand. MiniMax-M3, released in June, is downloadable: about 428B total parameters, about 23B active, a 1M-token context through MiniMax’s sparse attention design, published in BF16. Its model card reports 80.5 on SWE-bench Verified and 78.1 on MMMU-Pro.
The M3 licence is the most restrictive here. The base grant covers non-commercial use; commercial use needs a one-time notice to MiniMax below $20 million in annual revenue, written authorisation above it, and a “Built with MiniMax M3” label. Serving the model through an API counts as commercial use, and military use is prohibited.
M3.1 Flash, launched on 19 October at $0.15 input, $0.60 output and $0.015 cached input per million tokens, ties DeepSeek on price. MiniMax says “model weights will be released later”. Until then it is an API product with no published licence, parameter count or context window.
GLM: MIT one release, custom the next
Zhipu’s GLM-5.2, released in June, was MIT-licensed and text-only. GLM-5.3 reached the API in August and open weights on 28 August, after a two-week safety hold: roughly 744–753B total parameters, about 40B active, a 1M-token context. Its new licence requires hosts with more than $10 billion in annual revenue to pass Z.ai’s security review. Few buyers will hit that threshold, but it shows a family’s licence can change between point releases.
At $1.40 input and $4.40 output, GLM-5.3 is mid-priced. Artificial Analysis measured 85.5 output tokens per second and a 2.44-second time to first token on Z.ai’s API. Z.ai’s vLLM recipe starts at one node of eight H200 or H20 accelerators for the FP8 checkpoint, which makes it the most practical large model to self-host.
Licences: what “open-weight” permits
A downloadable checkpoint only means you can obtain the file. The table summarises the clauses that decide what you can do with it; it is not legal advice.
Table 4 — Licence conditions that change a deployment decision
| Model | Revenue or user trigger | What it triggers | Exempt |
|---|---|---|---|
| DeepSeek V4.1 Flash (MIT) | None | Keep the copyright notice | — |
| Qwen3.8-27B (Apache 2.0, reported) | None | Notice and licence retention | — |
| Qwen3.8-2.4T-A95B | >100M MAU or >$20M monthly revenue; MaaS/AI work-assistant revenue >$50M per year | Display model name; separate licence | Internal use |
| Kimi K3 | MaaS revenue >$20M per 12 months; >100M MAU or >$20M monthly revenue | Separate agreement; display “Kimi K3” | Internal use; use via Moonshot or certified partners |
| GLM-5.3 | Hosting company revenue >$10B per 12 months | Z.ai security review | Routing, embedding |
| MiniMax-M3 | Any commercial use; >$20M annual revenue | Notice; prior authorisation; “Built with MiniMax M3” | None stated |
The practical split is between internal use and resale. If you run a model only inside your company, the thresholds in the Kimi and large-Qwen licences generally do not apply. If you sell API access to a model, MiniMax-M3 requires permission at any scale, and Kimi K3 and Qwen’s flagship require agreements above their revenue thresholds.
Hosted API versus self-hosting economics
Headline prices are per token. A bill depends on how many of your tokens are input versus output, how many hit the cache, and, for DeepSeek, what time of day they arrive.
Example workload: 1 billion input tokens a month, of which 70% are cache hits, plus 200 million output tokens. This is roughly the shape of an agent or retrieval system that reuses long system prompts.
Table 5 — Monthly API bill for the example workload (prices checked 20 October 2026)
| Model | Cached input | Uncached input | Output | Monthly total |
|---|---|---|---|---|
| DeepSeek V4.1 Flash (off-peak) | 700M × $0.003 = $2.10 | 300M × $0.15 = $45.00 | 200M × $0.60 = $120.00 | $167.10 |
| DeepSeek V4.1 Flash (all at peak) | $4.20 | $90.00 | $240.00 | $334.20 |
| MiniMax M3.1 Flash | 700M × $0.015 = $10.50 | 300M × $0.15 = $45.00 | 200M × $0.60 = $120.00 | $175.50 |
| Qwen3.8-Max (reported rates) | 700M × $0.20 = $140.00 | 300M × $2.00 = $600.00 | 200M × $6.00 = $1,200.00 | $1,940.00 |
| GLM-5.3 (no cache discount assumed) | — | 1,000M × $1.40 = $1,400.00 | 200M × $4.40 = $880.00 | $2,280.00 |
| Kimi K3 | 700M × $0.30 = $210.00 | 300M × $3.00 = $900.00 | 200M × $15.00 = $3,000.00 | $4,110.00 |
The Qwen cache rate assumes explicit cache hits at 10% of the input price, as CloudZero reports for Alibaba Model Studio. GLM-5.3 is shown without a cache discount because Z.ai’s cached rate was not verified; its real bill would be lower. The DeepSeek cache-hit rate is taken from third-party transcriptions of DeepSeek’s pricing page.
Output is the largest line in every bill except GLM’s, where the missing cache discount inflates input. For Kimi K3 it is 73% of the total, so long answers or long reasoning traces widen the gap between vendors well beyond what input prices suggest.
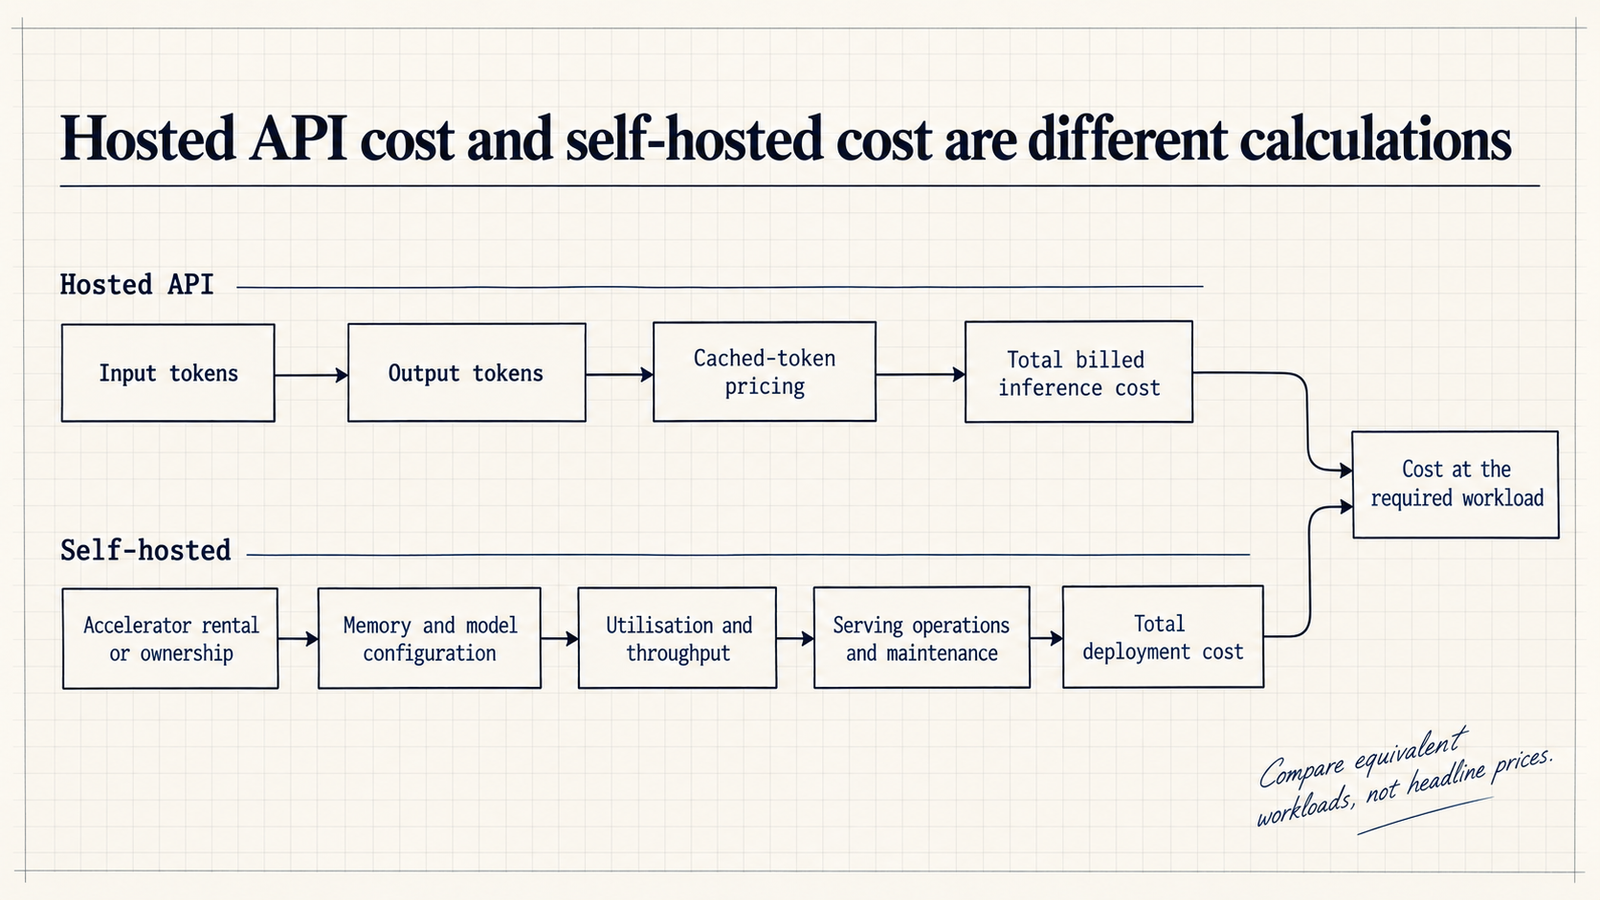
Self-hosting changes what you pay for. In a mixture-of-experts model, only the active parameters are computed per token, but every parameter must sit in accelerator memory.
Table 6 — Weight memory before KV cache and activations
| Model | Released precision | Weights in memory (approx.) |
|---|---|---|
| Qwen3.8-27B | BF16 | ~54 GB (~27 GB at FP8) |
| MiniMax-M3 | BF16 | ~856 GB (~428 GB if quantised to FP8) |
| DeepSeek V4.1-Flash-1017 | FP8 | ~0.55–0.76 TB |
| GLM-5.3 | FP8 | ~0.75 TB |
| Kimi K3 | MXFP4 | ~1.56 TB (repository size) |
| Qwen3.8-2.4T-A95B | FP8 / BF16 | ~2.4 TB / ~4.9 TB |
An eight-GPU H200 server holds 8 × 141 GB = 1,128 GB. GLM-5.3 and DeepSeek V4.1 Flash fit on one such node at FP8 with headroom for a modest KV cache, which is why Z.ai’s recipe starts there. Kimi K3 and Qwen’s 2.4T model do not fit and need either newer accelerators with more memory per device or a multi-node deployment.
To compare a node with an API bill, use monthly node cost = GPUs × hourly rate × 730 hours. At an assumed $3.00 per GPU-hour (a placeholder, not a quote), one eight-GPU node costs 8 × $3.00 × 730 = $17,520 a month, before redundancy, engineers or monitoring. That is about 4.3 times the Kimi K3 API bill for the example workload and more than 100 times DeepSeek’s off-peak bill. Self-hosting pays at much higher volume, under data-residency rules that exclude vendor APIs, or when the licence blocks the hosted route you need.
Utilisation decides the outcome: a node billed for 730 hours that is busy for 200 of them has more than tripled its effective cost per token. Measure throughput on your own prompts before trusting any published tokens-per-second figure.
Government restrictions and procurement
United States, federal civilian agencies. On 20 October 2026, DHS published a notice in the Federal Register (FR Doc. 2026-21447) of an exclusion and removal order under the Federal Acquisition Supply Chain Security Act of 2018. It covers information technology products and services from Hangzhou DeepSeek Artificial Intelligence Co. and its affiliates, plus “third-party products and services developed using DeepSeek implementations”, across federal civilian agency systems and procurement. The public notice gives no compliance deadline, does not say whether self-hosted copies of the MIT-licensed weights count as covered products, and makes no statement about private companies. The signed order sits in the docket (DHS-2026-0628), and federal suppliers should read it directly.
Earlier restrictions. Texas, New York, Virginia and Iowa barred DeepSeek on state government devices or networks in January and February 2025, and the US Navy told personnel not to use it in January 2025. The No Adversarial AI Act, introduced on 25 June 2025, would bar executive agencies from using AI from adversary-country companies; we found no evidence it has been enacted. None of these measures restricts private companies in general, but federal civilian contractors are exposed because the order reaches third-party products built on DeepSeek.
DeepSeek and Huawei. Reports of a hardware partnership are partly substantiated and partly not. In June 2026, a Huawei-led research group said, via the Shenzhen government, that it had post-trained DeepSeek V4-Pro on more than 1,000 Ascend 910C chips; DeepSeek did not comment. Bloomberg reported on 4 September that DeepSeek planned to buy at least 160,000 Ascend 950DT chips for inference while continuing to train on Nvidia hardware. The Information reported design collaboration on future chips. Neither company has confirmed a commercial arrangement.
Table 7 — Procurement checklist by family
| Check | DeepSeek | Qwen | Kimi | MiniMax | GLM |
|---|---|---|---|---|---|
| Weights downloadable now | Yes | Yes | Yes | M3 yes; M3.1 Flash no | Yes |
| Licence fits intended use | MIT | Depends on model and scale | Depends on scale | Notice or authorisation for any commercial use | Yes, below $10B revenue |
| US federal civilian restriction | Yes, FASCSA order (Oct 2026) | None found | None found | None found | None found |
| US state device bans | TX, NY, VA, IA (2025) | None found | None found | None found | None found |
| Vendor API data location | Vendor-operated; confirm in terms | Alibaba Cloud regions incl. Singapore, Frankfurt, Virginia (reported) | Vendor-operated; confirm in terms | Vendor-operated; confirm in terms | Vendor-operated; confirm in terms |
| Continuity signal | Five-hour outage, 15 Oct 2026 | Hosted flagship ahead of open release | Single large model | Weights for newest model pending | Licence changed between point releases |
Self-hosting puts data handling under your controls; a vendor API puts it under the vendor’s terms and jurisdiction. Where a model was trained does not by itself make either route safe or unsafe. Confirm the current position with your legal and procurement teams.
Which model fits which workload
- Startup on hosted APIs: DeepSeek V4.1 Flash and MiniMax M3.1 Flash, the cheapest endpoints by far. Run DeepSeek batch jobs off-peak, and check M3.1 Flash’s factual reliability before using it for question-answering.
- Self-hosting on one GPU: Qwen3.8-27B, the only current-generation option.
- Self-hosting on one eight-GPU node: GLM-5.3 or DeepSeek V4.1 Flash; DeepSeek’s MIT licence is simpler unless you sell to US federal civilian agencies.
- Software engineering: shortlist DeepSeek V4.1 Flash, MiniMax-M3 and GLM-5.3 and test them on your own repository, since vendor coding tables use different harnesses.
- Chinese-language or multilingual products: none of the cards consulted reports a comparable multilingual benchmark, so test on your own corpus.
- Reasoning and mathematics: HLE scores sit within 1.5 points, and Kimi K3’s 93.5 on GPQA Diamond has no like-for-like counterpart in the other cards. Run your own evaluation.
- Multimodal: Kimi K3, Qwen3.8-27B or MiniMax-M3. Qwen’s 2.4T download is text-only, and GLM-5.3’s multimodal support was not confirmed.
- Regulated or government-facing: exclude DeepSeek from US federal civilian supply chains; for the rest, check licence terms, data residency and vendor support.
A short evaluation protocol. Pick 50–200 tasks that represent real traffic. Run every candidate with the same prompts, tools, context limits and sampling settings. Record pass rate, time to first token, output speed, cost per successful task and failure types, and repeat after each model update.
Conclusion
The five families now differ more on rights and costs than on capability. DeepSeek has the cheapest API and the cleanest licence but sits under a federal civilian procurement order. Qwen has the only single-GPU option, and a flagship download that is narrower than what Alibaba hosts. Kimi posts strong agentic numbers on its own tables at the highest price. MiniMax’s licence requires notice for commercial use. GLM is mid-priced and the easiest large model to self-host. Choosing among Chinese open-weight models in 2026 means choosing which of those trade-offs your workload, budget and customers can accept, and then testing.
Frequently asked questions
What are Chinese open-weight models?
Large language models from Chinese developers whose trained weights can be downloaded and run on your own hardware, chiefly DeepSeek, Qwen, Kimi, MiniMax and GLM. The training data and code are not public, and commercial rights vary by licence.
Are DeepSeek and Qwen models open source?
Partly. DeepSeek V4.1 Flash (MIT) and Qwen3.8-27B (Apache 2.0) use standard permissive licences, but neither family publishes training data, and Qwen’s largest open model uses a custom licence.
Can Chinese open-weight models be used commercially?
Yes for most buyers, with model-specific conditions. MiniMax-M3 needs a notice to MiniMax for any commercial use; Kimi K3 and Qwen’s 2.4T model add conditions only above high revenue or user thresholds.
Which of these models can run on a single GPU?
Only Qwen3.8-27B. The other current flagships need hundreds of gigabytes to several terabytes of accelerator memory.
Is DeepSeek banned in the United States?
Not in general. DHS has ordered federal civilian agencies to remove DeepSeek products, and several states ban it on government devices; the published notice does not extend to private companies or individuals.
Is self-hosting cheaper than using an API?
Usually not at moderate volume. Self-hosting tends to win on data control, licence fit or very high, steady utilisation.
How should I compare benchmark results across vendors?
Only when benchmark version, harness and settings match, which is rare. Use scores to build a shortlist, then test it on your own tasks.
Keep reading
Here are the latest posts from the blog.
Chinese Open-Weight Models Compared: DeepSeek vs Qwen & More
AI Agent vs Copilot: Classify AI by Its Approval Model
Agents Are Reshaping Server CPU Design. The Evidence Is Narrower.