Model details checked against official announcements, model cards and documentation on 1 November 2026.
Line up four AI models that were current at the end of October 2026, and they have almost nothing in common. Google DeepMind’s Genie 4, announced on 27 October, generates a world you can steer while it runs. Liquid AI’s LFM3-1.7B fits in about 1 GB of memory. Moonshot’s Kimi K3, released in July, has 2.8 trillion parameters. Mistral Large 4, made open-weight on 29 October, lets you choose how hard it thinks.
Calling all of these “AI models” is accurate and nearly useless. The usual types of AI models (language models, image generators, classic machine learning) no longer describe what separates one system from another. What does is how a model is built, what it can do, what it takes in, and where it runs.
Key Takeaways
- Architecture, capability, modality and deployment are separate questions, and one model usually answers all four.
- Mixture-of-experts saves compute, not memory. Kimi K3 activates 104B of 2.8T parameters per token but still needs every expert in memory.
- Reasoning effort can change scores dramatically. Claude Opus 5.5 moves from 35 to 58 on Artificial Analysis’s Index, so a score without its setting is incomplete.
- Computer use is a model plus a driver. The model chooses actions, and the developer’s system executes them and owns the risk.
- Specialised often means gated. Carbon is a general model released to cyber defenders first; Gemini 3.8 Flash Cyber is a dedicated variant.
- World models generate interactive environments, not videos. Genie 4 holds a scene for about two minutes, so it’s early.
- On-device models change the economics from per-token fees to hardware limits, and weight size understates runtime memory.
- Agentic AI is system design, built around models rather than alongside them.
Quick Navigation
- How to classify types of AI models
- Types of AI models built around language
- Types of AI models that use sparse computation
- Types of AI models designed to reason
- Types of AI models that can operate software
- Types of AI models built for specialised domains
- Types of AI models that simulate environments
- Types of AI models that run on local devices
- Where agentic AI fits
- Choosing between types of AI models
- Frequently asked questions
- What are the main types of AI models in 2026?
- What is the difference between an LLM and a reasoning model?
- What is a Mixture-of-Experts model?
- Are agentic systems one of the types of AI models?
- What is a computer-use AI model?
- What are world models in artificial intelligence?
- What are small on-device AI models?
- What is the difference between open-source and open-weight AI models?
- Which types of AI models are best for business applications?
- Can one model belong to several types of AI models?
How to classify types of AI models
Four questions sort almost any model, and they’re independent of each other:
- Architecture: how is it built? A dense transformer, a mixture-of-experts, a hybrid with convolution layers.
- Capability: what can it do? Extended reasoning, operating a computer, finding software vulnerabilities.
- Modality: what does it take in and produce? Text, images, audio, video, or an interactive environment.
- Deployment: where does it run? A provider’s cloud, your own servers, or a phone.
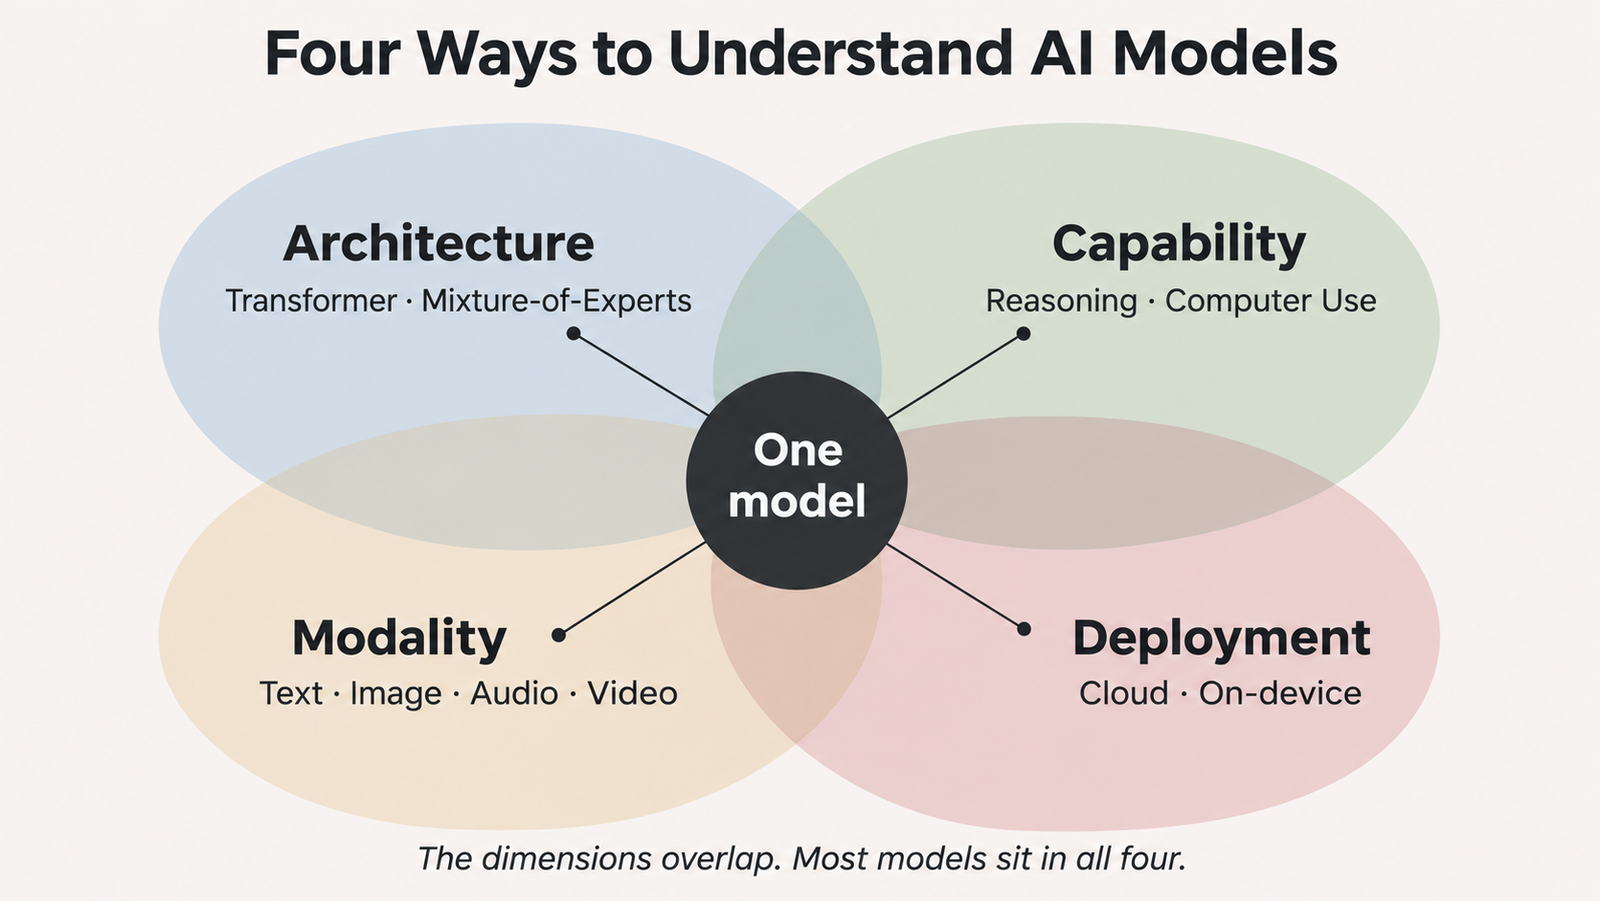
The point of separating them is that one model sits on all four axes at once. Mistral Large 4 is a mixture-of-experts by architecture, a reasoning model by capability, multimodal by input, and open-weight by deployment. Treating “reasoning model” and “mixture-of-experts” as rival categories is like asking whether a car is a diesel or an SUV.
Agentic AI sits outside all four. It describes how models are organised with tools, memory and a loop, which is why it gets its own section later.
Types of AI models built around language
A large language model (LLM) is a neural network trained to predict the next token of text, then shaped by post-training into something that follows instructions. Nearly every frontier system still starts here. Pretraining on vast amounts of text gives the model its knowledge and fluency. Post-training, through instruction tuning and reinforcement learning, decides how it behaves: how cautious it is, how it uses tools, how long it reasons.
“Language” undersells what these models now handle. OpenAI’s GPT-6.1 Terra, released on 26 October, takes text and images and returns text, with a context window of 1.05 million tokens. Most frontier LLMs are multimodal in the same way. The language model has become the general-purpose engine that other capabilities are built on.
That generality is also why their leaderboard scores mislead. A model that tops a composite index may still be the wrong choice for your extraction pipeline, a point our analysis of why benchmark scores don’t transfer to your workload makes in detail. The closed frontier labs also rarely publish architecture details, so “transformer-based” is often an assumption rather than a documented fact.
Types of AI models that use sparse computation
A mixture-of-experts (MoE) model splits parts of its network into many smaller “expert” sub-networks. A router then sends each token to only a few of them. The model’s total parameter count describes everything stored. The active parameter count describes what actually computes for each token.
Kimi K3 is the clearest current example. Its model card lists 2.8 trillion total parameters and 104 billion activated, with 896 routed experts, of which 16 are selected per token, plus two shared experts. Per token, it does roughly the arithmetic of a 104-billion-parameter dense model while drawing on far more stored knowledge.
The catch is memory. Sparse activation saves compute, not storage, because every expert must sit in memory in case the router picks it. Kimi K3 ships with MXFP4 weights, about half a byte per parameter, so the weights alone come to roughly 1.4 TB before any working memory. That’s multi-GPU server territory, as our breakdown of Kimi K3.1 Pro’s hardware requirements shows.
Version matters too. Moonshot describes Kimi K3.1 Pro, released on 23 October, as “a post-trained version of Kimi K3” and a “3T-class open-weight model.” It hasn’t published a separate parameter breakdown, and full weights are due by 4 November. The 2.8T/104B figures belong to K3. Assuming K3.1 Pro shares them is reasonable but unconfirmed.
Kimi K3 also isn’t a plain transformer. Its card lists a hybrid attention design: 69 layers of KDA, a linear-attention variant, and 24 layers of gated multi-head latent attention. Keep that detail in mind for the on-device section.
Types of AI models designed to reason
A reasoning model generates an internal chain of intermediate tokens before answering. It trades time and money for accuracy on hard problems. In 2026 this is less a separate model type than a setting on most frontier models.
Mistral Large 4 makes the setting explicit. Its API documentation accepts low, medium and high reasoning effort, with high recommended for best quality. GPT-6.1 Terra offers six levels, from none to max.
How much does the setting matter? Artificial Analysis, an independent benchmarking firm, tests models at each effort level and lists each level as a separate entry. On its Intelligence Index v5, published on 27 October, Claude Opus 5.5 scores 35 at low effort and 58 at max. Cost per task rises from $0.98 to $10.04. On launch day, the top two entries, Opus 5.5 and GPT-6 Astra, both at max, were separated by a single point.
For those flagship models, the gap from configuration was more than 20 times the gap between providers. That doesn’t mean effort always matters more than vendor choice. It does mean a benchmark score quoted without its effort level is close to meaningless.
Reasoning tokens are billed as output and add latency before the first useful word. Artificial Analysis measured Mistral Large 4 at high effort using about 82,000 output tokens per Index task, at $2.06 per task.
Types of AI models that can operate software
A computer-use model can look at a screen and decide on the next mouse or keyboard action. That’s a step beyond understanding screenshots: it has to locate elements precisely, keep track of state across many steps and recover when a page doesn’t do what it expected.
OpenAI describes GPT-6.1 Terra as “a fast, efficient model that combines detailed visual reasoning and precise computer use,” and lists computer use among its supported API tools. In the coverage reviewed, OpenAI didn’t publish a computer-use benchmark figure for Terra. Its published improvement is on internal error-inducing prompts, where the error rate fell to 16.7% at low effort and 4.3% at max, according to 9to5Mac’s report.
The model is only half of the system. OpenAI’s computer-use guide makes the split explicit. The model returns actions, and “your application supplies a driver” that executes them in a browser or desktop and sends back the result. The sandbox, the permissions, the human-approval checks and the screenshot pipeline all belong to the developer. The guide also warns that “page content can influence the model,” which is the prompt-injection risk in a single sentence.
Types of AI models built for specialised domains
A specialised model is tuned, evaluated and often released for one domain, most visibly cybersecurity in 2026. The distinction worth drawing is between a model built for a domain and a general model released through a domain.
Gemini 4 Carbon, announced on 28 October, is the second kind. Google calls it “our strongest model with state-of-the-art cybersecurity and long horizon capabilities.” It reports gains in coding, science and multimodal tasks too. What’s specialised is the rollout. Carbon went first to “a subset of cyber defenders,” and access is expanding through Google’s Fairwind Program while guardrails are refined. Google reports 88.2% on SEC-bench Pro and 54.8% on ExploitGym, evaluated without guardrails. These are vendor-reported results. Our Gemini 4 Carbon analysis covers the release in detail.
Gemini 3.8 Flash Cyber, released on 2 September, is the first kind: a cybersecurity-focused version of a smaller model, limited to vetted governments, critical-infrastructure operators and platforms.
Domain models make sense when the domain’s risks or data justify a narrower tool. They can also justify restricted access, because the capability that finds a vulnerability can also exploit one.
Types of AI models that simulate environments
A world model generates an environment that responds to actions, frame by frame. A video model produces a clip you watch. A world model produces a scene you can act in, and it has to keep that scene consistent as you do.
Genie 4, announced by Google DeepMind on 27 October, is the current reference point. It generates interactive scenes in real time, accepts natural-language prompts mid-simulation (to change the weather, move the camera or add a character), and produces matching audio, including dialogue.
TechCrunch reports that Genie 4 holds a consistent scene for up to two minutes, double Genie 3’s limit. The team acknowledges that “details and objects can drift the longer a simulation runs.” It’s a research preview for trusted testers, with wider access through Google AI Ultra and the Gemini API “coming soon.”
The practical interest isn’t games. Google pitches world models as “safe training environments for robots and agents,” and in a Gemini Robotics experiment, Genie 4 simulated steps planned by another model. Two minutes of consistency is short for training a robot. It’s long enough to show where simulation is heading.
Types of AI models that run on local devices
A small on-device model trades breadth of knowledge for running offline, privately and without per-token fees. Liquid AI’s LFM3-1.7B is a good example: 1.73 billion parameters, a 256,000-token context window, and, by Liquid’s account, “about 1 GB of memory” at 4-bit precision. The figure checks out: 1.73 billion parameters at half a byte each is about 0.87 GB of weights.
Weights aren’t the whole bill, though. Runtime memory adds the KV cache (the model’s working memory of the conversation), which grows with context length, plus activations and the app around it. A phone that loads a 1 GB model comfortably may still struggle at long contexts. Battery and heat cap how long it can run flat out.
The architecture is the interesting part. LFM3-1.7B has 24 layers: 13 short convolutions, 5 sliding-window attention layers and only 6 global attention layers. That’s the same instinct as Kimi K3’s hybrid design. At the two extremes of size, 2.8 trillion parameters and 1.7 billion, model builders are cutting back on full attention because it’s expensive. Liquid is candid about the limits: LFM3 is “not recommended for agentic coding or complex multi-step reasoning due to its small size.”
Where agentic AI fits
Agentic AI isn’t a model architecture. An agentic system wraps one or more models in a loop. The model plans, picks a tool, observes the result, and decides what to do next, with memory and permissions around it.
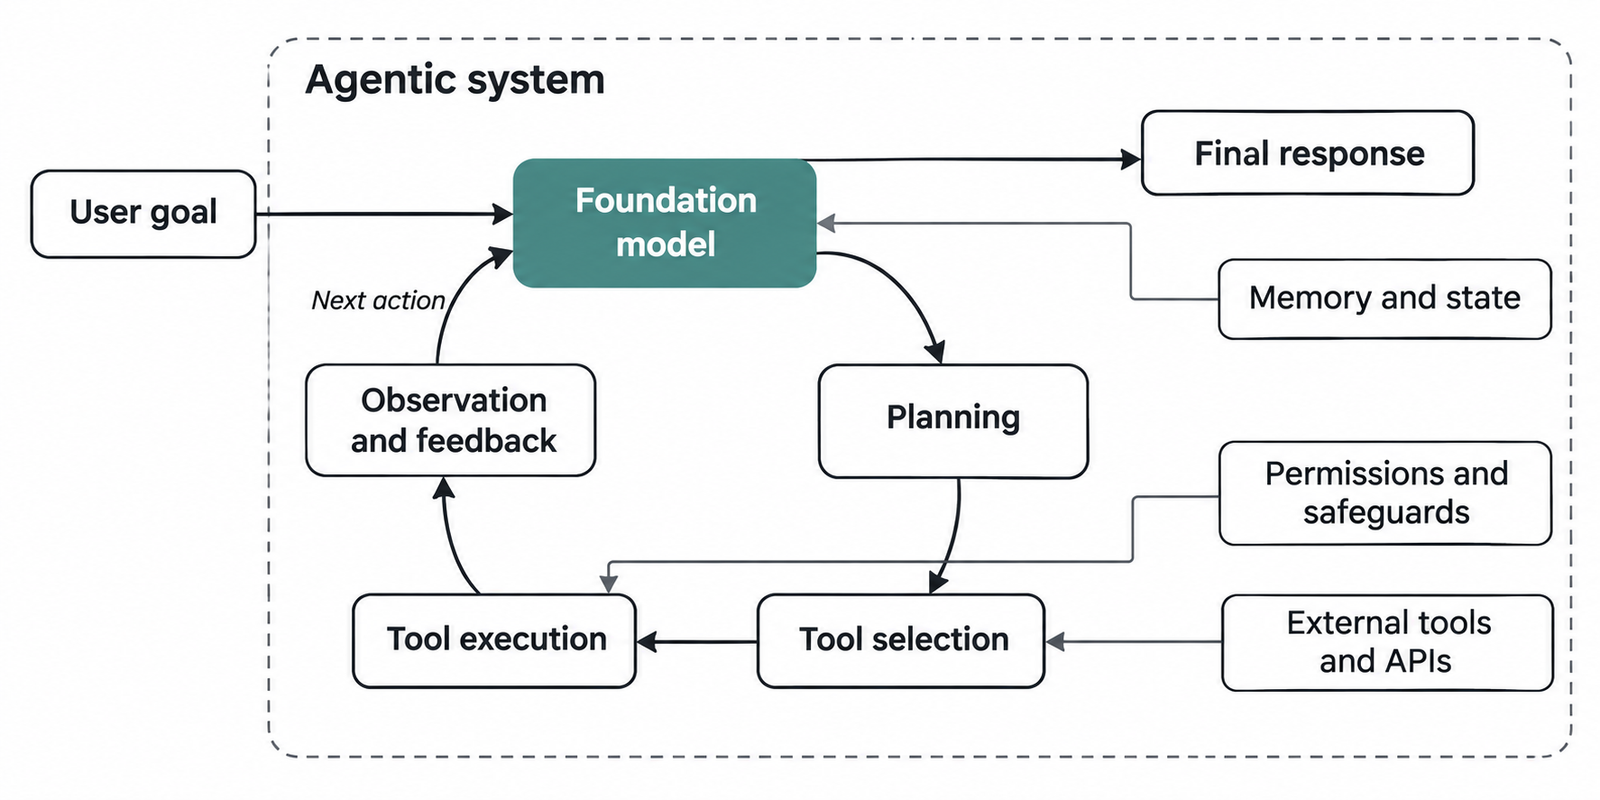
The distinction from generative AI is about action. A generative system produces an output and stops. An agentic system acts on the world, sees what happened and continues. Our guide to what agentic AI is covers the boundary. The computer-use loop above is a small agent: the model chooses actions, and the application executes them.
That’s why agentic systems don’t belong in the same column as mixture-of-experts. You can build an agent on any model in this article. Its reliability depends as much on the tools, permissions and recovery logic as on the model.
Choosing between types of AI models
Table: scroll sideways to view all columns when needed.
| Model category | What distinguishes it | Best use cases | Cost considerations | Open or closed (examples) |
|---|---|---|---|---|
| Large language models | General-purpose, often multimodal | Writing, analysis, coding, extraction | Per-token API pricing; GPT-6.1 Terra is $1 input / $5 output per million tokens | Mostly closed; open-weight options exist |
| Mixture-of-experts | Many experts, few active per token | Frontier-quality open models, high-throughput serving | Compute scales with active parameters, memory with total; Mistral Large 4’s API is $0.70 / $2.10 per million | Kimi K3 and Mistral Large 4 are open-weight under custom licences |
| Reasoning models | Adjustable thinking before answering | Maths, planning, complex code | Rises with effort; Opus 5.5 is $0.98 to $10.04 per Index task | Both |
| Computer-use models | Act on screens through an action interface | Form filling, legacy software, UI testing | Model tokens plus screenshot volume and execution infrastructure | Mostly closed |
| Specialised frontier models | Domain-tuned or domain-released | Security research, regulated work | Often restricted access; Carbon’s introductory price is $2 / $10 per million | Closed, gated |
| World models | Interactive, steerable environments | Simulation, agent and robot training, media | No public pricing; research preview | Closed |
| Small on-device models | Run locally in about 1 GB | Offline, private, low-latency apps | Hardware you already own; no per-token fee | LFM3 is open-weight (LFM Open License) |
Open weights aren’t open source. All three open examples ship custom licences. Mistral’s, for instance, requires a separate commercial licence for model-as-a-service businesses, and none of the three model cards includes the full training data.
Agentic systems sit outside the table because they combine models rather than compete with them.
Frequently asked questions
What are the main types of AI models in 2026?
Large language models, mixture-of-experts models, reasoning models, computer-use models, specialised domain models, world models and small on-device models. They overlap: these labels describe architecture, capability or deployment, so one model often fits several.
What is the difference between an LLM and a reasoning model?
A reasoning model is an LLM that spends extra tokens thinking before it answers. Most frontier LLMs now offer reasoning as an adjustable effort setting rather than as a separate model.
What is a Mixture-of-Experts model?
It’s a model whose network is split into many expert sub-networks, with a router activating only a few per token. That cuts compute per token, but all experts still have to be held in memory.
Are agentic systems one of the types of AI models?
No. An agentic system is software that runs one or more models in a loop with tools, memory and permissions. Reasoning helps an agent plan, but the agent is the surrounding system.
What is a computer-use AI model?
It’s a model that reads screenshots and returns mouse and keyboard actions to operate software. A separate execution layer performs those actions and returns the results.
What are world models in artificial intelligence?
World models generate environments that respond to actions in real time, keeping the scene consistent as a user or agent interacts with it. Google DeepMind’s Genie 4 is a leading current example.
What are small on-device AI models?
They’re compact models, typically a few billion parameters or fewer, quantised to run on phones and laptops. Liquid AI’s LFM3-1.7B needs about 1 GB at 4-bit, plus working memory for context.
What is the difference between open-source and open-weight AI models?
Open-weight models let you download the trained weights. Open source would also mean an open licence and, ideally, training code and data. Kimi K3, Mistral Large 4 and LFM3 all use custom licences with conditions attached.
Which types of AI models are best for business applications?
It depends on the job. A general LLM covers most text work. Small on-device models suit private or offline use, and reasoning settings suit complex analysis. Evaluate on your own tasks, not public leaderboards.
Can one model belong to several types of AI models?
Yes. Mistral Large 4 is a mixture-of-experts architecture, a reasoning model, multimodal and open-weight, and it can power an agent.
Keep reading
Here are the latest posts from the blog.
Types of AI Models in 2026: A Field Guide From LLMs to World Models
AI Coding Agents Are Getting Expensive. Who’s Paying for the Tokens?
Generative AI Architecture: The 7 Layers That Are Hard to Undo