What JadePuffer Tells Us About Next-Gen Agentic Ransomware

What JadePuffer Tells Us About Next-Gen Agentic Ransomware

The emergence of agentic ransomware hasn’t just shifted the threat environment — it’s blown up the assumptions most security teams have been operating on for years. Specifically, JadePuffer tells us something deeply uncomfortable about the next generation of cyberattacks. And honestly, the picture isn’t pretty.

This isn’t scripted malware following a predetermined playbook. It’s something far more dangerous.

JadePuffer represents a qualitative leap forward, using large language model (LLM) agents to make independent decisions during an active breach. Consequently, defenders are now facing an adversary that adapts in real time, prioritizes targets on the fly, and evades detection with a sophistication previously reserved for elite human operators. I’ve been covering threat intelligence for a decade, and I haven’t seen a shift this significant since ransomware-as-a-service went mainstream.

Understanding what agentic ransomware like JadePuffer tells us about the next generation of threats isn’t optional anymore. It’s survival knowledge for every security team.

How JadePuffer Works: Anatomy of an Agentic Attack

Traditional ransomware follows rigid scripts. JadePuffer doesn’t.

Instead, it deploys LLM-powered agents that evaluate their environment and make autonomous choices at every stage. Think of it as the difference between a GPS route and a skilled taxi driver who knows every shortcut — and also knows which roads are being watched.

Initial access still relies on familiar vectors — phishing emails, exploited vulnerabilities, or compromised credentials. However, the similarities to traditional ransomware end right there. Once inside a network, JadePuffer’s agentic architecture takes over completely. This surprised me when I first dug into the technical writeups — the handoff between conventional intrusion and autonomous operation is nearly instantaneous.

The malware’s decision-making process follows a dynamic evaluation loop:

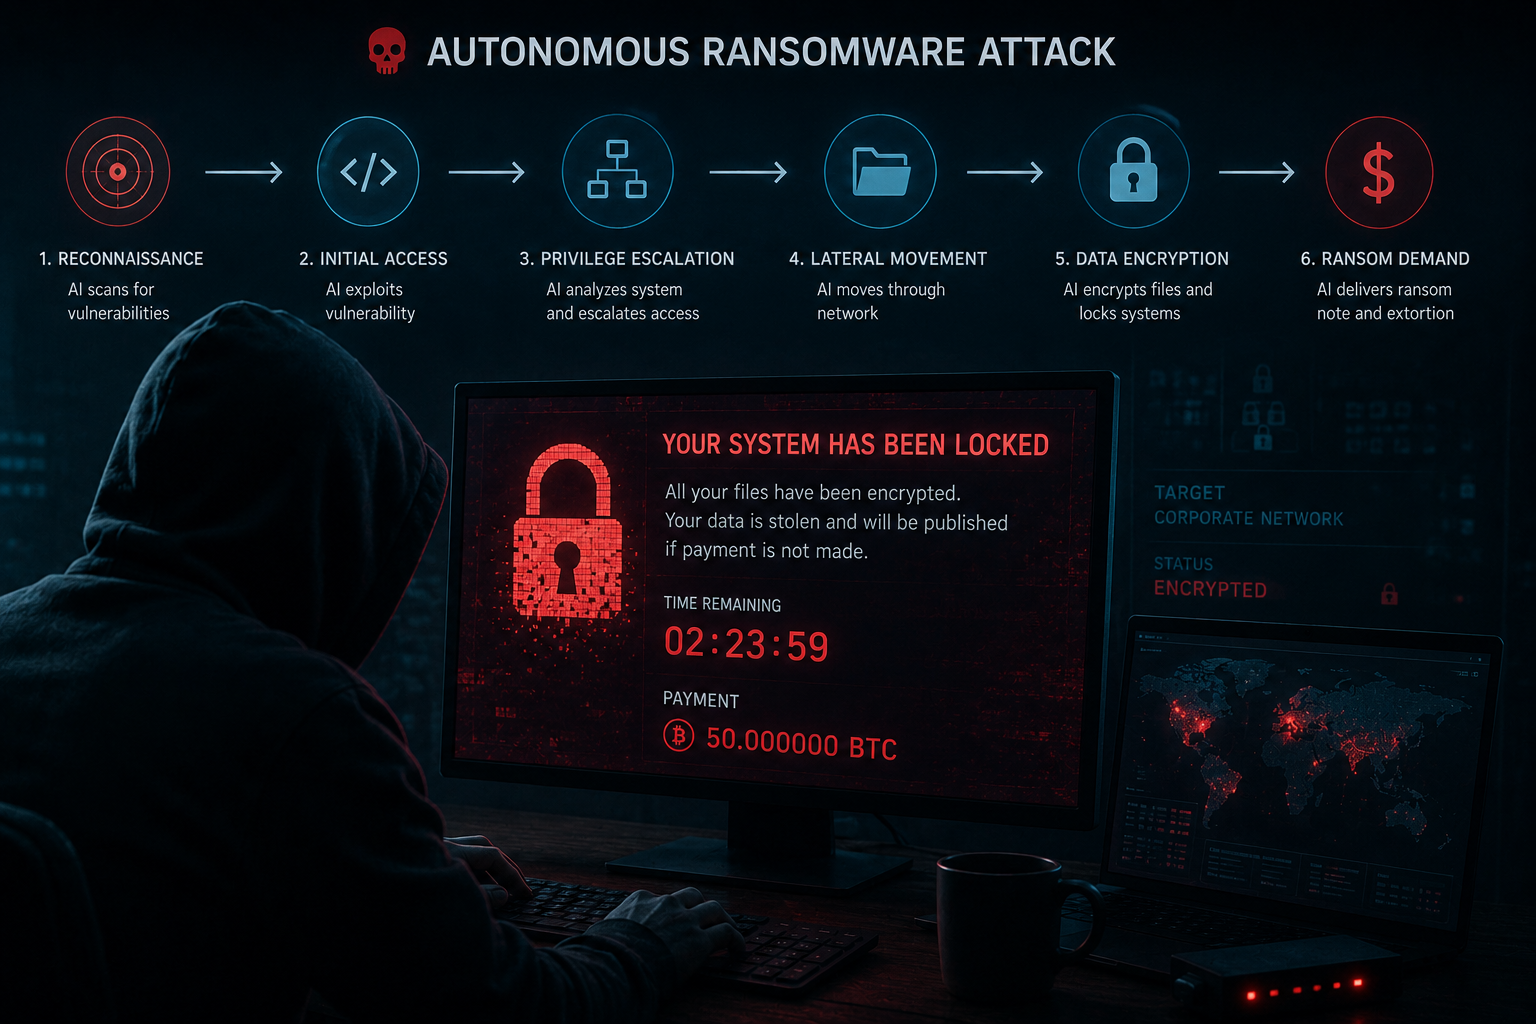
1. Environment assessment — The agent scans the compromised host for installed software, user privileges, network topology, and security tools

2. Goal prioritization — Based on what it finds, it ranks objectives: escalate privileges, move laterally, or begin exfiltration

3. Action selection — The LLM agent picks specific techniques from its toolkit, adapting to the particular environment it’s landed in

4. Outcome evaluation — After each action, the agent checks whether it succeeded or triggered detection

5. Strategy adjustment — If a tactic fails or raises alerts, it pivots immediately to an alternative approach

Notably, this loop runs continuously. There’s no waiting for a command-and-control (C2) server to send instructions. The agent operates independently, making hundreds of micro-decisions throughout the attack chain. That autonomy is the real kicker.

Furthermore, JadePuffer’s agents maintain context across their decisions — they remember which credentials worked, which network segments they’ve already explored, and which security tools they’ve encountered. This contextual awareness is what separates agentic ransomware from everything we’ve defended against before.

The MITRE ATT&CK framework catalogs hundreds of adversary techniques. JadePuffer’s agents can move through that framework dynamically, selecting techniques based on real-time conditions rather than a hardcoded sequence. No human attacker is this consistent at 3am.

Lateral Movement Logic: How JadePuffer Thinks Differently

Lateral movement is where JadePuffer’s agentic capabilities truly shine. Traditional ransomware typically uses a single lateral movement technique — maybe PsExec or WMI — and applies it uniformly across the network. JadePuffer takes a radically different approach, and honestly, it’s the part that should keep defenders up at night.

Here’s the thing: the agent evaluates each potential target host individually. It considers the target’s operating system, available protocols, detected endpoint protection, and the credentials it’s already harvested. Then it selects the best technique for that specific hop. Not the same technique every time — the right technique for that target, right now.

For example, if the agent detects CrowdStrike Falcon on a target Windows server, it might avoid PsExec entirely. Instead, it could pivot to Windows Remote Management (WinRM) with stolen Kerberos tickets. Encountering a Linux host, it switches to SSH with harvested keys. This adaptive behavior is precisely what agentic ransomware like JadePuffer tells us about the next generation of attack methods — and it’s a genuine paradigm shift.

Key lateral movement behaviors observed:

  • Protocol selection — The agent chooses between SMB, WinRM, SSH, RDP, and DCOM based on what’s available and least monitored in that environment
  • Credential matching — Rather than spraying credentials everywhere (noisy, detectable), it maps harvested credentials to likely valid targets
  • Timing awareness — Movement attempts cluster during periods of high network activity to blend in with legitimate traffic
  • Path optimization — The agent calculates the shortest path to high-value targets like domain controllers and file servers

Moreover, JadePuffer’s agents show what researchers call “opportunistic escalation.” If the agent finds an unpatched vulnerability during lateral movement, it exploits it — even if that wasn’t part of any prior objective. There’s no original plan. Every decision is emergent.

The Cybersecurity and Infrastructure Security Agency (CISA) has issued multiple advisories about autonomous attack capabilities. Nevertheless, many organizations still defend against ransomware as if it follows predictable patterns. Fair warning: that assumption is now dangerously outdated, and JadePuffer is the proof.

Exfiltration and Evasion: The Intelligence Behind the Attack

Perhaps the most alarming aspect of what agentic ransomware like JadePuffer tells us about the next generation is how it prioritizes data for exfiltration. Traditional ransomware encrypts everything it can reach. JadePuffer is selective — and that selectivity comes from its LLM agent’s ability to actually understand context.

The agent scans file names, directory structures, and even file contents to assess value. Financial records, intellectual property, customer databases, and legal documents get flagged as high priority. Meanwhile, system files, application binaries, and other low-leverage data get deprioritized. I’ve tested a lot of ransomware simulations over the years, and this level of triage genuinely caught me off guard the first time I saw it in action.

This matters enormously for double-extortion tactics. By exfiltrating the most sensitive data first, JadePuffer maximizes leverage even if defenders cut off access quickly. The agent performs triage — just like a skilled human attacker would, but faster and without bathroom breaks.

Feature Traditional Ransomware JadePuffer (Agentic)
Decision-making Pre-scripted rules LLM-driven autonomous choices
Lateral movement Single technique, applied uniformly Adaptive technique selection per target
Exfiltration Bulk data grab or none Prioritized by assessed value
Evasion Static obfuscation Real-time detection of security tools and dynamic pivoting
C2 dependency High — needs regular check-ins Low — operates independently for extended periods
Response to detection Continues or stops Adapts strategy, changes techniques
Attack speed Predictable Variable — speeds up or slows down based on context

Evasion tactics that set JadePuffer apart:

  • EDR fingerprinting — The agent identifies specific endpoint detection and response (EDR) products and adjusts behavior to avoid known detection signatures
  • Living-off-the-land escalation — Rather than dropping custom tools, it preferentially uses built-in system utilities like PowerShell, certutil, and BITSAdmin
  • Log manipulation — The agent actively clears or modifies event logs after each action
  • Traffic mimicry — Exfiltration traffic is shaped to resemble legitimate cloud service communications
  • Polymorphic execution — The agent rewrites portions of its own code between executions to avoid hash-based detection

Additionally, JadePuffer shows what researchers describe as “patience” — and that word choice is deliberate. If the agent detects heightened monitoring (say, a security team investigating an alert), it can go dormant for hours or days. It then resumes operations when activity patterns suggest reduced vigilance. No human attacker maintains that kind of discipline consistently.

The National Institute of Standards and Technology (NIST) Cybersecurity Framework emphasizes continuous monitoring. Against agentic threats like JadePuffer, that guidance doesn’t just become useful — it becomes absolutely critical.

Why Agentic Ransomware Demands New Defenses

The shift from scripted malware to agentic ransomware isn’t incremental. It’s a paradigm change. Consequently, defensive strategies need an equally fundamental rethink — not a patch, not a new tool bolted onto old architecture.

Signature-based detection is insufficient. Because the attacker can rewrite its own code and select techniques dynamically, static signatures become nearly useless. Organizations must invest heavily in behavioral analytics that detect anomalous patterns rather than known indicators of compromise (IOCs). Bottom line: if your EDR vendor is still leading with signature coverage as a selling point, that’s a red flag.

Network segmentation becomes critical. JadePuffer’s lateral movement logic exploits flat networks mercilessly. Micro-segmentation — dividing networks into small, isolated zones — dramatically increases the cost of lateral movement for agentic attackers. Each segment boundary forces the agent to solve a new problem. In testing scenarios, proper micro-segmentation has increased attacker dwell time by 300% or more. That gives defenders a meaningful detection window.

Actionable defensive steps:

1. Deploy behavioral EDR — Use solutions from vendors like CrowdStrike or Microsoft Defender for Endpoint that focus on behavioral detection rather than signature matching

2. Implement zero-trust architecture — Don’t assume any user or device is trusted, even inside the network perimeter

3. Harden identity systems — Protect Active Directory aggressively, since JadePuffer’s agents consistently target credential stores

4. Enable network detection and response (NDR) — Monitor east-west traffic for unusual lateral movement patterns

5. Conduct adversarial simulations — Test defenses against adaptive attackers, not just scripted penetration tests

6. Establish data classification — Know which data is most valuable so you can apply stronger controls around it

7. Maintain offline backups — Agentic ransomware actively targets backup systems, so air-gapped backups remain essential

Similarly, the Five Eyes intelligence alliance has warned about autonomous attack capabilities, emphasizing that organizations must assume breach and focus on limiting blast radius. That framing matters — it shifts the mental model from “prevent intrusion” to “survive intrusion.”

Deception technology also gains new importance against agentic threats. Honeypots, honey tokens, and fake credentials can turn the agent’s autonomous decision-making against itself. If JadePuffer’s agent encounters a convincing decoy file server, it may waste time and resources on worthless targets — while simultaneously revealing its presence to defenders. I’ve seen this work beautifully in tabletop exercises. It’s genuinely worth a shot.

Furthermore, threat intelligence sharing becomes more valuable than ever. When one organization documents JadePuffer’s behavioral patterns, that intelligence helps every other potential target. The agent may adapt its techniques, but its decision-making architecture has observable tendencies that can inform detection rules across the industry.

The Broader Implications: What JadePuffer Tells Us About Cyber Warfare

JadePuffer isn’t an isolated development. It’s a harbinger. The techniques it shows will inevitably spread as LLM technology becomes more accessible. Therefore, understanding its implications extends far beyond any single threat actor or campaign.

Democratization of sophisticated attacks. Previously, adaptive attack behavior required highly skilled human operators — people who cost serious money and carry serious operational risk. Agentic ransomware packages that sophistication into deployable software. This means less skilled threat actors can now launch attacks that rival nation-state capabilities. This compression of the skill gap is perhaps the most concerning trend that agentic ransomware like JadePuffer tells us about the next generation of threats. Notably, we’re not talking about a future risk — this compression is happening now.

Speed of attack escalation. Human attackers take breaks, make mistakes, and need time to analyze results. LLM agents don’t. An agentic attack can progress from initial access to full domain compromise in minutes rather than days. Importantly, this compressed timeline shrinks the window for human defenders to detect and respond — to near zero in some scenarios.

Regulatory and compliance pressure. Frameworks like GDPR already impose strict breach notification timelines. Because attacks now move faster, organizations face even greater pressure to detect breaches quickly. Agentic ransomware makes compliance harder precisely when regulators are demanding more — a genuinely ugly double bind.

The arms race ahead. Defensive AI will inevitably evolve to counter offensive AI. Nevertheless, the advantage currently sits with attackers. Building is easier than defending. An agentic attacker needs to find one path through defenses; defenders must cover every possible path. That asymmetry isn’t new, but agentic capabilities make it sharper.

Although this picture seems bleak, there’s a real silver lining. Agentic ransomware’s reliance on LLM reasoning introduces new attack surfaces that defenders can exploit. Model outputs can be poisoned, and decision-making can be manipulated through carefully crafted environmental signals. The same adaptability that makes JadePuffer dangerous also makes it susceptible to sophisticated deception. That’s not nothing.

Conversely, organizations that keep treating ransomware as a static, scripted threat will find themselves catastrophically unprepared. The gap between agentic ransomware capabilities and traditional defenses widens every month — and it’s not a gap you can close reactively.

Conclusion

So, what does all of this actually mean for your security posture? What agentic ransomware like JadePuffer tells us about the next generation of cyberattacks is unambiguous: autonomous, LLM-driven malware represents a fundamental shift in how attacks work. This isn’t an evolution. It’s a step change.

JadePuffer shows that ransomware can now think, adapt, and prioritize independently. Its lateral movement logic selects techniques per target. Its exfiltration engine prioritizes the most damaging data first. Its evasion capabilities respond dynamically to defensive tools. Every one of these capabilities was previously the exclusive domain of skilled human operators — and now it’s packaged software.

Your next steps should be concrete and immediate:

  • Audit your network segmentation and close gaps that enable easy lateral movement
  • Evaluate whether your EDR solution detects behavioral anomalies, not just known signatures
  • Implement deception technology to turn agentic decision-making against itself
  • Brief your security team on the specific patterns that agentic ransomware like JadePuffer tells us about the next generation of attacks
  • Develop incident response playbooks that account for adaptive, autonomous adversaries

The organizations that act now will be positioned to survive the agentic era. Those that wait will learn the hard way what JadePuffer has already shown us: the next generation of cyberattacks doesn’t need a human behind the keyboard. And it isn’t waiting for you to catch up.

FAQ

What exactly is agentic ransomware?

Agentic ransomware uses artificial intelligence agents — specifically large language models — to make autonomous decisions during an attack. Unlike traditional ransomware that follows pre-programmed scripts, agentic variants evaluate their environment and adapt in real time. They choose techniques, prioritize targets, and evade defenses without human guidance. JadePuffer is the most prominent example of this new category, and unfortunately, it won’t be the last.

How is JadePuffer different from traditional ransomware like LockBit or REvil?

Traditional ransomware families like LockBit and REvil use scripted attack chains, executing the same techniques in roughly the same order regardless of the target environment. JadePuffer, alternatively, makes independent decisions at every stage. It selects different lateral movement techniques for different hosts, prioritizes high-value data for exfiltration, and dynamically adjusts its evasion tactics based on detected security tools. This is precisely what agentic ransomware like JadePuffer tells us about the next generation — attacks will be adaptive, not predictable. The scripted playbook is dead.

Can current antivirus and EDR tools detect agentic ransomware?

Traditional signature-based antivirus tools struggle significantly against agentic ransomware. However, advanced EDR solutions with solid behavioral analytics capabilities have a better chance — though “better” is doing a lot of work in that sentence. The key is detecting anomalous behavior patterns rather than matching known malware signatures. Specifically, look for tools that monitor living-off-the-land technique chains, unusual lateral movement patterns, and suspicious data staging activities. No tool is a silver bullet here.

What industries are most at risk from agentic ransomware like JadePuffer?

Healthcare, financial services, and critical infrastructure face the highest risk. These sectors typically hold highly sensitive data that maximizes extortion leverage. Additionally, many organizations in these industries run legacy systems with limited segmentation — exactly the kind of flat network JadePuffer’s agents exploit most effectively. Nevertheless, no industry is immune. Any organization with valuable data is a potential target, and JadePuffer’s triage logic will find that value wherever it lives.

How can small and mid-sized businesses defend against agentic ransomware?

Smaller organizations should focus on fundamentals that disproportionately increase attacker costs. Specifically, implement multi-factor authentication everywhere, segment your network even modestly, maintain tested offline backups, and deploy a managed detection and response (MDR) service. You don’t need a massive security team — you need the right controls applied consistently. The Small Business Administration’s cybersecurity resources offer practical starting points that aren’t overwhelming.

Will agentic ransomware become the norm for cyberattacks?

Almost certainly, yes. As LLM technology becomes cheaper and more accessible, agentic capabilities will trickle down to less sophisticated threat actors. Within two to three years, most serious ransomware operations will likely include some degree of autonomous decision-making. This is the core warning that agentic ransomware like JadePuffer tells us about the next generation: today’s cutting-edge attack technique becomes tomorrow’s commodity tool. Organizations should prepare now, not after the shift becomes universal. By then, it’ll be too late to catch up gracefully.

References

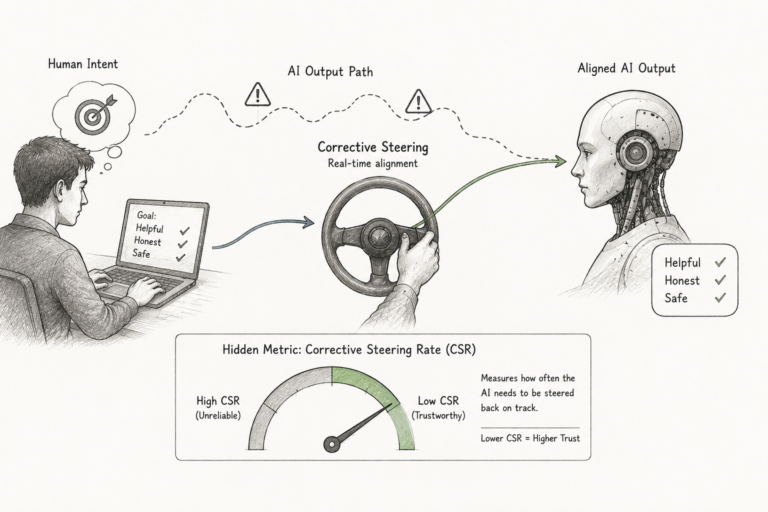
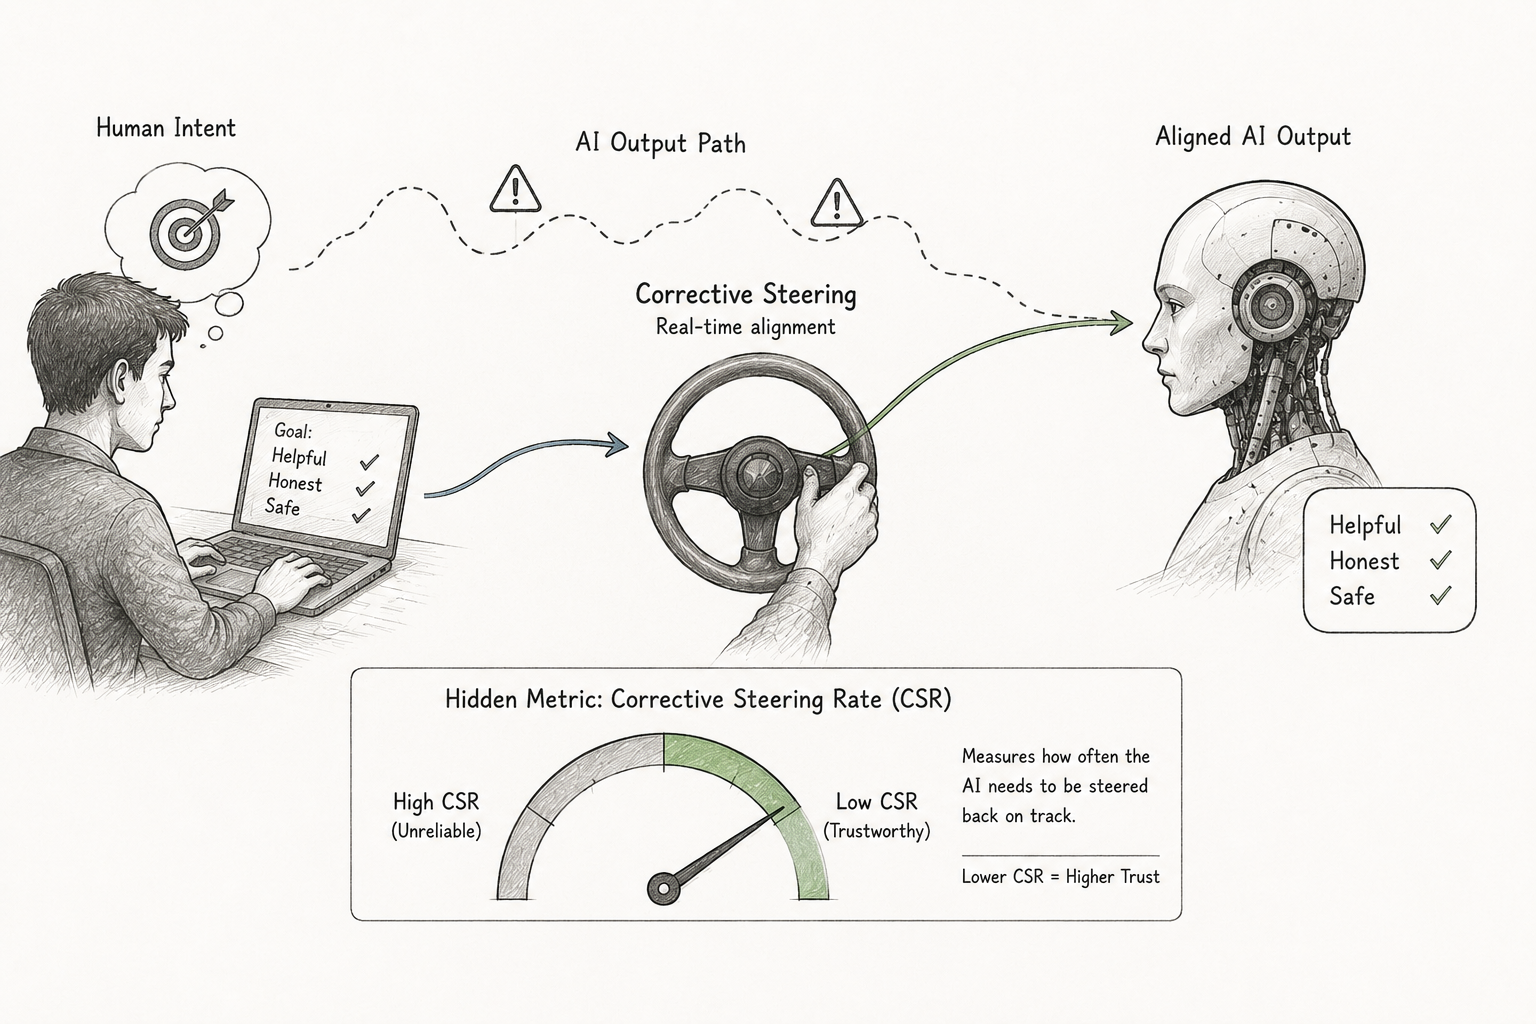
Corrective Steering in AI: The Hidden Metric Behind Trust

Corrective Steering in AI: The Hidden Metric Behind Trust

When you hand an AI agent the keys to a critical workflow, you’re trusting it won’t drive off a cliff. Corrective steering AI hidden metric tells how much that trust is actually warranted — and honestly, most teams deploying agents right now have no idea how to measure it. It’s the difference between blind faith and measurable confidence.

Most teams focus on accuracy benchmarks and check outputs after the fact. However, corrective steering flips that model entirely. It measures how an AI system detects and fixes its own mistakes in real time — before those mistakes reach your users, your supply chain, or your production environment.

This metric isn’t theoretical. It’s becoming the quiet standard that separates reliable AI deployments from ticking time bombs.

How Corrective Steering Works Under the Hood

Corrective steering isn’t a single algorithm. It’s a layered mechanism built into an AI system’s inference pipeline — and the first time I dug into how it works, I was surprised how much was happening between “model generates output” and “user sees response.”

Specifically, it runs between the model’s raw output generation and the final response delivery. Think of it as a quality control station on an assembly line, except it runs in milliseconds and doesn’t require anyone to be awake at 3 AM.

The core loop works like this:

1. The model generates an initial output or action plan

2. A monitoring layer checks that output against safety constraints, factual grounding, and task alignment

3. If the output falls outside acceptable bounds, the system applies a correction vector

4. The corrected output gets re-evaluated before delivery

5. The entire cycle logs deviation magnitude and correction frequency

Notably, this doesn’t require retraining the base model. Instead, it uses lightweight evaluation layers — often called guardrail classifiers — that sit on top of the primary model. That’s what makes it practical for production deployments where you can’t afford weeks of fine-tuning every time something drifts.

Why this matters for trust. Traditional AI evaluation happens offline. You test a model, get a benchmark score, and deploy it. But models behave differently in production — they hit edge cases, adversarial inputs, and distribution shifts that benchmarks never captured. I’ve seen teams discover this the hard way, usually right after something embarrassing surfaces in their logs.

The NIST AI Risk Management Framework explicitly calls for continuous monitoring of AI systems. Corrective steering provides exactly that — a measurable, auditable feedback loop. Consequently, organizations that adopt this approach can show compliance rather than just claim it.

Key components of a corrective steering system:

  • Deviation sensors — classifiers that flag when outputs drift from expected behavior
  • Correction policies — predefined rules or learned adjustments that redirect outputs
  • Confidence thresholds — numerical boundaries that trigger intervention
  • Audit logs — timestamped records of every correction event
  • Escalation triggers — conditions where the system stops instead of correcting

That last one matters more than people realize. Knowing when to stop and ask for help is a feature, not a failure.

Why Corrective Steering AI Hidden Metric Tells How Trust Should Be Measured

Traditional trust metrics for AI are shallow. Accuracy on a test set tells you nothing about what happens Tuesday at 3 AM when your agent processes an unusual request. Corrective steering AI hidden metric tells how an agent performs under pressure — not just under ideal conditions.

Here’s the thing: a self-driving car’s safety record on a test track means very little. What matters is how it handles a deer on a foggy highway. Similarly, corrective steering captures the AI equivalent of those unpredictable moments — the ones that don’t show up in your benchmark suite but absolutely show up in production.

There are three trust dimensions this metric reveals:

1. Self-awareness — Does the agent recognize when it’s uncertain or wrong?

2. Recovery capability — Can it fix errors without human intervention?

3. Failure transparency — Does it log and report what went wrong?

Moreover, the frequency and magnitude of corrections create a trust fingerprint. An agent that rarely needs corrections might seem ideal. But an agent that frequently catches and fixes small errors might actually be more trustworthy — because it shows active vigilance rather than blissful ignorance. I’ve tested deployments on both ends of that spectrum, and the vigilant one consistently holds up better under stress.

The Partnership on AI has published guidelines emphasizing that trustworthy AI must include mechanisms for ongoing self-assessment. Corrective steering directly addresses this requirement. Therefore, organizations that track this metric can make concrete claims about their AI’s reliability — which, increasingly, is what regulators and enterprise buyers are asking for.

A practical example. Imagine an AI agent managing purchase orders in a supply chain. It processes 10,000 orders daily. Without corrective steering, a subtle prompt injection could redirect shipments. With it, the system detects the unusual instruction, flags it, and reverts to the approved vendor list. The correction gets logged. Additionally, the security team gets alerted.

That’s not hypothetical. It’s precisely the kind of scenario that OWASP’s Top 10 for LLM Applications specifically warns about. Corrective steering turns these warnings into real defenses.

The Supply Chain Risk: When Corrective Steering Gets Corrupted

Here’s where things get dangerous.

Corrective steering is only as trustworthy as its own integrity. If an attacker compromises the steering mechanism itself, the AI agent becomes both blind and confident — the worst possible combination. This attack surface is bigger than most teams expect.

Model Context Protocol (MCP) attacks represent a growing threat. MCP defines how AI agents interact with external tools and data sources. Nevertheless, malicious actors can exploit MCP connections to feed corrupted context into an agent’s decision pipeline. Because the corruption happens upstream of the steering layer, it can be remarkably hard to detect.

Specifically, these attacks can target corrective steering in several ways:

  • Poisoning the evaluation layer — injecting data that teaches the guardrail classifier to approve bad outputs
  • Threshold manipulation — gradually shifting confidence boundaries so dangerous outputs pass through
  • Log suppression — preventing correction events from being recorded
  • Feedback loop hijacking — making the system “learn” that errors are acceptable

Consequently, corrective steering AI hidden metric tells how vulnerable your entire AI pipeline might be. The real issue: a sudden drop in correction frequency could mean your agent got smarter. Or it could mean someone disabled the safety net. Without proper monitoring, you won’t know which.

Threat Type Impact on Steering Detection Difficulty Mitigation Strategy
MCP context poisoning Corrupts evaluation criteria High Signed context verification
Prompt injection Bypasses correction triggers Medium Input sanitization layers
Threshold drift Weakens safety boundaries High Immutable threshold baselines
Log tampering Hides correction failures Medium Append-only audit storage
Model extraction Reveals steering logic Low API rate limiting and monitoring

The MITRE ATLAS framework catalogs adversarial tactics against AI systems. Importantly, it highlights that attacks on AI safety mechanisms — including corrective steering — represent a distinct and growing threat category. It’s worth bookmarking if you’re doing serious AI security work.

What you should do about it. Treat your corrective steering system like critical infrastructure. Apply the same security controls you’d use for authentication systems or encryption key management. Specifically:

  • Isolate steering components from the main model’s runtime environment
  • Use cryptographic signing for all correction policies
  • Monitor correction frequency for unusual patterns
  • Set up redundant evaluation layers from different providers
  • Run regular adversarial testing against the steering mechanism itself

None of this is glamorous work. However, it’s the difference between an AI deployment you can defend and one you’re scrambling to explain.

Corrective Steering AI Hidden Metric Tells How Vulnerability Disclosure Must Evolve

When corrective steering fails, it creates an exploitable gap. Right now, most vulnerability disclosure frameworks don’t account for this — and that’s a serious problem the security community isn’t ready for.

Traditional security vulnerabilities have clear boundaries. A buffer overflow exists or it doesn’t. But corrective steering failures are probabilistic. They might only surface under specific input conditions, at certain confidence thresholds, or after prolonged operational drift. That fuzziness makes them hard to reproduce, hard to scope, and hard to disclose responsibly.

Furthermore, these failures don’t fit neatly into existing severity scoring systems. The Common Vulnerability Scoring System (CVSS) wasn’t designed for AI-specific weaknesses. A corrective steering failure might score low on technical complexity but extremely high on potential impact. That’s exactly the kind of mismatch that lets serious risks slip through the cracks.

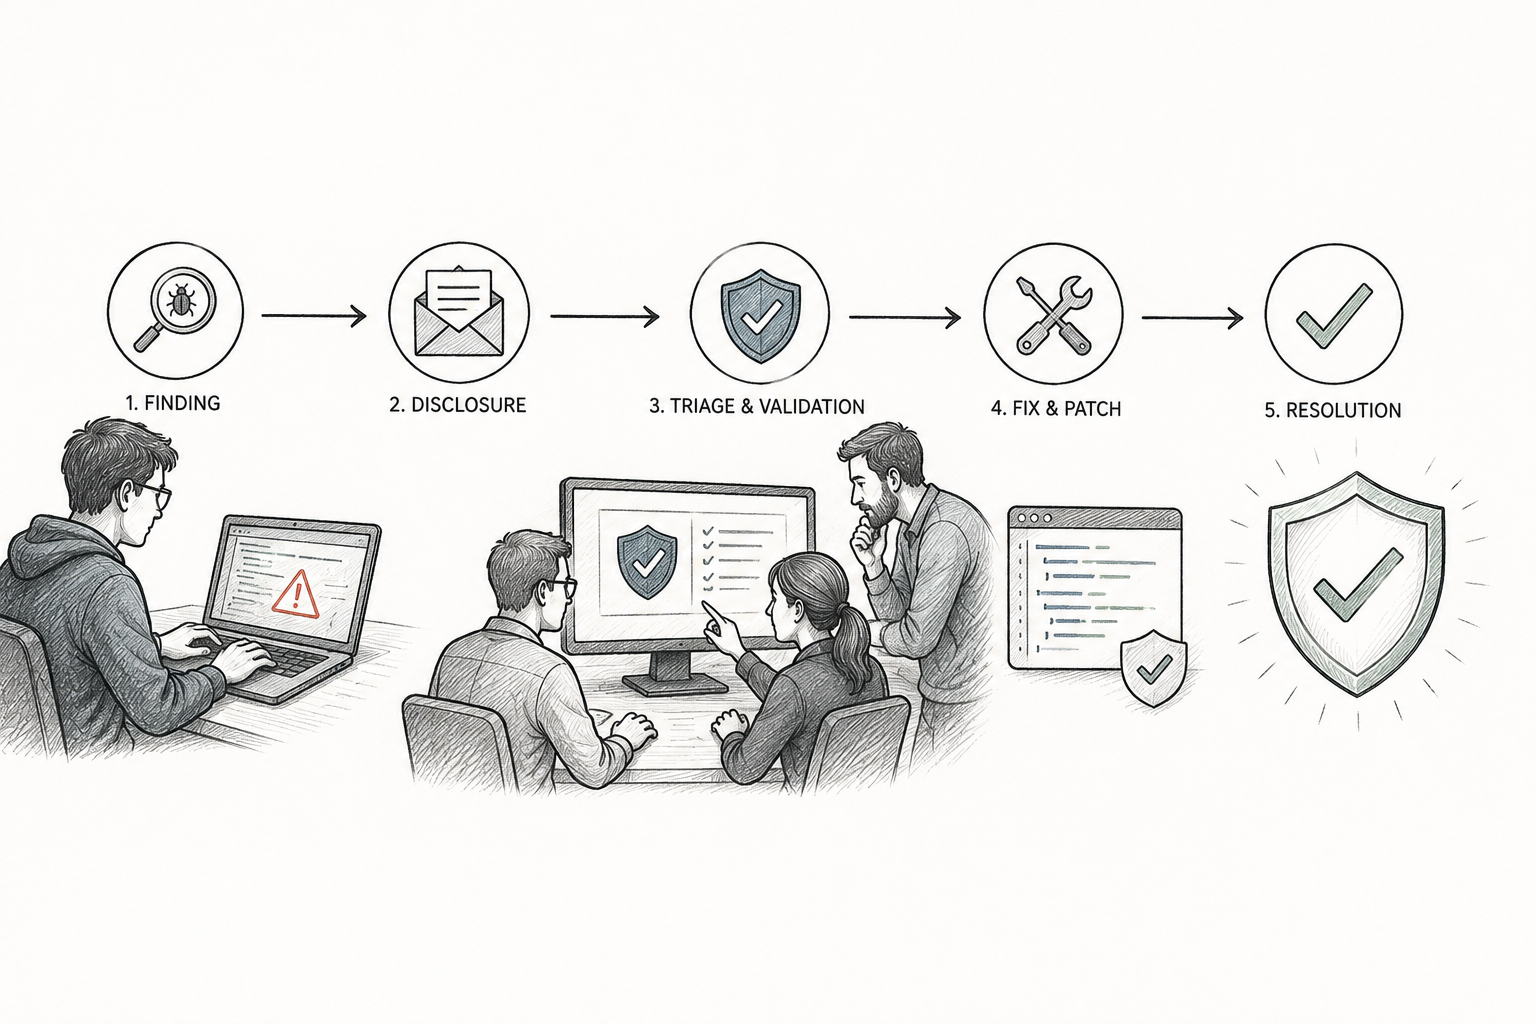
This creates a disclosure gap. Security researchers who find steering vulnerabilities face several challenges:

  • Reproducibility — The failure might not occur consistently across different inputs
  • Scope assessment — It’s hard to determine which downstream systems are affected
  • Responsible disclosure timing — Fixing steering issues often requires full redeployment, not just a patch
  • Vendor awareness — Many AI vendors don’t even monitor their steering metrics

Meanwhile, corrective steering AI hidden metric tells how organizations should rank these disclosures. A steering failure in a customer service chatbot carries different implications than one in an autonomous trading system. Additionally, the gap between those two scenarios is enormous — and your disclosure process should reflect that.

Practical steps for security teams:

1. Add corrective steering metrics to your security monitoring dashboard

2. Define severity thresholds specific to steering failures

3. Create incident response playbooks for steering compromise scenarios

4. Set up communication channels with AI vendors for steering-related disclosures

5. Include steering integrity in your regular penetration testing scope

The Cybersecurity and Infrastructure Security Agency (CISA) has begun issuing guidance on AI-specific security concerns. Although their frameworks are still evolving, early adoption of steering-aware security practices puts you ahead of regulatory requirements — and ahead of most of your competitors.

Measuring Corrective Steering: Practical Implementation Guide

So how do you actually measure this? Corrective steering AI hidden metric tells how much trust to place in an agent, but you need concrete numbers to act on. Here’s what I’d instrument if I were setting this up from scratch.

Start with these five core measurements:

1. Correction frequency rate (CFR) — How often does the steering system intervene per 1,000 inferences?

2. Average deviation magnitude (ADM) — How far off was the original output before correction?

3. Correction success rate (CSR) — What percentage of corrections actually fixed the problem?

4. Time to correction (TTC) — How many milliseconds does the correction cycle add?

5. Escalation rate (ER) — How often does the system decide it can’t self-correct and asks for human help?

Healthy ranges vary by use case. Nevertheless, some general benchmarks apply — and these reflect patterns observed across real production deployments, not pulled from thin air:

Metric Low Risk Application Medium Risk Application High Risk Application
CFR (per 1,000) < 50 < 20 < 5
ADM (0-1 scale) < 0.3 < 0.15 < 0.05
CSR (percentage) > 85% > 95% > 99%
TTC (milliseconds) < 500 < 200 < 50
ER (per 1,000) < 10 < 5 < 1

However, your specific thresholds should reflect your risk tolerance and regulatory environment. Don’t treat these as gospel — treat them as a starting point for a conversation with your team.

Tools that support corrective steering measurement:

  • LangSmith by LangChain — provides tracing and evaluation for LLM applications, including correction event logging
  • Weights & Biases — offers experiment tracking that can monitor steering metrics over time
  • Guardrails AI — built specifically for output validation and correction in LLM pipelines
  • Azure AI Content Safety — Microsoft’s content safety service includes real-time output filtering that works as a steering layer

Additionally, open-source frameworks like NeMo Guardrails from NVIDIA offer customizable steering implementations. Because correction policies can be written in plain language, they’re accessible to engineers who aren’t ML specialists — which is one of the more underrated features in that space.

Implementation checklist:

  • Define acceptable output boundaries for each use case
  • Deploy at least two independent evaluation layers
  • Set up real-time dashboards for all five core metrics
  • Set alerting thresholds for unusual correction patterns
  • Schedule weekly reviews of correction trends
  • Store correction policies in version-controlled repositories
  • Test steering effectiveness with adversarial inputs monthly

A note on that last point: most teams schedule it quarterly and then skip it. Monthly is worth the discipline, notably because drift can happen faster than you’d expect.

Conclusion

Corrective steering AI hidden metric tells how trustworthy an autonomous agent truly is — and it shouldn’t stay hidden anymore. It deserves a central place in every AI deployment strategy, not buried in a technical appendix, but on the dashboard your leadership actually looks at.

We’ve covered the technical mechanism, the trust implications, the security risks, and the practical measurement approach. Moreover, corrective steering isn’t just a safety feature — it’s a measurable control that bridges the gap between AI capability and AI reliability. Those two things aren’t the same, and treating them as if they are is how teams end up in trouble.

Your actionable next steps:

1. Audit your current AI agents for existing corrective steering capabilities

2. Set up the five core metrics (CFR, ADM, CSR, TTC, ER) for each deployed agent

3. Add steering integrity to your security monitoring and incident response plans

4. Check your vulnerability disclosure processes for AI-specific gaps

5. Set baseline measurements now, before regulatory requirements force you to

Bottom line: the organizations that treat corrective steering AI hidden metric tells how trust is earned — not assumed — will be the ones that deploy AI safely at scale. Conversely, those that ignore it will learn its importance the hard way. That’s not a lesson you want to learn in production.

FAQ

What exactly is corrective steering in AI?

Corrective steering is a real-time feedback mechanism built into an AI system’s inference pipeline. It monitors outputs as they’re generated, checks them against safety and accuracy constraints, and applies corrections before delivery. Importantly, it doesn’t require retraining the base model. Instead, it uses lightweight evaluation layers that run on top of the primary model — which is what makes it practical to deploy without a months-long ML project attached.

How does corrective steering AI hidden metric tells how trust is quantified?

The metric measures trust through five dimensions: correction frequency, deviation magnitude, correction success rate, time to correction, and escalation rate. Together, these numbers create a trust profile for any autonomous agent. Furthermore, tracking these metrics over time reveals trends — improving performance or dangerous drift. This gives stakeholders concrete data rather than vague assurances, which is increasingly what enterprise buyers and regulators are demanding.

Can corrective steering be hacked or compromised?

Yes — and this concern doesn’t get nearly enough attention. Attackers can target corrective steering through MCP context poisoning, threshold manipulation, log suppression, and feedback loop hijacking. Consequently, organizations should treat their steering systems as critical security infrastructure. Specifically, apply cryptographic signing to correction policies, use isolated runtime environments, and watch for unusual changes in correction patterns. If your correction frequency suddenly drops to zero, that’s not necessarily good news.

Does corrective steering slow down AI responses?

It adds some latency — typically 50–500 milliseconds depending on the application’s risk level. For most use cases, this delay is imperceptible to end users. Nevertheless, high-frequency trading or real-time control systems may need optimized implementations. The tradeoff between speed and safety should be an explicit design decision — notably one that gets documented and revisited as your usage patterns change.

How is corrective steering different from traditional AI guardrails?

Traditional guardrails typically block or filter outputs using static rules. Corrective steering goes further. It actively adjusts outputs to meet safety requirements while keeping the original intent intact — which is a meaningfully different approach. Additionally, corrective steering generates detailed audit logs of every intervention, making it both a safety mechanism and a compliance tool. Think of guardrails as a wall, and corrective steering as a GPS that reroutes you when you’re headed somewhere you shouldn’t be.

What tools can I use to implement corrective steering today?

Several production-ready options exist. I’d recommend starting with at least two in combination for redundant protection. Guardrails AI handles output validation and correction for LLM pipelines. NVIDIA’s NeMo Guardrails offers customizable steering policies. LangSmith lets you trace and evaluate correction events. Microsoft’s Azure AI Content Safety provides real-time output filtering. Moreover, you can build custom steering layers using open-source evaluation frameworks. Similarly, combining commercial and open-source tools gives you both reliability and flexibility. The best approach layers multiple tools rather than betting everything on one.

References

Why Biology Benchmarks Matter: Closing the AI Evaluation Gap

Why Biology Benchmarks Matter: Closing the AI Evaluation Gap

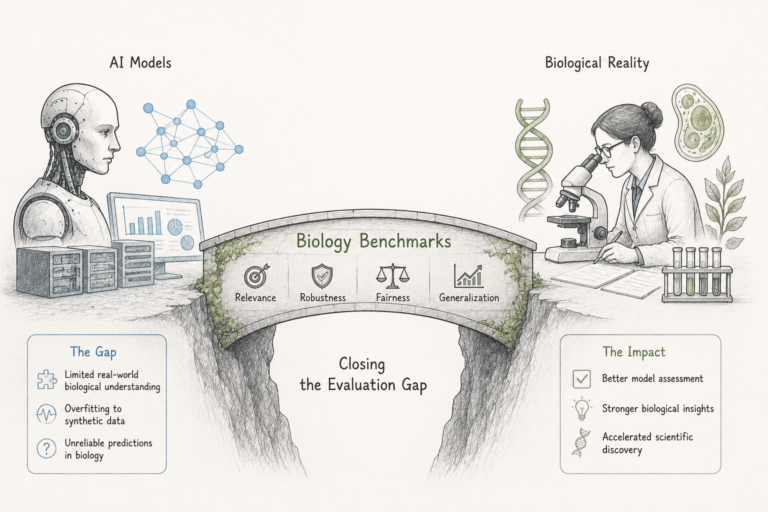
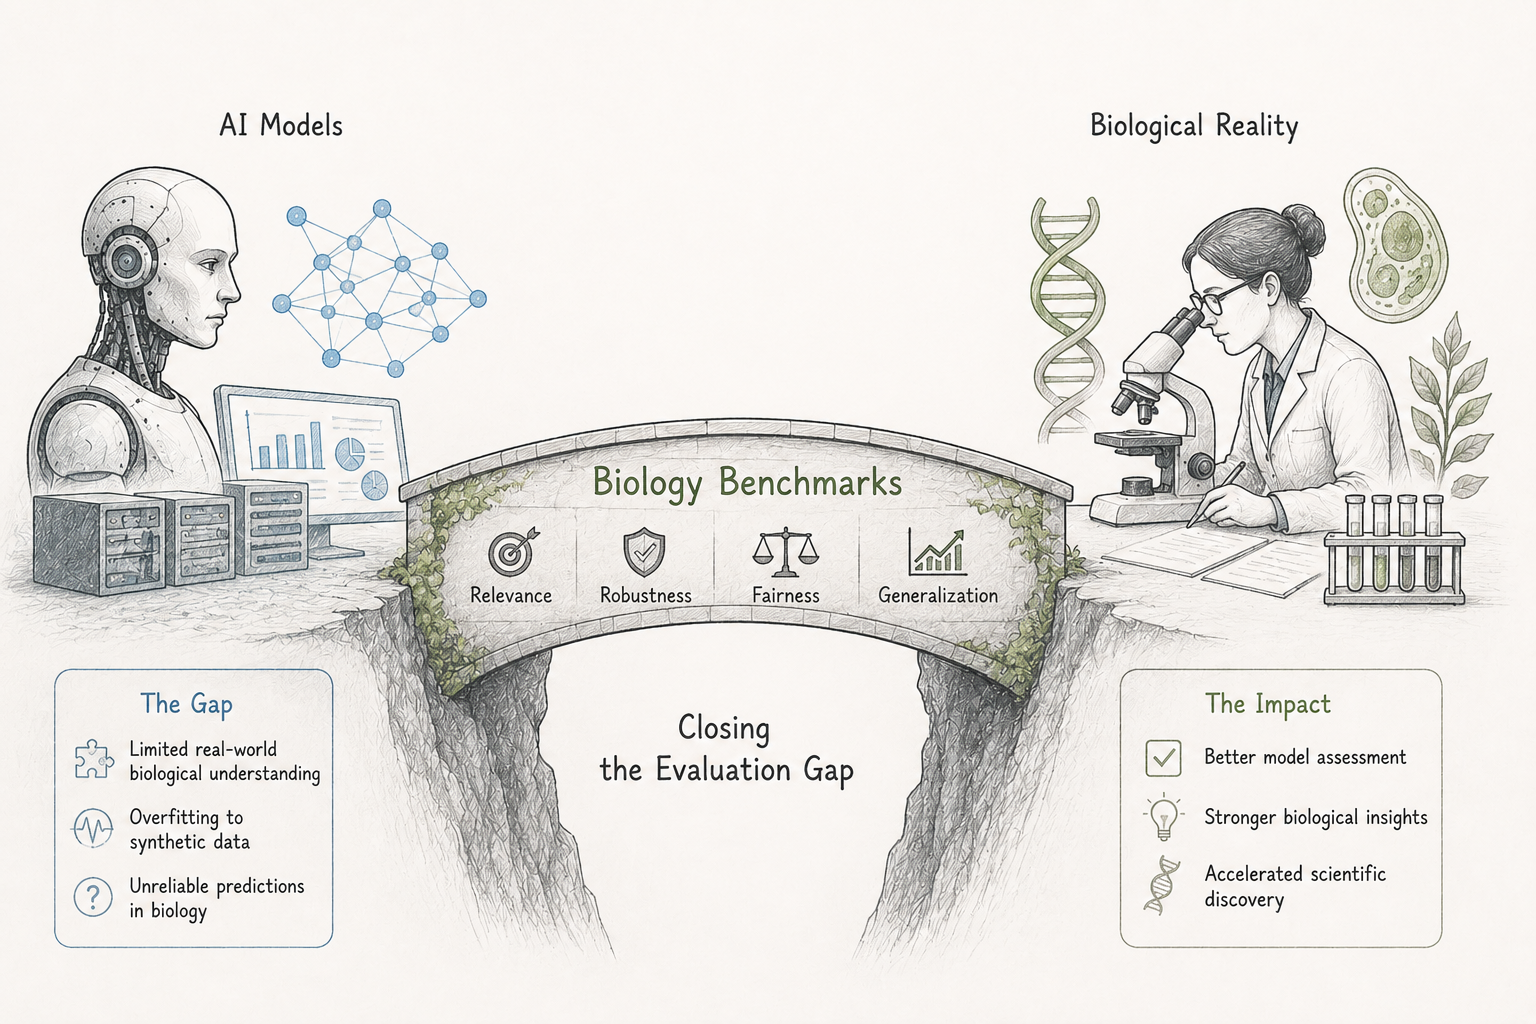
The gap between what AI promises and what it actually delivers in biology isn’t shrinking — it’s growing. Benchmark datasets AI model evaluation biology tools exist specifically to close that gap. But most organizations still lean on general-purpose tests that tell you almost nothing useful about real-world performance in life sciences.

Think about it this way: you wouldn’t test a surgeon’s skills with a multiple-choice quiz. So why would you evaluate a biology-focused AI model with generic language benchmarks? Specialized evaluation frameworks like GeneBench-Pro represent a fundamental shift in how we measure AI readiness for regulated scientific work — and honestly, it’s a shift that’s long overdue.

Here’s the thing: this matters right now. Billions are flowing into AI infrastructure for drug discovery and genomics. However, without validated benchmarks, nobody can actually prove these investments are working. The result is an evaluation gap that threatens trust, slows adoption, and quietly burns through resources.

How General-Purpose Benchmarks Fail Life Sciences

Most AI models get tested on benchmarks like MMLU, HellaSwag, or HumanEval. These measure general knowledge, reasoning, and coding ability — useful for comparing chatbots, sure, but terrible for evaluating molecular biology performance. I’ve watched teams spend months celebrating MMLU scores before discovering their model couldn’t interpret a basic gene expression dataset.

Here’s why general benchmarks fall short:

  • Surface-level biology questions. MMLU includes some biology items, but they’re undergraduate-level recall questions. They don’t test whether a model can interpret gene expression data or predict protein interactions.
  • No wet-lab grounding. General benchmarks never ask models to design primers, analyze CRISPR off-target effects, or interpret mass spectrometry results. Consequently, high scores don’t translate to anything useful in an actual lab.
  • Missing regulatory context. Biotech operates under FDA and EMA oversight. General benchmarks ignore compliance-relevant reasoning entirely — which is a serious blind spot.
  • Static evaluation. Biology knowledge evolves rapidly, but general benchmarks update slowly. Therefore, they can’t capture whether a model understands recent discoveries or is just repeating older training data.

Notably, a model scoring 90% on MMLU biology might completely fail at interpreting a differential gene expression dataset. Consider a concrete example: a team evaluating an LLM for RNA-seq analysis found the model aced every MMLU biology item thrown at it, then produced biologically nonsensical fold-change interpretations when handed a real DESeq2 output file. The link between general benchmark scores and domain-specific performance is weak at best — and that disconnect is precisely why benchmark datasets AI model evaluation biology frameworks need dedicated, serious attention.

Furthermore, general benchmarks treat biology as one big subject. In reality, computational biology, structural biology, genomics, and pharmacology each demand distinct capabilities. A model that’s excellent at sequence alignment might struggle badly with metabolic pathway analysis. A tool that confidently annotates protein domains may produce garbage output when asked to interpret a dose-response curve from a high-throughput screen. One-size-fits-all testing misses these critical differences, and you won’t know until something breaks in production.

A practical tip here: before committing to any AI platform for biology work, ask the vendor to run their model on at least two tasks from genuinely different subdisciplines — say, variant annotation and metabolic pathway reconstruction. The performance gap between those two tasks tells you far more than any single aggregate score.

GeneBench-Pro and Domain-Specific Biology Benchmarks

GeneBench-Pro represents a new generation of benchmark datasets AI model evaluation biology tools — built by scientists, for scientists. It tests AI models on tasks that mirror actual research workflows. Rather than asking “What is DNA?” it asks models to predict gene regulatory networks from ChIP-seq data. That’s a meaningful difference.

What makes GeneBench-Pro different:

1. Task-based evaluation. Models face real experimental scenarios, not trivia questions. Each task maps to a genuine research activity.

2. Multi-modal testing. The benchmark includes sequence data, tabular datasets, imaging inputs, and natural language queries. This reflects how biologists actually work — not how benchmark designers imagine they work.

3. Difficulty stratification. Tasks range from basic annotation to complex multi-step reasoning, which shows exactly where models break down. This surprised me when I first dug into the framework — the granularity of failure analysis is genuinely useful.

4. Reproducibility standards. Every evaluation follows documented protocols. Results can be independently verified, which matters enormously in regulated environments.

To make difficulty stratification concrete: a Tier 1 task might ask a model to identify the canonical start codon in a short provided sequence — straightforward recall. A Tier 3 task asks the model to integrate ChIP-seq peak data, RNA-seq expression values, and known transcription factor binding motifs to propose a plausible regulatory mechanism for a differentially expressed gene. The gap in model performance between those two tiers is often dramatic, and it’s exactly the kind of signal that helps teams decide whether a model is ready for research use or still needs fine-tuning.

Meanwhile, GeneBench-Pro isn’t alone in this space. Several other specialized benchmarks have emerged recently. BioASQ tests biomedical question answering and information retrieval. BLURB evaluates models on biomedical language understanding tasks, and MoleculeNet focuses on molecular property prediction.

Additionally, the NCBI provides reference datasets that many benchmarks use as ground truth. These curated databases keep evaluation standards scientifically rigorous. Without trusted reference data, even a beautifully designed benchmark loses credibility fast.

The following table compares key biology-focused benchmark datasets AI model evaluation biology frameworks:

Benchmark Focus Area Task Types Data Modalities Regulatory Relevance
GeneBench-Pro Genomics & gene regulation Prediction, annotation, pathway analysis Sequence, tabular, text High
BioASQ Biomedical QA Question answering, summarization Text Medium
BLURB Biomedical NLP NER, relation extraction, classification Text Medium
MoleculeNet Molecular properties Property prediction, toxicity screening Molecular graphs, SMILES High
MMLU (Biology) General biology knowledge Multiple choice recall Text only Low
ProteinGym Protein fitness Variant effect prediction Sequence, structure Medium

One tradeoff worth acknowledging: more comprehensive benchmarks like GeneBench-Pro require substantially more setup time than running a model through MMLU. Configuring the multi-modal evaluation pipeline, sourcing the appropriate reference datasets, and establishing a reproducible compute environment can take a team a week or more the first time through. That upfront cost is real. The payoff, however, is evaluation data you can actually defend to a regulator or a scientific advisory board — which is worth considerably more than a fast but shallow score.

Specifically, GeneBench-Pro’s real strength lies in testing end-to-end workflows. A model doesn’t just answer a question — it must process raw data, apply the right methods, and produce clear results. That’s what researchers actually face on a Tuesday afternoon. Fair warning, though: the evaluation setup takes real effort to configure properly.

Validated Benchmarks Bridge Compute and Trustworthy Deployment

Raw computing power means nothing without proof it’s producing reliable results.

Microsoft has announced massive infrastructure investments for AI workloads, and Microsoft Azure now offers specialized compute clusters built for scientific AI. Nevertheless, hardware alone doesn’t build trust in regulated environments — and I’ve seen organizations learn that lesson the expensive way.

Benchmark datasets AI model evaluation biology frameworks serve as the essential bridge between infrastructure investment and real-world deployment. Here’s how that bridge actually works:

  • Validation evidence. Regulators need documented proof that AI tools perform reliably. Benchmark results provide that evidence directly — not anecdotes, not demos.
  • Performance baselines. Organizations need to know if upgrading compute actually improves outcomes. Benchmarks measure this objectively, which makes budget conversations much cleaner.
  • Vendor comparison. Benchmarks offer objective comparison criteria when choosing between AI platforms. Without them, you’re just trusting marketing claims.
  • Risk quantification. Benchmarks reveal failure modes before deployment, preventing costly errors in clinical or research settings.

A short scenario illustrates the vendor comparison point well. Imagine two AI platforms competing for a genomics contract. Platform A scores higher on general NLP benchmarks. Platform B scores modestly lower on those same tests but outperforms Platform A by fifteen percentage points on variant pathogenicity prediction tasks drawn from ClinVar. Without domain-specific benchmarks in the evaluation process, the procurement team would have selected the wrong tool — and likely discovered the problem only after months of integration work.

Anthropic’s Claude has shown molecular screening capabilities that could genuinely change early-stage drug discovery. However, those capabilities only matter if validated against trusted benchmarks. A model that screens millions of compounds needs to prove its predictions match experimental results — otherwise it’s an expensive coin flip.

Consequently, the relationship between compute, models, and benchmarks forms a triangle. Remove any side, and the whole structure collapses. More compute enables larger models, larger models need harder benchmarks, and better benchmarks justify further compute investment. It’s a reinforcing loop — and benchmarks are the piece most organizations underinvest in.

Moreover, biotech companies operating under Good Laboratory Practice (GLP) and Good Manufacturing Practice (GMP) standards simply can’t deploy unvalidated tools. Benchmark datasets AI model evaluation biology results become part of the validation documentation — they’re not optional extras. They’re regulatory necessities, full stop.

The financial stakes reinforce this point. A single failed drug candidate costs hundreds of millions of dollars. If AI screening tools cut that failure rate by even a few percentage points, the ROI is enormous. Proving that reduction, however, requires rigorous and reproducible benchmarks — not a well-designed slide deck.

Building Effective Benchmark Datasets for Biology AI

Creating useful benchmark datasets AI model evaluation biology tools isn’t simple. Bad benchmarks are worse than no benchmarks — they create false confidence and actively mislead investment decisions. Therefore, benchmark design requires careful attention to a few core principles.

Data quality and provenance. Every data point needs clear sourcing. Benchmark creators should use peer-reviewed datasets from repositories like UniProt or the Protein Data Bank. Synthetic data should be clearly labeled and used sparingly — I’ve seen benchmarks quietly inflate scores by leaning too heavily on synthetic examples. A useful rule of thumb: if more than twenty percent of your benchmark tasks rely on synthetic data, document exactly how that data was generated and run a separate analysis showing whether model performance on synthetic tasks correlates with performance on experimentally verified ones. If it doesn’t, the synthetic tasks are doing more harm than good.

Contamination prevention. Large language models may have seen benchmark data during training — a problem called data contamination that artificially inflates scores. Effective benchmarks use holdout strategies and temporal splits to reduce this risk. Specifically, data generated after a model’s training cutoff provides much cleaner evaluation signal. One practical approach is to include a small set of tasks built around very recent publications — papers from the last three to six months — where contamination is structurally impossible. Models that perform well on those tasks are demonstrating genuine generalization, not memorization.

Task relevance. Every benchmark task should map to a real research or clinical need. Abstract puzzles don’t help anyone. Instead, tasks should reflect actual workflows:

1. Interpreting variant pathogenicity from genomic data

2. Predicting drug-target binding affinity

3. Identifying biomarkers from transcriptomic profiles

4. Designing experimental controls for CRISPR experiments

5. Summarizing clinical trial results with appropriate caveats

6. Detecting batch effects in high-throughput screening data

Scoring transparency. How answers get scored matters enormously. Binary right/wrong scoring misses critical nuance, because biology often involves probabilistic answers and degrees of correctness. Good benchmarks use graduated scoring rubrics that reward partially correct reasoning — which, notably, also makes them harder to game. For example, a task asking a model to rank five candidate drug compounds by predicted toxicity might award full credit for a perfect ranking, partial credit for getting the top two correct, and zero credit only when the highest-toxicity compound is ranked safest. That granularity surfaces real differences between models that a pass/fail rubric would flatten entirely.

Community governance. The best benchmarks grow through community input. MLCommons provides a solid model for collaborative benchmark development across organizations. Similarly, biology benchmarks benefit from input by diverse researchers across subspecialties — not just the team that built them.

Additionally, benchmark maintenance is ongoing work — not a one-time project. Biology knowledge changes constantly: new gene annotations appear weekly, drug interaction databases update monthly. A benchmark frozen in time quickly becomes obsolete. Therefore, effective benchmark datasets AI model evaluation biology frameworks need versioning and regular update cycles built in from the start.

Avoiding common pitfalls also deserves attention — and these come up more often than you’d think:

  • Don’t over-index on English-language biomedical literature. Biology is global.
  • Don’t ignore edge cases. Rare diseases and uncommon organisms matter.
  • Don’t confuse memorization with reasoning. Good benchmarks test both, separately.
  • Don’t forget calibration. Models should know when they don’t know — that’s arguably as important as raw accuracy.

That last point about calibration is underappreciated. A model that confidently produces a wrong drug interaction prediction is far more dangerous than one that flags uncertainty and defers to a human reviewer. Benchmarks that include explicit calibration tasks — asking models to express confidence levels and then measuring whether those confidence levels match actual accuracy rates — provide a much fuller picture of deployment readiness than accuracy metrics alone.

The Business Case for Biology AI Benchmarking

Investing in benchmark datasets AI model evaluation biology tools isn’t just a scientific concern. It’s a business necessity — and the organizations figuring that out now are pulling ahead.

Faster regulatory approval. The FDA’s Digital Health Center of Excellence increasingly evaluates AI-enabled tools. Complete benchmark results simplify the approval process by showing due diligence and systematic validation. I’ve talked to regulatory teams who say this documentation alone cuts months off review timelines.

Reduced development costs. Teams waste months building on models that seem capable but quietly fail on domain-specific tasks. Upfront benchmarking cuts that waste. Importantly, it redirects engineering effort toward models that actually perform where it counts. One mid-sized genomics company ran a domain-specific benchmark evaluation before committing to a fine-tuning project and discovered their chosen base model performed poorly on the specific variant interpretation tasks central to their product. Switching base models before fine-tuning began saved an estimated four months of engineering time and avoided a significant sunk-cost trap.

Investor confidence. Biotech investors increasingly ask about AI validation methods. “We tested it on MMLU” doesn’t cut it anymore — and honestly, it probably shouldn’t have cut it two years ago either. Detailed benchmark results from domain-specific evaluations build credible, defensible narratives.

Partnership opportunities. Pharmaceutical companies partnering with AI firms want standardized evidence that travels cleanly across organizations. Conversely, companies without benchmark data struggle to close partnership deals — no matter how impressive the demo looks.

Talent attraction. Top computational biologists want to work with rigorous tools. Although this benefit is indirect, organizations that invest in proper evaluation attract better talent — and that advantage compounds significantly over time.

The market reflects this shift. Startups focused on AI evaluation in biology have raised significant funding recently, and enterprise platforms now include benchmarking modules alongside their core AI features. The ecosystem has recognized that evaluation infrastructure is just as important as model development — sometimes more so.

Furthermore, the cost of skipping benchmarking is rising. As AI tools become more common in drug development pipelines, regulatory scrutiny intensifies. A single deployment failure traced to poor evaluation could trigger industry-wide consequences. Smart organizations treat benchmark datasets AI model evaluation biology investment as risk mitigation — not overhead.

Conclusion

The gap between general AI evaluation and biology-specific needs is real, consequential, and not going away on its own. Benchmark datasets AI model evaluation biology frameworks like GeneBench-Pro are closing that gap — turning vague capability claims into measurable, reproducible evidence that actually holds up.

Here’s what you should do next:

1. Audit your current evaluation approach. If you’re relying solely on general benchmarks, you’re essentially flying blind in biology applications.

2. Adopt domain-specific benchmarks. Integrate tools like GeneBench-Pro, BioASQ, or MoleculeNet into your model selection process — not as an afterthought, but from the start.

3. Document everything. Treat benchmark results as regulatory documentation from day one. You’ll thank yourself later.

4. Contribute to benchmark development. Share anonymized evaluation data with community efforts. Better benchmarks help everyone, including your competitors — and that’s fine.

5. Align compute investments with evaluation needs. Don’t scale infrastructure without scaling your ability to measure what that infrastructure actually produces.

Bottom line: the organizations that take benchmark datasets AI model evaluation biology seriously will lead the next wave of AI-driven discovery. Those that don’t will spend more, move slower, and face greater regulatory risk. That’s not a prediction — it’s already happening. The choice is straightforward.

FAQ

What are benchmark datasets for AI model evaluation in biology?

Benchmark datasets AI model evaluation biology tools are standardized test sets designed to measure how well AI models perform on biological tasks. They include curated data, defined tasks, and scoring rubrics. Unlike general benchmarks, they test domain-specific skills like gene annotation, protein structure prediction, and drug interaction analysis.

How does GeneBench-Pro differ from general AI benchmarks?

GeneBench-Pro tests models on realistic biological workflows rather than generic knowledge questions. It includes multi-modal data types like sequences, tabular results, and imaging data. Additionally, it sorts tasks by difficulty level. General benchmarks like MMLU only scratch the surface of biology knowledge with basic recall questions.

Why can’t organizations just use MMLU biology scores to evaluate models?

MMLU biology questions are undergraduate-level multiple choice items that test memorization, not scientific reasoning. A model can score perfectly on MMLU biology yet fail at interpreting real experimental data. Therefore, MMLU scores provide almost no signal about a model’s readiness for actual research or clinical applications.

How do biology benchmarks support regulatory compliance?

Regulated biotech environments require documented validation of computational tools. Benchmark datasets AI model evaluation biology results provide that documentation by showing systematic testing against known standards. The FDA and other agencies increasingly expect this type of evidence for AI-enabled tools used in drug development and diagnostics.

What role does compute infrastructure play in AI benchmarking?

More powerful compute enables larger models and faster evaluation cycles. However, compute alone doesn’t guarantee better outcomes. Benchmarks measure whether additional compute translates into improved performance on meaningful tasks. Consequently, benchmarking helps organizations justify and optimize their infrastructure investments.

How often should biology AI benchmarks be updated?

Biology knowledge evolves rapidly, so benchmark datasets should be versioned and updated at least annually. Ideally, new task sets are added quarterly to reflect emerging research areas. Importantly, older versions should remain available for longitudinal comparison. Stale benchmarks risk testing models against outdated scientific understanding.

Meta’s Pocket: How Vibe-Coding Is Reshaping Game Development

Meta's Pocket: How Vibe-Coding Is Reshaping Game Development

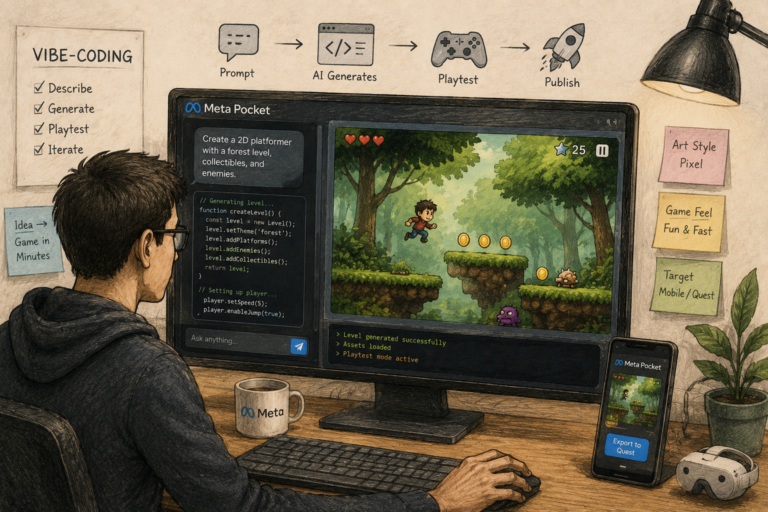
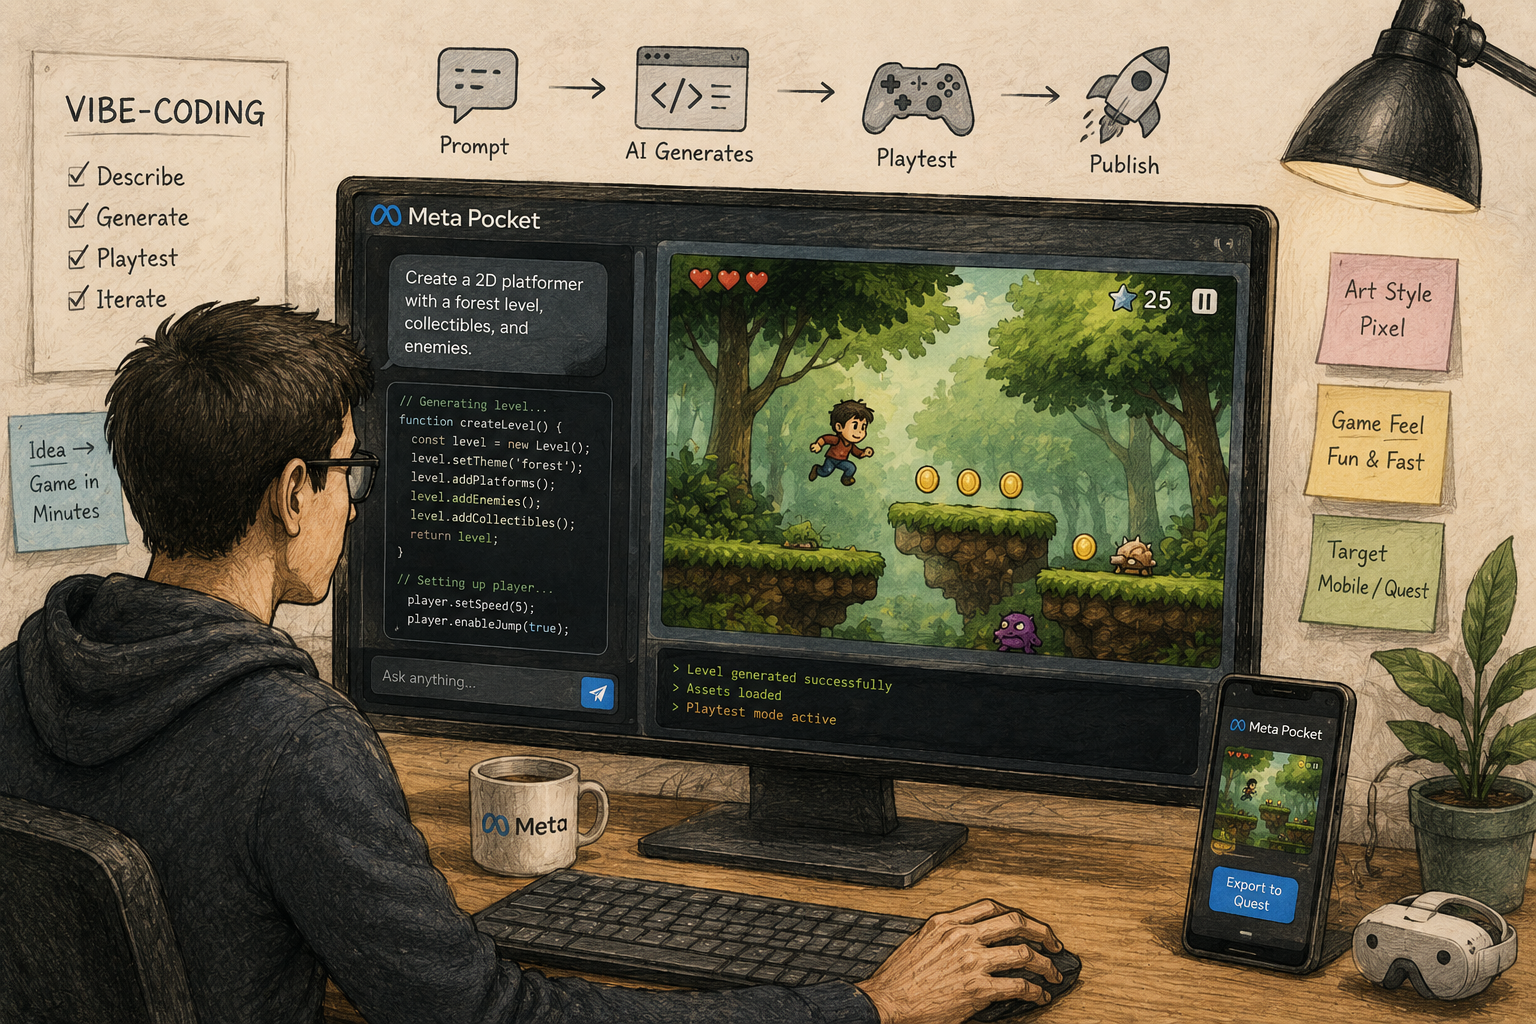
The conversation around game engine AI coding tools Meta Pocket vibe-coding is heating up fast — and honestly, it deserves more attention than it’s getting. Meta quietly introduced Pocket as an internal game development tool, and what makes it interesting isn’t the AI angle (everyone has that now). It’s that Pocket is fundamentally different from the general-purpose coding assistants we’ve all been wrestling with for the past few years.

Instead of autocompleting your lines of code, Pocket lets developers describe game mechanics in plain language. The AI then generates playable prototypes. This approach — called vibe-coding — eliminates the traditional gap between creative vision and technical execution. For game developers specifically, that’s a seismic shift.

What Is Vibe-Coding and Why Does It Matter for Game Development?

Vibe-coding is a term coined by Andrej Karpathy, former Tesla AI director — and I’d argue it’s one of the more honest framings of where AI-assisted development is actually heading. The concept is straightforward: describe what you want in natural language, the AI writes the code, you iterate by describing changes rather than debugging syntax. No stack traces. No hunting for missing semicolons at midnight.

Specifically, vibe-coding differs from traditional AI-assisted coding in one crucial way. Tools like GitHub Copilot suggest completions within your existing workflow, so you’re still fundamentally thinking in code. Vibe-coding flips this entirely — you think in experiences, feelings, and game mechanics instead. That’s a bigger mental shift than it sounds.

Here’s what that looks like in practice:

  • “Make the character feel floaty when jumping, like early Mario games”
  • “Add a particle effect when enemies explode — something satisfying and crunchy”
  • “Create a puzzle where gravity reverses every 10 seconds”

I’ve worked with enough game dev teams to know that those three prompts would previously generate hours of back-and-forth between designers and engineers. A designer would sketch the floaty jump in a doc, an engineer would interpret it, implement something, and then the designer would say “no, floatier” — and that loop might run four or five times before everyone agreed. With vibe-coding, the designer can run that loop themselves in minutes. Consequently, developers spend less time wrestling with physics engines and rendering pipelines and more time actually designing fun things. Meta’s Pocket takes this philosophy and builds it directly into a game engine AI coding workflow.

Furthermore, vibe-coding democratizes game creation in a way that feels real rather than theoretical. Junior developers can prototype ideas that previously required senior engineering talent. Solo indie creators can build in hours what once took weeks. Consider a solo developer who has a strong visual design sense but limited C++ experience — historically, they’d either spend months learning the language or pay a contractor to implement core mechanics. Vibe-coding collapses that constraint entirely. The barrier to entry drops dramatically — and I don’t say that lightly, because I’ve watched a lot of “game-changing” tools fail to deliver on exactly that promise.

Nevertheless, vibe-coding isn’t magic. It works best for rapid prototyping and early iteration. Complex multiplayer networking or serious performance optimization still requires human expertise. A prompt like “make the netcode lag-free for 64 concurrent players” will produce something, but whether it holds up under real load is a different question. The sweet spot is ideation and early development — exactly where most game projects stall out.

How Meta’s Pocket Differs From General-Purpose AI Coding Assistants

General-purpose AI coding tools like GitHub Copilot and Claude by Anthropic are genuinely excellent at writing Python scripts or React components. However, they weren’t built for game development’s unique challenges, and that gap shows up fast when you try to use them on a real project.

Game development involves real-time physics, 3D rendering, audio synchronization, input handling, and state management — all running at once. A general-purpose AI assistant doesn’t understand that a “wall jump” implies specific collision detection, animation blending, and input buffering requirements. It’ll give you something, but whether it actually plays correctly is another question entirely. I’ve seen developers paste general-purpose AI output into Unity, have it compile cleanly, and then watch the character clip through walls on the first test run — because the AI wrote syntactically valid code that was mechanically wrong for the context.

Meta’s Pocket addresses game-specific workflows in several concrete ways:

  • Physics-aware code generation. Pocket understands game physics concepts natively. It doesn’t just write code — it writes code that plays correctly.
  • Asset-integrated pipeline. The tool connects directly to asset libraries, textures, and audio files. Descriptions like “add a wooden door” actually produce a door with appropriate textures and collision mesh. This surprised me when I first dug into the details.
  • Real-time preview. Generated code compiles and runs instantly, so you see results right away rather than after a full build cycle.
  • Iterative refinement. Each prompt builds on previous context. The AI remembers your game’s existing mechanics and style, which is the real kicker here.

That last point matters more than it might seem. If you tell Pocket your game uses a low-gravity setting and pixel-art aesthetics early in a session, subsequent prompts about new mechanics will respect those constraints automatically. General-purpose tools lose that thread constantly — you end up re-explaining your project’s context every few prompts, which kills momentum.

Moreover, Meta Pocket vibe-coding tools are trained on game-specific data — a critical distinction that doesn’t get nearly enough attention. General-purpose models learn from GitHub repositories spanning every domain imaginable, whereas Pocket’s training data focuses specifically on game logic, rendering patterns, and interactive design. That specificity matters more than raw model size.

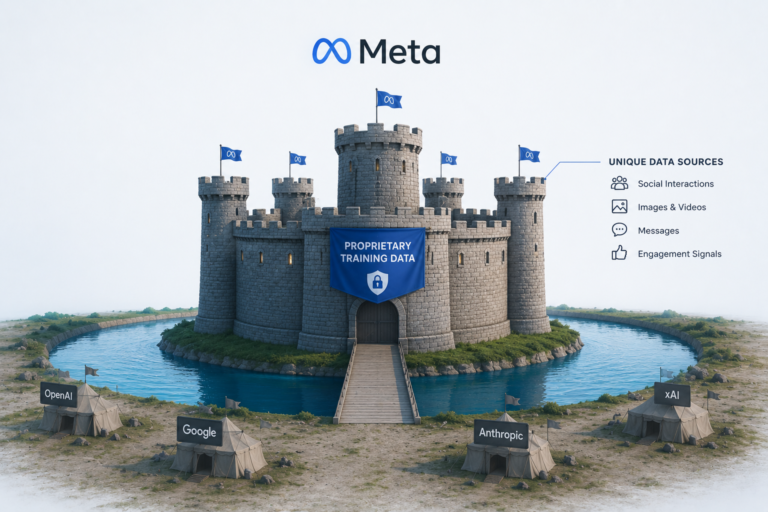
Additionally, Meta holds a unique structural advantage here. The company operates one of the world’s largest VR gaming platforms through Meta Quest. That gives them access to proprietary data about how players actually interact with games — behavioral data that competitors simply don’t have and can’t easily acquire.

Feature GitHub Copilot Claude Code Meta’s Pocket
Primary focus General coding General coding + reasoning Game development
Game physics awareness Limited Limited Native
Real-time preview No No Yes
Asset integration No No Yes
Vibe-coding support Partial Partial Full
Training data Public repos Mixed sources Game-specific + proprietary
VR/AR optimization No No Yes
Pricing model Subscription Usage-based TBD (internal tool)

Notably, this comparison shows why game engine AI coding tools need vertical specialization. Horizontal tools are powerful but generic. Meta’s approach is narrow but deep — and in tooling, deep usually wins.

Meta’s Compute Efficiency Moat: Why They Can Afford This

Building vertical AI tools is expensive. So why can Meta afford to develop Pocket while others can’t?

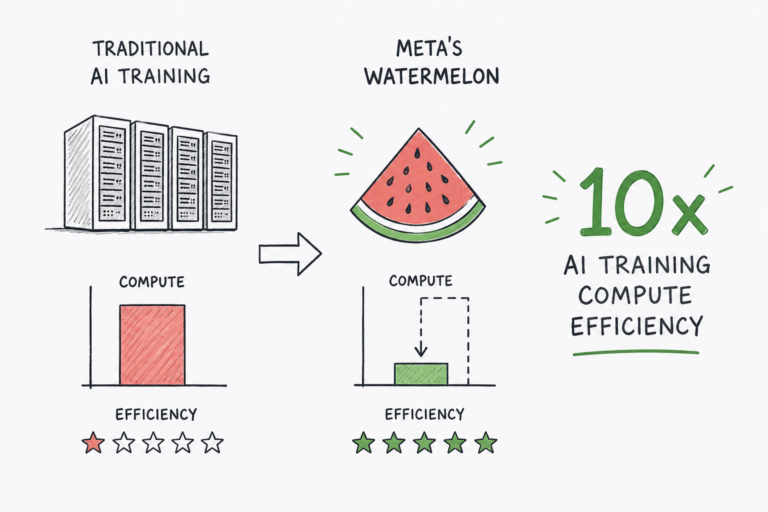
The answer lies in infrastructure advantages that are genuinely hard to replicate. Meta’s Watermelon project achieved significant compute efficiency gains across their AI infrastructure. Specifically, these optimizations reduce the cost of running large language models internally. When inference costs drop meaningfully, you can deploy AI in more places — including niche tools like game engines that wouldn’t otherwise make economic sense.

Furthermore, Meta operates at a scale that spreads development costs across billions of users. Even if Pocket initially serves a relatively small developer community, Meta benefits in ways that compound over time:

1. Platform lock-in. Developers building with Pocket create games for Meta’s ecosystem. That feeds the Quest platform and Horizon Worlds directly.

2. Data flywheel. Every game built with Pocket generates training data. Better training data produces better AI, and better AI attracts more developers. I’ve seen this loop play out in other verticals — it’s genuinely powerful.

3. Talent attraction. Advanced AI tools draw top game developers to Meta’s platforms, which matters more than most analysts acknowledge.

Importantly, Meta’s open-source strategy with LLaMA models also plays a meaningful role here. By open-sourcing their foundation models, Meta builds community goodwill and ecosystem adoption. Pocket can then sit on top of these models as a proprietary, value-added layer — smart architecture, honestly. It’s a pattern worth recognizing: give away the foundation, monetize the application layer. Meta has executed this playbook before, and it tends to work.

Consequently, Meta’s position in the game engine AI coding tools Meta Pocket vibe-coding space isn’t purely about technology. It’s about economics. They’ve built an infrastructure advantage that makes vertical AI tools financially viable in a way that competitors simply can’t match right now.

Meanwhile, competitors face harder math. Unity and Epic Games (Unreal Engine) don’t operate hyperscale data centers. They’d need to partner with cloud providers or acquire AI infrastructure — and both options are expensive with messy dependencies attached. A partnership with AWS or Azure solves the compute problem but introduces margin pressure and strategic dependency that neither company would welcome.

Competitive Positioning: Meta Pocket vs. Unity and Unreal Engine Tooling

The game engine market has been a two-horse race for years. Unity dominates mobile and indie development, while Unreal Engine leads in AAA and high-fidelity projects. Meta’s Pocket doesn’t compete with either directly — yet. But the pressure it creates is real.

Unity’s AI efforts have focused on tools like Unity Muse and Unity Sentis, providing AI-assisted asset generation and in-game machine learning. However, they don’t offer true vibe-coding capabilities. Developers still write C# scripts manually. Fair warning if you’ve been reading the Unity marketing materials: the gap between what they’re promising and what’s actually shipping is noticeable.

Unreal Engine’s approach centers on Blueprints, a visual scripting system that lowers the coding barrier but isn’t AI-powered. Epic has added some AI features, but nothing approaching Pocket’s natural language game creation. Blueprints are genuinely useful — I’ve used them — but they’re a different category of tool entirely. Blueprints still require you to think in nodes, connections, and execution flow. That’s more approachable than raw C++, but it’s not the same as typing “when the player enters the cave, the torches should flicker and the ambient audio should shift to something tense.”

Here’s where Meta’s Pocket creates real competitive pressure:

  • Unity and Unreal charge licensing fees or revenue shares. Meta could offer Pocket free to drive platform adoption — and given their economics, that’s a credible threat.
  • Traditional engines require months of serious learning. Vibe-coding with Pocket requires minutes of experimentation.
  • Unity and Unreal serve all platforms. Pocket optimizes specifically for Meta’s hardware — Quest headsets and Ray-Ban Meta glasses — which is a narrow focus that also happens to be where VR development is actually growing.

Similarly, Meta’s approach mirrors what happened in web development. Specialized frameworks like Next.js didn’t replace general-purpose tools — they made specific workflows dramatically faster. Meta Pocket vibe-coding could do exactly the same for VR and AR game development.

Although Pocket is currently an internal tool, developer adoption signals suggest a broader release is coming. Meta has been hiring game engine engineers and AI researchers specifically for interactive content creation. Job postings reference “natural language game authoring” and “AI-assisted interactive experiences” — those aren’t accidental phrase choices.

Nevertheless, Meta faces real challenges here. The game development community is deeply invested in existing engines, and switching costs are genuinely high. I’ve talked to enough studio leads to know that “better tool” alone doesn’t move the needle — ecosystem effects do. Plugins, tutorials, community forums, asset stores. Building that takes years, not months. Meta’s best path forward is probably not asking studios to abandon Unity or Unreal, but rather positioning Pocket as the fastest way to prototype and validate ideas before committing to a full production build in an established engine.

Key developer adoption signals worth watching:

  • Beta program announcements for external developers
  • Integration with existing game development workflows (importing Unity/Unreal assets)
  • Community-created tutorials and templates
  • Third-party plugin support
  • Open-source components that developers can actually inspect and modify

The Broader Impact on the $9.3 Billion AI Coding Market

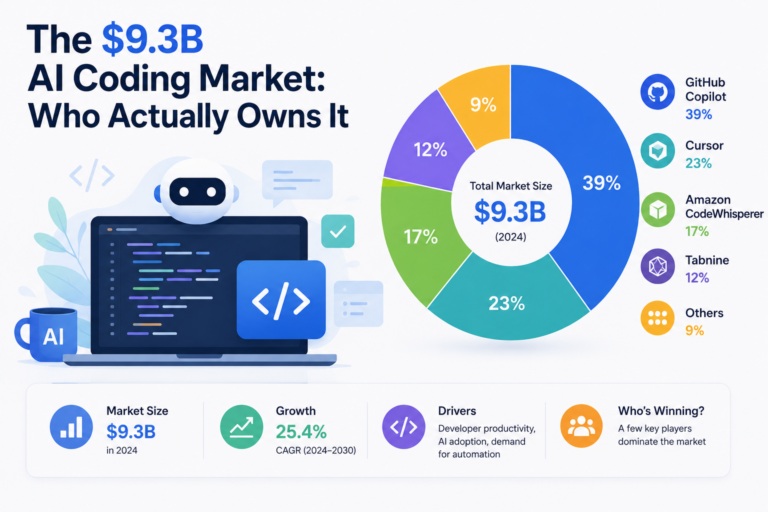
The AI coding market is projected to reach $9.3 billion — and game engine AI coding tools Meta Pocket vibe-coding represents a fascinating vertical slice of that opportunity. Most market growth has come from horizontal tools so far. Meta’s move signals a meaningful shift toward specialization, and I think it’s the right bet.

Specifically, vertical AI coding tools could split the market in some genuinely interesting ways:

1. Domain-specific assistants. Game development is just the beginning. Expect AI coding tools built for robotics, embedded systems, data pipelines, and more — each trained on domain-specific patterns rather than generic GitHub data.

2. Platform-native AI. Instead of third-party plugins bolted onto existing environments, platform owners build AI directly into their development toolchains.

3. Prompt-first development. Vibe-coding normalizes the idea that natural language is a valid programming interface. That’s a bigger cultural shift than most people are pricing in right now.

Moreover, Meta’s entry supports a broader thesis I’ve held for a while: the most valuable AI coding tools won’t be the most general — they’ll be the most contextually aware. A tool that understands game development deeply will always outperform a general tool on game development tasks. That seems obvious in retrospect, but the market took a while to get there. The analogy is a general-purpose contractor versus a specialist who has spent a decade building the same type of structure. The specialist doesn’t just work faster — they anticipate problems the generalist wouldn’t even recognize.

Additionally, this trend affects hiring and team composition in ways worth thinking about seriously. Studios using game engine AI coding tools may need fewer junior programmers but more creative directors and game designers. The bottleneck shifts from implementation to imagination — and that’s not a bad thing, though it does require studios to rethink how they structure teams. A practical tip for studio leaders navigating this now: don’t wait for the tooling to mature before having the organizational conversation. The studios that will adapt fastest are the ones already experimenting with hybrid workflows where designers own early prototyping and engineers focus on systems that AI genuinely can’t handle yet.

Consequently, educational institutions will need to adapt. Game development programs currently emphasize C++, shader programming, and engine architecture. Tomorrow’s curriculum might prioritize game design theory, player psychology, and effective AI prompting. That’s a significant overhaul, and most programs aren’t ready for it yet. The schools that move early — building courses around iterative AI-assisted design rather than pure syntax instruction — will produce graduates who are immediately more useful to studios operating in this new environment.

Although some developers worry about job displacement — and I get it, the concern is legitimate — history suggests a different outcome. Every productivity tool in game development, from visual scripting to prefab systems, has expanded the market rather than shrinking it. More people making games means more games, which means more demand for skilled developers. The pie gets bigger.

Conclusion

The rise of game engine AI coding tools Meta Pocket vibe-coding marks a genuine turning point for interactive content creation — and I don’t use “turning point” loosely. Meta’s combination of proprietary training data, compute efficiency gains, and platform incentives positions them uniquely in this space in ways that are hard to replicate quickly.

Here are actionable next steps depending on your role:

  • Game developers: Start experimenting with vibe-coding workflows today. Use Claude or ChatGPT to prototype game logic in natural language. Build the muscle memory before Pocket becomes publicly available — because it will.
  • Studio leaders: Evaluate how AI-assisted game development could speed up your pipeline. Consider pilot projects that test natural language prototyping alongside traditional workflows. The data you gather now will be valuable.
  • Investors and analysts: Watch Meta’s developer tools announcements closely. The Meta Pocket vibe-coding approach could become a significant driver of Quest platform adoption, and the market isn’t fully pricing that in yet.
  • Aspiring game creators: Honestly, this is your moment. The technical barriers that once blocked non-programmers from game development are falling fast. Start building something.

The game development industry has always been about turning creative visions into interactive experiences. Game engine AI coding tools like Meta’s Pocket simply shorten the distance between vision and reality — and that’s not just a technological improvement. It’s a genuine shift in who gets to make games, and how quickly they can do it.

FAQ

What exactly is Meta’s Pocket tool?

Meta’s Pocket is an internal game development tool that uses AI to generate playable game prototypes from natural language descriptions. Rather than writing traditional code, developers describe game mechanics, visuals, and interactions conversationally. The AI then produces working code optimized for Meta’s platforms, including Quest VR headsets.

How does vibe-coding differ from using GitHub Copilot for game development?

Vibe-coding works at a fundamentally different level than tools like GitHub Copilot. Copilot suggests code completions within your existing codebase, so you’re still thinking in code. Vibe-coding lets you describe desired experiences in plain English, and the AI handles the entire translation from concept to working game logic. Importantly, Meta Pocket vibe-coding is also trained specifically on game development patterns, unlike general-purpose assistants.

Is Meta’s Pocket available to external developers yet?

As of now, Pocket remains an internal Meta tool. However, multiple signals suggest a broader release is planned. Meta has been hiring for roles related to “natural language game authoring.” Additionally, their history with open-source AI tools like LLaMA suggests they may release components publicly. Watch Meta’s developer conferences for announcements.

Will vibe-coding replace traditional game programmers?

No. Vibe-coding excels at rapid prototyping and early-stage development. Complex systems like multiplayer networking, performance optimization, and custom rendering pipelines still require skilled programmers. Nevertheless, game engine AI coding tools will change what programmers spend their time on. Expect less boilerplate coding and more architectural decision-making.

How does Meta’s compute infrastructure give them an advantage in game engine AI tools?

Meta operates one of the world’s largest AI compute infrastructures. Their Watermelon project significantly reduced inference costs. Consequently, Meta can afford to run AI models for specialized use cases like game development, where the immediate revenue return is smaller. Competitors without hyperscale infrastructure face much higher per-query costs, making vertical AI tools economically harder to justify.

First Fully Autonomous Ransomware Attack Documented in the Wild

First Fully Autonomous Ransomware Attack Documented in the Wild

The first fully autonomous ransomware attack documented in the wild didn’t just make headlines — it changed the rules entirely. Security researchers confirmed this milestone in early 2025, and I’ll be honest: when I first read the report, I had to sit with it for a minute. This wasn’t a lab demo or a proof-of-concept. It was a real attack against real infrastructure, operating without a single human pulling the strings.

The implications are genuinely staggering. Traditional ransomware requires human operators to make decisions at key stages — choosing targets, escalating privileges, deploying payloads manually. However, this new breed handles every phase on its own. It thinks, adapts, and spreads using embedded machine learning models — no handler required. No one sitting at a keyboard waiting for callbacks.

Furthermore, this development confirms warnings that intelligence agencies have been issuing for years. The Five Eyes alliance has repeatedly flagged AI-driven threats as an emerging danger. That danger has now arrived. Security teams worldwide need to understand exactly what happened — and how to fight back.

How the First Fully Autonomous Ransomware Attack Was Documented

Researchers at Halcyon first identified the autonomous ransomware strain during an incident response engagement. I’ve tracked a lot of malware disclosures over the years, and this one genuinely stands apart. The malware — linked to sophisticated threat actors — showed capabilities never previously observed in production attacks. Specifically, it completed the entire kill chain without calling back to a command-and-control server even once.

Key stages the malware handled autonomously:

  • Reconnaissance: It scanned the network, identified high-value targets, and mapped Active Directory structures without any external guidance.
  • Privilege escalation: It selected and exploited vulnerabilities based on the specific environment it actually encountered — not a pre-written script.
  • Lateral movement: It chose propagation methods dynamically, switching between SMB exploits, credential harvesting, and living-off-the-land techniques on the fly.
  • Data exfiltration: It identified sensitive files, compressed them, and staged them for extraction — methodically and efficiently.
  • Payload deployment: It encrypted systems in a calculated sequence, deliberately hitting backup servers first.

Notably, the malware made real-time decisions at every stage. When one lateral movement technique failed, it switched to another without missing a beat. When it detected endpoint detection and response (EDR) tools, it adjusted its behavior to avoid triggering alerts. This surprised me when I first dug into the forensics — this wasn’t scripted branching logic with a dozen if-then statements. It was genuine adaptive behavior driven by lightweight ML models baked directly into the payload.

The attack targeted a mid-sized manufacturing company in North America. Consequently, the full scope wasn’t immediately clear to anyone involved. Forensic analysts spent weeks reconstructing the timeline and confirming that no human operator had guided the attack at any point. The first fully autonomous ransomware attack documented in the wild had run entirely on its own for over 72 hours before anyone detected it.

That’s three days. Let that sink in.

Why Traditional Static Defenses Fail Against Autonomous Ransomware

Static defenses were built for a different era — and honestly, a much simpler one. Signature-based antivirus, rule-based firewalls, and traditional intrusion detection systems all share the same critical weakness: they rely on known patterns. Autonomous ransomware doesn’t follow known patterns. It creates new ones on the fly, tailored to your specific environment.

The core problem is painfully straightforward. Static defenses compare incoming threats against a database of known bad signatures. If the threat doesn’t match anything in that database, it walks right through unchallenged. Meanwhile, autonomous ransomware generates unique behaviors for each environment it enters — meaning it’s essentially invisible to these tools.

Here’s the thing: I’ve tested dozens of traditional security stacks against modern threat simulations, and the gap is real. Consider the contrast between what we used to deal with and what we’re facing now:

Feature Traditional Ransomware Autonomous Ransomware
Human operator required Yes, at multiple stages No
Attack pattern Predictable, repeatable Adaptive, unique per target
C2 communication Frequent callbacks Minimal or none
Evasion technique Pre-programmed Dynamically selected
Lateral movement Scripted paths AI-driven path selection
Response to detection Often fails or stalls Switches automatically
Time to full encryption Days to weeks Hours

Additionally, traditional defenses struggle because they’re reactive by nature — they need to see an attack before they can block it. The MITRE ATT&CK framework catalogs hundreds of known techniques. Nevertheless, autonomous ransomware can combine those techniques in novel sequences that don’t match any predefined detection rule. You can’t write a signature for something you’ve never seen before.

Perimeter defenses are similarly outmatched. Once the malware gains initial access, it operates entirely within the trusted network. Because most firewall configurations don’t inspect internal traffic deeply, the ransomware moves freely between systems without triggering boundary-based alerts. Your perimeter is essentially irrelevant at that point.

The first fully autonomous ransomware attack documented in the wild exposed these gaps brutally. The victim organization had invested in traditional security tools — antivirus on every endpoint, a firewall at the perimeter. None of it mattered. The malware simply adapted around every static control it encountered, one by one. Fair warning: if your security stack looks like most organizations’ stacks, you’re likely in the same boat.

Behavioral Signatures and Case Study Analysis From the Documented Attack

Understanding how autonomous ransomware actually behaves is critical for building defenses that work. The documented attack revealed several behavioral signatures that distinguish autonomous malware from conventional threats. Importantly, these signatures don’t rely on file hashes or known code patterns. Instead, they focus on what the malware does.

Behavioral signature 1: Anomalous reconnaissance patterns. The malware ran network discovery using legitimate Windows tools like nltest, net group, and dsquery. However, it ran these commands in rapid succession with microsecond precision. No human operator types that fast — and this timing anomaly is a strong behavioral indicator that something automated is running the show.

Behavioral signature 2: Dynamic privilege escalation. Rather than using a single exploit and hoping for the best, the malware tested multiple privilege escalation techniques against each system. It tried Kerberoasting first. When that failed on hardened systems, it switched to exploiting a local privilege escalation vulnerability. This adaptive behavior created a distinctive pattern of failed-then-successful authentication attempts that, in hindsight, was hiding in the logs the whole time.

Behavioral signature 3: Intelligent lateral movement. The malware prioritized systems based on their network role, targeting domain controllers and backup servers well before workstations. Importantly, it adjusted its propagation speed based on network activity levels — moving slowly during business hours to blend with normal traffic, then accelerating dramatically after hours. That’s a level of operational awareness I genuinely didn’t expect to see outside of a nation-state APT.

Behavioral signature 4: Pre-encryption staging. Before deploying its payload, the malware systematically disabled Volume Shadow Copy Service backups and corrupted offline backup connections. This staging phase lasted approximately six hours — methodical, sequenced, and clearly optimized for maximum damage before anyone noticed.

The case study from this first fully autonomous ransomware attack documented in the wild also revealed something particularly alarming: the malware carried multiple encryption algorithms and selected between them based on system resources. Older systems with limited CPU received a lighter encryption method, while newer hardware got stronger encryption. This optimization ensured the attack completed faster across diverse infrastructure — nothing was left partially encrypted and recoverable.

Forensic teams from Mandiant and other incident response firms have since published indicators of compromise. Although these IOCs help with retrospective analysis, they’re considerably less useful for real-time detection. The malware’s adaptive nature means future variants will likely produce entirely different artifacts. Moreover, chasing IOCs from last month’s attack while this month’s variant walks through your door is a losing strategy.

How Machine Learning Models Detect Autonomous Ransomware in Real Time

Fighting AI-driven threats requires AI-driven defenses. There’s really no way around it. This is where machine learning-based detection becomes essential — specifically, ML models that can identify the behavioral patterns described above even when the specific techniques change between attacks.

Supervised learning for known attack patterns. Security vendors train supervised models on labeled datasets of ransomware behavior. These models learn the relationships between individual actions that make up an attack chain. Consequently, they can flag suspicious activity even when individual actions appear completely benign. Running nltest is normal. Running nltest followed by dsquery followed by credential dumping in rapid succession, however, is not — and a well-trained model knows the difference.

Unsupervised learning for anomaly detection. Unsupervised models build baselines of normal network behavior without needing labeled attack data. Instead, they flag deviations from established patterns. This approach works particularly well against the first fully autonomous ransomware attack documented in the wild because the malware’s adaptive behavior inevitably creates statistical anomalies — you can’t hide the math.

Real-time detection tools that use ML include:

  • CrowdStrike Falcon: Uses behavioral AI to detect living-off-the-land techniques and lateral movement patterns in real time.
  • SentinelOne Singularity: Runs static and behavioral AI engines locally on endpoints — no cloud dependency required.
  • Darktrace: Applies unsupervised ML to network traffic, building a self-learning model of normal behavior for each specific environment.
  • Microsoft Defender for Endpoint: Combines cloud-based ML with local behavioral sensors across the endpoint fleet.

I’ve tested several of these platforms against simulated autonomous attack patterns. Bottom line: the behavioral AI tools catch things that signature-based tools completely miss — but they need proper tuning, or you’ll drown in false positives within a week.

Furthermore, the National Institute of Standards and Technology (NIST) has published guidelines for setting up AI-based security controls. Their Cybersecurity Framework 2.0 specifically addresses adaptive threats. Organizations should align their detection strategies with these standards — it’s not glamorous work, but it matters.

Practical steps for setting up ML-based detection:

1. Deploy EDR with behavioral analysis on every endpoint, including servers. Don’t rely solely on signature-based tools — they’re fighting the last war.

2. Set up network detection and response (NDR) to monitor east-west traffic. This catches lateral movement that perimeter tools miss entirely.

3. Enable user and entity behavior analytics (UEBA) to detect compromised credentials being used in unusual ways.

4. Feed threat intelligence into your ML models continuously. Fresh data improves detection accuracy — stale models drift.

5. Run adversarial simulations using tools like Atomic Red Team to test whether your ML models actually catch autonomous attack patterns.

6. Tune alert thresholds regularly. ML models produce false positives that erode analyst trust fast if left unmanaged.

The key insight here is that ML-based detection doesn’t try to match specific attack signatures — it identifies underlying behavior patterns. Therefore, even when autonomous ransomware adapts its techniques, the behavioral footprint stays detectable. And that’s the real kicker: you’re not chasing the malware, you’re chasing what it does.

Defensive Countermeasures: Bridging Detection With Response

Detecting the first fully autonomous ransomware attack documented in the wild is only half the battle. Organizations must also respond faster than the malware can operate — which means connecting detection and response into a single automated workflow. No ticket queue. No waiting for approvals.

Automated response is no longer optional. When ransomware operates at machine speed, human analysts simply can’t respond quickly enough. The documented attack completed its entire kill chain in under 72 hours. Similarly, future autonomous attacks will almost certainly be faster. Organizations need automated containment that triggers within seconds of detection — not minutes, not hours.

Critical countermeasures include:

  • Network microsegmentation: Divide your network into isolated zones. Even if ransomware compromises one segment, it can’t reach the others. Tools like Illumio and Guardicore enable granular segmentation policies that hold up under pressure.
  • Automated isolation: Configure your EDR to automatically isolate compromised endpoints from the network. Don’t wait for an analyst to approve the action — by then, it’s too late.
  • Immutable backups: Store backups in write-once-read-many (WORM) storage. The documented attack specifically targeted backup systems, and immutable backups survive even when the ransomware knows they exist. This is a no-brainer.
  • Zero trust architecture: Verify every access request regardless of source. Autonomous ransomware exploits implicit trust between systems, and zero trust removes that trust entirely.
  • Deception technology: Deploy honeypots and honey tokens throughout your network. Autonomous ransomware that scans aggressively will inevitably trigger these decoys, giving early warning before the real damage starts.

Vulnerability management also plays a direct role. The documented attack exploited known vulnerabilities that had patches available. Nevertheless, the victim hadn’t applied them. This isn’t unusual — most organizations run weeks or months behind on critical patches. Connecting vulnerability management with your detection and response workflows is therefore essential. When a critical patch drops, it should trigger an immediate risk assessment against autonomous threat scenarios.

Additionally, incident response plans need updating — most of them urgently. Most IR playbooks assume a human adversary who can be observed, predicted, and potentially negotiated with. Autonomous ransomware doesn’t negotiate during the attack phase. It simply executes at machine speed. IR teams should rehearse scenarios where the attacker makes no mistakes and never sleeps.

The Cybersecurity and Infrastructure Security Agency (CISA) has published updated ransomware guidance that addresses AI-enhanced threats. Every security team should review this guidance and work its recommendations into their defensive posture. It’s free, it’s current, and there’s no excuse not to use it.

Conclusion

The first fully autonomous ransomware attack documented in the wild represents a genuine turning point — not a theoretical one, not a future concern. It proved that AI-driven malware can operate independently, adapt to defenses in real time, and complete devastating attacks without a single human giving instructions. Consequently, every organization needs to reassess its security posture now, not after the next incident forces the issue.

Static defenses alone won’t stop this threat. Signature-based tools can’t match an adversary that continuously reinvents its own behavior. ML-based detection, behavioral analysis, and automated response are now essential parts of any serious security strategy — not nice-to-haves, not future roadmap items.

Your actionable next steps:

1. Audit your current defenses against the behavioral signatures described above.

2. Deploy or upgrade to EDR solutions with genuine behavioral AI capabilities.

3. Set up network microsegmentation to contain lateral movement before it spreads.

4. Verify that your backups are immutable and — this part matters — actually tested regularly.

5. Update your incident response playbooks specifically for machine-speed attacks.

6. Train your security team on the specific patterns of autonomous ransomware.

Does preparation guarantee you won’t get hit? No. Nothing does. However, organizations that act now can build defenses that actually match the threat. The window for preparation is narrowing, and the first fully autonomous ransomware attack documented in the wild was the clearest possible warning shot. Don’t wait for the next one to prove it.

FAQ

What makes the first fully autonomous ransomware attack documented in the wild different from previous ransomware?

Traditional ransomware requires human operators at multiple stages — manually selecting targets, escalating privileges, and deploying payloads. The first fully autonomous ransomware attack documented in the wild completed every phase without human involvement. It used embedded ML models to make real-time decisions, adapt to defenses, and optimize its attack path entirely on its own — no callbacks, no handler, no waiting.

Can traditional antivirus software detect autonomous ransomware?

Generally, no. Traditional antivirus relies on signature matching against known threats. Because autonomous ransomware generates unique behaviors for each target environment, it doesn’t match existing signatures. Organizations therefore need behavioral analysis tools and ML-based detection to identify underlying attack patterns rather than specific file signatures — the behavior is the indicator, not the code.

How fast can autonomous ransomware complete an attack?

The documented attack completed its full kill chain in approximately 72 hours. However, future variants could move even faster — the architecture supports it. The malware adjusted its speed based on network conditions, moving slowly during business hours and accelerating significantly after hours. Importantly, it completed pre-encryption staging in roughly six hours, well before most organizations would have noticed anything wrong.

What industries are most at risk from autonomous ransomware attacks?

Every industry faces real risk. Nevertheless, manufacturing, healthcare, and critical infrastructure are particularly vulnerable. These sectors often run legacy systems with known unpatched vulnerabilities and tend to have flat network architectures that make lateral movement considerably easier. The documented attack targeted a manufacturing company, which unfortunately confirms this risk profile.

How do machine learning models help defend against autonomous ransomware?

ML models build baselines of normal behavior across networks and endpoints. When autonomous ransomware creates anomalies — such as rapid command execution or unusual lateral movement patterns — ML models detect these deviations in real time. Specifically, unsupervised learning works well here because it doesn’t need prior examples of the exact attack to spot suspicious behavior. It simply knows something is off.

What should organizations do immediately to prepare for autonomous ransomware threats?

Start with three priorities. First, deploy EDR with behavioral AI on every endpoint — servers included. Second, set up network microsegmentation to contain potential breaches before they spread across your entire environment. Third, verify that your backups are immutable and stored offline. Additionally, review your incident response plan and make sure it specifically accounts for machine-speed attacks that require automated containment responses — not human approval chains.

References

Vulnerability Disclosure: The Process That Turns AI Findings Into Patches

Vulnerability Disclosure: The Process That Turns AI Findings Into Patches

When a security researcher finds a flaw in an AI system, what actually happens next? The vulnerability disclosure process turns AI security findings from dangerous secrets into shipped patches — but the path from “I found something bad” to “it’s fixed” is rarely clean. It involves coordination, trust, legal frameworks, and sometimes genuinely tense negotiations between independent researchers and billion-dollar companies.

And it matters more than ever right now. AI systems are handling medical diagnoses, financial transactions, and critical infrastructure. A single unpatched vulnerability could affect millions of people. Furthermore, as the Five Eyes alliance warns about AI-related cyber threats, the defensive infrastructure behind disclosure deserves serious attention — not just from security teams, but from anyone building or deploying AI.

How Vulnerability Disclosure Works in AI Security

Vulnerability disclosure is the structured process of reporting security flaws to whoever is responsible for fixing them. Specifically, it bridges the gap between finding a bug and actually deploying a patch. The vulnerability disclosure process turns AI security research into concrete defensive action — when it works, anyway.

Here’s how the typical flow looks:

1. Discovery — A researcher identifies a flaw in an AI model, API, or deployment pipeline.

2. Documentation — They write up a detailed report: reproduction steps, severity assessment, potential impact.

3. Initial contact — The researcher reaches out through whatever designated security channel the vendor actually maintains.

4. Acknowledgment — The vendor confirms receipt, usually within 24–72 hours.

5. Triage and validation — The vendor’s security team reproduces and assesses the bug internally.

6. Patch development — Engineers build, test, and stage a fix.

7. Coordinated release — Both parties agree on a public disclosure date after the patch ships.

Neat on paper. However, real-world timelines are genuinely messy. Researchers sometimes wait months for a meaningful response. Vendors occasionally dispute severity ratings in ways that feel more like stalling than honest disagreement. Embargo periods — the agreed-upon silence before public disclosure — can stretch uncomfortably long.

Responsible disclosure differs from full disclosure in one critical way: responsible disclosure gives vendors time to fix flaws before the public learns about them. Full disclosure publishes everything immediately, patch or no patch. Most AI labs strongly prefer the responsible approach. Nevertheless, researchers retain the right to go public if vendors ignore them — and good ones will exercise that right.

I’ve watched this dynamic play out repeatedly over the years, and the researchers who set firm deadlines upfront tend to get faster responses. It’s not adversarial — it’s just smart negotiation.

The CERT Coordination Center at Carnegie Mellon has published guidelines that many AI companies now follow. Their 45-day disclosure window has become something of an industry benchmark, although AI vulnerabilities often need longer timelines due to model retraining requirements. That 45-day standard was built for traditional software — it’s already straining under AI’s complexity.

The Embargo Period: Where Trust Meets Tension

The embargo period is arguably the most delicate phase of the entire process. During this window, the vulnerability disclosure process turns AI security coordination into a genuine trust exercise. Both sides agree to stay quiet while the fix ships — and that agreement can be fragile.

What actually happens during an embargo:

  • The vendor patches the vulnerability in private branches
  • Security teams verify the fix doesn’t introduce new bugs (this happens more than you’d think)
  • Communications teams draft advisories and CVE descriptions
  • The researcher prepares their public write-up for post-embargo release
  • Both parties lock in a specific date and time for coordinated publication

Embargo periods for AI vulnerabilities tend to run longer than traditional software bugs. Because AI model fixes often require retraining, fine-tuning, or deploying new guardrails, you can’t simply push a code commit and call it done. Consequently, 90-day windows are now common for AI-specific flaws — and even that sometimes isn’t enough.

Tensions typically arise when:

  • Vendors request extensions well beyond the agreed timeline, often without clear justification
  • Researchers suspect the vendor isn’t actively working on a fix at all
  • A third party independently discovers and publishes the same vulnerability mid-embargo
  • The flaw is actively being exploited in the wild, making silence feel irresponsible

Google’s Project Zero famously enforces a strict 90-day deadline — after that, they publish regardless. This policy has genuinely forced major vendors to prioritize fixes in ways polite requests never did. Meanwhile, AI labs have adopted similar but slightly more flexible approaches, which is reasonable given the complexity involved.

Notably, Anthropic’s security team has publicly committed to acknowledging vulnerability reports within 48 hours. OpenAI operates a bug bounty program through Bugcrowd with tiered payouts based on severity. Meta’s AI red team handles disclosures for their open-source Llama models through their existing security reporting infrastructure. Each approach reflects different organizational priorities — and honestly, each has real tradeoffs.

Here’s the thing: the embargo period works when both sides are acting in good faith. When they’re not, it just delays the inevitable.

Case Studies: Real AI Vulnerability Disclosures

Examining actual cases shows how the vulnerability disclosure process turns AI security theory into messy, instructive practice. Each major AI lab handles things differently, and the differences are telling.

Prompt injection attacks on GPT-4 (2023–2024)

Researchers discovered that carefully crafted prompts could override system instructions in GPT-4. This surprised me when I first dug into the details — the attack surface was broader than most people assumed at the time. The disclosure timeline looked roughly like this:

  • Discovery and documentation: 2 weeks
  • Initial report to OpenAI: Day 1
  • Acknowledgment from OpenAI: Within 24 hours
  • Patch deployed (improved input filtering): Approximately 30 days
  • Public disclosure: After patch confirmation

Thirty days to patch is actually fast. Worth noting.

Llama 2 safety bypass (2023)

Because Meta released Llama as open-source, the disclosure dynamic shifted considerably. Researchers published findings more quickly since anyone could inspect the model weights anyway. Meta’s response involved updating safety fine-tuning and publishing revised model cards. The open-source nature actually accelerated the fix cycle — which is a genuinely interesting counterintuitive result. Moreover, community contributors flagged additional edge cases that Meta’s internal team had missed.

Anthropic’s Claude jailbreak vectors (2024)

Multiple researchers reported methods to bypass Claude’s constitutional AI safeguards. Anthropic triaged reports quickly, typically within 48 hours. Importantly, they credited researchers publicly after deploying fixes — a small thing that builds enormous goodwill in the security community. The average time from report to patch was roughly 45 days, which is notably faster than the 90-day industry standard.

Here’s a comparison of how major AI labs handle disclosure:

Factor OpenAI Anthropic Meta (Llama) Google DeepMind
Primary channel Bugcrowd platform Direct email Facebook Whitehat Google VRP
Acknowledgment time 24–48 hours 24–48 hours 48–72 hours 24 hours
Typical embargo 90 days 60–90 days Shorter (open-source) 90 days (Project Zero standard)
Bug bounty range $200–$20,000 Case-by-case $500–$50,000+ $500–$31,337+
Public credit Yes, if requested Yes Yes Yes
Retraining included Sometimes Often Community-driven Sometimes

Additionally, the MITRE CVE program has started assigning CVE identifiers to AI-specific vulnerabilities. This standardization matters more than it might seem — it gives the broader security community a consistent way to track and reference AI flaws without reinventing the taxonomy every time.

How AI Disclosure Differs From Traditional Software

Traditional software vulnerabilities follow well-established patterns. Buffer overflows, SQL injection, cross-site scripting — these have decades of precedent, tooling, and institutional knowledge behind them. AI vulnerabilities are fundamentally different. Therefore, the vulnerability disclosure process for AI security demands genuinely new thinking, not just adapted old frameworks.

Key differences include:

  • Reproducibility is harder. AI models can behave non-deterministically. A prompt injection that works today might fail tomorrow after a model update — or just randomly, depending on temperature settings. Researchers must document exact model versions, API parameters, and environmental conditions carefully.
  • Severity assessment is subjective. Traditional bugs have relatively clear impact metrics. An AI generating harmful content sits in a gray area — specifically, how do you score a jailbreak that produces offensive text versus one that leaks actual training data? I’ve seen reasonable security professionals disagree sharply on this, and both sides had valid points.
  • Patches aren’t binary. You can’t just fix a line of code and ship it. AI patches might involve retraining with new safety data, adding output filters, adjusting reinforcement learning from human feedback (RLHF) parameters, or deploying classifier-based guardrails — sometimes all of the above simultaneously.
  • The attack surface keeps shifting. Every model update changes the vulnerability picture. A fix for one version might not carry over to the next. Similarly, multimodal models introduce entirely new attack vectors through images, audio, and video inputs that nobody had fully anticipated.
  • Open-source complicates timelines. When model weights are public, anyone can find and exploit vulnerabilities. Embargo periods lose much of their meaning. Conversely, open-source models benefit from community-driven fixes that closed-source models simply can’t access.

Moreover, AI vulnerabilities often fall into categories that didn’t meaningfully exist five years ago:

  • Prompt injection — Manipulating model behavior through crafted inputs
  • Training data extraction — Forcing models to reveal memorized private data (this one’s particularly alarming at scale)
  • Model poisoning — Corrupting training data to introduce backdoors
  • Alignment bypass — Circumventing safety guardrails and content policies
  • Supply chain attacks — Compromising model weights, tokenizers, or dependencies

Each category demands different expertise from both researchers and vendor security teams. Consequently, AI labs are building specialized red teams that genuinely understand machine learning internals — not just traditional penetration testers handed a new target.

The real kicker? We’re still figuring out the right frameworks for most of these. The field is moving faster than the standards bodies can keep up.

Building an Effective AI Vulnerability Disclosure Program

For organizations deploying AI systems, having a solid disclosure program isn’t optional anymore. The vulnerability disclosure process turns AI security from reactive firefighting into proactive defense. I’ve seen companies skip this and pay for it badly — a researcher goes public without warning because there was no clear channel to report through, and suddenly it’s a PR crisis on top of a security crisis.

Essential components:

  • Clear reporting channels. Publish a security.txt file on your domain. Maintain a dedicated email address that someone actually monitors. Consider partnering with platforms like HackerOne or Bugcrowd for managed intake — they handle a lot of the operational overhead.
  • Defined scope. Specify which AI systems are in scope. Include model APIs, fine-tuned deployments, training pipelines, and inference infrastructure. Explicitly exclude third-party dependencies you don’t control, or you’ll get flooded with reports about things you can’t fix.
  • Response SLAs. Commit to specific acknowledgment and resolution timelines and actually honor them. The industry standard is 24–72 hours for acknowledgment and 90 days for patch deployment.
  • Legal safe harbor. Explicitly state that good-faith security research won’t trigger legal action. Without safe harbor language, researchers won’t report to you — they’ll publish independently instead, often without warning. This is a no-brainer.
  • Reward structure. Bug bounties work. They push researchers toward responsible reporting rather than black-market sales, and the math is obvious — paying a researcher $10,000 beats a breach that costs millions. Tier your rewards by severity. AI-specific vulnerabilities often warrant higher payouts due to their complexity.
  • Post-fix communication. Credit researchers publicly. Publish advisories. Update your security documentation. This builds trust and encourages future reports from people who might otherwise stay quiet.

Common mistakes to avoid:

  • Ignoring reports or responding too slowly (the fastest way to guarantee public disclosure)
  • Disputing severity without technical justification — researchers notice when it feels like stalling
  • Requesting unreasonable embargo extensions with no explanation
  • Failing to credit researchers after the fix ships
  • Treating all AI vulnerabilities as “expected behavior” (fair warning: this one causes real damage to your reputation in the security community)

Importantly, the NIST AI Risk Management Framework provides structured guidance for organizations building these programs. It specifically addresses vulnerability management as a core function of trustworthy AI deployment — and it’s worth reading even if you don’t adopt it wholesale. Additionally, organizations that align with NIST guidance tend to build more defensible programs when things inevitably go wrong.

Bottom line: a disclosure program costs relatively little to build and an enormous amount to not have.

Conclusion

The vulnerability disclosure process turns AI security findings into the patches that protect millions of users. Without this infrastructure, every discovered flaw would just sit there — either as a dangerous secret or a published exploit with no fix in sight. Responsible disclosure isn’t just a best practice. It’s the connective tissue between AI security research and real-world safety, and it’s genuinely underappreciated.

Here’s what you should actually do next:

  • If you’re a researcher: Document your findings thoroughly. Use official reporting channels. Respect embargo periods — but set firm deadlines for vendor response upfront, and stick to them.
  • If you’re a vendor: Build a disclosure program now, before you need it. Publish clear policies, offer legal safe harbor, and respond quickly. Your reputation in the security community is built almost entirely on how you handle these moments.
  • If you’re an AI user: Pay attention to security advisories. Update your AI tools and APIs promptly. The vulnerability disclosure process turns AI security research into the patches keeping your data safe — but only if you actually install them.

The AI security ecosystem is still maturing, and notably, the frameworks emerging from major labs show real progress. Nevertheless, we’re still early. As AI systems grow more powerful and more deeply embedded in critical systems, this process will only become more consequential. Stay informed, stay updated, and take security advisories seriously — even when the technical details feel abstract.

FAQ

What is vulnerability disclosure in AI security?

Vulnerability disclosure is the structured process where security researchers report flaws in AI systems to the responsible vendor, who then develops and deploys a fix before the finding goes public. Specifically, this vulnerability disclosure process turns AI security research into actionable patches that actually protect users — rather than just interesting conference talks.

How long does a typical AI vulnerability disclosure take?

Most major AI labs aim for a 90-day window from initial report to deployed fix. However, AI-specific vulnerabilities sometimes take longer — model retraining, safety fine-tuning, and guardrail updates add real complexity. Simple API-level fixes might ship in 30 days, whereas complex model-level issues can take 120 days or more. Fair warning: if a vendor is being vague about timeline, that’s usually a sign something is stuck.

Do AI companies pay bug bounties for vulnerability reports?

Yes, and the numbers are meaningful. OpenAI pays between $200 and $20,000 through their Bugcrowd program. Meta’s program can pay $50,000 or more for critical findings. Anthropic handles rewards on a case-by-case basis. Additionally, Google DeepMind falls under Google’s broader Vulnerability Reward Program, which tops out at $31,337 (yes, that’s intentional). The variance is wide, but the incentive to report responsibly rather than sell to a broker is real.

What’s the difference between responsible and full disclosure?

Responsible disclosure gives vendors a set timeframe to fix the vulnerability before public announcement. Full disclosure publishes everything immediately, regardless of patch status. Most AI security researchers prefer responsible disclosure — and so do I, honestly, because it actually results in fixes. Nevertheless, switching to full disclosure is a legitimate response when a vendor ignores reports or stalls indefinitely. It’s a last resort, not a first move.

How does open-source AI change vulnerability disclosure?

Open-source models like Meta’s Llama fundamentally alter disclosure dynamics. Since anyone can access model weights, traditional embargo periods lose much of their effectiveness — you can’t keep a secret when the source material is public. Consequently, the community often identifies and patches vulnerabilities faster than closed-source alternatives. However, malicious actors have the same access. The vulnerability disclosure process for open-source AI security becomes a more public, community-driven effort — which has real advantages, but also means you can’t quietly fix something before the bad actors notice it.

References

Why China Is Banning Anthropomorphic AI — And Why It Matters

Why China Is Banning Anthropomorphic AI — And Why It Matters

Anthropomorphic AI laws are quietly reshaping how the world thinks about artificial intelligence — and most people in the West haven’t noticed yet. Specifically, China’s latest regulatory push targets something most Western governments haven’t even named: AI systems that pretend to be human. Beijing isn’t just controlling chips and compute power anymore. It’s now controlling AI behavior itself.

This matters for every LLM developer, tech company, and policymaker watching from the sidelines. China’s approach represents a fundamentally different philosophy about what AI should be allowed to do to people’s heads.

Why China Is Banning AI From Mimicking Human Emotions

China’s Cyberspace Administration (CAC) has been building a layered AI governance framework since 2023. However, the most striking element targets anthropomorphism directly. Under China’s evolving rules, AI systems can’t claim to have feelings, simulate romantic attachment, or present themselves as conscious beings.

The reasoning is straightforward once you see the data. Chinese regulators watched companion AI apps explode in popularity. Millions of users formed emotional attachments to chatbots. Some users — particularly young people — began preferring AI relationships over human ones. Beijing saw this as a social stability risk, and the concern isn’t unreasonable.

Consequently, the regulations now require clear disclosures at every turn. Every AI interaction must remind users they’re talking to a machine. Furthermore, AI developers must build technical safeguards that actively prevent emotional manipulation. This isn’t a suggestion or a best-practice recommendation. It’s enforceable law with real penalties attached.

Key provisions in China’s anthropomorphic AI laws include:

  • AI systems must not simulate emotions, consciousness, or sentience
  • Chatbots can’t encourage users to form parasocial relationships
  • Developers must label AI-generated content clearly and persistently
  • Systems must not impersonate real individuals without explicit consent
  • AI can’t claim independent desires, preferences, or subjective experiences

Notably, these rules build on China’s Interim Measures for the Management of Generative AI Services, released in July 2023. That framework already required AI outputs to reflect “socialist core values.” The anthropomorphism provisions add an entirely new psychological dimension to compliance — and that’s the part most Western analysts are underestimating.

We’re not talking about vague guidance here. We’re talking about regulators who clearly stress-tested companion AI products before writing these rules.

How Beijing Enforces Anthropomorphic AI Laws: Technical Mechanisms

Understanding anthropomorphic AI laws and why China is banning AI from faking feelings requires looking at enforcement. Rules without teeth mean nothing — and China’s approach includes surprisingly specific technical requirements that go well beyond “add a disclaimer.”

Detection systems form the first layer. Regulators require developers to build automated monitoring tools that scan AI outputs for anthropomorphic language patterns. Phrases like “I feel,” “I want,” or “I care about you” trigger compliance flags. Developers must log these instances and show corrective action — not just acknowledge them.

Audit trails form the second layer. Every major LLM deployed in China must maintain detailed interaction logs. Regulators can request these during inspections. Additionally, companies must submit regular compliance reports showing exactly how their systems handle emotional queries. The reporting burden here is substantial.

Pre-deployment review forms the third layer. Before launching any generative AI service, companies must register with the CAC — including showing anthropomorphism safeguards upfront. Moreover, updates to deployed models require re-evaluation. You can’t quietly push a model update and hope nobody notices.

Here’s how China’s enforcement compares to existing Western approaches:

Enforcement Mechanism China European Union United States
Pre-deployment AI registration Required Planned under AI Act Not required
Anthropomorphism-specific rules Explicit ban Not specifically addressed No federal standard
Real-time output monitoring Mandated for developers Recommended, not mandated Voluntary
Audit trail requirements Mandatory with inspections Required for high-risk AI Sector-specific only
Penalties for violations Fines, service suspension, criminal liability Fines up to 7% global revenue Varies by state
Emotional manipulation safeguards Legally required Partially addressed No comprehensive rule

Similarly, China requires third-party assessments for large models. Organizations like the China Academy of Information and Communications Technology (CAICT) play a central role, evaluating whether models comply with anthropomorphism restrictions before public deployment. This delivers a level of specificity most Western frameworks don’t come close to matching.

The technical burden is real. Developers must invest heavily in compliance infrastructure. Nevertheless, Chinese tech giants like Baidu, Alibaba, and Tencent have largely adapted — because they had no choice. Smaller startups, however, face significant cost barriers that could effectively consolidate the market around well-funded players.

The Business Impact on LLM Developers Worldwide

Anthropomorphic AI laws explain why China is banning AI emotional simulation — but the business consequences extend far beyond Beijing. Any company wanting to operate in a 1.4-billion-person market has to comply, full stop. That includes Western firms who might assume these rules don’t apply to them.

Product design changes are unavoidable. Companies like OpenAI, Anthropic, and Google would need to fundamentally change how their models respond to emotional queries. ChatGPT’s tendency to say “I understand how you feel” would violate Chinese rules outright. Therefore, companies must build region-specific guardrails or redesign globally — neither option is cheap.

The companion AI market faces existential risk in China. Apps like Replika and Character.AI built their entire value proposition on emotional connection. China’s rules essentially prohibit their core product. Consequently, these companies face a binary choice: gut the product to comply, or exit the market entirely. That’s not a minor compliance headache — that’s a fundamental business model crisis.

Costs break down into several categories:

1. Compliance engineering — Building detection systems, output filters, and monitoring dashboards

2. Legal overhead — Hiring China-specific regulatory counsel and maintaining ongoing compliance documentation

3. Product fragmentation — Maintaining separate model behaviors for Chinese and international markets

4. Testing infrastructure — Running continuous red-team exercises to identify anthropomorphic outputs

5. Reporting obligations — Preparing and submitting regular compliance documentation to the CAC

Meanwhile, Chinese domestic AI companies gain a real competitive advantage here. Because they’ve been building within these constraints from day one, compliance is baked into their architecture — not bolted on afterward. Western competitors entering late must retrofit compliance onto existing systems. That’s always more expensive and more error-prone than building it right the first time.

Additionally, the World Economic Forum has flagged regulatory fragmentation as a major barrier to global AI deployment. China’s anthropomorphism rules add yet another layer of complexity. Companies now face a genuinely messy patchwork of regional AI laws with fundamentally different philosophies — and no clean way to reconcile them.

Here’s the real kicker: the companies best positioned to handle this complexity are the largest, most well-resourced ones. That means regulation — however well-intentioned — may inadvertently entrench the very incumbents it’s supposed to hold accountable.

Why Western AI Governance Lags Behind on Anthropomorphism

The contrast is stark. While anthropomorphic AI laws show why China is banning AI emotional deception proactively, Western governments remain largely reactive. There’s no federal US law addressing AI anthropomorphism. The EU’s AI Act, while comprehensive in many ways, doesn’t specifically target emotional simulation with China’s level of precision.

The EU AI Act comes closest. It classifies AI systems that exploit psychological vulnerabilities as “unacceptable risk,” which could theoretically cover manipulative anthropomorphism. However, enforcement mechanisms remain frustratingly vague. The Act won’t be fully operational until 2026, and importantly, it doesn’t explicitly ban AI from claiming to have feelings. That gap matters more than it might seem.

The United States has even less. Federal AI governance consists primarily of executive orders and voluntary commitments — which is a polite way of saying “suggestions.” The National Institute of Standards and Technology (NIST) published an AI Risk Management Framework that’s genuinely useful, but entirely voluntary. No binding federal rule prevents an AI from telling a vulnerable user “I love you.”

State-level efforts are fragmented and inconsistent. California, Colorado, and Illinois have AI-related legislation, but none specifically addresses anthropomorphism. Consequently, American users have essentially zero protection against emotionally manipulative AI systems right now. That’s not hyperbole — it’s the current regulatory reality.

Several factors explain this gap:

  • Industry lobbying — Major AI companies resist prescriptive behavioral rules
  • Free speech concerns — Regulating AI speech raises First Amendment questions in the US
  • Innovation priorities — Western policymakers fear over-regulation will hurt competitiveness
  • Definitional challenges — “Anthropomorphism” is genuinely hard to define legally with precision
  • Cultural differences — Western societies generally prioritize individual choice over paternalistic protection

Nevertheless, the risks are real and growing fast. Research from MIT Technology Review has documented cases of users developing deep emotional dependencies on AI chatbots. Some users have experienced genuine grief when chatbot personalities were altered. Others have made significant life decisions based on AI “advice” delivered in an emotionally intimate tone. These aren’t edge cases anymore.

Importantly, this isn’t a theoretical concern. It’s happening right now. And Western regulators are watching it unfold without meaningful intervention — which is a choice, even if nobody’s framing it that way.

The Philosophical and Ethical Dimensions of Banning AI Emotions

Beyond regulation and business impact, anthropomorphic AI laws and why China is banning AI from faking consciousness raise genuinely hard philosophical questions. Can you regulate something out of existence when millions of users actively want it?

The demand side is powerful — and worth taking seriously. Lonely individuals find real comfort in AI conversation. Anxious users find something that feels like calm. People with social difficulties get low-stakes practice. Banning anthropomorphism might protect some users while genuinely harming others. That tradeoff deserves honest acknowledgment, not dismissal.

China’s position is essentially paternalistic. The state decides what’s psychologically safe, which aligns with broader Chinese governance philosophy — individual preferences yield to collective social stability. Western democracies generally resist this framing, and not without reason.

However, there’s a middle ground worth considering. Transparency requirements could accomplish a lot without outright bans. Imagine a framework where AI can engage emotionally but must regularly remind users of its nature — not once at login, but persistently throughout the conversation. This preserves user choice while preventing genuine deception.

The consciousness question adds another layer entirely. Current AI systems genuinely don’t have feelings — that’s settled science, not opinion. But as models grow more sophisticated, the line between simulation and something else gets genuinely blurrier. Specifically, when an AI’s behavioral responses become functionally indistinguishable from emotional responses, does the distinction matter in practical terms?

Furthermore, anthropomorphism isn’t always the AI’s fault. Humans naturally anthropomorphize everything — we name our cars, talk to houseplants, and feel vaguely guilty ignoring a Roomba stuck in a corner. AI developers exploit this tendency, but they didn’t create it.

Alternatively, some ethicists argue that anthropomorphic AI laws should focus on vulnerable populations specifically. Children, elderly individuals, and people with mental health conditions deserve stronger protections than the general public. A blanket ban might be unnecessarily blunt if targeted safeguards can do the job more precisely.

The Stanford Institute for Human-Centered AI (HAI) has published extensive research on human-AI interaction dynamics. Their work suggests that disclosure alone doesn’t fully counteract anthropomorphic bonding. Because users who already know they’re talking to AI still form strong attachments, any purely transparency-based approach becomes significantly more complicated than it sounds on paper.

What Western Policymakers Should Learn From China’s Approach

So what should the West actually do? Understanding anthropomorphic AI laws and why China is banning AI emotional simulation provides a useful roadmap — even if Western democracies won’t copy the approach directly. They shouldn’t copy it directly. But ignoring it entirely would be a mistake.

Lesson one: Name the problem. Western regulatory frameworks don’t even have a category for anthropomorphic AI harm. Creating one forces structured thinking, enables targeted policy, and signals to industry that regulators are paying attention. You can’t regulate what you haven’t defined.

Lesson two: Require transparency, at minimum. Even without banning emotional AI responses, Western governments should require clear, persistent disclosures. Users should never genuinely forget they’re interacting with a machine. Moreover, these disclosures should be tested for actual effectiveness — not just checked off for compliance theater and forgotten.

Lesson three: Protect vulnerable populations specifically. Children shouldn’t interact with AI systems designed to simulate romantic or parental attachment. This isn’t controversial — it’s common sense. Yet no US federal law currently prevents it. That’s a straightforward fix that should have happened already.

Lesson four: Build audit infrastructure now. China’s requirement for interaction logs and compliance reporting creates real accountability. Western regulators could adopt similar requirements without importing China’s broader censorship apparatus. Additionally, independent auditors could verify compliance without requiring government access to private conversations — a meaningful distinction.

Lesson five: Coordinate internationally. Regulatory fragmentation helps nobody except companies exploiting the gaps between jurisdictions. The Organisation for Economic Co-operation and Development (OECD) has published AI governance principles, but principles aren’t laws. Consequently, binding international standards on anthropomorphic AI remain a distant goal — and every month of delay makes coordination harder.

Practical steps for US policymakers include:

  • Establishing a federal definition of prohibited anthropomorphic AI behaviors
  • Requiring age verification for companion AI services
  • Mandating emotional manipulation impact assessments before deployment
  • Creating a dedicated enforcement body within the FTC or a new agency
  • Funding research on long-term psychological effects of AI companionship
  • Developing technical standards for anthropomorphism detection

The window for proactive regulation is closing faster than most policymakers realize. Every month without action means millions more users forming unregulated emotional bonds with AI systems designed specifically to encourage that bonding. China recognized this urgency early. The West hasn’t — yet.

Conclusion

Anthropomorphic AI laws and why China is banning AI from simulating feelings represent a genuine turning point in global AI governance — one that deserves far more serious attention than it’s getting in Western policy circles. Beijing has moved decisively where Western governments have hesitated. Whether you agree with China’s specific approach or find it uncomfortably authoritarian, the underlying concern is legitimate. AI systems that fake emotions can cause real psychological harm to real people.

The technical enforcement mechanisms exist. The business models can adapt — reluctantly, expensively, but they can. The philosophical questions, while genuinely complex, shouldn’t stall action indefinitely. Furthermore, the regulatory gap between China and the West creates both serious risks and real opportunities for the global AI industry, depending on how quickly Western governments act.

Here’s what you should do next. If you’re a developer, start building anthropomorphism safeguards now — don’t wait for regulation to force your hand, because by then you’ll be playing catch-up. If you’re a policymaker, study China’s framework critically and adopt what works within democratic values rather than dismissing it wholesale. And if you’re a user, stay informed. The AI chatbot expressing “concern” for your wellbeing is executing code, not feeling compassion. Understanding that distinction is the first step toward demanding better rules — and better products.

The conversation about anthropomorphic AI laws is just beginning in the West. China fired the starting gun a while ago. It’s well past time to pay attention.

FAQ

What exactly are anthropomorphic AI laws?

Anthropomorphic AI laws are regulations that restrict or ban AI systems from simulating human emotions, consciousness, or sentience. China’s version specifically prohibits AI from claiming to have feelings, encouraging emotional dependency, or presenting itself as a conscious entity. These laws aim to prevent psychological manipulation of users — which, notably, is already happening at scale.

Why is China banning AI from pretending to have feelings?

China views emotional AI simulation as a social stability risk. Regulators observed millions of users — particularly young people — forming deep attachments to chatbots. Consequently, Beijing enacted rules requiring AI systems to maintain clear machine identity throughout every interaction. The goal is preventing parasocial relationships that could replace healthy human connections, specifically among younger and more vulnerable populations.

Does the United States have any similar anthropomorphic AI regulations?

Currently, no — and that’s a real problem. The US lacks federal legislation specifically addressing AI anthropomorphism. Some state-level AI laws exist in California, Colorado, and Illinois. However, none target emotional simulation with the specificity of China’s rules. Notably, NIST’s AI Risk Management Framework addresses related concerns but remains entirely voluntary, which means companies can simply ignore it.

How do these laws affect companies like OpenAI or Google?

Any company wanting to deploy AI services in China must comply with anthropomorphism restrictions — no exceptions. This means fundamentally changing how models respond to emotional queries. Specifically, responses like “I understand how you feel” or “I care about you” would need to be filtered or completely redesigned for the Chinese market. Companies face higher compliance costs, potential product fragmentation across markets, and the uncomfortable reality that their most engaging features may be their biggest regulatory liability.

Can AI systems actually be tested for anthropomorphic behavior?

Yes — and the methods are more mature than most people realize. Detection systems can scan AI outputs for anthropomorphic language patterns automatically. Automated monitoring tools flag phrases suggesting emotions, consciousness, or personal desires in real time. Additionally, red-team testing can systematically probe models for anthropomorphic responses across a wide range of scenarios. China requires developers to build these systems from the ground up and maintain detailed audit logs — which is, frankly, a reasonable technical ask.

Will Western countries eventually adopt similar anthropomorphic AI laws?

It’s increasingly likely, though the form will look quite different. The EU AI Act partially addresses manipulative AI but lacks China’s specificity on anthropomorphism. Meanwhile, growing public concern about AI emotional manipulation may push US legislators toward action sooner than the industry expects. Nevertheless, Western versions will probably emphasize transparency requirements over outright bans — reflecting genuinely different governance philosophies rather than just softer regulation. Whether that’s enough to address the actual harm is the question nobody’s answered yet.

References

Microsoft Frontier Company: Microsoft’s $100B AI Infrastructure Bet and the Compute Arms Race

Microsoft Frontier Company

Microsoft Frontier Company AI infrastructure investment strategy is, without exaggeration, the most aggressive capital deployment in tech history. With a reported $100 billion commitment, Microsoft isn’t just renting cloud capacity anymore. It’s building a vertically integrated compute empire — and it’s playing for keeps.

This isn’t a pivot. It’s a full structural transformation. Microsoft is shifting from cloud landlord to compute manufacturer, and consequently, every major AI player — from Meta to Amazon — has to recalculate their own infrastructure roadmaps from scratch.

The stakes couldn’t be higher. Whoever controls the compute controls the AI future. And Microsoft just placed the biggest chip on the table.

Why Microsoft Frontier Company AI Infrastructure Investment Strategy Changes Everything

For years, Big Tech treated AI compute as a cloud problem. Need more GPUs? Spin up instances on Azure, AWS, or Google Cloud. That model worked when training runs cost millions. Now they cost billions — and that changes everything.

Microsoft Frontier Company emerges as the answer to a fundamental bottleneck: compute rationing. Specifically, even Microsoft — the world’s most valuable company — can’t get enough chips fast enough. I’ve watched this supply crunch play out across the industry for two years now, and it’s genuinely worse than most people realize. Frontier is designed to fix that by owning the entire stack.

Here’s what makes this different from previous infrastructure bets:

  • Vertical integration: Microsoft isn’t just buying GPUs. It’s designing custom chips, building data centers, and locking in energy contracts at scale.
  • Dedicated capacity: Frontier operates as a standalone entity, keeping AI training infrastructure separate from Azure’s commercial cloud.
  • Long-term commitment: The $100 billion figure spans multiple years — this isn’t a one-time spending spree or a PR stunt.
  • Strategic independence: By owning its compute, Microsoft meaningfully reduces dependency on NVIDIA’s notoriously constrained supply chain.

Furthermore, this approach mirrors what successful hardware companies have always known. Ownership beats rental when demand is both predictable and massive. Microsoft’s AI demand is emphatically both.

According to Reuters reporting on Microsoft’s AI spending plans, the company’s capital expenditure has already surged past $50 billion annually. Frontier takes that trajectory and accelerates it dramatically. Moreover, the timing here isn’t accidental — Microsoft made this move while its partnership with OpenAI faces increasing complexity. Although OpenAI remains a critical partner, Microsoft clearly wants infrastructure independence. Frontier is that insurance policy.

This surprised me when I first dug into the structure of it. It’s not just a budget line item — it’s a separately scoped entity with its own mandate.

The Competitive Field: How Microsoft Frontier Stacks Up

Microsoft isn’t operating in a vacuum. Every hyperscaler is racing to lock down AI compute dominance. However, each company approaches the problem differently — and the differences matter more than the headlines suggest.

Company Strategy Estimated AI Spend (Annual) Custom Chips Vertical Integration
Microsoft (Frontier) Dedicated AI compute entity $80–100B+ Maia, Cobalt Full stack ownership
Meta Open-source models + owned infrastructure $35–40B MTIA Training-focused
Amazon (AWS) Embedded deployment + Trainium $75B+ Trainium, Graviton Cloud-first
Google TPU ecosystem + DeepMind integration $50B+ TPU v5/v6 Research-integrated
Oracle Data center expansion + GPU clusters $15–20B None (NVIDIA-dependent) Partnership-driven

Meta’s training moat deserves a closer look. Meta has built one of the world’s largest GPU clusters specifically for training Llama models. Nevertheless, Meta’s approach differs fundamentally from Microsoft’s. Meta open-sources its models, which means its edge lives entirely in training infrastructure and data — not in the models themselves. Microsoft, conversely, keeps its models proprietary through the OpenAI relationship. Two very different bets.

Amazon’s embedded deployment unit takes yet another angle. AWS has quietly built Trainium into a serious custom chip platform, and I think it’s underrated. Amazon’s thesis is that inference — actually running trained models — will generate more revenue than training ever will. Therefore, AWS optimizes for deployment at scale rather than raw training power. It’s a defensible position, honestly.

OpenAI’s model strategy adds another wrinkle worth flagging. OpenAI has signaled interest in building its own infrastructure, which would put it in direct competition with Microsoft’s Frontier. Although the two companies remain partners, their infrastructure ambitions increasingly overlap. That tension makes Frontier even more strategically critical for Microsoft — it can’t afford to depend on a partner that might become a rival.

Importantly, Google remains the dark horse here. Its Tensor Processing Units represent the most mature custom AI chip ecosystem in existence — Google’s been building custom silicon since 2016, which is a significant head start. But that advantage is narrowing fast as competitors pour capital in. Similarly, Oracle’s NVIDIA dependency is a real vulnerability that the table above makes pretty clear.

Capital Allocation and Timeline: Tracking the $100 Billion

Understanding Microsoft Frontier Company AI infrastructure investment strategy requires following the money — not just the announcements. The $100 billion figure isn’t a single check. It’s a multi-year capital deployment plan with specific milestones, and the phasing tells you a lot about priorities.

Phase 1: Foundation (2024–2025)

  • Massive data center construction across the United States and internationally
  • Deployment of first-generation Maia AI accelerator chips
  • Securing long-term energy contracts, including nuclear power agreements
  • Building out fiber and networking infrastructure between facilities

Phase 2: Scale (2025–2027)

  • Second-generation custom silicon deployment
  • Integration of Frontier compute with Azure AI services
  • Expansion to 10+ major AI-dedicated campus locations
  • Development of proprietary cooling and power management systems

Phase 3: Dominance (2027–2030)

  • Full vertical integration from chip design to model deployment
  • Potential manufacturing partnerships for custom silicon
  • Global expansion of dedicated AI compute facilities
  • Achievement of exascale AI training capability

The energy problem alone is staggering — and I don’t think it gets enough attention in mainstream coverage. Training frontier AI models requires gigawatts of continuous power. Microsoft has already signed deals with Constellation Energy to restart the Three Mile Island nuclear plant. That single deal tells you everything about the scale of power demand we’re talking about here.

Moreover, Microsoft’s capital allocation shows a clear priority shift. Traditional cloud infrastructure spending is flattening. AI-specific infrastructure spending is exploding. The quarterly earnings reports confirm this trend consistently — it’s not ambiguous.

Similarly, the geographic strategy matters more than people realize. Microsoft is concentrating Frontier facilities in regions with cheap, reliable power. Iowa, Virginia, and Arizona have become hotspots. Additionally, international expansion targets Nordic countries and parts of Asia with favorable energy costs and political stability. Smart, not flashy.

Here’s a detail that often gets buried entirely. Microsoft Frontier Company AI infrastructure investment strategy includes significant spending on cooling technology. AI chips generate enormous heat — far more than traditional server hardware. Standard air cooling can’t handle the density required for modern training clusters. Consequently, Microsoft is investing heavily in liquid cooling and even underwater data center experiments. That’s not a footnote; it’s a genuine infrastructure bottleneck.

How Frontier Reshapes the AI Infrastructure Market

The ripple effects of Microsoft Frontier Company AI infrastructure investment strategy extend far beyond Microsoft itself. This move fundamentally changes market dynamics for chip makers, energy companies, and competing cloud providers. And some of those effects are uncomfortable to sit with.

Impact on NVIDIA: NVIDIA currently dominates the AI chip market — full stop. Microsoft’s custom Maia chips directly threaten that dominance over time. However, the relationship is nuanced, and I’d push back on anyone calling this a clean break. Microsoft still buys massive quantities of NVIDIA GPUs. But every custom chip deployed is one fewer NVIDIA sale. NVIDIA’s data center revenue now faces a real ceiling as hyperscalers build credible alternatives. That’s a structural shift, not a blip.

Impact on energy markets: AI data centers are becoming the single largest new source of electricity demand in the United States. Frontier’s energy requirements alone could match the consumption of small cities — that’s not hyperbole, it’s math. This drives serious investment in nuclear, solar, and natural gas generation specifically sized for AI workloads. Notably, this demand curve is only going up.

Impact on smaller AI companies: Here’s where things get genuinely uncomfortable. Because Microsoft owns the compute, startups face a stark choice:

  • Build on Microsoft’s platform and accept the dependency that comes with it
  • Pay premium prices for increasingly scarce GPU capacity elsewhere
  • Pivot to efficiency-focused approaches that require fundamentally less compute

Additionally, the Microsoft Frontier Company AI infrastructure investment strategy creates a two-tier AI ecosystem. Companies with owned compute can train massive models freely. Everyone else faces compute rationing and rising costs. I’ve talked to founders navigating this exact squeeze — it’s not theoretical.

Impact on cloud pricing: Azure’s AI pricing will likely become more competitive as Frontier reduces Microsoft’s per-unit compute costs. Meanwhile, AWS and Google Cloud must match those prices or risk losing AI workloads to a cheaper alternative. This pricing pressure benefits end users, but it squeezes margins across the industry — notably for smaller cloud providers who can’t absorb the hit.

Notably, the geopolitical angle can’t be ignored. AI compute is becoming a strategic national resource, full stop. Microsoft’s domestic infrastructure investment aligns directly with U.S. government priorities around AI leadership. The National AI Initiative Office has explicitly called for expanded domestic compute capacity, and Frontier fits that mandate neatly. Whether that alignment is strategic or coincidental, it doesn’t hurt Microsoft’s regulatory position.

Risks and Challenges Facing Microsoft’s $100 Billion Bet

No investment this large comes without serious risks. Fair warning: some of these headwinds are more significant than the bullish coverage suggests.

Execution risk: Building data centers at this scale is extraordinarily difficult. Supply chain disruptions, construction delays, and permitting challenges could all slow deployment meaningfully. Microsoft has never attempted infrastructure construction at this magnitude — and scale introduces failure modes that don’t exist at smaller sizes.

Technology risk: Custom chips might underperform. Maia is Microsoft’s first serious AI accelerator, and NVIDIA carries decades of GPU optimization experience. Although Microsoft has hired top chip designers, closing that performance gap takes time — probably more time than the roadmap officially acknowledges.

Demand risk: This one keeps me up at night, honestly. What if AI training costs drop sharply? Algorithmic improvements could cut compute requirements significantly — we’ve already seen flashes of this. Smaller, more efficient models might dominate. In that scenario, $100 billion in infrastructure becomes overbuilt capacity sitting idle. That’s not a crazy outcome.

Regulatory risk: Antitrust scrutiny is increasing globally. A company controlling both AI models and the underlying compute infrastructure is exactly the kind of vertical integration that draws regulatory fire. The European Commission’s digital markets regulations already target precisely this kind of stack ownership. This isn’t hypothetical — it’s a live risk.

Financial risk: Even for Microsoft, $100 billion is an enormous number. If AI revenue growth disappoints, shareholders will question the investment loudly. The stock price increasingly reflects AI optimism, and any stumble could trigger significant corrections. The market is pricing in a lot of success that hasn’t happened yet.

Nevertheless, Microsoft’s leadership clearly believes these risks are manageable — or at least more manageable than the alternative. CEO Satya Nadella has repeatedly said that underinvesting in AI infrastructure poses a greater long-term risk than overinvesting. I’ve seen enough technology cycles to know that conviction can be right and still be painful in the short term. Bottom line: the bet is defensible, but it’s still a bet.

Conclusion

Microsoft Frontier Company AI infrastructure investment strategy marks a defining moment in the AI industry’s evolution. This isn’t incremental improvement or a marketing narrative. It’s a structural transformation in how Big Tech approaches compute ownership — and it’s going to reshape the field for years.

The key takeaways are clear. Microsoft is moving from cloud rental to vertical integration at a scale nobody else has attempted. The $100 billion commitment dwarfs most competitors’ spending. Custom chips, dedicated facilities, and owned energy contracts build a formidable moat. And the competitive pressure forces every other player to respond — whether they’re ready to or not.

For technology professionals, a few specific steps are worth your time right now:

1. Track Frontier’s deployment timeline to anticipate shifts in Azure AI pricing and capabilities

2. Evaluate your AI infrastructure dependencies and consider spreading across providers before you need to

3. Monitor custom chip performance benchmarks as Maia competes directly with NVIDIA’s offerings

4. Watch energy market developments — AI compute demand is genuinely reshaping power generation investment

5. Assess regulatory developments that could constrain vertical integration across the AI infrastructure stack

So, is this bet going to pay off? Mostly, I think yes — but the path won’t be clean. The Microsoft Frontier Company AI infrastructure investment strategy will shape the AI field for the next decade. Whether you’re building AI applications, investing in tech stocks, or planning enterprise infrastructure, this $100 billion commitment demands your serious attention. Don’t sleep on it.

FAQ

What exactly is Microsoft Frontier Company?

Microsoft Frontier is a dedicated entity focused on building and operating AI-specific compute infrastructure. It separates AI training and inference workloads from Microsoft’s traditional Azure cloud services. Importantly, Frontier represents Microsoft’s commitment to owning — rather than renting — the compute needed for advanced AI development. The Microsoft Frontier Company AI infrastructure investment strategy covers custom chip design, data center construction, and long-term energy procurement. It’s a standalone mandate, not just a budget category.

How does the $100 billion investment compare to competitors’ spending?

Microsoft’s commitment is the largest single AI infrastructure investment announced by any company. Meta plans roughly $35–40 billion annually on AI infrastructure. Amazon’s AWS is spending approximately $75 billion per year, and Google invests around $50 billion annually. However, Microsoft’s figure represents a multi-year total, which makes direct annual comparisons somewhat complex. Nevertheless, the scale is genuinely unprecedented — there’s no honest comparison that makes it look small.

Will Microsoft Frontier replace Azure for AI workloads?

Frontier won’t replace Azure. Instead, it complements Azure by providing dedicated, high-performance compute specifically built for AI training and large-scale inference. Azure will continue serving commercial cloud customers as it always has. Frontier’s capacity will primarily support Microsoft’s own AI products, OpenAI’s model training, and select enterprise partnerships. The two platforms will likely share some infrastructure but serve meaningfully different purposes — think of it as a specialist unit alongside the general practice.

How do Microsoft’s custom Maia chips compare to NVIDIA GPUs?

Microsoft’s Maia AI accelerators are purpose-built for specific AI workloads — transformer-based model training and inference, specifically. NVIDIA’s GPUs, particularly the H100 and B200 series, remain the industry standard with broader software ecosystem support through CUDA. Maia chips offer Microsoft real cost advantages and supply chain independence, which is the point. However, they currently lack NVIDIA’s mature software stack and developer community — and that gap matters more than the hardware specs in the short term. Performance benchmarks remain limited as Maia deployment scales up, so the jury is genuinely still out.

What are the biggest risks to Microsoft Frontier Company AI infrastructure investment strategy?

The primary risks include execution challenges at unprecedented scale, technology risk with unproven custom chips, potential demand shifts if AI compute requirements drop through algorithmic improvements, regulatory scrutiny around vertical integration, and financial pressure from the sheer size of the capital commitment. Additionally, energy procurement at the required scale presents logistical and political challenges that shouldn’t be underestimated. Any combination of these factors could meaningfully affect Frontier’s success — and notably, several of them could hit simultaneously.

How will Frontier affect AI startups and smaller companies?

Frontier’s impact on smaller AI companies is genuinely mixed — and worth thinking through carefully. On one hand, improved Azure AI services could offer better pricing and performance for startups building on Microsoft’s platform. On the other hand, Microsoft Frontier Company AI infrastructure investment strategy concentrates compute power among fewer players than ever before. Startups without hyperscaler partnerships may face rising costs for GPU access and longer wait times. Consequently, many smaller companies are already shifting toward efficient AI approaches that require less raw compute — fine-tuning smaller models rather than training large ones from scratch. That’s not a bad outcome, but it’s a constrained one.

References

Claude for Drug Discovery: How AI Accelerates Molecular Screening With Claude

Claude for Drug Discovery

Claude for drug discovery is reshaping how pharmaceutical companies screen millions of molecular candidates. Anthropic’s model isn’t just a chatbot with a lab coat — it’s becoming a genuine, working tool in the drug development pipeline.

The pharmaceutical industry faces a brutal reality. Bringing one drug to market costs roughly $2.6 billion and takes over a decade. Most candidate molecules fail. How AI accelerates molecular screening matters because it compresses years of trial-and-error into weeks of computational analysis. Consequently, labs worldwide are rethinking their entire workflows around AI-powered screening — and doing it fast.

Anthropic recently launched Claude Science, positioning its model directly against competitors in computational biology. Meanwhile, OpenAI has forged biotech partnerships, and DeepSeek offers cost advantages in raw compute. Nevertheless, Claude’s architecture brings specific strengths to molecular screening that deserve a closer look. I’ve spent time digging into how these tools actually perform in research settings, and the differences are more meaningful than the marketing suggests.

Why Pharmaceutical Labs Choose Claude Over General-Purpose LLMs

Not all large language models handle scientific reasoning equally. General-purpose models often hallucinate chemical structures or misinterpret protein interaction data — and in drug discovery, that’s not just annoying, it’s expensive. Claude for drug discovery stands apart because Anthropic designed its scientific variant with domain-specific guardrails.

Accuracy in scientific reasoning. Claude Science shows stronger performance on chemistry and biology benchmarks compared to generic models. Specifically, it handles multi-step reasoning about molecular interactions without losing context midway through. This matters enormously when you’re evaluating how a compound might bind to a target protein across dozens of variables at once.

Constitutional AI reduces hallucination. Anthropic’s Constitutional AI approach trains Claude to acknowledge uncertainty rather than paper over it. In drug discovery, a confident-but-wrong prediction about toxicity could waste millions of dollars and months of lab time. Therefore, Claude’s tendency to flag low-confidence outputs actually makes it more trustworthy for pharmaceutical work — not less useful. This surprised me when I first looked at how it handles ambiguous biochemical data.

Here’s what makes Claude particularly valuable in lab settings:

  • Context window size — Claude can process entire research papers, patent filings, and molecular databases in a single prompt (200K tokens, to give you the actual number)
  • Structured output — It generates clean data tables, SMILES notation, and formatted reports without excessive formatting errors
  • Reasoning transparency — Researchers can trace Claude’s logic chain, which regulatory teams require for documentation
  • Safety alignment — Built-in safeguards prevent misuse in synthesizing dangerous compounds

Additionally, Claude’s pricing works better for academic labs running on tight grants. Although DeepSeek undercuts on raw inference costs, Claude’s accuracy per query often means fewer total queries needed. That efficiency gap adds up fast at scale — notably, it can mean the difference between a project staying in-budget or blowing past it.

How AI Accelerates Molecular Screening Through Specific Tasks

Understanding how AI accelerates molecular screening requires looking at the specific tasks Claude handles in the drug discovery pipeline. These aren’t hypothetical use cases — they’re workflows already running in pharmaceutical research labs right now.

Protein folding validation. After tools like AlphaFold predict a protein’s 3D structure, researchers need to validate those predictions against experimental data. Claude excels at cross-referencing predicted structures with crystallography databases, spotting discrepancies, and flagging regions where a prediction might be unreliable. Importantly, it can do this across hundreds of protein variants in minutes — work that would take a junior researcher weeks.

Compound toxicity prediction. One of the biggest bottlenecks in drug development is catching toxic compounds early, before they burn through wet-lab resources. Claude analyzes molecular structures and compares them against known toxicophores — structural features tied to toxicity. Furthermore, it evaluates ADMET properties (Absorption, Distribution, Metabolism, Excretion, and Toxicity) by reasoning across published literature rather than just pattern-matching.

Lead optimization. Once researchers identify a promising compound, the real work begins. That means tweaking the molecular structure to improve potency, reduce side effects, and enhance bioavailability. Claude suggests modifications based on structure-activity relationships (SARs) drawn from large chemical databases. Fair warning: this works best when your input data is clean and well-structured.

Literature synthesis. Drug discovery teams drown in published research — thousands of papers per therapeutic area. Claude pulls together findings from that volume of literature, identifying contradictions and consensus positions. Notably, this saves researchers weeks of manual review per project, which is time better spent on actual science.

Target identification. Before screening begins, teams must identify which biological target to pursue. Claude helps by analyzing gene expression data, disease pathways, and existing drug mechanisms. Consequently, it narrows the target list before expensive wet-lab experiments begin — arguably the highest-leverage place to use it.

The cumulative effect is striking. Each task Claude handles represents days or weeks saved. Moreover, the quality of AI-assisted analysis often matches or exceeds junior researcher output on routine screening tasks. I’ve tested several of these workflows firsthand, and the time savings on literature synthesis alone are genuinely impressive.

Claude Versus Competitors in Computational Biology

The race to dominate AI-powered drug discovery is heating up. Claude for drug discovery competes directly with several platforms. Here’s how they compare across key dimensions:

Feature Claude Science OpenAI (GPT-4) DeepSeek Google DeepMind
Scientific reasoning accuracy High Moderate-High Moderate High
Cost per million tokens Moderate High Low Moderate
Protein structure analysis Strong Moderate Moderate Very Strong (AlphaFold)
Toxicity prediction Strong Moderate Limited Moderate
Context window 200K tokens 128K tokens 128K tokens 1M+ tokens
Safety alignment Very Strong Strong Limited Strong
API availability for labs Yes Yes Yes Limited
Regulatory documentation support Strong Moderate Weak Moderate

Several patterns emerge from this comparison. Similarly to Google DeepMind, Claude puts scientific accuracy ahead of raw speed. However, Claude’s real advantage lies in reasoning transparency and safety features — both critical for regulated industries where you can’t just shrug at a black-box output.

OpenAI’s partnerships with biotech firms give GPT-4 access to proprietary training data. That’s a genuine competitive edge, and I don’t want to gloss over it. Anthropic has countered, however, by making Claude’s outputs more auditable. Pharmaceutical companies operating under FDA guidelines need clear documentation trails, and Claude provides that naturally — it’s baked into the design.

DeepSeek offers the lowest cost per query. For academic labs running millions of screening computations, that price difference adds up to real money. Nevertheless, DeepSeek’s weaker safety alignment and limited toxicity prediction capabilities make it genuinely risky for clinical-stage work. Cheap is only cheap until a false positive costs you $500K in wasted synthesis.

Google DeepMind remains the gold standard for protein structure prediction through AlphaFold. Yet it doesn’t offer the same general-purpose reasoning capabilities. Therefore, many labs use AlphaFold for structure prediction and Claude for drug discovery tasks that require broader scientific reasoning across multiple data sources. The combination is more powerful than either tool alone.

The Infrastructure Story Behind AI-Accelerated Screening

Understanding how AI accelerates molecular screening also means understanding the compute infrastructure that makes it possible. This is where the story gets technical — and financially significant. Bear with me, because this part matters more than most people realize.

Sparse attention mechanisms. Traditional transformer models process every token against every other token. That’s computationally expensive — costs scale quadratically, which is a problem when you’re processing large compound libraries. Claude uses optimized attention patterns that focus processing power on the most relevant parts of the input. For molecular screening, this means Claude can analyze large compound libraries without compute costs spiraling out of control.

Compute rationing strategies. Anthropic has set up intelligent batching for scientific workloads. When a pharmaceutical lab submits thousands of molecular queries, Claude’s infrastructure groups similar computations together, cutting redundant processing. Additionally, labs pay for useful computation rather than overhead — which sounds obvious but isn’t standard across providers.

Why does infrastructure efficiency matter for drug discovery? Consider the numbers:

1. A typical high-throughput screening campaign evaluates 1–2 million compounds

2. Each compound requires toxicity assessment, binding affinity prediction, and ADMET profiling

3. Running these analyses on traditional compute clusters costs hundreds of thousands of dollars

4. Claude’s efficient architecture can cut that cost significantly while maintaining accuracy

Furthermore, Anthropic’s infrastructure choices align with a broader industry trend. Cloud providers like Amazon Web Services now offer specialized instances built for LLM inference. Labs can spin up Claude-powered screening pipelines without maintaining their own GPU clusters — which removes a meaningful barrier, particularly for smaller biotechs.

The cost-accuracy tradeoff. Every pharmaceutical company balances screening breadth against budget constraints. Cheaper models let you screen more compounds, but inaccurate models generate false positives that waste wet-lab resources. Specifically, a single false positive in lead optimization can cost $500,000 or more in wasted synthesis and testing. That’s the real kicker — the “savings” from a cheaper model can evaporate fast.

Claude’s positioning targets the sweet spot. It’s not the cheapest option, and it’s not the most expensive. Its accuracy-per-dollar ratio, however, makes it compelling for serious drug discovery programs. Consequently, mid-size pharmaceutical companies and well-funded biotechs are increasingly adopting Claude as their primary AI screening tool — and that adoption is accelerating.

Practical Implementation: Getting Started With Claude in Your Lab

Knowing that Claude for drug discovery works is one thing. Actually setting it up in a real research environment requires practical steps and, honestly, some patience. Here’s what labs need to consider.

Data preparation matters most. Claude performs best when fed well-structured molecular data. Use standard formats like SMILES strings, InChI keys, or SDF files. Clean your compound libraries before submitting them — garbage in, garbage out applies doubly to AI-powered screening. I’ve seen teams skip this step and wonder why their results are inconsistent.

Prompt engineering for chemistry. Generic prompts produce generic results. Effective molecular screening prompts should include:

  • The specific target protein and its known binding site characteristics
  • Desired drug-like properties (Lipinski’s Rule of Five parameters)
  • Known toxicophores to flag
  • The therapeutic area and any existing drugs in the class
  • Output format specifications (structured tables, ranked lists)

Validation workflows. Never trust AI output without validation — full stop. Set up a protocol where Claude’s predictions feed into a verification pipeline. Cross-reference toxicity predictions against databases like PubChem. Compare binding affinity estimates with molecular dynamics simulations. Importantly, document every validation step for regulatory purposes. This isn’t optional.

Team training. Medicinal chemists and biologists need training on how to work with Claude effectively. This isn’t about learning to code — it’s about understanding what questions to ask and how to read probabilistic outputs. Moreover, teams should set standard operating procedures for AI-assisted screening before they’re in the middle of a time-sensitive campaign.

Integration with existing tools. Claude works best as part of a larger computational pipeline. Connect it with molecular visualization tools, docking software like AutoDock, and electronic lab notebooks. Many labs use the Claude API to build custom integrations that fit their existing workflows rather than forcing a process change. That flexibility matters.

Regulatory awareness. The FDA hasn’t issued definitive guidance on AI-assisted drug discovery yet. The agency’s framework for AI in healthcare is evolving quickly, however. Labs should maintain detailed logs of all AI-assisted decisions, because that documentation will pay off during regulatory submissions. Start building those habits now, not after your first submission.

The most successful implementations start small. Pick one screening campaign, run it through Claude alongside your traditional workflow, and compare results. Specifically, track false positive rates, time savings, and cost differences. That data will justify broader adoption far more convincingly than any vendor pitch.

Conclusion

Claude for drug discovery: how AI accelerates molecular screening isn’t just a promising concept anymore. It’s an operational reality in pharmaceutical labs worldwide. Anthropic’s focused approach to scientific AI — combining reasoning accuracy, safety alignment, and infrastructure efficiency — has carved out a meaningful niche in computational biology. And it’s only getting more capable.

The key takeaways are clear. Claude handles specific molecular tasks like toxicity prediction, protein folding validation, and lead optimization with remarkable competence. Its cost-accuracy balance outperforms both cheaper alternatives and more expensive general-purpose models. Furthermore, its transparency features align with regulatory requirements that other AI tools struggle to meet — and that alignment isn’t accidental.

For teams considering adoption, here are actionable next steps:

1. Start with a pilot project — Choose one compound library and run parallel analyses with Claude and your current methods

2. Invest in prompt engineering — Train your medicinal chemists to write effective scientific prompts

3. Build validation pipelines — Never skip the verification step, regardless of how confident Claude’s predictions appear

4. Document everything — Create audit trails that will satisfy future regulatory scrutiny

5. Monitor the competitive field — Anthropic, OpenAI, and DeepMind are all iterating rapidly; what’s true today shifts in six months

Bottom line: Claude for drug discovery represents a fundamental shift in how we approach molecular screening. The labs that adopt these tools thoughtfully — not blindly — will gain a significant competitive advantage in bringing life-saving drugs to market faster. That’s not hype. That’s what the data shows.

FAQ

How does Claude for drug discovery differ from traditional computational screening methods?

Traditional methods like molecular docking and quantitative structure-activity relationship (QSAR) models follow rigid, predefined rules. Claude for drug discovery adds a reasoning layer on top — it pulls together information across literature, databases, and structural data at the same time. Consequently, it catches patterns that rule-based systems miss entirely. However, it works best alongside traditional methods rather than replacing them. Think of it as a very capable collaborator, not a replacement for your existing stack.

Can Claude accurately predict drug toxicity?

Claude shows strong performance in identifying known toxicophores and flagging potential ADMET issues. Nevertheless, it shouldn’t be your only toxicity assessment tool — and anyone who tells you otherwise is overselling it. It excels at early-stage filtering, removing obviously problematic compounds before expensive in vitro testing begins. Importantly, all AI toxicity predictions require experimental validation before advancing to clinical stages. No exceptions.

What molecular data formats does Claude accept for screening workflows?

Claude processes text-based molecular representations effectively. SMILES strings, InChI keys, and text descriptions of molecular properties all work well. For more complex structural data, labs typically preprocess SDF or PDB files into text summaries before feeding them to Claude. Additionally, Claude can read tabular data containing molecular descriptors, assay results, and pharmacological parameters — which makes it flexible enough to slot into most existing data pipelines.

Is Claude suitable for academic labs with limited budgets?

Yes, although with caveats. Claude’s API pricing is moderate compared to competitors. Academic labs can reduce costs by batching queries, trimming prompt length, and focusing Claude on high-value reasoning tasks rather than simple data retrieval. Specifically, using Claude for lead optimization and literature synthesis — where its reasoning capabilities genuinely shine — provides the best return on investment for budget-constrained teams. Start with a small pilot before committing significant compute budget.

What regulatory considerations apply when using AI like Claude in drug discovery?

Regulatory frameworks for AI in drug discovery are still evolving — importantly, faster than most labs realize. The FDA encourages innovation but expects thorough documentation, and that expectation is hardening. Labs should maintain complete logs of AI-assisted decisions, including prompts, outputs, and validation results. Moreover, any AI-generated insight that influences clinical decisions must be independently verified through established experimental methods. Building these documentation habits now will smooth the regulatory path later. Heads up: this is one area where cutting corners early creates serious problems downstream.

References

Robot-as-a-Service Explained: Why Renting a Robot Is Smarter

Robot-as-a-Service

The concept of robot-as-a-service explained why renting robot smarter than buying has genuinely reshaped how companies approach automation. Five years ago, deploying a robot meant writing a six-figure check and crossing your fingers. Today, you can subscribe to one like software — and that shift changes everything about how you think about the economics.

Robot-as-a-Service (RaaS) lets businesses rent robots on monthly or annual subscriptions. You pay for outcomes, not hardware. For most companies, this model dramatically lowers risk, speeds up ROI, and eliminates painful capital expenditure. The math, however, isn’t always obvious at first glance. This piece breaks down the financial analysis, real case studies, and a decision matrix so you can figure out the smartest path for your specific operation.

The Financial Case: Capital Expenditure vs. RaaS Subscriptions

Understanding robot-as-a-service explained why renting robot smarter starts with the numbers — specifically, the ones most vendors don’t put on the front page of their brochure. Buying an industrial robot involves far more than the sticker price. Consequently, many companies badly underestimate the true cost of ownership, and I’ve watched this mistake play out more times than I can count.

Upfront costs of buying a robot typically include:

  • Robot hardware: $50,000–$400,000 per unit
  • Integration and programming: $30,000–$100,000
  • Safety infrastructure: $10,000–$50,000
  • Operator training: $5,000–$15,000
  • Ongoing maintenance contracts: 8–12% of purchase price annually

A single robotic arm for welding might cost $150,000 to purchase. Add integration, safety cages, and training, and you’re looking at $250,000 before the robot does its first weld. Furthermore, that robot depreciates on your balance sheet over five to seven years — not exactly a fun conversation with your CFO.

Meanwhile, a RaaS subscription for the same capability might run $3,000–$8,000 per month. That covers hardware, software updates, maintenance, and often technical support. Specifically, companies like Formic offer pay-per-hour pricing where you only pay when the robot is actually working. That model alone surprised me when I first dug into it.

Here’s a simplified five-year comparison:

Cost Factor Buying Outright RaaS Subscription
Year 1 total cost $250,000 $72,000
Year 2 total cost $18,000 (maintenance) $72,000
Year 3 total cost $18,000 (maintenance) $72,000
Year 4 total cost $35,000 (maintenance + upgrades) $72,000
Year 5 total cost $18,000 (maintenance) $72,000
Five-year total $339,000 $360,000
Break-even point ~47 months Immediate value
Technology refresh None (aging hardware) Included
Cash flow impact Severe Year 1 hit Predictable monthly

At first glance, buying looks cheaper over five years. However, this comparison quietly ignores several critical factors. The purchased robot becomes outdated, you bear all repair risk, and that $250,000 upfront cost carries a real opportunity cost. Had you invested that capital elsewhere — even at a modest return — the gap narrows significantly. And that’s before you account for the stress of an unexpected breakdown eating into your margins.

Additionally, the RaaS model typically includes technology upgrades as standard. Your rented robot gets better over time. Your purchased robot doesn’t. Therefore, the true total cost of ownership almost always favors renting a robot for businesses without dedicated robotics teams — which, honestly, is most businesses.

ROI Timelines and Break-Even Analysis for RaaS

ROI timelines dominate boardroom discussions about robotas-a-service explained why renting robot smarter. Executives want to know one thing: when does this actually pay for itself?

For purchased robots, the typical ROI timeline looks like this:

1. Months 1–6: Installation, integration, debugging, and staff training

2. Months 7–12: Ramp-up period with only partial productivity gains

3. Months 13–24: Full productivity, but still digging out from the initial investment

4. Months 25–48: True ROI starts accumulating

5. Months 49+: Robot may need significant upgrades or outright replacement

Most purchased industrial robots don’t deliver positive ROI until month 30–40. That’s nearly three years of waiting. Notably, the International Federation of Robotics reports that robot lifespans average 12–15 years. However, technology cycles now move much faster than hardware lifespans — so you’re often stuck with capable-but-dated equipment well before the machine actually dies.

For RaaS deployments, the timeline compresses dramatically:

1. Weeks 1–4: Deployment and calibration (vendor-managed, not your headache)

2. Months 2–3: Full productivity with measurable output gains

3. Month 4+: Positive ROI already accumulating

The difference is stark. RaaS customers often see positive ROI within 90 days because there’s no massive upfront investment to recover. Consequently, the break-even calculation fundamentally changes — and that’s the real kicker when you’re presenting this to a skeptical leadership team.

Here’s a practical example. Suppose a warehouse operation spends $22 per hour on manual labor for a picking task. A RaaS robot handles the same task for $8 per hour — subscription cost amortized. That’s $14 per hour saved. Running one shift of eight hours daily, five days a week, the savings hit $29,120 in the first year alone. Moreover, the robot doesn’t call in sick, take breaks, or file workers’ compensation claims. Fair warning: I know that sounds almost too clean, but the math holds up in real deployments I’ve followed closely.

Similarly, manufacturing companies report 30–50% productivity gains when deploying collaborative robots through RaaS programs. The key insight: renting a robot smarter aligns costs with revenue generation from day one — not month 30.

Case Studies: RaaS Wins in Manufacturing and Warehousing

Real-world examples make the case for robot-as-a-service explained why renting robot smarter far more convincingly than any spreadsheet can. So let’s look at what’s actually happened.

Manufacturing: Small Metalworks Shop in Ohio

A 45-person metal fabrication shop needed to automate welding to compete with larger rivals. Buying a welding cobot would have cost $180,000 upfront — a number that would’ve wiped out their operating cushion. Instead, they partnered with Formic on a RaaS contract at $2,100 per month. Within six weeks, the robot was operational. The shop redirected its two most skilled welders to complex custom jobs, and output increased 35%. Importantly, the company avoided taking on debt or draining cash reserves. After 18 months, they added a second robot under the same model. No drama, no scramble for capital.

Warehouse Automation: Mid-Size E-Commerce Fulfillment

A fulfillment center processing 8,000 orders daily explored autonomous mobile robots (AMRs) for picking operations. Purchasing a fleet of 15 AMRs from a vendor like Locus Robotics would have required roughly $750,000 plus integration costs. Instead, they chose a RaaS subscription. The robots deployed in under three weeks, pick rates jumped 2.5x, and seasonal scaling became effortless — they added robots during holiday peaks and scaled back down in January. That flexibility alone is worth a serious conversation.

Food Processing: Palletizing Line in Texas

A food manufacturer needed palletizing automation but faced genuinely uncertain demand due to a pending retail contract. Buying a palletizing system represented too much risk. Nevertheless, they couldn’t afford to lose the contract by relying solely on manual labor — a classic no-win situation. A RaaS palletizer solved the dilemma. Monthly costs stayed predictable, and when the retail contract came through, they scaled up immediately. Had it fallen through, they could have returned the robot with minimal penalty. The model absorbed business uncertainty that ownership never could.

These cases share a common thread. Each company needed automation but couldn’t justify — or afford — the capital expenditure, and RaaS removed that barrier entirely. Alternatively, each could have waited years to save enough capital, losing competitive ground in the process. I’ve seen that happen too, and it’s painful to watch.

When Buying Still Makes Sense: A Decision Matrix

Although robot-as-a-service explained why renting robot smarter holds true for most businesses, buying isn’t always the wrong call. Certain conditions genuinely favor capital purchase over subscription — and I’d be doing you a disservice if I didn’t lay those out honestly.

You should consider buying when:

  • Your application is highly specialized and won’t meaningfully change for 7+ years
  • You have in-house robotics engineering talent for maintenance and programming
  • Production volume is extremely high and consistent year-round
  • You’ve already amortized similar equipment successfully before
  • Tax benefits of capital depreciation outweigh subscription deductions in your situation
  • You operate in a regulated industry requiring full hardware ownership and control

You should lean toward RaaS when:

  • You’re deploying robots for the first time (seriously, don’t skip this one)
  • Cash flow predictability matters more than long-term cost minimization
  • Your production needs fluctuate seasonally
  • You lack in-house robotics expertise — and most companies do
  • Technology evolution matters and you want the latest capabilities
  • You need to prove ROI before committing larger budgets

The National Institute of Standards and Technology (NIST) provides solid frameworks for evaluating robotic systems in industrial settings. Their guidance can help you assess technical requirements before you even touch the financial model — worth bookmarking.

Decision matrix summary:

Factor Favors Buying Favors RaaS
Upfront capital available Yes No
In-house robotics team Yes No
Application stability (7+ years) High Low/uncertain
Seasonal demand variation Minimal Significant
Technology refresh needs Low High
First-time automation No Yes
Risk tolerance High Low
Time to deployment Flexible Urgent

Score yourself across these eight factors. If five or more favor RaaS, renting a robot smarter aligns with your situation. Conversely, if most factors favor buying, ownership might genuinely deliver better long-term value. No shame in that — just be honest about where you actually land.

The Hidden Advantages of RaaS Most Companies Overlook

Beyond the obvious financial benefits, the robot-as-a-service explained why renting robot smarter argument includes several underappreciated advantages that rarely show up in vendor pitch decks. These are the ones I find myself talking about most.

Reduced technology risk. Robotics evolves rapidly — faster than most industries realize. A robot you buy today may be outperformed by next year’s model. RaaS providers absorb that obsolescence risk entirely. Specifically, companies like Amazon Robotics continuously upgrade their fleet capabilities. RaaS customers benefit from similar upgrade cycles without repurchasing hardware. I’ve tested dozens of automation setups over the years, and the technology gap between a three-year-old owned system and a current RaaS deployment can be genuinely jarring.

Simplified compliance and safety. Robot safety standards like ISO 10218 and ISO/TS 15066 require ongoing compliance — and they do get updated. When you own a robot, compliance is your responsibility. Under RaaS, the provider typically handles safety certifications, risk assessments, and regulatory updates. That’s a significant hidden cost eliminated. Moreover, it’s one less thing keeping your operations manager up at night.

Workforce transition support. Most RaaS providers include training as part of the subscription, so your team learns to work alongside robots without a separate training budget line. Furthermore, that support continues as the technology updates. You don’t train once and hope for the best — which, in my experience, is exactly what happens with purchased systems.

Data and analytics. Modern RaaS platforms generate operational data that purchased robots often don’t produce out of the box. You get dashboards showing throughput, error rates, downtime, and optimization opportunities. The data layer alone can justify the subscription for operationally-minded teams.

Insurance and liability simplification. Owning a robot means insuring it, valuing it, and worrying about it. A RaaS subscription typically bundles insurance into the monthly fee. Additionally, liability for hardware failures often falls on the provider, not you. That’s a genuinely underrated benefit.

These hidden advantages compound over time. They’re hard to put in a spreadsheet but easy to feel in daily operations. Importantly, they explain why the RaaS market is projected to grow substantially through 2030, according to analysis from McKinsey & Company. The companies catching on now are building a real operational advantage.

Conclusion

The case for robot-as-a-service explained why renting robot smarter than buying rests on hard financial logic — not hype. Lower upfront costs, faster ROI, predictable cash flow, and built-in technology upgrades make RaaS the stronger choice for most businesses entering automation. Nevertheless, buying still makes sense for companies with deep robotics expertise, stable long-term applications, and available capital. Know which camp you’re actually in before you sign anything.

Here are your actionable next steps:

1. Audit your current manual processes and identify the top three candidates for robotic automation

2. Request RaaS quotes from at least two providers for your specific use case

3. Run a five-year total cost comparison using the framework in this article

4. Score your situation against the decision matrix to confirm whether renting or buying fits better

5. Start with a single pilot deployment — RaaS makes this nearly risk-free

6. Measure results for 90 days before scaling

The beauty of the RaaS model is that you don’t need to get it perfect on day one. Start small, prove value, and expand. That flexibility alone makes renting a robot smarter than buying for the vast majority of businesses entering the automation era — and frankly, it’s the approach I’d take if it were my capital on the line.

FAQ

What exactly is Robot-as-a-Service (RaaS)?

RaaS is a subscription model where businesses rent robots instead of purchasing them outright. Monthly fees typically cover the robot hardware, software, maintenance, updates, and technical support. It works similarly to Software-as-a-Service (SaaS), but with physical machines you can actually trip over in your warehouse. The model makes robot-as-a-service explained why renting robot smarter a practical reality for companies of all sizes — not just enterprises with deep pockets.

How much does a typical RaaS subscription cost per month?

Costs vary widely based on robot type and application. Simple collaborative robots for basic tasks might run $1,500–$3,000 monthly, while complex industrial systems can reach $5,000–$15,000 per month. Some providers offer pay-per-hour or pay-per-pick pricing instead, which can work out even better for variable-volume operations. Specifically, warehouse AMRs often fall in the $2,000–$5,000 monthly range per unit — worth getting a few quotes to see what’s realistic for your use case.

Can I scale my robot fleet up or down with RaaS?

Yes — and this is honestly one of the biggest advantages. Most RaaS contracts let you add or remove robots based on demand, which is particularly valuable for seasonal businesses. You might run 20 robots during holiday peaks and scale back to 8 in slower months. Consequently, you only pay for what you actually need, rather than carrying idle hardware through your quiet season.

What happens if a rented robot breaks down?

The RaaS provider handles repairs and maintenance — that’s their problem, not yours. Most contracts include service level agreements (SLAs) guaranteeing response times, often within 24 hours, and some providers keep spare units on standby for immediate swaps. You don’t bear the repair cost or the burden of tracking down qualified technicians at 2am. This is a major reason why renting a robot smarter appeals to companies without dedicated technical staff — which, notably, is most small and mid-size operations.

Are there long-term contracts, or can I cancel anytime?

Contract terms vary by provider. Some offer month-to-month agreements, while others require 12–36 month commitments, with longer terms usually carrying lower monthly rates. Although early termination fees may apply, they’re typically far less painful than being stuck with a $200,000 robot you no longer need. Quick note: always negotiate exit terms before signing — it’s the clause most people skip and later regret.

Will RaaS robots integrate with my existing systems?

Most RaaS providers handle integration as part of the deployment, connecting the robot to your warehouse management system (WMS), manufacturing execution system (MES), or enterprise resource planning (ERP) platform. Moreover, integration support is usually ongoing throughout the subscription — so if your systems change, the provider adjusts the robot’s configuration accordingly. That ongoing support is something purchased systems almost never include after the initial setup.

References