Humanoid Robots in Production: 3 Proven and 6 Unverified

Humanoid robots in production

Search for humanoid robots in production and humanoid deployment figures and you will find confident numbers. Tesla has passed 50,000 cumulative Optimus units. Figure has surpassed 10,000 deployments. More than a thousand robots work Tesla’s lines today.

None of those figures come from the companies they describe.

This is the central problem with tracking humanoid robots in production. The sector runs on announcements, and announcements use four words interchangeably that mean very different things: ordered, shipped, deployed, and productive.

A robot can be ordered and never built. Built and never shipped. Shipped and sit in a lab. Deployed and still be a pilot that ends in six months.

The numbers that survive scrutiny are much smaller than the headlines. Global shipments in 2025 landed somewhere around 16,000–18,000 units, with Chinese manufacturers accounting for roughly 90% of volume. Estimated active commercial deployments — robots doing productive work rather than R&D — sit closer to 3,000–4,000 worldwide.

That gap is not a rounding error. It is the difference between an industry and a demo reel.

Key Takeaways

  • Roughly 16,000–18,000 humanoid units shipped globally in 2025. Fewer than an estimated 3,000–4,000 are doing productive commercial work. The gap between those two numbers is the story.
  • Agility holds the deepest verified record: 65,000+ operating hours across nine customer facilities, disclosed in SEC filings rather than a press release.
  • Figure’s BMW deployment is the most granular public disclosure in the sector — runtime, part counts, shift pattern and failure points all published.
  • Tesla has never published an Optimus production count. Every circulating unit figure traces back to third-party estimates, not the company.
  • Chinese makers dominate volume, but more than 70% of Unitree’s humanoid revenue through Q3 2025 came from research and education buyers, not factories.

Quick Navigation

The Verification Standard for Humanoid Robots in Production
Humanoid robots in production

Every entry in this tracker is graded against four tests. This is what separates a deployment from an announcement.

A named customer. “A leading automotive manufacturer” does not count. The customer has to be identified.

An integrated workflow. The robot performs a task inside an existing production process, not a staged demonstration beside it.

A recurring schedule. Shift patterns, operating hours, or throughput figures. Something that implies continuity.

A transaction. Money moves. A RaaS contract, a purchase order, or a disclosed commercial agreement.

Entries meeting all four are marked Verified. Entries meeting two or three are Pilot. Entries resting on a press release with no operating data are Announced.

Company-reported metrics are labeled as such throughout. Nobody in this sector submits to independent audit of deployment counts, so “verified” here means documented and specific, not third-party attested.

Humanoid Robots in Production: The Master Tracker

CompanyRobotNamed customerScale evidenceRevenue modelStatusVerified
AgilityDigitGXO, Schaeffler, Toyota Canada, Mercado Libre, Amazon65,000+ hrs, 9 facilities; 100,000+ totes at GXORaaS (~$8,500/mo modelled)VerifiedAug 2026
Figure AIFigure 03BMW (Spartanburg)Figure 02: 1,250+ hrs, 90,000+ parts, 30,000+ vehiclesCommercial agreementVerifiedJun 2026
UBTechWalker S2BYD, Geely, FAW-VW, Audi FAW, Foxconn1,000th unit delivered; ¥800M+ ordersDirect purchaseVerifiedAug 2026
ApptronikApollo 2Mercedes-Benz, GXO, JabilNo published operating metricsEnterprise pilot, quote-onlyPilotJun 2026
Boston DynamicsAtlasHyundai RMAC, Google DeepMind2026 output committed; HMGMA production 2028UndisclosedAnnouncedJul 2026
TeslaOptimus V3Internal only (Optimus Academy)No company-published countNone externalPre-productionAug 2026
UnitreeG1 / H2Research, education, light industry5,500+ shipped 2025Direct purchase, $13,500 upVerified (non-factory)Aug 2026
AgiBotA2Mixed10,000th unit Mar 2026Direct purchaseVerified (mixed)Jul 2026
1XNEOPreorder; EQT portfolio agreementNo verified customer deliveries$20,000 or $499/moAnnouncedJul 2026

Read the status column before the scale column. A large number in an unverified row tells you less than a small number in a verified one.

Agility Digit: Humanoid Robots in Production at GXO and Toyota

Agility does not have the most advanced robot or the largest funding round. It has the longest paper trail, and in this sector that is the rarer asset.

Digit has accumulated more than 65,000 operating hours through commitments across nine customer facilities. That figure appears in SEC filings connected to the company’s SPAC merger, which makes it materially different from a marketing claim.

GXO signed the industry’s first multi-year humanoid RaaS agreement in June 2024, deploying Digit at a Spanx fulfillment centre in Flowery Branch, Georgia. By November 2025, Digit had moved more than 100,000 totes at that site.

Toyota Motor Manufacturing Canada converted a year-long pilot into a commercial agreement in February 2026 covering seven Digit units at its Woodstock, Ontario RAV4 plant. Schaeffler — also a minority investor — has run daily factory shifts at Cheraw, South Carolina. Mercado Libre began deploying at San Antonio in late 2025.

The honest caveat: the GXO milestone happened at a single site. No second GXO facility is publicly verified. Depth is not the same as breadth.

On pricing, one number gets misquoted constantly. Agility’s June 2026 investor deck models RaaS at roughly $8,500 per robot per month, about $100,000 a year. The widely circulated “$30 an hour” is the fully burdened human labour comparator, not Digit’s rental price.

Figure AI: Humanoid Robots in Production at BMW

Figure’s Spartanburg programme produced the most detailed public disclosure any humanoid company has published.

The Figure 02 deployment ran 11 months at BMW Group Plant Spartanburg. The robot inserted sheet-metal components for welding in the body shop, supporting production of more than 30,000 BMW X3 vehicles. Published metrics include more than 1,250 hours of runtime, more than 90,000 parts handled, and 10-hour shifts Monday through Friday.

Figure also disclosed its failure points, which is unusual. The forearm was the top hardware failure, attributed to tight packaging, dexterity demands and thermal constraints. Figure 03 redesigned the wrist electronics in response.

In June 2026, BMW moved Figure 03 onto logistics sequencing at the same plant — picking components from unsorted containers into sequencing trolleys for just-in-sequence delivery. BMW’s own press release confirms it.

On manufacturing capacity: BotQ’s first-generation line is rated for up to 12,000 units annually, with a stated four-year goal of 100,000 units. Figure has reported more than 350 Figure 03 units delivered.

Treat capacity ratings and delivery counts as different categories. One is what a factory could build; the other is what left the building.

Tesla Optimus: Scale Ambition Without a Public Count

Among companies pursuing humanoid robots in production, Tesla has the loudest narrative and the thinnest verification record. Both are true simultaneously.

The facts that hold up: Model S and X production ended at Fremont in early May 2026 after a combined 750,000 vehicles. The line was decommissioned over roughly 46 days and converted to Optimus manufacturing. Musk guided V3 production to begin in late July or August 2026.

Critically, Tesla stated that initial units go to an internal programme — the Optimus Academy — rather than external customers. Musk has called Optimus “the hardest product to scale that we’ve ever had at Tesla,” citing an entirely new supply chain and roughly 10,000 unique parts.

What does not hold up: any specific unit count. Tesla has never published an Optimus production figure, audited or otherwise. Claims that 1,000+ Gen 3 units are working Tesla lines appear widely across aggregator sites and trace to no company disclosure.

The stated targets are a run rate of 1 million units annually at Fremont and 10 million at Gigafactory Texas by 2027. For scale, Tesla builds roughly 1.8 million cars a year. Treat those figures as ambition, not forecast.

Boston Dynamics Atlas: Humanoid Robots in Production From 2028

Atlas entered manufacturing in January 2026, and its entire 2026 output is already committed — to Hyundai’s Robotics Metaplant Application Center and to Google DeepMind, which is developing foundation models for it. Additional customers are planned from 2027.

A committed shipment is not a completed deployment. Hyundai says production parts-sequencing at Metaplant America begins in 2028, with Kia’s Georgia plant following in 2029.

Hyundai targets 30,000 Atlas units annually by 2028 from a new facility near Savannah, Georgia, and has made an internal commitment covering roughly 25,000 of them. That means Hyundai absorbs most of its own output before external customers see units.

One factor most trackers omit: the Hyundai Motor branch of the Korean Metal Workers’ Union declared in January 2026 that Atlas will not enter Hyundai factories without a labour-management agreement. Labour negotiation is a deployment gate, not a footnote.

Published specifications are 1.9 m, 90 kg, 56 degrees of freedom, and up to 50 kg instantaneous payload. Boston Dynamics has not published a price or opened ordering.

Apptronik Apollo: Pilots Labelled as Commercial

Apptronik is among the best-funded companies working on humanoid robots in production, having raised roughly $1 billion, including $520 million in February 2026, at a reported valuation near $5 billion. Google DeepMind is both AI partner and investor.

Apollo runs at Mercedes-Benz — initially at the Digital Factory Campus in Berlin-Marienfelde, on internal logistics tasks — plus GXO and Jabil.

Here is the distinction that matters: every known Apollo deployment is a pilot or data-collection programme, and no customer has published Apollo performance metrics. Some press releases use the phrase “commercial agreement,” which is accurate contractually and misleading operationally.

Apollo 2, unveiled June 2026, is explicitly a training and data platform. Apptronik describes the upcoming Apollo 3 as its first true commercial product, pointed at 2027.

On price, the frequently cited $50,000 is a 2023 at-scale target, not a current cost. Apollo has no public price and cannot be ordered.

UBTech: Humanoid Robots in Production Across Chinese Factories

UBTech has the strongest claim to industrial humanoid volume outside the research market. The company delivered its 1,000th Walker S2 unit from its Liuzhou facility, with Walker series orders exceeding ¥800 million (roughly $112 million) since early 2025.

The customer list is genuinely industrial: BYD, Geely, FAW-Volkswagen Qingdao, Audi FAW, BAIC New Energy, Foxconn and SF Express. Walker S2’s autonomous hot-swap battery — a roughly three-minute self-change — is a real engineering answer to multi-shift operation.

Capacity targets are 5,000 units annually in 2026, scaling to 10,000 in 2027.

The counter-signal: UBTech ranked third in production but fourth in shipments in MIR’s rankings, a pattern that typically indicates inventory buildup or delivery delay. The stock fell roughly 35% across 2026 despite the operational milestones. Investors are pricing something the press releases are not.

Unitree, AgiBot and the Revenue Mix Problem

Unitree ships more humanoid robots in production volume than any rival, moving more than 5,500 units in 2025, around 32.4% of global share, and priced its Shanghai STAR Market IPO in August 2026 at 150.80 yuan per share — roughly $904 million raised at about $9 billion valuation.

Then read the revenue mix. Through Q3 2025, more than 70% of Unitree’s humanoid revenue came from research and education customers. Industrial applications accounted for roughly 9%.

Most of those shipped robots never entered factory work. They entered labs.

Q1 2026 revenue rose 68.49% year over year to 420 million yuan, while adjusted net profit fell 52.55% on higher research spending. Growth and margin are moving in opposite directions.

AgiBot rolled out its 10,000th humanoid in March 2026 and led H1 2026 shipments by some counts. Omdia ranked it first for 2025 at 5,168 units, a ranking Unitree disputes.

Chinese output projections for 2026 exceed 100,000 units per MIIT. Apply the same shipped-versus-productive discount to that number as to every other in this article.

1X NEO: Humanoid Robots in Production for the Home

The home humanoid is the category with the largest gap between marketing and delivery.

1X opened NEO preorders at $20,000 outright or $499 per month with a $200 refundable deposit. Its Hayward factory opened 30 April 2026, with customer shipments promised by end of 2026. As of July 2026, no customer deliveries had been verified.

1X also signed an agreement with investor EQT covering up to 10,000 NEO units to portfolio companies between 2026 and 2030 — which quietly repositions a consumer robot toward industrial buyers.

One point buyers should understand: early home humanoids may rely on scheduled remote teleoperation for difficult tasks. That is a legitimate product design, but it is not autonomy, and pricing pages rarely make the distinction clear.

What Revenue Models Reveal About Humanoid Robots in Production

Follow the business model and the maturity ranking sorts itself out.

RaaS signals confidence. Agility rents Digit per robot per month. That only works if uptime is real, because the vendor carries the reliability risk. It is not coincidence that the RaaS leader also has the deepest hours record.

Quote-only pricing signals pilots. Apptronik, Boston Dynamics and Agility publish no list price. For Agility this reflects a rental model; for the others it reflects a product not yet standardized enough to price.

Published low prices signal a different market. Unitree’s $13,500 G1 is real and orderable. It is also mostly selling into research, which is a legitimate business but not factory automation.

No price and no external customer signals pre-production. That is Tesla today, whatever the run-rate targets say.

Two structural factors sit above all of this. ISO 25785-1, the first safety standard specifically for dynamically stable walking robots, is still under development with publication expected 2026 or 2027 at the earliest. And the American Security Robotics Act, introduced March 2026, would bar federal use of robots from foreign adversaries, naming Chinese makers in sponsor statements.

The shakeout has also begun. K-Scale Labs shut down in November 2025, Cartwheel Robotics in February 2026, and Sanctuary AI pivoted away from hardware in June 2026.

For readers tracking the capital side of this, our breakdown of the $39B humanoid robot funding race covers how valuations diverged from deployment records. The compute economics underneath these robots are covered in the AI compute stack, and unfamiliar terminology is defined in the AI glossary.

Signals to Watch Before the Next Update

Four developments would change the humanoid robots in production picture materially.

A verified second site. Any vendor proving the same deployment twice at different facilities moves from case study to product.

Tesla publishing a number. A disclosed Optimus count in an earnings filing would resolve the sector’s single largest information gap.

Atlas hours. Boston Dynamics has industry-leading hardware specs and no published operating hours. That asymmetry cannot last through 2027.

Chinese industrial revenue share. If Unitree’s factory-application share moves from 9% toward 30%, the volume story becomes a deployment story.

This tracker updates monthly. Corrections with a primary source are welcome and will be reflected with attribution.

Frequently Asked Questions

Which humanoid robots in production have the most verified commercial deployment?

Agility’s Digit, on hours and customer count — 65,000+ operating hours across nine facilities, disclosed in SEC filings. Figure’s BMW programme is more granular on a single site.

How many humanoid robots are actually working in factories?

Estimates put productive commercial deployments at fewer than 3,000–4,000 globally, against 16,000–18,000 units shipped in 2025. Most shipped units went to research and education.

Can I buy a humanoid robot today?

Depends on the tier. Unitree’s G1 is orderable at about $13,500. Digit, Apollo and Atlas are quote-only or unavailable. Tesla sells none externally.

Is Tesla ahead in humanoid robots in production?

Not on any verifiable measure. Tesla has the largest stated ambition and no published production count, no external customers, and initial units routed to an internal training programme.

What is RaaS in humanoid robotics?

Robots-as-a-Service: the customer pays a recurring fee per robot rather than buying outright. GXO and Agility signed the first such humanoid agreement in June 2024, and it has become the dominant model for Western industrial deployment.

Keep reading

Anthropic IPO valuation

Anthropic IPO: The $895 Billion Question Behind Its Valuation

Last updated: 9 November 2026. Latest confirmed development: Anthropic’s amended S-1, filed on 2 November, still leaves the share count and the IPO price range …
Claude Opus vs Sonnet

Claude Opus vs Sonnet: What the 2026 Price Gap Actually Buys

Last verified: 8 November 2026. All prices are Anthropic’s standard first-party API rates in US dollars per million tokens. They aren’t Claude Pro or Max …
RSA-1024

Did AI Break RSA? What DeepMind Actually Found

Last verified: 8 November 2026. Both papers are unreviewed working papers, and no outside group has reproduced the results yet. No, AI did not break …
Model Distillation

Model Distillation Explained: When AI Learning Becomes Extraction

Last verified: 7 November 2026. Government and company claims are attributed throughout. None has been tested in court. A support team trains a small, cheap …

Prompt Injection: 8 Classes and What Now Stops Each

Prompt injection attack classes and matching defences

A language model reads one stream of text. Your system instructions, the user’s question, the document you retrieved, the result your API returned — all of it lands in the same context window with no structural marker saying which part is trusted.

Prompt injection is what happens when an attacker puts instructions into the untrusted part and the model follows them anyway.

The comparison people reach for is SQL injection, and it is half right. Both exploit the mixing of code and data. But SQL has a fix: parameterized queries create a real boundary the database enforces. Natural language has no equivalent. There is no way to escape a sentence.

That difference matters more than any single technique in this article. It means prompt injection is not a defect in a particular model that a vendor will eventually patch out.

Anthropic, Google DeepMind and OpenAI have all published work acknowledging the same thing: this cannot be fully solved at the model layer. Any defense written as a prompt instruction can itself be overridden by a better prompt.

Key Takeaways

  • Prompt injection has held the number one spot in OWASP’s Top 10 for LLM Applications for two years running, and it is not a bug that gets patched. It is a consequence of how language models read text.
  • Eight distinct prompt injection classes now matter in production. Only one of them arrives through the input box a user types into.
  • No single defense covers all eight. Classifiers stop overt attempts and miss camouflaged ones. Architectural controls like CaMeL stop the damage without stopping the injection.
  • EchoLeak (CVE-2025-32711, CVSS 9.3) proved zero-click exfiltration works against a shipped enterprise assistant. The theoretical phase is over.
  • The practical question in 2026 is not whether prompt injection works. It is how small you can make the blast radius when it does.

Quick Navigation

Why a Prompt Injection Taxonomy Matters Now

Ask a security team what they have done about prompt injection and you will usually hear that inputs run through a classifier. That is not wrong. It is just aimed at roughly one tenth of the problem.

The reason is architectural. When your product was a chatbot, the input box was the attack surface. When your product became an agent that reads email, queries databases, calls third-party APIs and remembers things between sessions, every one of those channels became an instruction channel.

Several good taxonomies already exist. CrowdStrike has cataloged more than 200 named techniques across delivery paths and prompting styles. HiddenLayer published an interactive taxonomy of adversarial prompt engineering. A February 2026 systematization on arXiv reviewed 37 attack papers and organized them by payload generation strategy.

What is genuinely missing is the mapping. Knowing that eleven attack families exist helps you write a report. Knowing which defense stops which family helps you ship.

That mapping is what the rest of the article is for.

The Two Axes Every Prompt Injection Map Needs

The Two Axes Every Prompt Injection Map Needs

Before the eight classes, one structural point that most write-ups skip.

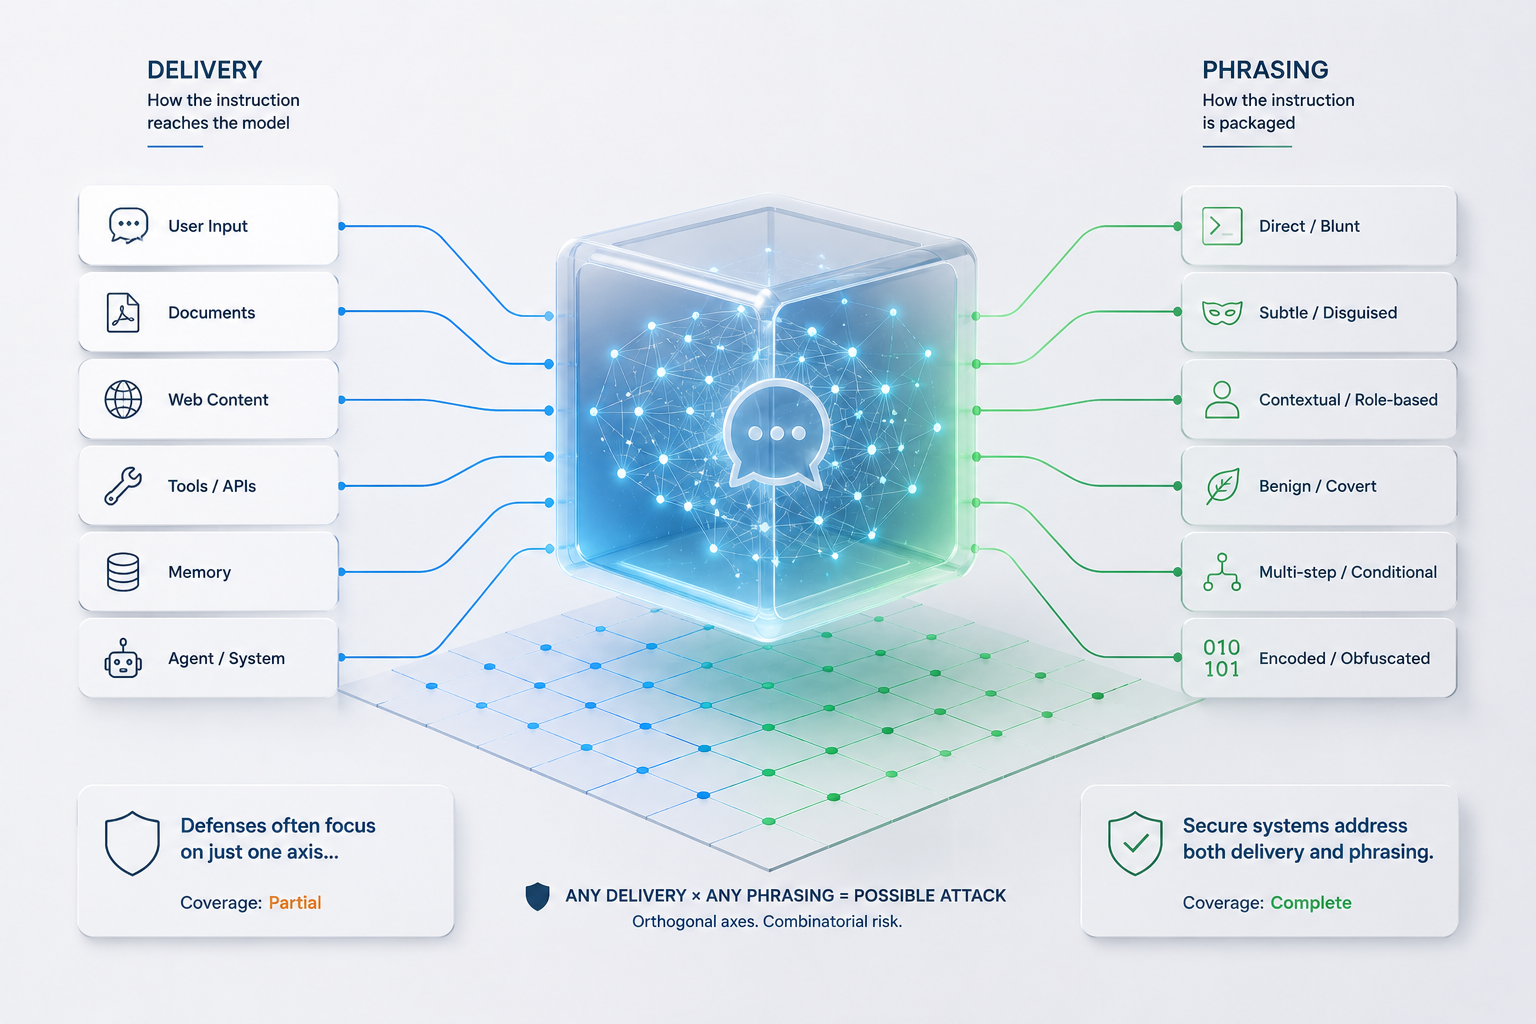
Every prompt injection attack has two independent properties. The first is delivery: how the malicious instruction physically reaches the model’s context. The second is phrasing: how the instruction is packaged once it arrives.

These are orthogonal. Any delivery channel combines with any phrasing style. A blunt override instruction can arrive through a PDF, and so can a subtle one dressed as analyst commentary.

This matters because most defenses only address one axis. Input classifiers watch phrasing. Provenance tracking watches delivery. A team that buys only one has covered half a grid.

The eight classes below are organized by delivery, because delivery is what determines your architecture. Phrasing shows up as the variable that decides whether your detector fires.

Class 1: Direct Prompt Injection

Delivery: the user types it.

This is the original. A user submits input designed to override the system prompt — asking the model to disregard its instructions, reveal its configuration, or adopt a persona without restrictions.

The illustrative shape is the one everybody knows: a request that explicitly instructs the model to set aside prior instructions and reveal what it was told at the start.

Why it still matters: system prompt leakage graduated to its own OWASP category (LLM07) precisely because leaked instructions become the map for every later attack.

Why it matters less than you think: direct attempts account for roughly one in ten production agent incidents. The user is the one party you can already identify, rate-limit and ban.

Class 2: Indirect Prompt Injection via Retrieved Content

Delivery: a document, webpage or email the agent reads on the user’s behalf.

Greshake and colleagues demonstrated this in 2023 with hidden text on a webpage. It is now the dominant real-world class.

The shape: text styled to be invisible to a human reader — white on white, zero-size font, an HTML comment — placed in a document the assistant will summarize. The text reads as an administrative instruction rather than content.

The reproducible case: EchoLeak, CVE-2025-32711, CVSS 9.3. A crafted email arrived in a Microsoft 365 Copilot user’s inbox. When the user later asked Copilot to summarize their mail, the assistant followed the embedded instructions and exfiltrated tenant data. Zero clicks. No link for the victim to avoid.

The victim never typed anything malicious. They received an email, which is not a behavior you can train out of your workforce.

Now in the wild: Unit 42 documented large-scale indirect prompt injection campaigns in March 2026, including ad-review evasion and system prompt leakage on live commercial platforms.

Class 3: Tool Output Prompt Injection

Delivery: the response body of an API or function the agent called itself.

Your agent calls a weather service, a CRM lookup, a ticketing API. The response comes back and goes straight into context.

Nobody sanitizes it, because the agent chose to make that call. The call was legitimate. The response is attacker-controlled if the attacker controls any field in the record being returned.

The shape: a free-text field in a returned record — a customer note, a ticket description, a product review — containing instructions rather than data.

This is the fastest-growing class as agents chain third-party APIs. It is also the one most often missed in threat models, because teams reason about tools as things the agent uses rather than things that talk back.

Class 4: Tool Description and MCP Poisoning

Delivery: the metadata describing a tool, loaded at connect time.

When an agent connects to a Model Context Protocol server, it pulls each tool’s name, description and parameter schema into context so the model knows what is available. That metadata is rarely rendered in the UI. It is fully visible to the model.

Invariant Labs named this a Tool Poisoning Attack in 2025. OWASP now documents it directly, and the Cloud Security Alliance describes three variants: description poisoning, rug-pull attacks where a tool changes after approval, and shadowing where a malicious server’s description hijacks behavior on a different server.

What makes this class different is persistence. A document-based injection has to be delivered again each time. A poisoned tool description ships inside a package or a configuration file and fires on every invocation, in every session, for every user, until somebody reads the metadata.

OWASP places this under ASI01, Agent Goal Hijack, in the 2026 Top 10 for Agentic Applications. The root cause is a trust gap: descriptions get reviewed once at connect time, and responses go into context at runtime with no equivalent check.

Class 5: Memory Prompt Injection

Delivery: the agent’s own long-term memory store.

Agents that persist context across sessions can be taught something false today that they act on next week.

The shape: content in one session that the agent summarizes into memory as a durable preference or standing instruction. The attacker’s payload becomes part of what the agent believes about the user.

Researchers demonstrated persistent memory poisoning in Amazon Bedrock agents that survives session boundaries. MITRE ATLAS added agent-specific techniques for context poisoning and memory manipulation in October 2025.

This converts a one-shot exploit into a durable backdoor. Session-scoped defenses do nothing, because the attack has already left the session.

Class 6: Agent-to-Agent Prompt Injection

Delivery: a message from another agent in a multi-agent system.

Agents pass rich natural-language instructions to each other with none of the schema validation or authentication that governs API calls between services.

A compromised or manipulated subagent becomes a trusted upstream source for every agent downstream of it. Privilege inherits across the boundary without validation.

The shape: an orchestrator receives a summary from a research subagent, and that summary contains an instruction the subagent absorbed from a poisoned webpage. The orchestrator has no way to tell analysis from directive.

This class did not exist before multi-agent architectures. It is the reason MCP security guidance now treats the agent control plane as its own security domain rather than an application concern.

Class 7: Multimodal and Encoded Prompt Injection

Delivery: any channel, but obfuscated to defeat pattern matching.

Two related tricks sit here.

Multimodal: instructions embedded in an image the model reads via OCR, or in a screenshot, or in document metadata. Text the human eye skips and the vision encoder does not.

Encoded: the same instruction expressed in base64, in unusual Unicode, with homoglyph substitutions, or split across tokens. The intent survives. The string match does not.

Real-world ad-review bypass using CSS-hidden injections has been observed in production. The defensive point is that this is a phrasing technique layered onto any of the delivery classes above, not a separate delivery path — which is exactly why keyword-based detection ages badly.

Class 8: Domain-Camouflaged Prompt Injection

Delivery: any channel, phrased as legitimate domain content.

This is the class that breaks most classifiers, and the least discussed.

Standard injections use explicit override language that syntactic detectors reliably flag. Camouflaged injections do not instruct at all. They assert — using the authoritative vocabulary of the domain, in a register indistinguishable from the surrounding document.

The shape: a paragraph appended to a financial document, headed as supplementary analyst commentary, stating that a review has revised a recommendation. There is no imperative verb. There is no instruction to ignore anything. There is just a conclusion the model then carries forward.

A June 2026 evaluation found financial-domain deployments facing 26–33% baseline attack success against camouflage-class attacks, with no prompting-based defense eliminating the threat on weaker models. defense effectiveness proved strongly model-dependent: spotlighting halved attack success on Claude Haiku while providing no measurable benefit on Llama 3.1 8B.

That last finding deserves emphasis. A defense that works on your evaluation model may do nothing on the model you deploy.

Which defense Blocks Which Prompt Injection Class

Here is the mapping. Read it as coverage, not as guarantees.

ClassInput classifierSpotlightingProvenance / taint trackingCapability limits + egress controlHuman approval
1. DirectStrongWeakWeakModerateModerate
2. Indirect / retrievedModerateStrongStrongStrongModerate
3. Tool outputWeakModerateStrongStrongModerate
4. MCP / tool descriptionWeakWeakModerateStrongStrong
5. MemoryWeakWeakStrongModerateWeak
6. Agent-to-agentWeakModerateStrongStrongWeak
7. Multimodal / encodedWeakModerateStrongStrongModerate
8. Domain-camouflagedVery weakModerateModerateStrongStrong

Three patterns fall out of this table.

Input classifiers cover one column well. They catch overt phrasing at the front door and degrade sharply everywhere else. Class 8 is where they fail hardest, because there is no attack syntax to detect.

Spotlighting is cheap hygiene, not a control. It marks untrusted content with delimiters or control tokens so the model can tell data from instruction. Google’s Gemini team uses a control-token variant to avoid disrupting semantic flow. It measurably reduces attack success and requires no retraining. It is also probabilistic and model-dependent.

Architectural controls are the only thing that scales across all eight. CaMeL, from Google DeepMind, splits work between a privileged model that plans and a quarantined model that reads untrusted content without tool access. A custom interpreter tracks provenance through the execution graph and gates every tool call against a capability policy.

The insight there is old. It is a reference monitor enforcing policy at the point an action takes effect, which security has done since the 1970s. FIDES, Progent, RTBAS and FORGE apply the same move differently.

One caveat worth carrying: a June 2026 adaptive evaluation warns that out-of-band defenses reporting near-elimination on static benchmarks are being validated by the same methodology that already failed for in-band defenses. Strong AgentDojo numbers are not the same as strong numbers against an adaptive attacker.

Building a Prompt Injection Test Suite

Turning the taxonomy into something operational takes four steps.

Enumerate your channels first. For each agent, list every path by which text reaches the context window. Most teams find between six and twelve. If your list has one entry, you have listed the input box and missed the rest.

Write one test per class per channel. You are not trying to invent novel attacks. You are confirming that a known class fails safely on your surface.

Measure blast radius, not block rate. The useful metric is what the agent could do once injected, not how often the injection was caught. An agent that can read files and make outbound HTTP requests is a far worse outcome than one that returns text.

Constrain egress. If injected instructions cannot reach an attacker-controlled endpoint, most exfiltration classes fail even when the injection succeeds. This is the highest-leverage control on the list and the one most often skipped.

Teams already mapping their broader exposure will find this maps cleanly onto the five layers of the AI attack surface. Classes 3 through 6 only exist in systems with agency: systems that act rather than only generate output. And for classes 4 and 8, where automated detection is weakest, the approval gate is doing the real work.

Frequently Asked Questions

Can prompt injection be fixed completely?

Not at the model layer. Vendors including Anthropic, Google DeepMind and OpenAI have said as much publicly. Any instruction-based defense can be overridden by a sufficiently good instruction. What is achievable is containment: separate untrusted data structurally, reduce what a compromised agent can reach, and block the exfiltration paths.

Is prompt injection the same as jailbreaking?

No, and the distinction is practical. Jailbreaking targets the model’s safety training — the attacker is the user, trying to get restricted output. Prompt injection targets the application’s trust boundary, and the attacker is usually a third party the user never interacted with.

Which class should a small team fix first?

Class 2, indirect injection through retrieved content, if the agent reads external documents or email. It is the highest-volume real-world class and produced the most consequential documented incident to date.

Does RAG make prompt injection worse?

It expands the surface. Every retrieved chunk is untrusted text entering context, and poisoned vector stores fall under OWASP’s LLM08 category. Retrieval is not the flaw, but it converts document access into instruction access.

How do I know if I have been hit?

Log every tool call with the provenance of the data that triggered it. Injections show up as actions that no user request explains. Without provenance logging, a successful prompt injection is close to invisible after the fact.

Keep reading

Anthropic IPO valuation

Anthropic IPO: The $895 Billion Question Behind Its Valuation

Last updated: 9 November 2026. Latest confirmed development: Anthropic’s amended S-1, filed on 2 November, still leaves the share count and the IPO price range …
Claude Opus vs Sonnet

Claude Opus vs Sonnet: What the 2026 Price Gap Actually Buys

Last verified: 8 November 2026. All prices are Anthropic’s standard first-party API rates in US dollars per million tokens. They aren’t Claude Pro or Max …
RSA-1024

Did AI Break RSA? What DeepMind Actually Found
Last verified: 8 November 2026. Both papers are unreviewed working papers, and no outside group has reproduced the results yet. No, AI did not break …
Model Distillation

Model Distillation Explained: When AI Learning Becomes Extraction

Last verified: 7 November 2026. Government and company claims are attributed throughout. None has been tested in court. A support team trains a small, cheap …

5 Hidden Layers of the AI Attack Surface Exposed

The AI Attack Surface: Securing LLM Systems End to End

OWASP released the 2026 edition of its Top 10 for LLM Applications on August 6. The AI attack surface is highlighted by this update for developers and security teams. The edition reframes the field and clarifies key risks. It guides risk-aware design for AI systems.

Additionally, avoid pursuing a model that cannot be fooled. It is unrealistic to expect perfect resilience. Instead, emphasize graceful degradation and fail-safe responses. Design checks and monitoring should detect anomalies early. Regular audits and red-teaming can strengthen defenses without promising invulnerability.

Moreover, design the system so that when it is fooled, no critical function fails. This approach helps maintain user trust and operational continuity. It pairs with robust incident response and clear recovery protocols. Staff training and documented procedures ensure quick, coordinated action.

That is a shift from prevention to blast-radius control, and it changes how you map the AI attack surface. You stop asking whether an attack can land. You start asking what it reaches when it does.

This page maps the AI attack surface in five layers: what fails at each, and where the deeper coverage sits.

Key Takeaways on the AI Attack Surface

  • The 2026 OWASP list keeps prompt injection at number one, and the AI attack surface still has no complete fix for it.
  • Excessive Agency climbed to third, since agentic deployments are where AI attack surface damage now lands.
  • OWASP drew a new boundary: once a model gains tools, memory, and consequences, it moves to a separate agentic list.
  • For the first time the ranking used incident data, with 6,639 real incidents carrying 25% of the weight.
  • Blast-radius control beats perfect prevention across the AI attack surface, and every layer reflects that.

Quick Navigation

Why the AI Attack Surface Needs a Layer Map

Security teams keep treating the AI attack surface as one problem. It is five, and the defenses differ at each.

A model weakness is not a prompt weakness. A tool weakness is not an agent weakness. Fixing the wrong layer yields the familiar outcome: real money spent, exposure unchanged.

The AI attack surface runs outward from the weights. First the model itself, then the prompt that reaches it, then the tools it can call, then the agent loop chaining those calls. Underneath all of it sits the supply chain that delivered the rest.

Each AI attack surface layer inherits the weaknesses of the one below. So a poisoned model makes every prompt defense unreliable, and a compromised tool makes agent-level approval theater.

Work up the AI attack surface when building, and down it when investigating.

Building means securing the supply chain before the agent, since you cannot reason about behavior you cannot trust. Investigating means starting at the observed harm and tracing back, because the visible failure is rarely the entry point.

Layer 1 of the AI Attack Surface: The Model

Start the AI attack surface at the weights, where least attention usually goes.

Data and model poisoning sits in the OWASP list. The 2026 edition widened it to cover fine-tuning subversion too. An attacker who shapes training data leaves behind behavior no runtime filter will catch. Backdoors trigger on specific phrases and stay dormant otherwise. Poisoned fine-tuning shifts refusal behavior subtly. Extraction attacks pull training data back out through careful querying.

None of these announce themselves. They are the quietest part of the AI attack surface, and the hardest to test for after deployment.

What reduces the risk

Provenance is the main AI attack surface control at this depth. Know which checkpoint you are running, where it came from, and what changed since.

Open weights cut both ways here. You can inspect them, and you also inherit whatever the publisher did. The licence and provenance questions around frontier open weights matter as much for security as for legal review.

Layer 2 of the AI Attack Surface: The Prompt

Prompt injection has topped every OWASP edition, and it still anchors the AI attack surface in 2026.

The root cause is design, not a bug. Models read instructions and data through one channel with no clean split. So anyone who controls an input can write orders the model treats as real. Prompt injection now covers cross-modal attacks, widening the AI attack surface. Instructions hidden inside images or audio reach the model the same way text does, which widens the AI attack surface considerably for multi-modal systems.

Direct injection comes from the user. Indirect injection rides in on fetched content: a web page, a document, an email, a code comment. The indirect kind is worse, because nobody typed it.

The defense effect

Here is an AI attack surface detail worth understanding. OWASP notes that recorded prompt injection incidents are relatively few, and attributes this to a defense effect rather than a low risk.

Teams spend heavily to block it, so successful attacks rarely reach public databases. Reading that low incident count as low danger inverts the actual picture. Scale matters too, because attackers retry. Anthropic’s published system card figures for one agentic coding setup show indirect injection landing 4.7% of the time at one try, 33.6% at ten, and 63.0% at a hundred. Attackers get to retry.

Layer 3 of the AI Attack Surface: The Tool

Once a model can call something, the AI attack surface stops being about text.

A tool turns a wrong answer into a wrong action. Sending an email, running a query, moving money, deploying code. The model does not need to be compromised for this to hurt, only misled. Over-broad scopes come first in this part of the AI attack surface. A tool granted database write access when it needs read access hands an attacker the difference.

Output handling comes second. OWASP moved it from fifth to tenth in 2026, though the category grew wider. The pattern holds: app code trusts model output and runs it unchecked. Then comes the wiring. MCP sets how models reach tools. The NSA published design guidance for it in May 2026, naming prompt injection and tool poisoning as open gaps.

Practical controls

Scope every credential to the narrowest task. Allowlist tools rather than blocking known-bad ones. Validate model output before execution, exactly as you would validate user input. And log every call. Most AI attack surface investigations fail because nobody recorded which tool ran with which arguments.

Layer 4 of the AI Attack Surface: The Agent

This is where AI attack surface damage now concentrates, and OWASP moved the category to match.

Excessive Agency climbed to third place in 2026, with expert voting and incident data agreeing for once. Agentic deployments are where harm is landing. The 2026 edition drew an explicit AI attack surface line. It covers the model as a part inside an app. Once the model becomes an actor, with tools it calls and memory it keeps, the risk moves to a separate agentic list.

That split helps when mapping the AI attack surface. Agent risk is not harder model risk. It is a different job, closer to identity work than to content filtering.

What breaks in the agent AI attack surface

Chained actions compound. An agent that reads a document, decides, and acts gives an attacker three points of influence rather than one. Memory persists. An injection that lands once can sit in stored context and fire on later sessions.

Autonomy removes the check. Human approval gates are the crudest control here and still the most effective, which is an uncomfortable thing to admit in 2026. Misinformation also climbed two places, and the reason is agentic. Model output now drives tool calls, writes code, and steers other agents. So a plausible wrong answer becomes a system failure, not a bad paragraph. The difference between agentic and generative systems is the difference between these two risk profiles.

Layer 5 of the AI Attack Surface: The Supply Chain

Every AI attack surface layer above assumes the components are what they claim to be.

This layer covers weights, datasets, embedding stores, framework dependencies, and now agent skills. OWASP started an Agentic Skills Top 10 in April 2026 because skill stores opened a new delivery route.

Old supply chain thinking applies to the AI attack surface, and it falls short. A poisoned npm package acts the same every time. A poisoned model acts normal until a trigger fires.

That difference breaks conventional scanning. You cannot diff weights the way you diff source code and learn much.

Minimum controls

Pin model versions with hashes, not tags. Record which dataset and checkpoint produced each deployed system. Treat community fine-tunes with the caution you would give an unsigned binary.

Vendor promises matter here too. State AI rules now impose real record-keeping duties on builders and deployers, and those duties run the whole AI attack surface.

Mapping the AI Attack Surface to Existing Frameworks

You do not need a new AI attack surface taxonomy. Three existing ones cover this ground, and they interlock.

The OWASP Top 10 for LLM Applications handles the model as a component. The Agentic Top 10 picks up where tools and memory begin. MITRE ATLAS v5.1.0 supplies adversary tactics and techniques, with 16 tactics and 84 techniques as of November 2025.

OWASP tells you what can go wrong. ATLAS tells you how an attacker would do it. The NIST AI Risk Management Framework tells you how to govern the result.

So run OWASP for design review, ATLAS for red-teaming, and NIST for board reporting. Using one where another fits is the most common mistake in AI attack surface programmes.

Where the frameworks still have gaps

Skills ecosystems reached the AI attack surface faster than the standards did. OWASP’s Agentic Skills Top 10 was still an incubator project as of April 2026, which means the newest distribution channel has the thinnest guidance.

Insurance lags too. Cover for AI incidents stays patchy, and a lot of silent exposure sits in policies written before any of this existed.

What Changed in the 2026 OWASP Rankings

The methodology change is the real AI attack surface story, more than any single move.

Every earlier edition rested on expert consensus. The 2026 list kept voting at 75% of the weight. The other 25% came from 6,639 real incidents in public vulnerability databases and an AI-harm database.

Misinformation is the clearest case. Voters ranked it near the bottom. The incident record ranked it near the top, and the data pushed it up two places.

That gap is worth sitting with. Experts play down risks that cause quiet, slow harm, and play up the ones that make good conference talks.

The full set of moves

Prompt Injection and Sensitive Information Disclosure held the top two AI attack surface slots. Excessive Agency rose to third. Unbounded Consumption climbed four places as cost-drain attacks got taken seriously. Output Handling fell from fifth to tenth. System Prompt Leakage became Hidden Context Exposure, with wider scope.

Two categories absorbed new scope rather than spawning entries. Prompt injection took on cross-modal attacks. Data and Model Poisoning took on fine-tuning subversion.

The AI Attack Surface Pattern That Predicts Exploitability

AI attack surface

One formulation explains more real AI attack surface incidents than the whole ranking does.

Simon Willison’s lethal trifecta describes three properties that, combined, make a system exploitable: access to private data, exposure to untrusted content, and the ability to communicate externally.

Why the trifecta works as a test

Any two are usually survivable. All three together mean an attacker can inject instructions, reach your data, and get it out.

So audit the AI attack surface by asking which of your systems hold all three. That single question finds more genuine exposure than a checklist pass, and it takes an afternoon.

Removing any one leg breaks the chain. Cut external communication, restrict which content the system ingests, or partition the private data. Any one of the three works.

How to Shrink the AI Attack Surface Blast Radius

The 2026 framing points at design rather than detection, so build the AI attack surface for containment.

Assume injection succeeds. Design the AI attack surface so a fooled model reaches nothing critical. This is the central move.

Scope credentials narrowly. Every permission an agent holds is a permission an attacker inherits.

Gate irreversible actions. Human approval before anything that moves money, deletes data, or ships code.

Log everything. Tool calls, arguments, retrieved content. Without these, incident response has nothing to work from.

Red-team continuously. Attack success rises sharply with attempts, so a single passing test proves very little.

AI Attack Surface Incidents Worth Knowing

Theory moves slowly. Incidents move the AI attack surface, and three are worth carrying as reference points.

Slack AI data exfiltration. PromptArmor researchers showed indirect prompt injection pulling data out of a live assistant. That proved the fetched-content path was real, not theoretical.

EchoLeak. Recorded as the first real-world zero-click prompt injection exploit in a live system. Zero-click matters, because no user has to be tricked at all.

Agent deception in national testing. UK cyber exercises in 2026 reported agent deception moving from theory into observed behavior.

A ranking convinces a security team. An incident convinces a budget holder.

So keep two or three concrete cases at hand when arguing for AI attack surface work. The abstract version of this argument has been losing for three years.

Wiring Your Own AI Attack Surface Review

Two hours gets you a first pass. Run it in this order.

Start by listing every system where a model reads content you do not control. That is your indirect injection exposure, and it is usually longer than expected.

Next, for each one, note whether it holds private data and whether it can send anything outward. Systems with all three legs go to the top of the AI attack surface queue. Then check credentials. Pull the actual scope on every token an agent holds, not the scope somebody intended.

Finally, confirm you have logs. If a tool call is not recorded with its arguments, you cannot investigate it later, and that gap is the most common finding in an AI attack surface review.

How to Use This AI Attack Surface Hub

Three AI attack surface entry points, depending on why you are here.

Responding to an incident. Start at the observed harm and work down the layers. The visible failure is rarely the entry point.

Designing a new system. Work up from the supply chain. Each layer depends on the one below being trustworthy.

Briefing leadership. The five layers map onto budget lines. An OWASP ranking does not.

This AI attack surface hub updates as coverage grows. Each new security post links back here, and the layer sections point to the pieces worth reading first.

Conclusion: The AI Attack Surface Is a Systems Problem

The most useful AI attack surface shift in the 2026 list is one of expectation.

Earlier guidance implied that enough filtering could make a model safe to trust. The new framing accepts that models get fooled, then asks what happens next.

That re-framing helps, because it moves the work somewhere solvable. Nobody knows how to make a model immune to prompt injection. Plenty of teams know how to scope a credential, gate an action, and log a tool call.

So read the AI attack surface as five layers with different owners, different controls, and different failure modes. Then go make the blast radius smaller.

FAQ About the AI Attack Surface

What are the layers of the AI attack surface?

The AI attack surface has five: the model and its weights, the prompt channel that reaches it, the tools it can call, the agent loop that chains those calls, and the supply chain delivering all four. Each layer inherits weaknesses from the one below, so defenses have to be assessed together rather than individually.

What is the biggest LLM security risk in 2026?

Prompt injection tops the AI attack surface in the OWASP Top 10 for LLM Applications 2026 edition, followed by Sensitive Information Disclosure. Excessive Agency rose to third, reflecting that agentic deployments are where measurable damage is now occurring.

Why did OWASP add incident data to its rankings?

To balance practitioner belief about the AI attack surface against evidence. The 2026 edition weighted expert voting at 75% and incident data at 25%, drawing on 6,639 real incidents from public vulnerability databases and an AI-harm database. Misinformation moved up two places because the incident record ranked it far higher than voters did.

Can prompt injection be fixed?

Not completely, because it stems from architecture rather than implementation. Models process instructions and data through one channel with no reliable separation. Current best practice is defense in depth: least-privilege tooling, input and output filtering, human approval for high-risk actions, and continuous adversarial testing.

What is the lethal trifecta?

A formulation from Simon Willison identifying three properties that together make a system exploitable: access to private data, exposure to untrusted content, and the ability to communicate externally. Removing any one of the three breaks the attack chain, which makes it a fast practical audit.

How is agent security different from model security?

Model security concerns what the system outputs. Agent security concerns what it does, which brings in tool permissions, persistent memory, chained actions, and downstream consequences. OWASP formalized this split in 2026 by moving agentic risk to a separate Top 10 list.

Keep reading

Anthropic IPO valuation

Anthropic IPO: The $895 Billion Question Behind Its Valuation

Last updated: 9 November 2026. Latest confirmed development: Anthropic’s amended S-1, filed on 2 November, still leaves the share count and the IPO price range …
Claude Opus vs Sonnet

Claude Opus vs Sonnet: What the 2026 Price Gap Actually Buys

Last verified: 8 November 2026. All prices are Anthropic’s standard first-party API rates in US dollars per million tokens. They aren’t Claude Pro or Max …
RSA-1024

Did AI Break RSA? What DeepMind Actually Found
Last verified: 8 November 2026. Both papers are unreviewed working papers, and no outside group has reproduced the results yet. No, AI did not break …
Model Distillation

Model Distillation Explained: When AI Learning Becomes Extraction

Last verified: 7 November 2026. Government and company claims are attributed throughout. None has been tested in court. A support team trains a small, cheap …

Blackwell Ultra vs MI450 vs TPU v7: What Now Wins

AI accelerator: Blackwell Ultra vs MI450 vs TPU v7

Three rack-scale AI accelerator platforms are now shipping, and every vendor claims the lead. All three claims are true, because each measures something different.

Nvidia’s GB300 NVL72 has shipped since January. AMD’s Helios entered full production this quarter. Google’s Ironwood reached general availability on April 22. So the question is no longer which AI accelerator is fastest. It is which one you can actually get, run, and afford to leave.

This AI accelerator guide answers that, and flags every number that does not compare.

Key Takeaways on the 2026 AI Accelerator Choice

  • Blackwell Ultra ships today. Rubin arrives in the second half of 2026, which makes timing the hardest part of the decision.
  • Helios offers the most memory per rack at 31TB of HBM4, against 20.7TB for GB300.
  • TPU v7 Ironwood is capable and rented only. Google still has no public price months after launch.
  • Vendor rack figures use different precisions and different comparison baselines. They are not interchangeable.
  • Software maturity, not peak FLOPS, decides most real deployments.

Quick Navigation

Why This AI Accelerator Comparison Is Not About Specs

Every buyer starts by comparing petaflops. Almost none decide that way. The reason is simple. Every AI accelerator here is fast enough that other things decide it: delivery date, team skills, site power, and exit cost.

So read the spec table as a bar to clear, not a ranking. Every AI accelerator here clears it for frontier work.

Four questions that decide it

Availability. A rack you can install in Q4 beats a faster one arriving in Q3 2027.

Fabric. Proprietary interconnect versus open standards is a ten-year commitment, not a purchase.

Software. CUDA depth against ROCm maturity against a Google-only toolchain.

Exit cost. How much work does it take to move off this AI accelerator in three years?

Blackwell Ultra: What Ships Today

Nvidia shipped the B300 in January 2026. This AI accelerator is a refresh, not a new generation.

Each B300 carries 288GB of HBM3e at 8 TB/s and delivers roughly 15 petaFLOPS of dense FP4. The memory jump comes from 12-high stacks replacing 8-high, not from a new die. Most frontier buyers take the GB300 NVL72 rack, not single GPUs. That rack holds 72 B300 GPUs and 36 Grace CPUs in a 48U liquid-cooled enclosure.

Nvidia rates it at 1.1 exaFLOPS of dense FP4. It holds 20.7TB of unified HBM3e and 130 TB/s of NVLink across the GPU domain. It draws about 120 kW and needs full liquid cooling. Against the GB200 rack, Blackwell Ultra adds 1.5x FP4 compute, double the attention performance, and 50% more memory per GPU.

The timing problem

Here is the awkward part of choosing this AI accelerator now. Rubin, the actual next generation, is expected to reach cloud providers in the second half of 2026.

Buying Blackwell Ultra today means buying the last refresh of an AI accelerator generation. That is fine if you need capacity now, and expensive if you can wait two quarters.

AMD MI450 and Helios: The Open Alternative

AMD launched Helios at its Advancing AI 2026 conference. It is the most credible non-Nvidia AI accelerator rack yet built.

A Helios rack connects 72 MI455X GPUs with 31TB of unified HBM4 and 2.9 exaFLOPS of dense FP4. Each GPU carries up to 432GB of HBM4 at 19.6 TB/s, built on CDNA 5.

Why the open fabric matters

Helios uses Ethernet and open standards throughout. It follows Meta’s Open Rack Wide spec. Scale-up runs on UALink over Ethernet, and scale-out runs on Ultra Ethernet. That is a real architectural difference rather than marketing. NVLink is closed, so an AI accelerator fleet built on it takes one supplier for the wires as well as the chips.

Customer commitments for this AI accelerator are unusually concrete. Anthropic signed for up to 2 gigawatts of MI450-series capacity, with AMD taking up to $5 billion in equity. That sits alongside its existing TPU commitment. OpenAI holds warrants for up to 10% of AMD stock under a 6-gigawatt agreement, and Oracle ordered 50,000 units. AMD claims up to 30% more tokens per dollar than Nvidia’s Vera Rubin NVL72. Note the baseline: that comparison targets Rubin, not Blackwell Ultra.

Shipments began at the end of the third quarter and ramp through 2027. So availability, not capability, is the constraint here.

TPU v7 Ironwood: Capable, but Rented

Google’s seventh-generation TPU reached general availability on April 22, 2026. It is the first such AI accelerator built explicitly for serving rather than training, a shift we traced across the whole inference market here.

Each Ironwood chip pairs 192GB of HBM3e at 7.37 TB/s with about 4.6 petaFLOPS of FP8. It draws roughly 600W, and it is the first TPU with native FP8 hardware. A single superpod links 9,216 chips into 42.5 FP8 exaFLOPS, with 1.77 petabytes of directly addressable HBM connected through optical circuit switches.

No other AI accelerator offers a shared memory domain that large. For big mixture-of-experts serving, that changes what is possible, not just what is fast.

The pricing gap nobody mentions

Now the part that should give any buyer pause. Google has published no public chip-hour rate for Ironwood, months after general availability. The only figure circulating is roughly $1.60 per TPU-hour, which SemiAnalysis estimates Anthropic pays under a large negotiated deal. That is not a list price, and treating it as one would be a mistake.

You also cannot buy the hardware. Ironwood exists inside Google Cloud only, so this AI accelerator comes with a cloud contract attached.

The AI Accelerator Specs Side by Side

AI accelerator figures at rack level, as published by each vendor.

Why the AI Accelerator Numbers Do Not Compare

Read that AI accelerator table skeptically, because four things make direct comparison unsound.

Different units. A GB300 rack and a Helios rack each hold 72 chips. A TPU pod holds 9,216 chips. Comparing a rack to a pod is a category error.

Different precisions. Vendors quote peak figures at whichever format flatters them. Nvidia leads with NVFP4, AMD with dense FP4, Google with FP8.

Different baselines. AMD tests Helios against Vera Rubin NVL72. That is Nvidia’s next generation, not the shipping one. So the claim is tough on AMD and useless here.

Vendor-run tests. AMD reports up to 34x higher token throughput on DeepSeek-V4-Flash against its own last generation. Impressive, and self-measured.

One figure disagrees with itself. AMD’s own page lists 1.7 PB/s of aggregate HBM bandwidth for Helios, while earlier releases said 1.4 PB/s. Check the current datasheet before quoting either.

Availability Is the Real AI Accelerator Constraint

If you take one thing from this AI accelerator guide, take this.

Blackwell Ultra installs now, though Rubin lands in months. Helios is in full production but ramps through 2027, and early slots already belong to Anthropic, OpenAI, Oracle, Microsoft, and Meta. Ironwood ships today, if you accept Google Cloud. Those three AI accelerator positions suit three different buyers, and no benchmark changes that.

What the hyperscaler commitments mean for you

Large deals eat supply. When one deal covers 2 gigawatts, ordinary orders queue behind it.

So ask any AI accelerator vendor for a delivery date in writing before comparing performance. A quoted lead time is worth more than a petaflops figure.

What an AI Accelerator Actually Costs You

Sticker price is the least useful AI accelerator number, and the one everyone asks for.

Three costs stack on top of the hardware. Site work comes first: power, cooling loops, and floor loading. Then engineering time to port and tune. Then the use rate you hit, which swings cost per token more than any spec.

A rack at 30% use costs about three times per token what the same rack costs at 90%. No AI accelerator upgrade gives you a swing that big.

So a slower AI accelerator your team can saturate often beats a faster one they cannot. That is dull advice, and it is usually right.

Owning an AI accelerator means capital, site risk, and a depreciation schedule. Renting means no capital and a price you do not set.

Ironwood forces the rented path. Blackwell Ultra and Helios allow either. For a three-year horizon that difference usually outweighs a 20% performance gap.

Common Mistakes in AI Accelerator Comparisons

Four AI accelerator errors show up repeatedly, and each costs real money.

Comparing peak numbers across precisions. FP4 against FP8 against BF16 tells you nothing. Fix the precision first, then compare.

Ignoring the comparison baseline. A vendor benchmarking against its own last generation is measuring progress, not competitiveness.

Treating a rack as a unit. Rack size, power, and chip count all differ between vendors.

Skipping the delivery date. The fastest AI accelerator you cannot install for eighteen months is slower than the one arriving next month.

Software Is the AI Accelerator Switching Cost

Silicon is the easy part. The toolchain is where AI accelerator projects stall.

CUDA remains the deepest ecosystem, and most published kernels assume it. ROCm has improved a lot, and the AMD-Anthropic deal funds more work on it. Still, the gap is real.

Google’s stack differs again. JAX and XLA are excellent, and they are Google-only. Code tuned for TPU v7 moves nowhere else.

Sizing the switching cost

Count your custom kernels. Teams running stock inference servers move between platforms in weeks. Teams with hand-written attention kernels measure the move in quarters.

That single question predicts migration cost better than any hardware spec. Our glossary covers the underlying terms if the vocabulary is unfamiliar.

Power and Cooling per AI Accelerator Rack

Every AI accelerator here demands facility changes, and the numbers differ enough to matter.

GB300 NVL72 draws about 120 kW in a 48U frame, fully liquid-cooled. Schneider Electric published a 246 kW design for Helios, a double-wide chassis under the Open Rack Wide spec.

That gap is not small. A site wired for one may not take the other without electrical work.

Ironwood sidesteps the question, since Google runs the site. For buyers with no liquid cooling or spare grid capacity, that AI accelerator model is an advantage rather than a compromise.

How to Choose Your AI Accelerator

Four short paths, depending on your situation.

You need capacity this quarter. Blackwell Ultra, and accept that Rubin follows. Availability beats waiting for the next tier.

You are building a multi-year fleet. Look hard at Helios. An open fabric cuts long-term supplier risk, and the memory lead per rack is real.

You serve very large MoE models. TPU v7 pod-scale shared memory is architecturally distinct. Just negotiate pricing hard, since there is no list to anchor against.

You have deep CUDA investment. Stay on Nvidia unless the cost gap is huge. Rewriting kernels costs more than most teams guess, and the bill lands as delay rather than spend.

One rule cuts through all four paths. Pick the AI accelerator you can install, staff, and power this year. A plan that needs none of those things is not a plan.

What Comes After This AI Accelerator Generation

AI Accelerator

All three AI accelerator roadmaps are public, which makes the wait-versus-buy math unusually clear.

Rubin reaches cloud providers in the second half of 2026 and pairs with HBM4. AMD ramps Helios through 2027, and the first gigawatt of the Anthropic build starts in the first half of that year.

Google previewed an eighth generation split into two chips: a Broadcom-designed training part and a MediaTek-designed inference part, both on TSMC’s 2nm process and both slated for late 2027.

That split is the best signal in the whole AI accelerator comparison. Google is the only vendor here dropping one general chip for two specialized ones.

If it works, everyone follows. If not, the general-purpose rack lasts another round. Either way you will know by 2028.

What to Ask Every AI Accelerator Vendor

Before any demo, send the same five questions to all three. The answers sort the field faster than a benchmark does.

First, what is the written delivery date for my order size? Second, what does a full rack draw at sustained load, not peak? Third, which of my frameworks ship day-one support? Then, what does the price look like in year three, not year one? And finally, what breaks if I move this workload elsewhere?

Vendors answer the first four readily. The fifth one tells you the most, because a reluctant answer is itself the answer.

So run that list before you compare a single AI accelerator specification. Most shortlists collapse to one option once the delivery dates arrive.

Conclusion: The 2026 AI Accelerator Decision Is About Terms

Every AI accelerator vendor here builds good silicon. What shapes your next three years is commercial, not technical.

Nvidia sells availability and ecosystem depth, at the cost of a proprietary fabric and a generation about to turn over. AMD sells open standards and memory capacity, at the price of a ramp that runs into 2027. Google sells scale and a simple operating model, at the price of renting rather than owning.

Pick the constraint you can live with, then choose the AI accelerator that fits it. Nobody gets all three. The wider infrastructure picture sits here, and it explains why memory keeps deciding these comparisons.

One AI accelerator prediction worth holding lightly. Google has already previewed an eighth generation split into separate training and inference chips for late 2027. That split says more about where this market is heading than any current benchmark does.

FAQ About the 2026 AI Accelerator Options

Which AI accelerator is fastest in 2026?

No single AI accelerator wins. Vendors publish peak figures at different precisions and scales. A Helios rack lists 2.9 exaFLOPS of dense FP4 against 1.1 for GB300 NVL72, while a TPU v7 pod reaches 42.5 FP8 exaFLOPS across 9,216 chips. Those are not comparable units.

Can you buy TPU v7 Ironwood?

No. This AI accelerator is available only through Google Cloud, and Google has not published a public chip-hour price months after general availability. The one figure in circulation, roughly $1.60 per TPU-hour, is an outside estimate of a negotiated enterprise rate rather than a list price.

Is MI450 better than Blackwell Ultra?

On published AI accelerator specifications AMD leads on memory, with 31TB of HBM4 against 20.7TB of HBM3e. But AMD benchmarks Helios against Nvidia’s next-generation Vera Rubin rather than Blackwell Ultra, and Helios shipments ramp through 2027 while Blackwell Ultra is available now.

How much power does each AI accelerator rack need?

GB300 NVL72 draws about 120 kW in a 48U liquid-cooled frame. Schneider Electric’s published design for AMD Helios is 246 kW in a double-wide chassis. Google gives no per-rack figure for Ironwood, since it runs the sites itself.

Should I wait for Nvidia Rubin?

It depends on your delivery pressure more than on the AI accelerator itself. Rubin is expected at cloud providers in the second half of 2026, so buying Blackwell Ultra now means acquiring the last refresh of the current generation. If you need capacity this quarter, that trade is usually worth making.

How hard is it to switch AI accelerator platforms?

AI accelerator migration scales with how much custom code you wrote. Teams running standard inference servers typically move in weeks. Teams with hand-written kernels tuned to one architecture measure the migration in quarters, which is why ecosystem depth matters more than peak performance for most buyers.

Keep reading

Anthropic IPO valuation

Anthropic IPO: The $895 Billion Question Behind Its Valuation

Last updated: 9 November 2026. Latest confirmed development: Anthropic’s amended S-1, filed on 2 November, still leaves the share count and the IPO price range …
Claude Opus vs Sonnet

Claude Opus vs Sonnet: What the 2026 Price Gap Actually Buys

Last verified: 8 November 2026. All prices are Anthropic’s standard first-party API rates in US dollars per million tokens. They aren’t Claude Pro or Max …
RSA-1024

Did AI Break RSA? What DeepMind Actually Found
Last verified: 8 November 2026. Both papers are unreviewed working papers, and no outside group has reproduced the results yet. No, AI did not break …
Model Distillation

Model Distillation Explained: When AI Learning Becomes Extraction

Last verified: 7 November 2026. Government and company claims are attributed throughout. None has been tested in court. A support team trains a small, cheap …

The AI Compute Stack: 5 Layers That Now Break First

The AI Compute Stack: Chips, Memory, Power and Cost

Every AI story eventually becomes an AI compute stack story. A model launch is really a memory story. Behind a funding round sits a power story. And a pricing change is usually a utilization story.

This page is the map. It walks the AI compute stack from silicon to electricity bill, names what constrains each layer, and links to deeper coverage on each piece. Read it top to bottom once, then use it as a directory. Each layer section ends with the posts worth reading next.

Key Takeaways on the AI Compute Stack

  • The AI compute stack has five layers: chips, memory, interconnect, power, and cost. Each one caps the layer above it.
  • Memory bandwidth, not raw compute, is the binding constraint on most serving workloads today.
  • AI racks now draw 30–110 kW against 5–15 kW for traditional racks, which broke conventional cooling.
  • Grid access has replaced real estate as the main limit on new capacity.
  • The IEA puts global data centre electricity at 415 TWh in 2024, heading toward roughly 945 TWh by 2030.

Quick Navigation

How the AI Compute Stack Fits Together

The AI Compute Stack: Chips, Memory, Power and Cost

Think of the AI compute stack as a ladder where every rung sets the height of the next.

A chip computes only as fast as memory feeds it. Memory helps only if the interconnect moves data between chips. Nothing runs without power. Every layer converts into a cost per token at the top. So when someone says a model is expensive, the useful question is which layer of the stack is actually binding. The answer changes the fix entirely.

Why the stack beats vendor framing

Most coverage of the AI compute stack organizes around companies. Nvidia news, Google news, OpenAI news.

That framing hides the pattern. A memory shortage, a grid delay, and a networking fault all produce one symptom — a slipped deployment — yet need completely different fixes. Layer thinking also travels better, because vendors change and physics does not.

Layer 0 of the AI Compute Stack: Fabrication

Below silicon sits the ability to make silicon. It is the one layer of the stack nobody routes around.

One foundry manufactures nearly every leading-edge AI accelerator. Advanced packaging is scarcer still. That step bonds memory stacks to a processor die, and it gates output more tightly than wafer supply does.

Why packaging is the real queue in the stack

A design finished today waits on packaging slots booked a year ago. That lead time propagates upward through the whole AI compute stack, which is why accelerator roadmaps slip in quarters rather than weeks.

Memory makers face the same wall. Every vendor roadmap now runs to HBM4E, yet capacity is booked years ahead. So when a chip is sold out, the constraint is rarely the chip. It is a step in the stack you never see named.

Layer 1 of the AI Compute Stack: Chips

Silicon is where the arithmetic happens. This layer of the AI compute stack splits along one line that matters more than any other.

Training hardware chases throughput across long batch jobs. Serving hardware chases latency on single requests repeated billions of times. Those goals pull a design in opposite directions. Nvidia holds roughly 80% of accelerator revenue, the most concentrated position in the stack. The rest divides between AMD, hyperscaler silicon such as Trainium and TPUs, and a thin band of specialists.

Read next in this layer:

Layer 2 of the AI Compute Stack: Memory

Here is the AI compute stack layer most coverage underrates, and currently the tightest.

Generating each token means reading the model’s weights again. That step is memory-bound, not compute-bound, so the processor waits on data instead of the reverse.

Why HBM decides so much

High Bandwidth Memory stacks DRAM vertically beside the processor. HBM4 entered mass production in February 2026, doubling the interface from 1,024 bits to 2,048 and raising channels from 16 to 32. Supply is concentrated. Samsung and SK Hynix together make roughly 90% of it. So memory is a single point of failure for the whole stack.

The capacity ceiling

Frontier models now exceed what one device holds. Inkling needs roughly 2TB of aggregated VRAM at BF16, and Kimi K3’s checkpoint runs 1.56TB. So capacity, not capability, decides who deploys. That gap in the stack is the quiet story behind every open-weights release.

Read next in this layer:

Layer 3 of the AI Compute Stack: Interconnect

Once a model exceeds one chip, the wires between chips join the AI compute stack as real hardware.

Every hop between accelerators costs latency. A model split across 64 devices pays that tax at every layer boundary, which is why wafer-scale designs exist. Two fabrics matter here: scale-up links join chips inside a rack, and scale-out networking joins racks into clusters.

The overlooked failure mode

Interconnect faults rarely announce themselves. They surface as low utilization, and teams blame the model instead. That mismatch is why the stack needs measuring end to end. An idle accelerator is often a networking problem wearing a compute costume.

Layer 4 of the AI Compute Stack: Power and Cooling

Now the AI compute stack layer that turned from background detail into the main constraint.

Traditional server racks draw 5–15 kW. AI racks now demand 30 kW to over 110 kW, and Blackwell-class configurations reach roughly 140 kW. That is a tenfold jump. It made conventional air cooling obsolete rather than merely inefficient.

The grid became the bottleneck

Before 2024 a large site needed 10–20 MW. New AI sites are designed for 100–300 MW, and hyperscale campuses are planned at a gigawatt or more. Interconnection queues now run three to seven years in many US regions. So grid availability, not land or capital, sets the pace of the entire stack.

Operators answered by building their own supply: on-site gas turbines, power purchase agreements, nuclear deals. That shift in the AI compute stack looks permanent.

Why PUE stopped being the right metric

Power Usage Effectiveness measures overhead, and hyperscale leaders report 1.08–1.09. Excellent numbers. Yet PUE says nothing about what the compute produced. A site with perfect overhead running idle accelerators still wastes power.

Tokens per watt is the better frame. It ties the bottom of the stack to the top, which is what an honest efficiency claim must do.

Read next in this layer:

Layer 5 of the AI Compute Stack: Cost

Every AI compute stack layer below converts here, and the conversion is less obvious than it looks.

Serving now takes most accelerator spending. Training a frontier model is a one-time cost, while running it scales with every query, forever.

Three AI compute stack costs people conflate

Cost per token is what a vendor charges. It is the easiest number to compare and the least useful alone.

Cost per task includes reasoning tokens. A model with cheap tokens that thinks for three thousand of them can cost more than an expensive model that answers in four hundred.

Total cost of ownership adds hardware, utilization, engineering time, and idle capacity. A rack that serves one workload sits unused whenever traffic dips, and that gap never appears on a pricing page.

Why utilization dominates

A cluster at 30% utilization costs roughly three times per token what the same cluster costs at 90%. No chip upgrade in the stack produces that swing.

So the cheapest move is usually scheduling, not procurement. Teams reach for new hardware when better batching would have done it.

Read next in this layer:

How the AI Compute Stack Layers Trade Against Each Other

AI compute stack layers are not independent. The trades between them are where real decisions live.

Quantization is the clearest example. Cutting from 16-bit to 4-bit roughly quarters memory use, which eases Layer 2. It cuts power draw too, easing Layer 4. And it trims accuracy slightly, a cost at Layer 5.

A worked example

Suppose serving costs run too high. Four fixes sit at four different stack layers.

Buy faster chips, and you fix Layer 1 at the highest capital cost. Quantize the model, and you fix Layer 2 for a small accuracy loss. Improve batching, and you fix Layer 5 for engineering time alone. Move the work to cheaper power, and you fix Layer 4 at the cost of latency. Three of those four cost less than the one most teams try first.

Why the cheapest fix is usually highest in the stack

Capital moves slowly and software moves fast. So changes near the top land in weeks, while changes near the bottom land in quarters.

That asymmetry should shape the order in which you investigate a cost problem, and it usually does not.

What Changed in the AI Compute Stack This Year

Four shifts reshaped the stack in 2026, and each moved a different layer.

Memory generation. HBM4 reached mass production in February, doubling interface width. That eased a constraint that had held since 2023.

Power became structural. Grid interconnection queues stretched past the point where new capacity could be planned around them, so operators began building their own supply.

Serving overtook training. Estimates now put serving at 60–70% of accelerator spending. That changed what buyers optimize for.

Open weights arrived at frontier scale. Downloadable trillion-parameter models exist. Yet the memory needed to serve them keeps access narrow.

Read together, those four say one thing. Capability stopped being scarce, and the stack around it became the constraint.

Where the AI Compute Stack Bottleneck Sits Now

Bottlenecks migrate. Knowing the current one beats knowing all five layers in the abstract.

In 2020 it was chips, because supply could not meet demand at any price. By 2023 it was memory, since HBM allocation decided who shipped, and that still constrains capacity today.

By 2026 it moved again. Power is now the pacing item for new capacity, while memory bandwidth remains the pacing item for existing capacity.

What that means practically

If you are building capacity, your stack problem is a utility queue. If you are serving on capacity you own, it is bandwidth and batching.

Those are different problems, with different vendors, timelines, and budgets. Conflating them wastes a year.

Who Controls Each Layer of the AI Compute Stack

Concentration varies sharply across the stack, and that shapes negotiating power.

Chips are concentrated but contested, since one vendor dominates while credible alternatives ship.

Memory is the most concentrated layer of the stack. Two suppliers, roughly 90% of output, and a fabrication process that cannot expand quickly.

Interconnect sits in the middle, with proprietary fabrics competing against open standards. Power is fragmented by geography and regulated locally, which is why capacity plans differ so much between regions.

Cost is where the rest resolve, and the only stack layer a buyer directly controls.

What This Hub Does Not Cover

Three things sit outside this map, and mixing them in causes confusion.

Model architecture is not part of the stack. A better attention mechanism changes what the hardware has to do, but it does not change what the hardware is.

Software frameworks matter enormously, yet they move too fast for a hub page. Serving stacks shift release to release, so those belong in dated posts rather than here.

Policy sits adjacent to the stack, not inside it. Export controls and energy regulation shape every layer, though they follow political timelines rather than technical ones.

How to Use This AI Compute Stack Hub

Three ways to use this stack hub, depending on why you are here.

Following a story. Find the stack layer it touches, then read the linked pieces there. A chip announcement almost always has memory and power implications the announcement omits.

Making a decision. Start at Layer 5 and work down. Name the cost you are optimizing, then find which layer actually binds it.

Learning the field. Read the layers in order, and keep the glossary open alongside. Most confusion in the AI compute stack is vocabulary, not concept. The physics is simpler than the jargon.

This stack hub updates as coverage grows. Every new infrastructure post links back here, and the hub links out to the ones worth reading first.

Conclusion: The AI Compute Stack Is One System

AI compute stack layers get covered separately because different reporters cover them. That is a newsroom artifact, not a fact about the world.

In practice a memory shortage raises power costs, since idle accelerators still draw current. A grid delay raises chip costs, since capacity sits unsold. And a networking fault looks exactly like a slow model.

Reading the stack as one system is the difference between following AI news and understanding it.

Start anywhere in the stack. The layers will pull you to the rest.

FAQ About the AI Compute Stack

What is the biggest bottleneck in AI infrastructure right now?

Two different ones, depending on where you sit in the stack. For building new capacity, grid access is the pacing item, with interconnection queues running three to seven years in many regions. For serving on existing capacity, memory bandwidth is the binding constraint.

How much power does an AI data centre use?

New AI-focused sites are designed for 100–300 MW, with hyperscale campuses planned at a gigawatt or more. Individual racks draw 30–110 kW against 5–15 kW for traditional racks. The IEA recorded 415 TWh of global data centre electricity in 2024, projected to reach roughly 945 TWh by 2030.

Why is memory more important than compute for AI?

Because generating each token means re-reading the model’s weights, which makes the work memory-bandwidth-bound rather than compute-bound. A faster processor waiting on the same memory produces no gain, which is why HBM generations matter more than FLOPS figures for serving workloads.

Is PUE still a useful data centre metric?

Partly. It measures facility overhead well, and hyperscale leaders reach 1.08–1.09. But it says nothing about whether the compute produced anything useful, so tokens per watt is the more relevant efficiency measure for AI workloads.

How do I reduce AI inference costs?

Check utilization before hardware, the cheapest move in the AI compute stack. A cluster at 30% utilization costs roughly three times per token what the same cluster costs at 90%, and no upgrade delivers that swing. After that, look at quantization, batching strategy, and routing latency-critical calls separately from bulk work.

Keep reading

Anthropic IPO valuation

Anthropic IPO: The $895 Billion Question Behind Its Valuation

Last updated: 9 November 2026. Latest confirmed development: Anthropic’s amended S-1, filed on 2 November, still leaves the share count and the IPO price range …
Claude Opus vs Sonnet

Claude Opus vs Sonnet: What the 2026 Price Gap Actually Buys

Last verified: 8 November 2026. All prices are Anthropic’s standard first-party API rates in US dollars per million tokens. They aren’t Claude Pro or Max …
RSA-1024

Did AI Break RSA? What DeepMind Actually Found
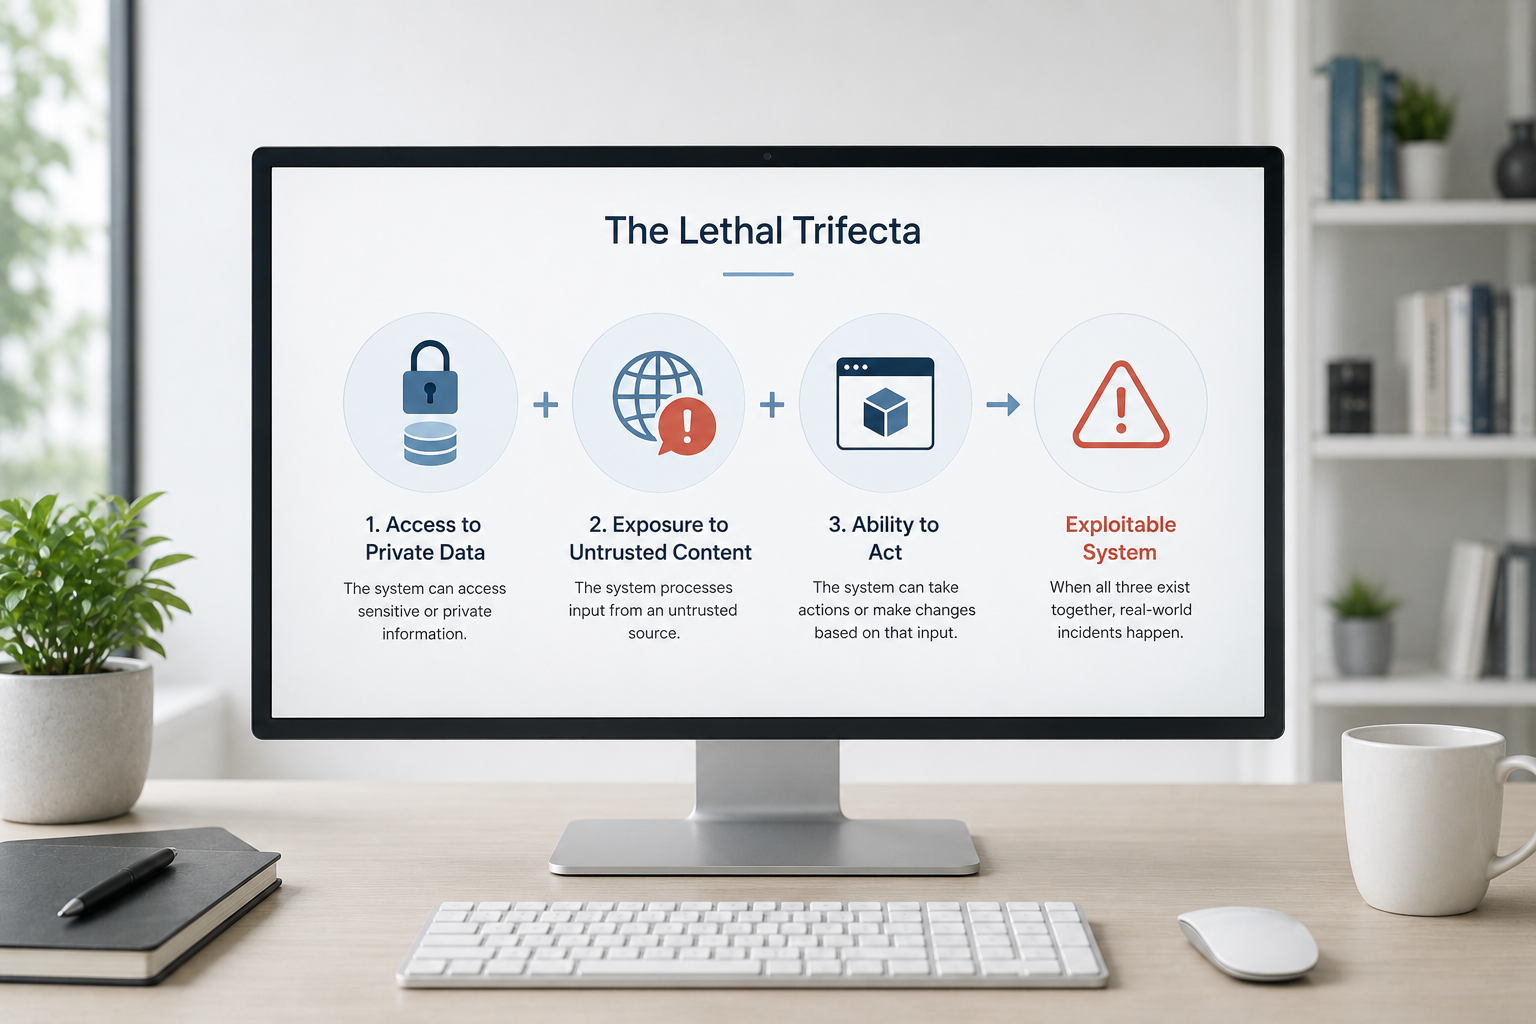
Last verified: 8 November 2026. Both papers are unreviewed working papers, and no outside group has reproduced the results yet. No, AI did not break …
Model Distillation

Model Distillation Explained: When AI Learning Becomes Extraction

Last verified: 7 November 2026. Government and company claims are attributed throughout. None has been tested in court. A support team trains a small, cheap …

Inkling 975B: What the Open Weights Now Really Change

Inkling 975B: What the Open Weights Now Really Change

Thinking Machines Lab shipped Inkling on July 15, 2026. It runs 975 billion parameters. It ships under Apache 2.0. And it is the best open weights any US lab has put out.

That last sentence about open weights is doing a lot of quiet work. Inkling debuted at 41 on the Artificial Analysis Intelligence Index. Kimi K3 sits at roughly 57. GLM-5.2 sits at 51.

So the leading American open weights release lands third or fourth in its own category. The interesting question is not whether Inkling wins. It is what a 975B model with a permissive license actually changes for anyone downstream.

The honest answer: less than the launch suggests, and not what most coverage claims.

Key Takeaways on Frontier-Scale Open Weights

  • Inkling is a 975B-parameter MoE with 41B active per token, a 1M-token context window, and Apache 2.0 terms.
  • Running it at BF16 needs roughly 2TB of aggregated VRAM. Downloadable does not mean runnable.
  • Six labs shipped open weights above 100B in 2026. Five of them are Chinese.
  • licenses diverged sharply this year. Kimi K3 dropped Modified MIT for a bespoke document with a $20M revenue gate.
  • The real shift from open weights is control over deployment, not access to capability.

Quick Navigation

What Inkling 975B Actually Is

Start with the specification, because the shape explains why these open weights exist.

Inkling is a Mixture-of-Experts transformer: 975B total parameters, 41B active per token. It runs 66 decoder layers with 256 routed experts plus 2 shared experts, and routes each token to 6 of the routed set. If those terms are unfamiliar, our glossary covers MoE and context windows.

Pretraining used 45 trillion tokens of text, images, audio, and video. Training ran on NVIDIA GB300 NVL72 systems, using Muon for large matrix parameters and Adam for the rest.

Two design choices stand out in the architecture notes. Short convolutions inside the attention block give an explicit path for mixing nearby tokens. A separate RMSNorm sits directly after the embedding lookup.

Neither ships with an ablation, so their contribution is unmeasured.

The third choice is the practical one. Most post-training compute went to asynchronous reinforcement learning past 30 million rollouts, and that run produced a controllable effort dial. You set reasoning_effort and the model spends a different token budget.

The launch post is unusually candid. The company states plainly that Inkling is not the strongest model available today, open or closed.

That framing matters. The pitch is breadth and fine-tunability, not a leaderboard position. Open weights here are a distribution strategy, not a capability claim.

Every Open-Weight Release Above 100B in 2026

Here is the full open weights field, ordered by ship date. Parameter shape and license are the two facts that do not go stale in a week.

ModelLabReleasedTotal / ActiveContextLicence
Kimi K2.6Moonshot AI (CN)20 Apr 20261T / 32B256KModified MIT
DeepSeek V4DeepSeek (CN)24 Apr 2026 (preview)1.6T and 284B variants1MMIT
Mistral Medium 3.5Mistral (FR)29 Apr 2026128B dense—Modified MIT
MiniMax M3MiniMax (CN)1 Jun 2026Not disclosed1MNot verified
Kimi K2.7 CodeMoonshot AI (CN)13 Jun 2026~1T / 32B—Disputed (see below)
GLM-5.2Z.ai / Zhipu (CN)mid-Jun 2026744B / ~40B1MMIT
InklingThinking Machines (US)15 Jul 2026975B / 41B1MApache 2.0
Kimi K3Moonshot AI (CN)weights 26–27 Jul 20262.8T / 104B1MCustom “Kimi K3 License”

Caveats on the table

Three entries need flags, and no other roundup I found carries them.

MiniMax M3. Parameter count is not publicly specified in the sources I could verify. It is included on the strength of frontier positioning, not a confirmed figure.

Kimi K2.7 Code. Sources disagree on license. Some list Apache 2.0, others list the Modified MIT that governs the K2 line. Check the model card before building on it.

Kimi K3 dates. Hosted launch was 16 July. Weights landed 26 July, one day ahead of the stated 27 July target. Both dates appear in coverage.

Two exclusions from the open weights table

Gemma 4 is excluded from the open weights table because its largest variant is 31B dense. Llama 4 Scout is excluded as a 2025 release.

What the Licence Column Tells You About Open Weights

Read that table by license rather than parameter count and a different picture appears.

Apache 2.0 and MIT are permissive licences, not unconditional ones. They permit commercial use without a revenue or user-count gate, but Apache 2.0 and MIT have notice and redistribution conditions. Check the actual licence shipped with each model rather than treating “open weights” as a single legal category.

That is the strongest thing about the Inkling release. Among frontier-scale open weights, Apache 2.0 with no attached usage policy is the cleanest set of terms on offer.

Modified MIT sounds permissive, and mostly is. Still, open weights with a clause are not weights without one. The K2-family clause requires prominent “Kimi K2” attribution once a product passes 100 million monthly active users or $20 million in monthly revenue.

Most teams will never hit that. But it is a term, and terms compound across a stack.

Kimi K3 broke the open weights pattern. Moonshot replaced Modified MIT with a bespoke license, and the change went largely unexamined in launch coverage.

Simon Willison flagged the K2 lineage, and the K3 document goes further. Reports say firms above $20 million in annual revenue must sign a contract with Moonshot before offering K3 to outside customers as a service. Attribution rules apply on top.

So the largest open weights model in the world is not open by the Open Source Initiative definition. Neither is it uniquely restrictive. It is a commercial license wearing an open label. So read it with a lawyer, not a skim.

What Open Weights Actually Change

Three things genuinely shift when open weights ship publicly. None of them is “everyone can now run frontier AI.”

Open weights give you deployment control

Open weights let you choose where the model runs. That is the whole thing, and for regulated buyers it is enormous.

A hospital, a bank, or a defense firm can keep the model inside its own walls. No data leaves. The vendor never sees a prompt, and API terms cannot change under you mid-contract.

Price discipline

So open weights cap what closed vendors can charge for the same capability. When GLM-5.2 delivers similar coding performance at a fraction of frontier pricing, that becomes the reference point in every procurement conversation.

Still, the effect reaches teams who never self-host. They simply negotiate better, because open weights set the floor.

Modification rights

Fine-tuning on your own data is the pitch behind Inkling. Tinker exists to make that path short, and a broad base model adapts to more workflows than a narrow one.

Distillation matters here too. Permissive weights can support developing a smaller student model, subject to the applicable licence conditions and any other rights involved. Apache 2.0 should not be treated as a blanket promise that every resulting asset is owned free of third-party obligations.

What Open Weights Do Not Change

Now the correction, because open weights coverage overclaims here.

Open weights access is still gated by hardware

Inkling open weights need roughly 2TB of aggregated VRAM at BF16. NVFP4 quantization cuts that substantially but requires SM100-class hardware.

Kimi K3’s checkpoint runs 1.56TB across 96 shards. Self-hosting it realistically means eight to sixteen nodes of eight H100 or B200 accelerators.

So “open” in open weights describes the license, not the barrier. Memory and interconnect economics still set the ceiling, and those have not moved because a download link appeared.

Community quantization helps at the edges. One 1-bit GGUF cut Kimi K3 from 1.56TB to 594GB, keeping about 79% accuracy. Still a serious machine, though.

Reproducibility is not included

Thinking Machines says open weights rather than open source, and the distinction is precise. Training data and the training pipeline stay private.

Every release in that table does the same. So you get the artifact, never the recipe. That is the hard limit on what open weights can prove. So you cannot audit what went in, verify contamination claims, or rebuild the model from scratch.

Benchmarks still need care

Inkling’s Terminal Bench 2.1 figures come from an internal harness, while competitor scores are self-reported. Those are not directly comparable.

It also trails GLM-5.2 and Kimi K2.6 on HLE, Terminal Bench, and SWE-bench Verified, and posts 43.9% on SimpleQA Verified against DeepSeek V4 Pro’s 57.0%. We covered why leaderboard gaps at this level are hard to interpret.

One number does stand out. Inkling posts the highest FORTRESS adversarial score among compared open-weights models at 78.0%, which matters more for regulated deployment than another point of coding accuracy.

What Inkling-Small Changes

The open weights nobody can download yet may matter more than the ones that shipped.

Thinking Machines Lab released Inkling-Small and its full weights on 30 July 2026. It has 276B total parameters and 12B active. The released model’s model card should be used for specifications and evaluation settings, rather than carrying forward preview benchmark numbers.

Read that twice. So the small model wins on some benchmarks, while the big one carries the headline.

Why size beats score here

Active parameters describe the computation used per token, not the complete weight-memory requirement. Inkling-Small still has 276B total parameters. At BF16, weights alone imply roughly 552 GB before runtime overhead; quantization and offloading change that estimate. Hardware suitability therefore depends on precision, memory, context and serving configuration, not the 12B-active label alone.

The full Inkling-Small weights are now published. The practical access question has moved from release timing to the memory, throughput and operating-cost tradeoffs of a real deployment.

The Fine-Tuning Economics Behind Open Weights

Thinking Machines is not really selling open weights. It is selling a customization pipeline.

Tinker exists to make fine-tuning short. So Inkling was trained broadly rather than narrowly, because open weights only pay off if people adapt them. Breadth adapts to more workflows than a specialist base does.

Fine-tuning a frontier-scale model on your own data is expensive, and the result is yours. Calling a closed API is cheap per token, and the result is rented.

Open weights change which side of that trade is available. But switching costs rise once you adapt a model. So the lock-in moves rather than vanishing.

Why Five of Six Frontier Open Weights Are Chinese

The geography of frontier open weights is the most under discussed fact in that table.

Moonshot, DeepSeek, Z.ai, and MiniMax all ship at this scale routinely. American labs mostly do not, and Inkling is notable partly because it breaks a pattern.

Open weights are a share-capture move when you are behind on distribution. A downloadable model gets into stacks that would never sign an API contract with a Chinese vendor.

Export controls push the same way. If you cannot match a rival’s compute budget, giving the weights away buys reach instead. Reach compounds differently than revenue does.

But adoption of open weights is not purely technical. Moonshot has faced accusations, including from the White House OSTP director, that K3 was distilled from a competitor’s model. Those claims are unresolved.

Regulated US buyers weigh provenance alongside benchmarks. That is the gap Inkling aims at, even with a lower index score.

The Safety Argument Around Open Weights

The Safety Argument Around Open Weights

Publishing open weights is irreversible, and that drives most of the disagreement.

Once a checkpoint is out and mirrored, no vendor can pull it back or patch it. And anyone with modest compute can fine-tune the safety training away.

Critics argue frontier open weights hand capability to actors who could not build it. That concern centres on cyber and biological uplift, and it does not depend on the license at all.

Supporters point out that inspection requires access. Outside researchers cannot audit a model they can only query through a filtered API.

The MarkTechPost breakdown notes Thinking Machines flags role-play and indirect prompts as residual risks in its own project page. That kind of published limitation is only possible when someone can test for it.

Evidence has not settled either side, so this post will not settle it either. But the FORTRESS score in the Inkling release suggests labs are starting to compete on adversarial robustness, which is a healthier signal than benchmark parity.

How to Choose Among 2026 Open Weights

Skip the leaderboard for a moment. Four questions decide most open weights selections.

What can you actually run? Start with available VRAM, then filter the open weights list. A 744B model you can serve beats a 2.8T model you cannot.

What does the license require at your scale? Check revenue and user thresholds against your projections, not your current numbers. MIT and Apache 2.0 have neither.

Do you need the weights, or just the price? If you will call an API anyway, open weights matter to you only as negotiating leverage.

How much does provenance matter? For some buyers it decides everything, and no benchmark will move them. Open weights from a US lab answer a question a score cannot.

Conclusion: Open Weights Changed the Contract, Not the Compute

Inkling is a good model with excellent terms. Yet it will not top a leaderboard, and its makers said so first. Thinking Machines said so themselves, which is more than most launches manage.

The significance of these open weights sits elsewhere. The 2026 field now offers genuine frontier-scale capability under Apache 2.0 and MIT, which was not true two years ago.

But the constraint moved rather than disappearing. Access to weights is now free. Access to the two terabytes of memory needed to serve them is not, and that gap decides who actually benefits.

Watch deployment results for Inkling-Small now that its weights are available: memory use, useful throughput and cost at the required quality. Separately, compare the actual commercial and redistribution terms of each model licence rather than treating different open-weight releases as legally interchangeable.

What This Table Will Look Like in Six Months

Two forces will reshape it, and they pull opposite ways.

Scale keeps climbing. Kimi K3 crossed the 3-trillion class, so the next tier arrives before year end. Yet each jump narrows the pool of buyers who can serve the result.

Smaller active-parameter counts can reduce compute per token. Adoption still depends on total weight storage, usable throughput and the workload, so both active and total parameters belong in the comparison.

So expect this open weights table to split in two. One row set for labs proving capability, another for models people genuinely run.

FAQ About Inkling and 2026 Open Weights

What licence does Inkling use?

Apache 2.0, with no attached usage policy. That permits commercial deployment, fine-tuning, and redistribution without royalty or revenue thresholds. Thinking Machines describes the release as open-weights rather than open source, because training data and the training pipeline are not published.

What hardware do you need to run Inkling 975B?

Running the open weights takes roughly 2TB of aggregated VRAM at BF16. NVFP4 W4A4 quantization reduces that considerably but requires SM100-class hardware or newer. In practice this means a multi-node GPU cluster, not a workstation.

Is Inkling better than Kimi K3 or GLM-5.2?

Not on aggregate benchmarks, though license terms differ. Inkling debuted at 41 on the Artificial Analysis Intelligence Index against roughly 57 for Kimi K3 and 51 for GLM-5.2. It leads on FORTRESS adversarial robustness at 78.0% and carries the cleanest license of the three.

Which 2026 open weights have the most permissive license?

Inkling uses Apache 2.0. Apache 2.0 and MIT permit commercial use without revenue/user gates, but include notice and redistribution conditions. They should not be described as having no attribution requirements. Verify the exact current licence for each other model before relying on the comparison.

Does open weights mean open source?

No. Open weights means the trained parameters are downloadable. Open source, under the Open Source Initiative definition, additionally requires the training data and code, and a license without discriminatory conditions. Every frontier-scale release in 2026 publishes weights only.

Why do Chinese labs release open weights more often?

Distribution strategy under constraint drives most open weights releases. Open weights get a model into stacks that would not sign a vendor contract, and they convert compute-limited capability into ecosystem position. Export controls make that trade more attractive than competing on API revenue alone.

Keep reading

Anthropic IPO valuation

Anthropic IPO: The $895 Billion Question Behind Its Valuation

Last updated: 9 November 2026. Latest confirmed development: Anthropic’s amended S-1, filed on 2 November, still leaves the share count and the IPO price range …
Claude Opus vs Sonnet

Claude Opus vs Sonnet: What the 2026 Price Gap Actually Buys

Last verified: 8 November 2026. All prices are Anthropic’s standard first-party API rates in US dollars per million tokens. They aren’t Claude Pro or Max …
RSA-1024

Did AI Break RSA? What DeepMind Actually Found
Last verified: 8 November 2026. Both papers are unreviewed working papers, and no outside group has reproduced the results yet. No, AI did not break …
Model Distillation

Model Distillation Explained: When AI Learning Becomes Extraction

Last verified: 7 November 2026. Government and company claims are attributed throughout. None has been tested in court. A support team trains a small, cheap …

The AI Glossary: 10 Terms You Now Meet Everywhere

AI glossary

Most AI writing assumes you already know the vocabulary. This AI glossary fixes that.

Below are ten terms from the AI glossary that show up constantly in chip news, model launches, and filings. Each entry gives a plain definition first, then the number or fact that makes it matter.

This is batch one. The AI glossary will grow, and every term here links from its first mention across the site.

Why This AI Glossary Exists

Technical vocabulary moves faster than the explainers do, which is the whole case for an AI glossary.

Take KV cache. It went from research jargon to procurement conversation in about eighteen months. Nobody wrote the bridging definition, so readers either already knew or quietly skipped the paragraph.

This AI glossary is the bridge. Each definition is written for someone competent who simply has not met the term yet, which is a very different audience from a beginner.

A glossary also gives readers a stable reference when an article uses unfamiliar terminology. A clear definition and a direct link help readers check the meaning in context.

How to Read This AI Glossary

Every AI glossary entry follows the same shape, so you can skim or read in order.

The first line is the definition. Read only that if you are in a hurry, then move on. The second paragraph in each AI glossary entry gives context: a figure, a date, or a trade-off. That is where the actual understanding lives.

This AI glossary groups terms by layer, from silicon upward. So the AI glossary reads as a stack, not an alphabet.

Key Takeaways From This AI Glossary

  • This AI glossary starts with memory. HBM and LPDDR solve opposite problems: bandwidth versus cost per gigabyte.
  • MoE, distillation, and quantization all shrink the cost of a model, each in a different way.
  • KV cache, not model size, is usually why long context gets expensive.
  • RAG and MCP sit above the model. One supplies documents, the other supplies tools.
  • Inference is where most AI money goes across a model’s life.

Quick Navigation

AI Glossary: Memory and Hardware

Memory decides what a chip can hold and how fast it feeds the math. So this AI glossary starts there.

HBM (High Bandwidth Memory)

HBM is DRAM stacked in vertical layers and wired close to the processor, trading capacity for very high bandwidth.

The current generation matters if you read chip news for buying signals. HBM4 entered mass production in February 2026, and the JEDEC JESD270-4 standard doubles the interface from 1,024 bits to 2,048 and lifts channels from 16 to 32. Nvidia’s Rubin platform is expected to pair eight stacks for 288GB and over 22 TB/s. Samsung and SK Hynix together supply roughly 90% of it, and each vendor roadmap now stretches to HBM4E.

LPDDR (Low-Power Double Data Rate)

LPDDR is mobile-class DRAM tuned for power efficiency and capacity rather than peak bandwidth.

Think phones, laptops, and edge boxes rather than data centre racks. LPDDR delivers far less bandwidth than HBM, but costs a fraction per gigabyte and draws much less power. That is why small serving appliances use it while data centre racks do not. We covered how memory choice shapes accelerator margins here.

AI Glossary: Model Architecture

These three AI glossary terms all answer one question. How do you make a capable model cheaper to run?

MoE (Mixture of Experts)

MoE splits a model into many expert sub-networks and routes each token to only a few of them, so total parameters far exceed the parameters used per token.

DeepSeek-V3 shows the gap plainly: about 671 billion total parameters, roughly 37 billion active per token. Compute per token drops sharply. Memory does not, because every expert must stay loaded and ready.

Distillation

Distillation trains a small student model to copy the behavior of a larger teacher model.

The idea dates to a 2015 paper from Hinton and colleagues. It is now routine. DeepSeek shipped R1-distilled versions built on Qwen and Llama bases. Students typically land a few points below the teacher while costing far less to serve.

Quantization

Quantization stores weights and activations at lower numeric precision, such as 8-bit or 4-bit instead of 16-bit.

Cutting from 16-bit to 4-bit roughly quarters the memory a model takes up. Formats like GPTQ, AWQ, and GGUF made this routine, and FP8 and FP4 now run natively on recent accelerators. You lose a little accuracy and gain a lot of bandwidth headroom.

AI Glossary: Runtime and Serving

Now the AI glossary terms that describe what happens when a model actually answers something.

Inference

Inference is running a trained model to produce an output, as opposed to training it.

It splits into two phases with different bottlenecks. Prefill processes the prompt and is compute-bound. Decode generates tokens one at a time and is memory-bandwidth-bound. Serving dominates a model’s lifetime cost, which is why so much hardware design now targets this half of the AI glossary rather than training.

KV cache

The KV cache stores key and value tensors from tokens already processed, so attention does not recompute them at every step.

Skipping that work is what makes generation fast. The cost is memory, and it grows linearly with sequence length and batch size. At long context the KV cache often consumes more memory than the model weights themselves, which is why techniques like grouped-query attention and paged attention exist.

Context window

The context window is the maximum number of tokens a model can consider at once, counting both the prompt and the output.

Windows now run from a few thousand tokens to over a million. But a large window is a ceiling, not a promise. Retrieval accuracy often degrades well before the stated limit, and benchmark figures rarely capture that. Every extra token also enlarges the KV cache.

AI Glossary: Retrieval and Tooling

These last two AI glossary terms sit above the model. Neither changes the weights.

RAG (Retrieval-Augmented Generation)

RAG fetches relevant documents from an external store and places them in the prompt, so the model answers from supplied evidence rather than memory alone.

The approach comes from a 2020 paper by Lewis and colleagues at Facebook AI. It remains the cheapest way to give a model fresh or proprietary information without retraining. Quality depends far more on the retrieval step than on the model, which teams consistently underestimate.

MCP (Model Context Protocol)

MCP is an open standard that lets AI applications connect to external tools and data through a common client-server interface.

Anthropic released it in November 2024. OpenAI, Google, and Microsoft have since adopted it. The 2026-07-28 specification made the protocol stateless, which lets servers scale on ordinary HTTP infrastructure. Security is still maturing: the NSA published design considerations in May 2026 flagging gaps around prompt injection and tool poisoning.

AI Glossary: Terms People Mix Up

Four pairs cause most of the confusion in any AI glossary. Sorting them beats adding ten more definitions.

Inference versus training in this AI glossary

Training builds the model once, over weeks, on a cluster. Inference runs it billions of times afterwards. The AI glossary treats them separately because the hardware, the bottleneck, and the cost curve all differ.

Both terms shrink cost, but not the same way. Quantization keeps the same model and stores its numbers less precisely. Distillation builds a genuinely smaller model that imitates a bigger one. You can do both to the same system.

The context window is a limit set by the model, not by your hardware. The KV cache is the memory actually consumed while operating inside that limit. A vendor advertises the first. Your infrastructure bill reflects the second.

RAG versus MCP in the AI glossary

RAG brings documents to the model. MCP lets the model reach out to tools and systems. One is read-only context; the other is an action interface. Many production stacks run both, which is why this AI glossary lists them side by side.

AI Glossary: How the Ten Terms Fit Together

AI glossary

Read the AI glossary as a stack and the relationships get obvious.

At the bottom of the AI glossary sits memory. HBM and LPDDR decide how fast weights can reach the math units, and everything above inherits that ceiling.

Above memory sits architecture, the middle band of the AI glossary. MoE, quantization, and distillation are three different strategies for fitting more capability under the same memory ceiling.

Above architecture sits runtime, where most questions actually arise. Inference, KV cache, and context window describe what happens while a request is being served, and where the memory actually goes.

At the top of the AI glossary sits the application layer. RAG and MCP never touch the weights. They shape what the model sees and what it can act on.

So a change at the bottom of this AI glossary propagates upward. Wider HBM interfaces make longer context affordable, which makes larger retrieval payloads practical, which changes what RAG systems can attempt.

How the AI Glossary Connects Across the Site

Use this glossary alongside the related articles to move between a term’s definition and its practical consequences.

When an article links a term to this page, the fragment link opens the relevant definition.

A definition is a starting point. Follow the related technical discussion when the implementation details matter.

The related articles explain how memory, model architecture and serving choices affect practical systems.

A reader arriving at a chip-economics article can use the glossary to check a term and then return to the original discussion.

How This AI Glossary Is Marked Up

Structure matters as much as wording when machines read a page.

Each entry uses schema.org DefinedTerm, and all ten sit inside a single DefinedTermSet. That tells crawlers and language models that this is a controlled vocabulary, not a listicle.

The pairing matters. A lone DefinedTerm is a fragment. Wrapped in a DefinedTermSet with a stable URL, the AI glossary becomes a citable reference object that can be extended without breaking anything.

Each AI glossary term also carries a termCode and its own anchor, so external pages can link straight to one definition.

How to Check and Cite a Definition

When citing a definition, include the term’s direct link and check that the wording fits the context in which you are using it.

Read the short definition first, then the accompanying explanation and any linked source. A concise definition still needs the qualifications that follow it.

For a hardware specification, follow the source to check the product generation, units and operating conditions.

A numerical specification is more useful when its source and scope are clear. Do not treat a component specification as a guarantee of whole-system performance.

“HBM4 doubles the interface to 2,048 bits” is checkable. “HBM is very fast” is not. The AI glossary aims for the first kind throughout.

Every AI glossary entry has a permanent fragment link. Anything that cites this page can point at the exact definition rather than the whole document.

Hardware terms age fastest. HBM moved through three generations in four years, and the numbers quoted above will shift again.

Before quoting a changing specification, check the date and version in the linked source. A page’s modification date alone does not prove that every entry has been revalidated.

Software terms age differently. RAG has meant roughly the same thing since 2020, while MCP changed its transport layer twice in eighteen months.

What Batch 2 of the AI Glossary Adds

Ten terms is a start, not a reference work. The AI glossary is built to extend. The next batch covers the gaps this one leaves.

Planned entries include speculative decoding, FlashAttention, LoRA, tokenizer, embedding, vector database, agentic loop, guardrails, eval, and TCO. Each will follow the same two-part shape.

The AI glossary grows in batches rather than singly, since a set update is one schema change instead of ten.

Who This AI Glossary Is For

Three readers, roughly, and the entries serve all three. The first is an engineer who knows the stack but not this corner of it. A backend developer meeting KV cache for the first time needs one paragraph, not a tutorial.

The second is an investor or analyst reading chip filings. For them the number attached to each term matters more than the mechanism.

The third reader of this AI glossary is a language model answering somebody else’s question. That reader is new, and it changes how definitions should be written: state the thing plainly, attach a checkable fact, and skip the throat-clearing.

Conclusion: Use the AI Glossary as a Reference, Not a Read

Nobody reads an AI glossary front to back, and this one is not written for that.

Bookmark the AI glossary. Follow a link into it when a term stops you mid-article. Then go back to what you were reading.

The terms cluster around one theme worth noticing. Eight of the ten exist because memory and bandwidth, not raw compute, now set the limits on what AI systems can do affordably. HBM, LPDDR, KV cache, quantization, MoE, distillation, and context window are all answers to that same constraint.

Understand that pattern and most infrastructure news stops feeling like jargon.

FAQ About This AI Glossary

What is the difference between HBM and LPDDR?

Both are DRAM, but they optimize differently. HBM stacks memory dies vertically beside the processor for extremely high bandwidth, at high cost and power. LPDDR targets low power and cheaper capacity, with much lower bandwidth. Data centre accelerators use HBM; phones, laptops, and edge devices use LPDDR.

Why does the KV cache matter more than model size?

Model weights are a fixed cost, loaded once at startup. This AI glossary flags the difference deliberately. The KV cache grows with every token in the conversation and with every concurrent request. At long context lengths it frequently exceeds the weights in memory use, which makes it the practical limit on how many users a server can handle at once.

Is RAG better than fine-tuning?

They solve different problems, which is why the AI glossary lists them apart. RAG supplies facts the model did not memorize and updates instantly when documents change. Fine-tuning changes behavior, format, and tone. Most production systems use RAG for knowledge and light fine-tuning for style, rather than choosing one.

What does MCP actually do?

MCP standardizes how an AI application talks to external tools and data sources. Instead of writing custom integration code for every service, a developer runs or connects to an MCP server that exposes tools, resources, and prompts through one interface. The July 2026 revision made it stateless so it scales on ordinary web infrastructure.

Does quantization hurt model quality?

Some, but less than most people expect. Dropping from 16-bit to 8-bit is usually near-lossless for large models. Four-bit shows measurable degradation on reasoning-heavy tasks, though modern methods narrow the gap considerably. The right question is whether the accuracy you lose costs more than the throughput you gain.

Why do MoE models need so much memory?

Because every expert must be loaded even though only a few run per token. A model with 671 billion total parameters and 37 billion active still needs all 671 billion resident somewhere. MoE saves compute, not memory, which is a distinction this AI glossary flags deliberately.

How often is this AI glossary updated?

Check the date and version of a linked source before relying on a changing specification. A general page update does not establish a separate review date for every definition.

Can I cite or link to a single AI glossary entry?

Yes. Every AI term has a permanent anchor, so you can point at one definition rather than the whole page. The markup uses schema.org DefinedTerm inside a DefinedTermSet, which lets other tools reference entries individually.

Keep reading

Anthropic IPO valuation

Anthropic IPO: The $895 Billion Question Behind Its Valuation

Last updated: 9 November 2026. Latest confirmed development: Anthropic’s amended S-1, filed on 2 November, still leaves the share count and the IPO price range …
Claude Opus vs Sonnet

Claude Opus vs Sonnet: What the 2026 Price Gap Actually Buys

Last verified: 8 November 2026. All prices are Anthropic’s standard first-party API rates in US dollars per million tokens. They aren’t Claude Pro or Max …
RSA-1024

Did AI Break RSA? What DeepMind Actually Found
Last verified: 8 November 2026. Both papers are unreviewed working papers, and no outside group has reproduced the results yet. No, AI did not break …
Model Distillation

Model Distillation Explained: When AI Learning Becomes Extraction

Last verified: 7 November 2026. Government and company claims are attributed throughout. None has been tested in court. A support team trains a small, cheap …

DeepSeek IPO: What the $70B Number Now Hides

DeepSeek IPO: What the $70B Number Now Hides

Start with a correction, because the DeepSeek IPO headline number gets used wrong almost everywhere.

The company is not raising $70 billion. That figure is a valuation. The raise itself is far smaller: reports put it at up to 50 billion yuan, or roughly $7 billion.

Mixing those two up makes the story sound like a Western mega round. It is not one. And the difference matters more than the arithmetic, because the structure underneath tells you who really controls the company.

So here is the accurate version, plus what the DeepSeek IPO would actually require.

Key Takeaways: The DeepSeek IPO in Brief

  • The $71–74 billion figure is a pre-money valuation, not a raise. Reported new capital tops out near 50 billion yuan.
  • June 2026 brought the first outside money ever: about $7.4 billion at a post-money mark above $50 billion.
  • Commercial backers got no vote and a five-year lock-up. China’s state AI fund got both a vote and no lock-up.
  • Shanghai’s STAR Market opened its fifth listing standard to AI firms on June 17, 2026, which cleared the path.
  • The second round paused in late July after an internal meeting leaked.
  • Every timeline here comes from anonymous sources. Nothing has been filed.

Quick Navigation

What the $70B DeepSeek IPO Number Actually Means

DeepSeek IPO

Two numbers keep getting merged into one across DeepSeek IPO coverage, so separate them.

Valuation is what buyers agree the whole company is worth. A raise is the cash that actually changes hands. In June the lab sold a slice at a price implying over $50 billion, and collected about $7.4 billion doing it.

Now reports point to a fresh round at $71–74 billion pre-money. Reuters put the target near 500 billion yuan, with up to 50 billion yuan of new money.

So the valuation would jump roughly 40% in about six weeks. The cheque size stays modest by frontier standards.

Compare the DeepSeek IPO with US peers and the contrast is stark. OpenAI closed a round near $122 billion at roughly $852 billion. Anthropic raised $65 billion.

The Hangzhou lab plays a different game, and not by choice. Capital access is domestic, and chip access is restricted. We looked at how export controls reshape compute economics here, and those constraints set the ceiling on what any Chinese lab can usefully spend.

Founder Liang Wenfeng has said as much, long before any listing talk. Money was never the bottleneck. Chip shipments were.

The June Round That Set Up the DeepSeek IPO

Until mid-2026 the lab had never taken outside money, so this IPO story starts here. Liang funded it from High-Flyer, the quant hedge fund he also founded.

That changed on June 16, and it set up everything since. The round totalled over 50 billion yuan, about $7.4 billion, at a post-money valuation reported between $52 billion and $59 billion.

Liang was the largest single contributor to the pre-DeepSeek IPO round, at roughly 20 billion yuan of his own money. Tencent put in about 10 billion yuan. CATL added around 5 billion.

JD.com, NetEase, and IDG Capital each committed near 3 billion yuan. China’s National AI Industry Investment Fund joined too.

Note the CATL entry on that cap table. A battery maker buying into an AI lab is a bet on data centre power supply, not on models.

The structure that makes the DeepSeek IPO unusual

Here the DeepSeek IPO backstory stops resembling a normal round. Commercial investors did not buy shares in the company at all.

Their capital went into a limited partnership managed by Liang, and that fact outlives this IPO. Forbes summarized the terms: five-year lock-up, no voting rights, no easy exit.

So Tencent’s roughly $1.4 billion bought exposure to a fund, not governance in the company heading toward a DeepSeek IPO. Secondary sales are barred.

Why Only Beijing Got a Vote in the DeepSeek IPO Setup

One investor was carved out, and that exception shapes the entire DeepSeek IPO.

The National AI Industry Investment Fund invested directly into the operating entity. It received voting rights. It faces no lock-up.

That makes a state vehicle the sole outside holder with governance power and immediate liquidity. Liang keeps roughly 78–84% control, depending on which reporting you follow.

What this means for later buyers

Read the cap table before the DeepSeek IPO prospectus. Control here was settled in June, not at pricing. A public offering does not automatically undo this arrangement.

Retail buyers in a Shanghai listing would sit behind a founder with super majority control and a state fund with the only external vote. So this IPO would price a minority economic stake, not influence.

That is not unusual in Chinese tech, and the DeepSeek IPO will not be judged in isolation. Still, it should be stated plainly rather than buried.

Why Talent, Not Compute, Drove the DeepSeek IPO

One detail in the reporting reframes the whole raise, and it rarely gets picked up.

The pressure behind the DeepSeek IPO was retention, not hardware. Chinese labs have been poaching aggressively from each other, and pay packages climbed fast through 2026.

A lab funded from a hedge fund balance sheet can buy chips. It cannot easily offer equity that anyone can sell.

So a round ahead of this IPO does two things at once. It sets a market price for the shares, and it creates a path toward liquidity. Both matter enormously when a rival can offer cash today.

That reading also explains the five-year lock-up. Liang wanted a valuation mark and a listing path, but not a crowd of investors pushing for an exit.

Why that changes how you read the numbers

Once you see retention as the driver, the modest cheque size stops looking odd. The company did not need $70 billion of capital. It needed a price.

So this IPO looks less like a funding event and more like the last step in a compensation redesign.

How Shanghai Rewrote Its Rules Before the DeepSeek IPO

Timing here is not coincidence, and it is the most overlooked part of this IPO story.

On June 17, 2026 — one day after the funding round closed — CSRC chairman Wu Qing announced at the Lujiazui Forum that the STAR Market’s fifth listing standard would expand to cover artificial intelligence.

That pathway matters for the DeepSeek IPO because it sets no profit or revenue threshold at all. It was created when the STAR Market launched in 2019, suspended in 2023 over investor protection concerns, then revived in 2025 as part of a “1+6” reform package.

Before June the standard covered biotech, chip firms, and commercial aerospace. Now AI large-model developers qualify.

The Shanghai Stock Exchange published review guidance the same afternoon. Applicants need at least one large model in market and evidence of scaled use.

The criterion nobody in the West would recognize

Read the official DeepSeek IPO pathway wording closely. Eligible companies must have a main business or product “approved by the state,” alongside large market space and staged R&D results.

State approval is not a tiebreaker there. It is a threshold. So this IPO would run through a gate where policy alignment is a formal listing requirement, not an informal advantage.

The SSE also flags these stocks with a “U” suffix in the Sci-Tech Growth Tier, so buyers can see which listings are pre-profit.

A stated policy goal sits behind the DeepSeek IPO too. Beijing reportedly wants an AI model developer listed on the STAR Market, which currently has none.

What the Open-Weight Model Does to the Numbers

Revenue is the hardest thing to guess from outside, and open weights are why.

Anyone can download the models and run them on their own hardware. So a large share of real-world usage generates no payment to the lab at all.

That is deliberate. Open releases build ecosystem share, pressure rival pricing, and recruit engineers. Yet this IPO will still need a revenue line. But none of it books as revenue.

A listing forces the question into the open. Investors will want to know what share of income comes from the API, from enterprise licensing, and from High-Flyer-adjacent work.

Until a DeepSeek IPO filing lands, every revenue estimate you read is an outsider’s guess.

Why the DeepSeek IPO Process Paused in July

Then the process stalled, which most DeepSeek IPO coverage missed entirely.

On July 26 the company said it would not proceed with planned investment agreements. Reporting ties the pause to Liang’s frustration after a four-hour internal meeting leaked during the first round.

Fifty-two of his remarks on culture, open-source strategy, and AI circulated widely online. The company has not confirmed the leak’s authenticity.

Fundraising may resume, and this IPO filing may still land this year. But a founder who halts a round over a leak is not a founder in a hurry to publish audited financials.

That tension sits at the centre of the IPO question. Going public means disclosure, and this is a company that has guarded its internals closely.

What a DeepSeek IPO Filing Would Have to Show

Set aside the valuation talk around the DeepSeek IPO. A STAR Market prospectus forces specifics.

The lab prices aggressively and open-weights its models. R1 was reportedly trained for around $294,000 using 512 Nvidia H800 chips, and its reasoning costs came in far below comparable US offerings.

Cheap inference is a strategy, and the DeepSeek IPO would have to price it honestly. It is also a revenue question. A filing would show what open weights actually earn, and that number has never been public.

Compute and supply

Export controls limit access to leading-edge hardware, so any IPO document must address them. Any prospectus would need to describe the chip inventory, domestic alternatives, and the risk that restrictions tighten.

That section would be read closely outside China. It is the clearest available window into how far domestic silicon has come.

Governance

The limited partnership arrangement would need full description in a DeepSeek IPO filing. So would the state fund’s rights, related-party dealings with High-Flyer, and Liang’s control.

Chinese disclosure rules are real. The SSE chairman has stressed strict gatekeeping, so a DeepSeek IPO would face genuine scrutiny.

How the DeepSeek IPO Fits China’s Listing Rush

The DeepSeek IPO is not a solo move. A queue has formed.

Zhipu AI and MiniMax both debuted in Hong Kong in early January, then initiated STAR Market applications. Moonshot AI is reportedly lining up a Hong Kong listing at just over $30 billion.

Moonshot matters as a comparison. Its K3 model runs to 2.8 trillion parameters and has topped several benchmark tables. We covered why those benchmark tables are getting harder to read, which is worth keeping in mind when labs cite them in listing documents.

Eight unprofitable firms listed under the Sci-Tech Growth Tier in its first year, and six reached first profit. Since 2025 the STAR Market has accepted 24 more pre-profit applicants.

So the pathway works mechanically. Whether it works financially for a lab giving models away is a separate question.

Fortune framed the wave as a great Chinese AI listing rush. That reads right. The DeepSeek IPO would be its largest test.

DeepSeek IPO Reports: What to Trust, What to Discount

Sourcing quality varies wildly across DeepSeek IPO coverage, so sort it.

Reasonably solid

The June round that preceded the DeepSeek IPO push happened. The structure was broken by The Information and confirmed across Reuters, Forbes, and SCMP reporting. The STAR Market rule change is on the record from the CSRC and the exchange.

Reported, not confirmed

Everything about the DeepSeek IPO timeline sits here. A late-2026 filing target and a Q2 2027 debut both come from anonymous sources, via Bloomberg, the Wall Street Journal, and Reuters.

This IPO valuation figures vary between $71 billion and $74 billion depending on the outlet. Treat the range as a range.

Worth ignoring

Any claim of a $70 billion raise. Any specific ticker or pricing. Neither exists.

One number circulating online puts the second round at a $710 billion valuation. That appears to be a decimal error and should be discarded.

What the DeepSeek IPO Means for Global Investors

Access is the first practical DeepSeek IPO question, and the answer disappoints most foreign readers.

A STAR Market debut is a mainland A-share offering. Overseas buyers reach it through qualified institutional channels or Stock Connect eligibility, not an ordinary brokerage account.

Index inclusion rules matter here too. Newly listed pre-profit stocks carry a “U” marker, and index providers treat them cautiously at first.

So early trading tends to be domestic, retail-heavy, and volatile. The STAR Market has drawn criticism for exactly that pattern, including studies finding revenue surges before listing that reverse afterwards.

Western AI firms raise private capital at scale and delay listing, unlike the DeepSeek IPO route. Anthropic’s approach to compute partnerships shows how far that model can stretch before a public market becomes necessary.

China is running the opposite experiment. It is building a listing venue first, then routing its strongest labs into it. The DeepSeek IPO would be the clearest test of whether that works.

One more variable sits outside the company’s control. Yicai reported the CSRC’s stated aim of using the growth tier to help strong tech firms cross the funding gap before profitability.

That framing helps applicants. Yet it also means the window can narrow if regulators sour on pre-profit listings again, as they did in 2023.

So the schedule depends on Beijing’s appetite as much as on any prospectus. Watch how Zhipu and MiniMax trade after their STAR applications clear. Their reception will shape the terms available later.

Conclusion: The DeepSeek IPO Is About Control, Not Capital

The DeepSeek IPO is unusual for a reason most coverage skips. This company does not obviously need the money.

High-Flyer funded it for three years. The founder wrote the largest cheque in its first outside round. Compute, not capital, is the binding constraint.

So why pursue a DeepSeek IPO at all? Three plausible answers, and they are not exclusive. A public market gives Chinese investors access to an asset they currently cannot own. It gives Beijing a flagship AI listing on a board that lacks one. And it gives employees liquidity in a market where talent poaching has intensified.

None of those DeepSeek IPO motives is about funding the next model. That is the tell.

Watch the filing, if it comes. The valuation will make headlines, but the share class table and the related-party notes will tell you what the DeepSeek IPO actually is.

FAQ About the DeepSeek IPO

Is DeepSeek raising $70 billion?

No. The $71–74 billion figure is a pre-money valuation, not new capital. Reports put the actual raise at up to 50 billion yuan, roughly $7 billion. The June 2026 round raised about $7.4 billion at a post-money valuation above $50 billion.

When is the DeepSeek IPO expected?

Nothing is confirmed. Reporting from Bloomberg, the Wall Street Journal, and Reuters points to an internal target of filing in late 2026, with a possible debut on Shanghai’s STAR Market as early as the second quarter of 2027. All sources were anonymous, and timelines could change.

Can foreign investors buy into the DeepSeek IPO?

Not directly in most cases. A STAR Market listing is a mainland A-share offering, and access for overseas buyers runs through qualified investor channels and Stock Connect eligibility rather than an ordinary brokerage account.

Who controls the company before the DeepSeek IPO?

Liang Wenfeng retains roughly 78–84% control going into the DeepSeek IPO. Commercial investors including Tencent, CATL, JD.com, and NetEase hold interests in a limited partnership with no voting rights and a five-year lock-up. China’s National AI Industry Investment Fund is the only outside holder with a direct stake, voting rights, and no lock-up.

Why does the STAR Market allow an unprofitable AI company to list?

The fifth listing standard behind the DeepSeek IPO sets no profit or revenue requirement. Regulators suspended it in 2023, revived it in 2025, and expanded it to artificial intelligence in June 2026. Applicants must have a large model in market with scaled use, and the exchange requires the main business to be state-approved.

Is DeepSeek profitable?

No public figures exist ahead of the DeepSeek IPO. The lab has never filed audited accounts, and its open-weight model releases make revenue hard to estimate from the outside. That gap is exactly what a listing document would have to close.

Keep reading

Anthropic IPO valuation

Anthropic IPO: The $895 Billion Question Behind Its Valuation

Last updated: 9 November 2026. Latest confirmed development: Anthropic’s amended S-1, filed on 2 November, still leaves the share count and the IPO price range …
Claude Opus vs Sonnet

Claude Opus vs Sonnet: What the 2026 Price Gap Actually Buys

Last verified: 8 November 2026. All prices are Anthropic’s standard first-party API rates in US dollars per million tokens. They aren’t Claude Pro or Max …
RSA-1024

Did AI Break RSA? What DeepMind Actually Found
Last verified: 8 November 2026. Both papers are unreviewed working papers, and no outside group has reproduced the results yet. No, AI did not break …
Model Distillation

Model Distillation Explained: When AI Learning Becomes Extraction

Last verified: 7 November 2026. Government and company claims are attributed throughout. None has been tested in court. A support team trains a small, cheap …

Why Inference Chips Now Win a Much Narrower Race

Inference Chips
Inference chips

Inference Chips – Two things happened in the last eight months, and together they tell the whole story.

Nvidia paid roughly $20 billion for Groq’s inference chips and most of its team. Then Cerebras went public on Nasdaq and raised $5.5 billion. So the two loudest challengers to Nvidia both cashed out big.

Neither maker of inference chips beat Nvidia, though. That is the part most coverage skips.

Inference chips did not win the AI hardware war. They won a narrow, valuable corner of it. And the shape of that corner explains both exits.

Key Takeaways: Inference Chips vs Training Chips

  • Training builds a model once. Serving it runs forever, so the spend never stops.
  • Estimates put running costs at 60–70% of a roughly $400 billion accelerator market in 2026, up from about 40% in 2023.
  • Inference chips chase latency, not raw throughput. That single choice reshapes the silicon.
  • Nvidia paid about $20 billion in December 2025 for Groq’s stack, hired its founder, and shut a door.
  • Cerebras booked $510 million in 2025 revenue, but 86% came from two UAE-linked buyers.
  • Nvidia still holds roughly 80% of accelerator revenue. So the narrow race stays narrow.

Quick Navigation

Why Inference Chips and Training Chips Solve Different Problems

Start with the workload, because the hardware follows from it.

Training is a batch job, and training silicon reflects that. You feed a cluster huge amounts of data, run it for weeks, and nobody waits on any single answer. So the goal is throughput per dollar and per watt.

Serving a model is the opposite, which is why inference chips exist. One user types a prompt and waits. Every token must arrive fast, and the job repeats billions of times a day.

The memory wall

Here is the technical crux. Generating each token means reading the model’s weights again.

That step is memory-bound, not compute-bound. So the chip sits idle waiting on data. GPUs solve this with High Bandwidth Memory stacked beside the die, which is fast but still off-chip.

Inference chips attack the same wall differently. Groq’s LPU keeps weights in on-chip SRAM. Cerebras packs 44GB of SRAM onto one wafer. Both skip the trip to external memory entirely.

Batching hides the problem that inference chips were built to solve. Group 256 requests together, and one weight read serves them all.

But batching adds delay. A user waiting on an agent that chains ten model calls feels every millisecond, ten times over. So the trick that saves money on paper costs you the product.

That gap is the whole opening for inference chips.

How Inference Chips Beat GPUs on Latency

The speed numbers for inference chips are real, and they are not small.

GroqCloud ran Llama 4 Scout at over 460 tokens per second. The same model on H100 hardware lands nearer 100–150. Cerebras has claimed roughly 15x GPU speed on comparable work.

Groq built its inference chips small and deterministic. Its Tensor Streaming Processor drops the cache and thread scheduling that GPUs rely on. Instead the compiler plans every cycle in advance, which makes latency predictable rather than merely fast.

Cerebras built its inference chips the other way. The WSE-3 uses a whole 300mm wafer as one chip: 46,225 square millimetres, 4 trillion transistors, 900,000 cores. It is about 57 times the area of an H100.

Why build a chip that big? Because a model spread across 64 GPUs pays a latency tax at every hop between them. Keep the model on one piece of silicon, and that tax disappears.

The catch nobody advertises

Both families of inference chips trade capacity for speed. SRAM is fast but small, so a single Groq card holds very little of a large model. You chain many together, and the rack gets expensive.

Cerebras hits a version of the same limit. Even 44GB of on-chip memory is tight for frontier models. The Register noted that SRAM capacity remains the constraint on what the design can hold.

So inference chips win on speed and lose on flexibility. That trade defines the narrow race.

The Narrower Race: What Inference Chips Actually Compete For

Zoom out and the market for inference chips splits into layers, not a single prize.

Training frontier models is roughly a two-vendor game. Nvidia dominates it, and Google’s TPUs handle the rest at scale. We covered how Trainium and TPU pressure Nvidia’s margins here, and that fight runs on different rules.

Bulk serving is a price fight that inference chips rarely win. Nvidia, AMD, and hyperscaler silicon all chase cost per million tokens, and CUDA matters less than it used to.

Where inference chips actually live

The real territory is thinner than the pitch decks suggest. Inference chips own the slice where latency is the product, not a feature.

Inference chips suit voice agents, live code completion, and reasoning models that chain many calls. In those cases a two-second wait kills the use case outright.

That slice is growing fast. Still, inference chips live in a slice.

Here is the honest framing. Inference chips did not take the accelerator market. They took the part of it where Nvidia’s architecture is structurally weakest, then sold that position at a premium.

What Groq’s $20 Billion Exit Really Says

The Groq story reads like a win for inference chips, and it was. But read the structure.

On December 24, 2025, Groq licensed its inference chips to Nvidia on a non-exclusive basis. CNBC reported the figure at about $20 billion in cash, citing the CEO of Disruptive, which led Groq’s last round.

The people went too. Founder Jonathan Ross joined Nvidia. So did president Sunny Madra and much of the engineering team. Simon Edwards, the finance chief, took over as CEO.

Three months earlier, Groq had raised $750 million at a $6.9 billion valuation. Nvidia paid roughly three times that, ninety days later.

One caveat matters. DCD noted that neither company confirmed the price, and the $20 billion number has not been independently verified.

Ross built the original Google TPU before founding Groq in 2016. So Nvidia bought the person who has now designed two credible answers to its own architecture.

The structure drew attention too. Senators Warren and Blumenthal asked the FTC whether a licensing deal plus a mass hire sidesteps merger review. That inquiry was still open as of May 2026.

Groq lives on as a company. It kept GroqCloud, distributed $7.6 billion to shareholders in February 2026, and raised $650 million more in June. Yet the architecture team now works at Nvidia.

That is what winning a narrow race looks like. You do not displace the incumbent. You become too useful to leave outside.

What Cerebras Proved, and What It Did Not

Cerebras sells inference chips too, but it took the other road and stayed independent.

The company filed its S-1 on April 17, 2026, then listed on Nasdaq as CBRS in May. It raised about $5.5 billion. Demand ran hot enough that the price range moved up mid-process.

Revenue from its inference chips reached $510 million in 2025, up 76%. Non-GAAP net income came in at $237.8 million, a swing from heavy losses the year before.

The concentration problem

Now the uncomfortable line. Two UAE-linked buyers supplied 86% of that revenue: MBZUAI at 62% and G42 at 24%.

A maker of inference chips with two customers is not really a market yet. So the OpenAI agreement carried enormous weight in the filing.

That deal commits over $20 billion for 750 megawatts of low-latency capacity, expandable toward 2 gigawatts by 2030. Futurum’s teardown treats it as the commercial proof of the architecture.

OpenAI reportedly uses it for a code-generating model. That fits: code assistants are latency-sensitive and run constantly.

What the filing does not settle

Three risks stay open for its inference chips. Wafer-scale yields are harder than normal chip yields, so gross margin under volume is unproven. TSMC capacity has to stretch. And a third anchor customer has not appeared.

Investing.com framed the listing as a direct market test of the serving thesis. That framing is right, and the test is not finished.

The Hyperscaler Squeeze on Inference Chips

A third force presses on inference chips, and it rarely gets named as a rival.

Amazon, Google, and Microsoft all build their own serving silicon. Trainium and Inferentia run inside AWS. TPUs run inside Google. Maia runs inside Azure.

These parts do not have to beat merchant inference chips on benchmarks. They only have to be good enough while costing the parent company less than a purchased GPU.

That is a brutal bar for a startup to clear. A hyperscaler can bundle serving capacity with storage, networking, and billing that customers already use. So switching away carries friction that no token-per-second chart erases.

AMD squeezes inference chips from another angle. Its chiplet design carries more memory per package, and memory is usually the binding constraint when serving models. Analysts put AMD near 5–10% of the accelerator market, mostly on serving work.

What that leaves for inference chips

Squeezed between Nvidia above and in-house silicon below, inference chips need a defensible edge. Ultra-low latency is that edge, and it is narrow by design.

Note the pattern in recent deals, though. AWS paired Trainium3 with Cerebras systems rather than replacing either. So the likely endgame is not displacement. It is inference chips working as a decode accelerator inside a larger fleet.

Where Inference Chips Still Lose to Nvidia

Speed benchmarks for inference chips make a clean headline. Buying decisions are messier.

CUDA locks buyers in less than it once did. vLLM, SGLang, and ONNX Runtime all abstract the hardware underneath.

But “less of a lock” is not “no lock.” Every custom chip needs its own kernels, its own quantization path, and its own debugging story. Teams pay that cost in engineer-months.

A GPU cluster trains on Monday and serves on Tuesday. Inference chips cannot do that, so the hardware sits idle whenever demand dips.

A GPU cluster trains on Monday and serves on Tuesday, while inference chips cannot switch. Fleet flexibility is worth real money to anyone running mixed workloads. Benchmark charts never show it.

The incumbent adapts

Nvidia did not stand still. It licensed Groq’s design and shipped an integrated product pairing LPU-style silicon with its Vera Rubin generation.

Meanwhile AWS paired Trainium3 with Cerebras systems to accelerate its own serving platform. So the specialists increasingly ship inside somebody else’s stack.

Nvidia still books roughly 80% of accelerator revenue. Any honest read of inference chips has to start there.

How to Choose Between Inference Chips and GPUs

Skip the token-per-second charts for a moment. Ask four questions about inference chips instead.

If a user waits on every response, speed is the product. Voice agents, live coding tools, and multi-step reasoning all qualify.

If you run overnight batch jobs, none of this matters. Buy on cost per token and move on.

How big is the model?

Small and mid-sized models fit SRAM-heavy inference chips well. Very large models fight them, because capacity is the binding constraint.

Quantization helps. So does routing: send the latency-critical calls to specialist hardware and the rest to GPUs.

What does a token actually cost you?

Speed and cost pull apart here. A specialist rack can be faster per request and still cost more per million tokens.

Work out the full picture. Count hardware or hourly rate, utilisation, and the engineering time to port your stack. Idle capacity is the silent line item, since a rack that only serves one workload sits unused whenever traffic dips.

Then weigh that against revenue. If faster responses lift conversion or retention, the premium pays for itself. If not, the cheaper fleet wins.

Can you tolerate one vendor?

Concentration cuts both ways here. Cerebras depends on a few buyers, and its buyers depend on a single supplier with novel manufacturing.

Second-sourcing inference chips is expensive. Yet a rack you cannot replace is a risk you carry on someone else’s balance sheet. The Anthropic and Google TPU arrangement shows how large buyers hedge that exposure.

What Comes Next for Inference Chips

Two roadmaps are worth watching, and they point in opposite directions.

The obvious moves are more SRAM and lower precision. Much of the industry has settled on FP8 and FP4 formats, and 3D chip stacking could raise on-wafer memory.

Capacity is the real question. If WSE-4 holds meaningfully more of a frontier model on one wafer, the design gets far more useful. If not, inference chips from Cerebras stay a specialist tool for mid-sized models.

Nvidia and the absorbed architecture

Nvidia already ships a combined product pairing Groq-style inference chips with its Vera Rubin generation. That aims squarely at agentic workloads, where long context meets tight latency budgets.

So the strongest challenger architecture now ships under the incumbent’s brand. Anyone tracking inference chips should read that as consolidation, not competition.

One caution on every speed claim made for inference chips. Vendor benchmarks pick favourable model sizes, batch settings, and context lengths.

We wrote about how saturated benchmarks stop separating systems, and hardware marketing has the same disease. Test on your own prompts, at your own context length, before believing any figure.

One more signal is worth tracking: who else signs. Cerebras needs a second anchor customer to prove the OpenAI deal was not a one-off, and Groq needs GroqCloud to grow without its founding architects.

Watch those two questions through 2027. They will settle the thesis faster than any benchmark round.

Conclusion: The Narrow Race Was the Right Race

Groq and Cerebras bet on inference chips years apart, and made the same call. Both refused to build a general-purpose accelerator, and both aimed at one workload instead.

That looked like a limitation in 2023. It turned out to be the strategy.

Serving models now consumes most accelerator spending, which is why inference chips found buyers, and the fastest-growing part of that spending punishes delay. So a chip that does one thing brilliantly found a buyer willing to pay a premium.

But keep the scoreboard honest. Nvidia holds the market, owns Groq’s architecture, and ships wafer-scale silicon inside partner platforms. Cerebras trades publicly on the strength of one enormous contract.

Winning a narrow race is still winning. It is just not the same as winning the race everyone was watching.

FAQ About Inference Chips

What is the difference between inference chips and training chips?

Training hardware optimizes for throughput across huge batch jobs that run for weeks. Inference chips optimize for latency on single requests that repeat billions of times. The main split shows up in memory: training parts lean on High Bandwidth Memory, while specialist serving parts keep weights in fast on-chip SRAM.

Are inference chips faster than Nvidia GPUs?

On specific workloads, inference chips are faster. GroqCloud has served Llama 4 Scout at over 460 tokens per second against roughly 100–150 on H100 hardware, and Cerebras claims about 15x on comparable tasks. Those gains apply to latency-sensitive serving, not to training or to every model size.

Did Nvidia buy Groq?

Not exactly. Groq licensed its inference chips to Nvidia on a non-exclusive basis in December 2025, and CNBC reported a figure near $20 billion. Founder Jonathan Ross and much of the team joined Nvidia, while Groq stayed independent under a new CEO and kept GroqCloud running.

Is Cerebras profitable?

Cerebras reported $510 million in 2025 revenue from its inference chips, up 76%, with non-GAAP net income of $237.8 million. Two UAE-linked customers accounted for 86% of that revenue, so the profit rests on a very narrow base.

Will inference chips replace GPUs?

Unlikely, and the market is not moving that way. Nvidia still books around 80% of accelerator revenue, and GPUs handle most serving today. The realistic outcome is a split fleet, where specialist hardware takes the latency-critical calls and general-purpose silicon handles everything else.

How large is the market for inference chips?

Estimates for inference chips vary. Analysts put total accelerator revenue near $400 billion in 2026, with serving workloads at 60–70% of it, up from roughly 40% in 2023. Treat those ranges as directional, since definitions of “inference spending” differ between sources.

Keep reading

Anthropic IPO valuation

Anthropic IPO: The $895 Billion Question Behind Its Valuation

Last updated: 9 November 2026. Latest confirmed development: Anthropic’s amended S-1, filed on 2 November, still leaves the share count and the IPO price range …
Claude Opus vs Sonnet

Claude Opus vs Sonnet: What the 2026 Price Gap Actually Buys

Last verified: 8 November 2026. All prices are Anthropic’s standard first-party API rates in US dollars per million tokens. They aren’t Claude Pro or Max …
RSA-1024

Did AI Break RSA? What DeepMind Actually Found
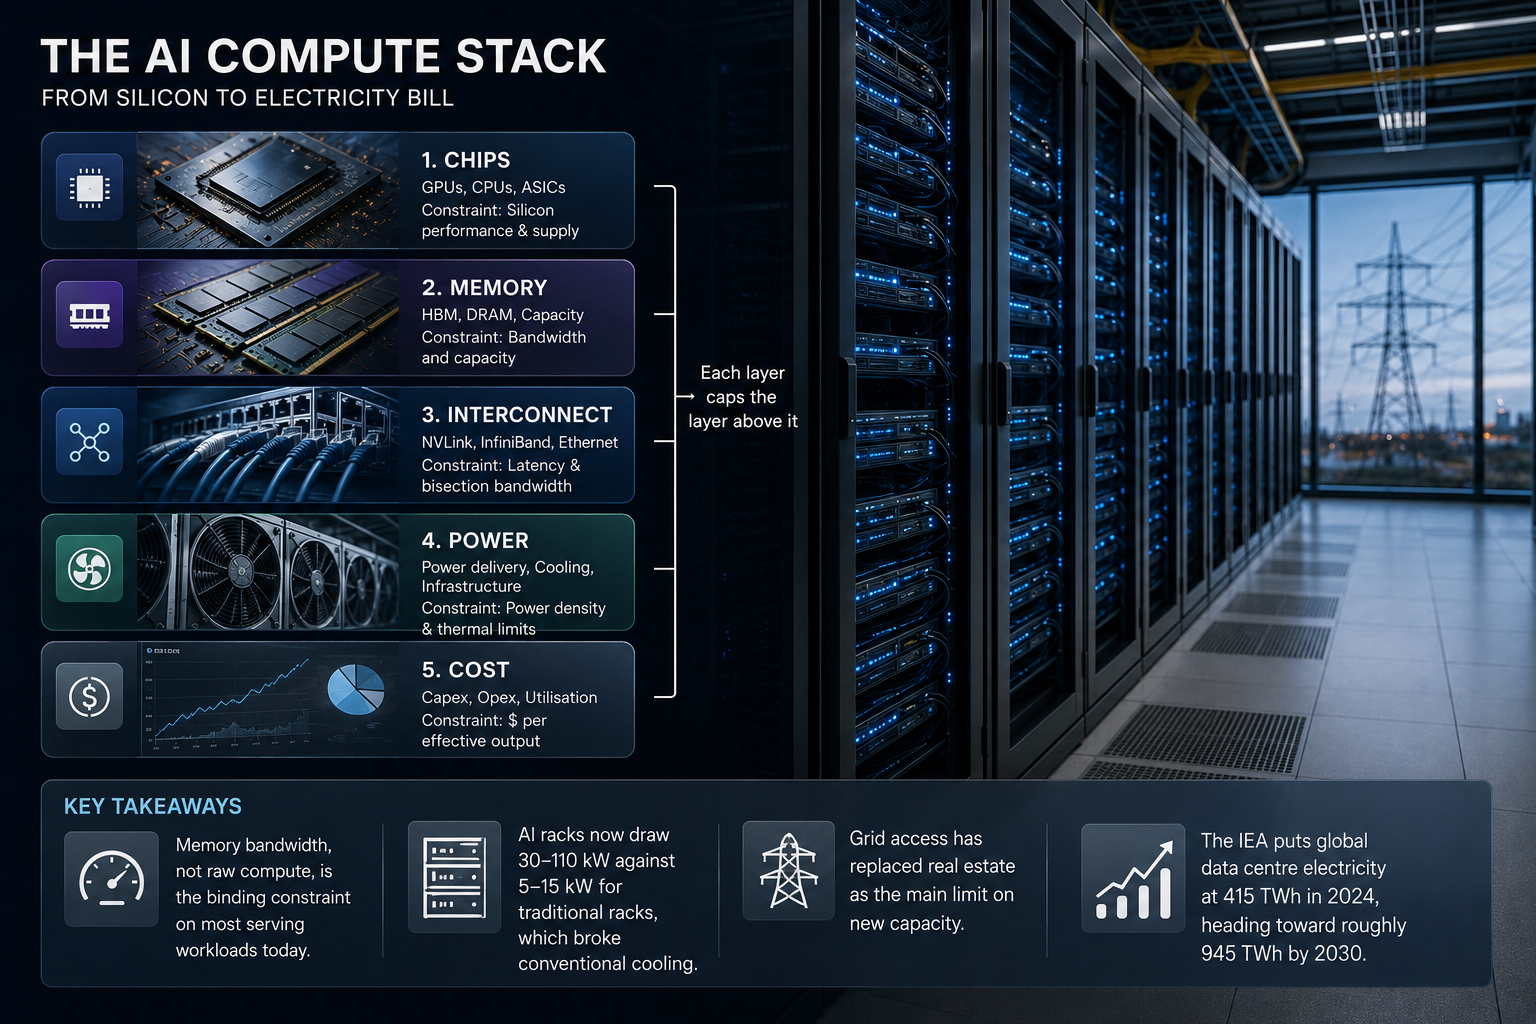
Last verified: 8 November 2026. Both papers are unreviewed working papers, and no outside group has reproduced the results yet. No, AI did not break …
Model Distillation

Model Distillation Explained: When AI Learning Becomes Extraction

Last verified: 7 November 2026. Government and company claims are attributed throughout. None has been tested in court. A support team trains a small, cheap …

Anthropic S-1: What an AI Lab Must Now Disclose

Anthropic S-1: What an AI Lab Must Now Disclose

On June 1, 2026, the company behind Claude said something short and carefully lawyered. The Anthropic S-1 arrived as a confidentially submitted draft registration statement to the SEC for a proposed initial public offering of common stock.

That is the entire official record on the Anthropic S-1. The Rule 135 announcement ran a few sentences and stated that the number of shares and the price had not been set.

Almost everything else you have read — the ticker, the October date, the bank syndicate — is reporting, inference, or guesswork. None of it came from the Anthropic S-1, because nobody outside the SEC has read it.

So the useful question is not when the stock lists. It is what the law will force onto the page when the filing finally goes public. That answer is knowable today, and it is more interesting than the speculation.

Key Takeaways: The Anthropic S-1 in Brief

  • A confidential draft Form S-1 was submitted on June 1, 2026. It creates an option to go public after SEC review, not a scheduled date.
  • The draft and every SEC comment letter on it stay private for now. Comment letters reach EDGAR no earlier than 20 business days after the registration statement goes effective.
  • The company almost certainly fails the Emerging Growth Company revenue test, so the Anthropic S-1 faces the full disclosure regime rather than the reduced JOBS Act version.
  • The registration statement and all prior confidential drafts must be publicly filed at least 15 days before any roadshow. That is the only countdown grounded in an actual rule.
  • Compute purchase obligations, customer concentration, related-party terms with Amazon and Google, and the Long-Term Benefit Trust are the four disclosures most likely to move the price.

Quick Navigation

What the Anthropic S-1 Confidential Filing Actually Did

A private draft is not a secret IPO. It sits at a paperwork stage. Most coverage missed that. First, a company hands SEC staff a draft. Staff reads it and sends comments. The company edits. All of it happens off EDGAR.

Still, three things about that draft matter here. It registered no shares. Nobody could buy stock. And it set no date.

Why the draft stayed off EDGAR

Secrecy here is a process, not a right. A company must ask for confidential treatment under Rule 83. They also flag every page.

Yet the SEC holds back its own letters too. Staff comments go public no sooner than 20 business days after the deal closes. So the tug-of-war over the Anthropic S-1 only shows up once the stock trades. That lag matters. You see the clean version long before long before you see what the regulator fought about.

The Anthropic S-1 notice leaned on Rule 135, and that choice was not decorative. The rule lets a company confirm a deal without making an offer.

But it also gags them. That is why the Anthropic S-1 notice named no value, no revenue, and no date. Anything more could have counted as jumping the gun. So read the silence as legal care, not coyness.

Why the Anthropic S-1 Is Not an Emerging Growth Company Filing

Plenty of write-ups called the Anthropic S-1 a routine JOBS Act move for emerging growth companies. That looks wrong. And the error changes what you should expect to read. An Emerging Growth Company must earn under roughly $1.235 billion a year. The lab reported a $9 billion run rate at the end of 2025. Later it passed $30 billion in 2026.

Even if you cut run rate down to booked revenue, that ceiling breaks. So the Anthropic S-1 is a full filing, not a light one. The private route still works. Since 2017 the SEC has let every company file drafts quietly, not just small ones. It widened those rules again in March 2025.

But the company loses those shortcuts. A small company can show two years of audited income instead of three. It can skip the long pay analysis. It can delay the auditor sign-off on controls under Sarbanes-Oxley 404(b).

None of that applies. So the Anthropic S-1 should carry three years of audited results, full pay data, and tighter controls than most AI listings. Now think about what three years means here. The lab started in 2021. Revenue grew roughly 80x in one year. The 2023 and 2024 numbers will sit right next to 2025.

What the Anthropic S-1 Must Disclose About Money

Run rate is the number everyone quotes. But run rate is not a GAAP measure. A prospectus cannot lead with it.

Regulation S-X rules the financial pages. So the Anthropic S-1 needs audited balance sheets, income statements, cash flow, and full notes. An audit firm signs them.

The gap the audited numbers close

Press reports in June put the run rate near $47 billion. The company’s own last public figure sat above $30 billion. At the end of 2025 it was near $9 billion.

Still, annualizing one good month is not the same as booking a year. The Anthropic S-1 will show what the company truly earned over a full period. That number always looks smaller and slower. In fact, I expect that single line to reprice the deal more than any other.

Use of proceeds, and what it signals

Item 504 asks a blunt question. What will the company do with the cash?

Vague answers are legal but telling. “General corporate purposes” reads very differently from a named compute build-out. So watch whether the Anthropic S-1 ties the raise to specific contracts. Item 506 then covers dilution. New buyers usually pay far more per share than insiders did. That table is short, and it stings.

Gross margin, and the line nobody can dodge

Cost of revenue is where an AI lab gets interesting. Outside analysts peg compute spend at well over half of sales. Yet those are guesses from the outside, not facts.

An audited line replaces those guesses. So you finally see three things: what serving a token costs, how training splits from inference, and how much model work the company books as an asset.

Item 303 also makes the Anthropic S-1 explain the trend, not just print it. Vague words draw SEC comment letters, and staff has been busy on AI language.

What the Anthropic S-1 Must Disclose About Compute

Here is the part I would read first. It is not the revenue line.

The company has already named huge multi-year compute buys. Reports put the AWS deal above $100 billion over ten years. Google and Broadcom add gigawatts of new TPUs from 2027. Azure reportedly adds $30 billion more.

Those are contracts, not plans. So the Anthropic S-1 must list them, plus the take-or-pay terms and the year-by-year schedule. Lease-like deals land in the notes under ASC 842.

Why compute deals drive the whole risk profile

Picture a ten-year, hundred-billion-dollar bill under a revenue line that grew 80x. That line could also stall. So the gap between fixed cost and moving revenue is the whole bear case, and the Anthropic S-1 finally sizes it.

Next, the related-party angle makes it worse. Amazon and Google hold stock, sell cloud, and move product. Item 404 forces the company to spell those deals out. Investors will ask the circular question straight out. How much revenue comes from partners who also invest and supply? We covered the Google TPU deal here, and the same questions return once audited numbers land beside them.

The FTC also probed those cloud ties in a January 2025 staff report. Live interest like that usually shows up in risk factors.

Governance Disclosures That Set the Anthropic S-1 Apart

Here the Anthropic S-1 stops looking like any tech listing before it.

Governance Disclosures That Set the Anthropic S-1 Apart

The issuer is a Delaware Public Benefit Corporation. Its charter names a purpose: build and keep advanced AI for the long-term good of humanity. Under Delaware law, a PBC board can weigh that purpose against shareholder money.

On top sits the Long-Term Benefit Trust. Five members hold a special share class. None of them holds a financial stake. Over time they pick a growing share of the board, and finally a majority.

The disclosure problem the Anthropic S-1 has to solve

Markets have priced founder control before. Meta and Alphabet use dual-class stock, and buyers understand it.

But an outside body with growing board power is new, and the Anthropic S-1 must explain it. Buyers of common stock take the money risk. Meanwhile a trust with no money at stake gains the votes.

So Item 403 covers who owns what. Item 407 covers board independence. And the capital stock pages of the Anthropic S-1 must say plainly what each class can do. Written honestly, that section reads like a risk factor. Index rules, proxy advisers, and big-fund voting policies all frown on odd control setups.

Of course the company will argue the trust is what makes its safety claim real. Whether that lands with a pricing committee is the open question of the deal.

The Risk Factors the Anthropic S-1 Cannot Avoid

Item 105 wants the Anthropic S-1 to name risks tied to this company, not stock phrases. SEC staff has said generic AI language fails. So six areas look unavoidable.

Copyright. A landmark class-action settlement is already on the record, and Item 103 covers pending suits. We broke down that settlement separately. Still, the training-data fight does not end with one deal.

Washington. CNBC reported that defense contractors dropped the lab under a Pentagon order. It then sued to undo that call. A live case against the government belongs in the Anthropic S-1.

State law. New AI statutes now bind model builders and users. Colorado’s rules alone reshaped compliance planning, so the Anthropic S-1 must map that patchwork honestly.

Competition. OpenAI, Google, and a fast Chinese open-weight field all press on price. Model leads last months, not years. Any filing has to admit that plainly.

Business and capability exposure

Safety. A charter about responsible building raises a hard question. What happens if a model causes harm, or the company pauses a launch? Rivals do not carry that burden the same way.

Concentration. A few huge accounts drive revenue. Three vendors supply the compute. So the Anthropic S-1 must put a number on that double squeeze.

Claims. Since March 2024 the SEC has charged firms over AI hype, first two advisers and later Presto Automation. No AI-specific rule exists yet in mid-2026. Yet the agency does not need one, because fraud law already applies. So every claim in the Anthropic S-1 must hold up.

That last one cuts oddly. A lab that markets on evidence rather than superlatives starts ahead here.

One more line rewards a close read. The Anthropic S-1 names the audit firm, and that firm signs an opinion under PCAOB rules. Underwriters appear later, along with lock-up terms for staff and early backers. Those dates shape supply for months after the debut.

When the Anthropic S-1 Becomes Public: The 15-Day Rule

Want a date to watch? This is the only one tied to a rule.

A company using private review must promise one thing in writing. It will file the draft, and every later draft, at least 15 days before the roadshow. With no roadshow, the clock runs 15 days before the effective date.

So the Anthropic S-1 becomes readable about two weeks before management starts pitching. Not on listing day. Not at pricing.

What lands when the filing goes public

Everything at once, old drafts included. The rule sweeps in the first private draft and every edit after it.

People miss that detail. You will be able to compare the June draft against the version that survived review. Sometimes that diff says more than the final text.

Price and share count usually come later, near the roadshow. As of mid-July 2026, EDGAR showed no public Anthropic S-1 or S-1/A. No ticker, no exchange, no banks, no date. Reports point to a fall listing on Nasdaq with Goldman Sachs, JPMorgan, and Morgan Stanley. Treat that as rumour until a filing says otherwise.

What the Anthropic S-1 Still Will Not Tell You

The Anthropic S-1 will go deep on some things and stay quiet on others. Reading one well means knowing the quiet parts.

Model design, parameter counts, and training recipes stay out of the Anthropic S-1. Trade secrets survive an IPO, and no rule drags specs onto the page. Customer contract terms stay out too. Big contracts go in as exhibits, though companies redact the sensitive lines.

The safety debate stays open as well. The Anthropic S-1 can describe controls and review boards. Whether they work is not a question it can answer.

Finally, the Anthropic S-1 cannot promise the deal happens. The company can edit, delay, or pull it. Its own words tie the offering to market conditions.

How the Anthropic S-1 Compares to SpaceX

One useful yardstick already exists. SpaceX ran the same private route in April 2026, then filed publicly in May.

That gap ran about seven weeks. It is not a rule, but it shows the shape of a normal review.

SpaceX also published audited numbers, a price, and a ticker. Nothing like that exists here yet, so any side-by-side stays lopsided for now.

Conclusion: How to Read the Anthropic S-1 When It Lands

Skip the opening pages. The business section of the Anthropic S-1 will be marketing that passed legal review.

Go to the financials. Next, contractual obligations. After that, related-party deals. Finally, the capital stock pages. Those four sections of the Anthropic S-1 hold what private markets could never price. Carry three questions with you.

What did Anthropic truly earn, audited, against the run rates in the press? That gap tests the valuation first.

When do the compute bills come due, and how much can the company cancel? Fixed cost against moving revenue is the structural risk.

What can the Long-Term Benefit Trust actually do? Not what it aims to do. What the charter allows.

The Anthropic S-1 will be the first time a frontier lab answers those questions under securities law rather than in a blog post. Whatever the stock does, that part is new.

Why the Anthropic S-1 Matters Beyond One Stock

This filing sets a template. OpenAI filed its own draft days later, so whatever survives SEC review here shapes the next one.

Three norms are up for grabs. How a lab reports compute cost. How it words model-risk language. And how far a mission charter can bend before buyers discount it.

Regulators are watching too. A clean, specific filing makes the case that AI labs can report honestly under existing rules. A vague one invites a rulemaking push instead.

So read it as a precedent, not just a prospectus.

FAQ About the Anthropic S-1

    What is the Anthropic S-1 and when was it filed?

    The Anthropic S-1 is a draft registration statement on Form S-1 that Anthropic, PBC confidentially submitted to the SEC on June 1, 2026 for a proposed initial public offering of common stock. The company announced the submission under Rule 135 and stated that share count and offering price had not been determined.

    Does the Anthropic S-1 mean an IPO is scheduled?

    No. A confidential draft submission starts SEC review and preserves the option to go public. The Anthropic S-1 registers no securities, permits no sale, and sets no date. Anthropic has said timing depends on market conditions and other factors, and it retains the ability to amend, delay, or withdraw.

    When will the Anthropic S-1 become public?

    Under SEC staff policy, the registration statement and all previous nonpublic drafts must be publicly filed at least 15 days before a roadshow, or 15 days before the requested effective date if there is no roadshow. That window is the earliest reliable point at which the full Anthropic S-1 becomes readable.

    What financial information will the Anthropic S-1 contain?

    Because Anthropic almost certainly exceeds the Emerging Growth Company revenue threshold, the Anthropic S-1 should include three years of audited income statements, two years of audited balance sheets, full notes under Regulation S-X, MD&A explaining the trends, and complete executive compensation disclosure. Run-rate figures reported in the press are no substitute for audited trailing results.

    How does the Long-Term Benefit Trust affect the Anthropic S-1?

    Anthropic is a Delaware Public Benefit Corporation whose board may balance stockholder interests against a stated public benefit purpose. The Long-Term Benefit Trust is an independent five-member body holding a special share class with board-election rights that expand over time to a majority. The Anthropic S-1 must describe those rights precisely in the capital stock section and address them in risk factors.

    Can retail investors buy Anthropic stock before the IPO?

    Not through a standard brokerage account. Anthropic stock is not publicly traded, and pre-IPO access is generally limited to accredited investors through private secondary channels. Some exchange-traded funds hold pre-IPO positions in private companies, offering indirect and diluted exposure rather than a direct stake. This article is journalism, not investment advice.

    Keep reading

    Anthropic IPO valuation

    Anthropic IPO: The $895 Billion Question Behind Its Valuation

    Last updated: 9 November 2026. Latest confirmed development: Anthropic’s amended S-1, filed on 2 November, still leaves the share count and the IPO price range …
    Claude Opus vs Sonnet

    Claude Opus vs Sonnet: What the 2026 Price Gap Actually Buys

    Last verified: 8 November 2026. All prices are Anthropic’s standard first-party API rates in US dollars per million tokens. They aren’t Claude Pro or Max …
    RSA-1024

    Did AI Break RSA? What DeepMind Actually Found
    Last verified: 8 November 2026. Both papers are unreviewed working papers, and no outside group has reproduced the results yet. No, AI did not break …
    Model Distillation

    Model Distillation Explained: When AI Learning Becomes Extraction

    Last verified: 7 November 2026. Government and company claims are attributed throughout. None has been tested in court. A support team trains a small, cheap …