Specifications and prices checked October 11, 2026 · Prices in USD per million tokens, standard API tier
Short answer: In an LLM context window comparison for 2026, input capacity barely separates the leading models. Every proprietary API checked here accepts about 1 million tokens (1M to 1,050,000), and the two open-weight hosts list 1M or 524,288. Output caps differ more, from 65,536 tokens on Gemini to 128,000 on GPT-6.1 Sol and Claude Opus 5.5. Long-context pricing rules differ most of all: a 300,000-token prompt costs anywhere from $0.06 to $1.20 in input charges.
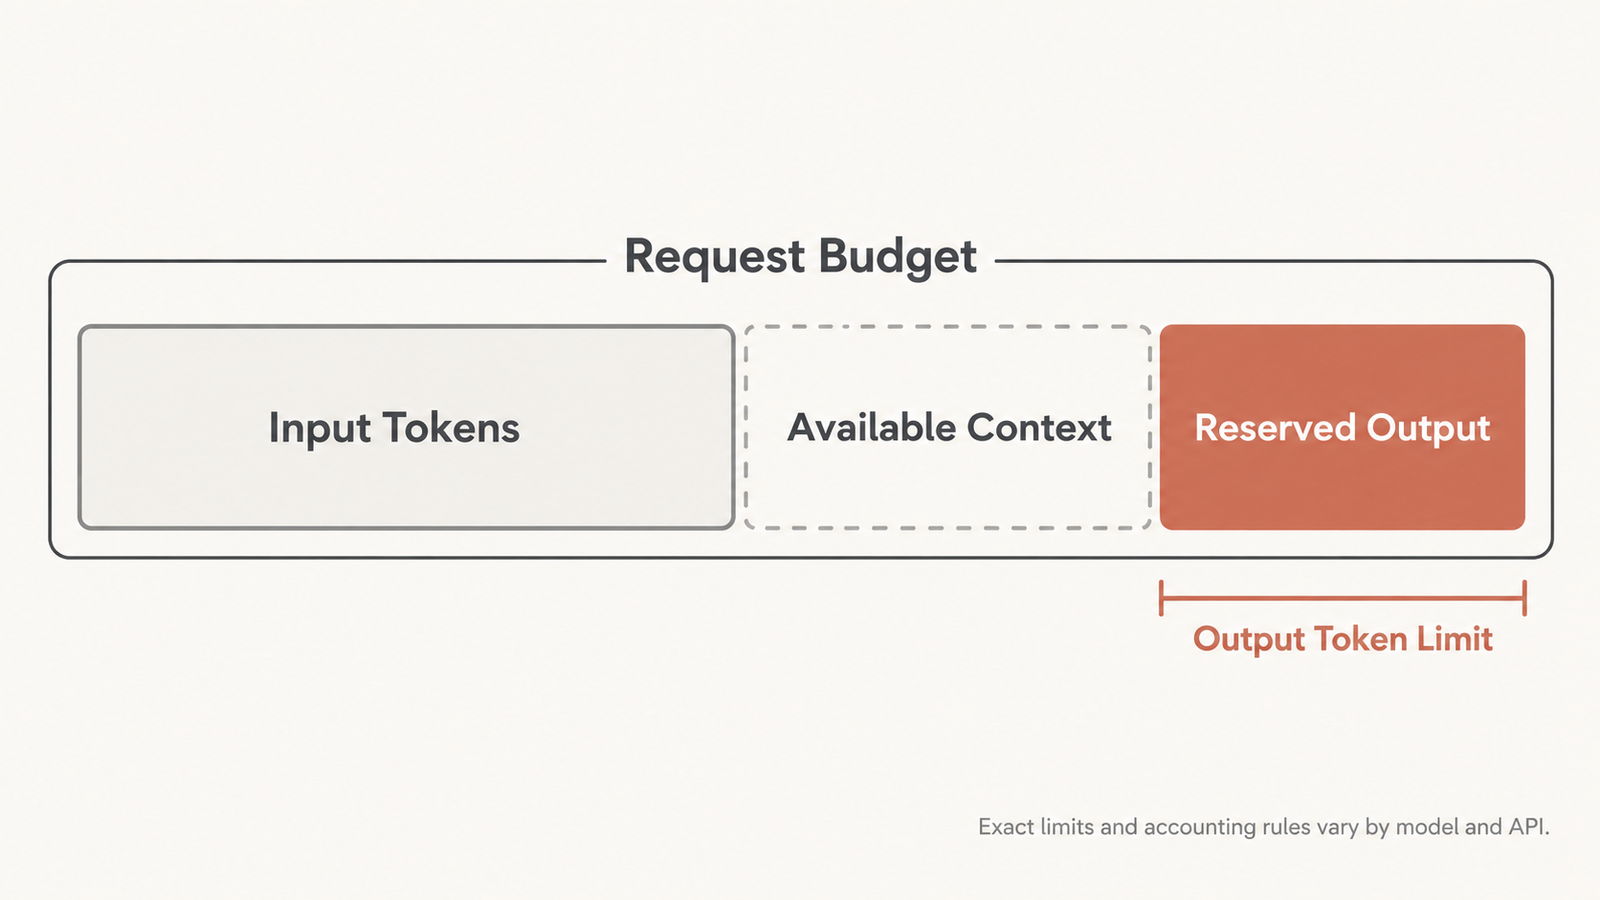
Three numbers get conflated in most spec sheets. The context window is how much a model can read in one request. The output limit is how much it can write back. The long-context pricing threshold is the prompt size at which the provider starts charging more. A model can have a huge window, a modest output cap and a threshold that doubles your bill well before you get near the window’s edge.
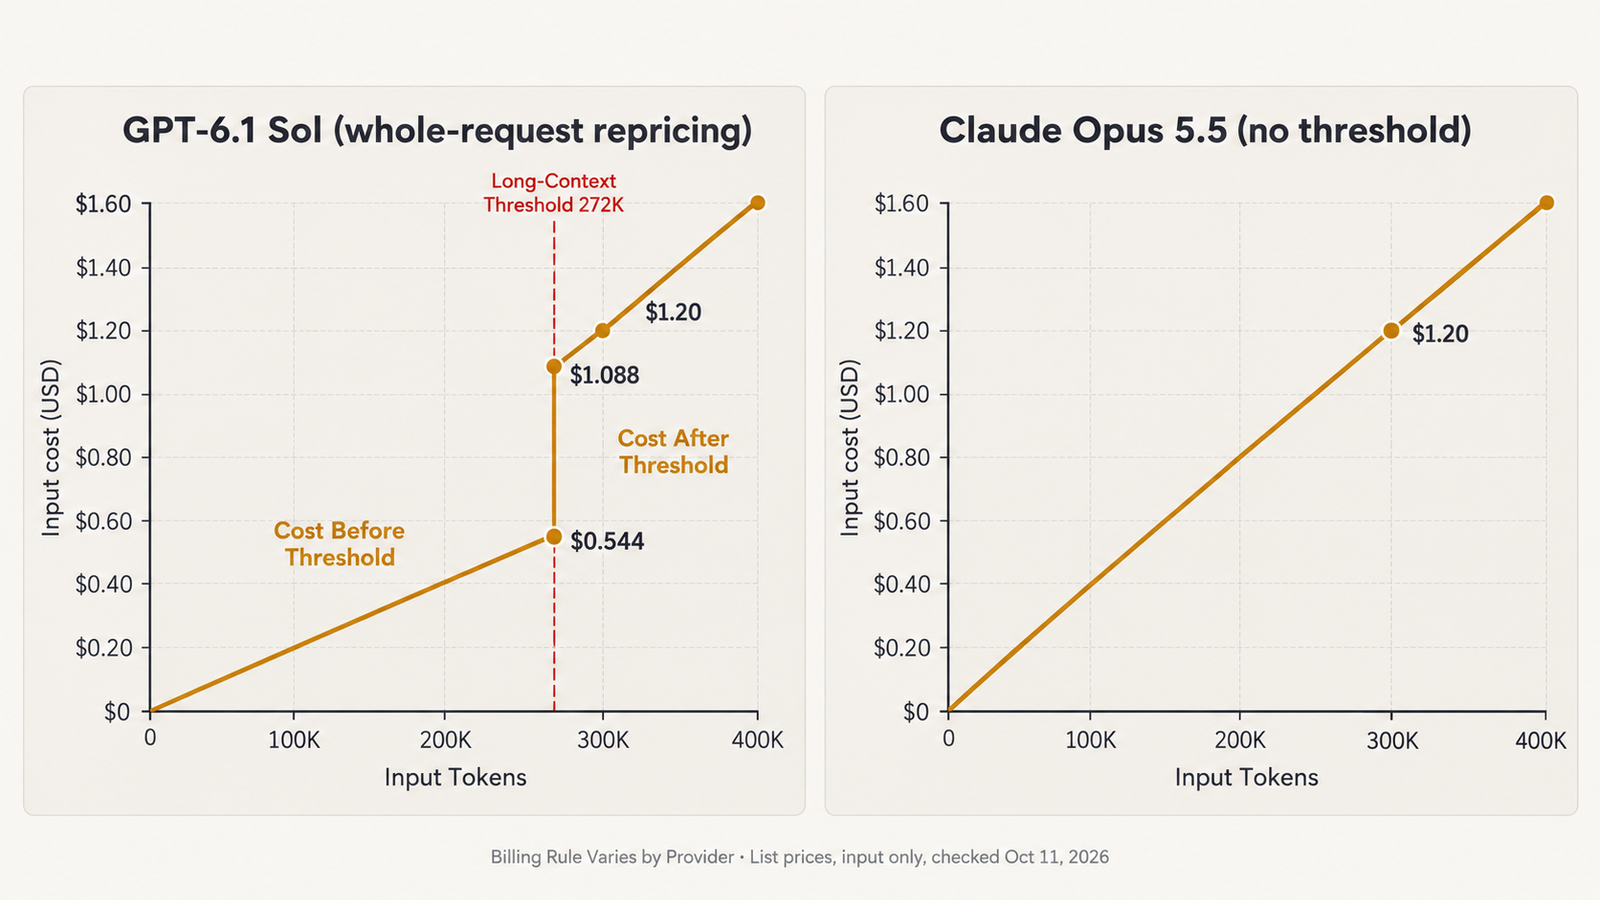
The third number is the one buyers skip. GPT-6.1 Sol charges $2.00 per million input tokens up to 272,000 tokens and $4.00 per million above it, and OpenAI applies the higher rate to the full request. A 270,000-token prompt costs $0.54. A 280,000-token prompt costs $1.12. Ten thousand extra tokens cost 58 cents.
Key Takeaways
- Context capacity has converged. Every proprietary model checked lists about 1M input tokens, so window size rarely decides a purchase in 2026.
- Output caps have not converged. Gemini 3.1 Pro and 3.8 Flash cap output at 65,536 tokens, about half of GPT-6.1 Sol’s and Claude Opus 5.5’s 128,000.
- Three providers reprice by prompt size. OpenAI does it above 272K for the whole request, Google above 200K for Gemini 3.1 Pro, and Anthropic above 100K for Claude Haiku 5.5 only.
- Claude Opus 5.5 and Sonnet 5.5 have no long-context surcharge. At 300K tokens, Opus 5.5 ($1.20) costs the same as GPT-6.1 Sol and Gemini 3.1 Pro, even though its base rate is twice theirs.
- Crossing a threshold can cost more than the extra tokens are worth. Just past 272K, a GPT-6.1 Sol prompt more than doubles in price.
- Caching flattens the comparison. A fully cached 300K prefix costs $0.06 on both GPT-6.1 Sol and Claude Opus 5.5.
- Open-weight hosting is cheapest per token, but a host’s served context can differ from the model card. Check the endpoint, not the paper.
Quick Navigation
- The LLM context window comparison table
- Context window versus output limit
- Where long-context pricing start
- What a 300K-token request costs
- Context window choices for RAG, coding and agents
- A context window checklist before you choose
- Conclusion
- Frequently Asked Questions
- What is the difference between an LLM context window and an output token limit?
- Does a larger context window always mean a better model?
- What happens when a request exceeds the context window?
- How does long-context pricing work?
- Does crossing a pricing threshold reprice the entire request?
- Can prompt caching reduce long-context costs?
- How should developers compare proprietary and open-weight models?
- What should an AI agent developer measure before choosing a model?
The LLM context window comparison table
All values are taken from official documentation and were checked October 11, 2026. “Threshold” is the prompt size at which input pricing changes. Costs cover input tokens only, with no output, caching, batch discounts or taxes.
| Model and version | Max input context | Max output | Long-context threshold | Input below | Input above | 300K input cost | Availability | Documentation |
|---|---|---|---|---|---|---|---|---|
GPT-6.1 Sol (gpt-6.1-sol) | 1,050,000 | 128,000 | >272K, whole request | $2.00 | $4.00 | $1.20 | GA, OpenAI API | Model page |
GPT-6 Luna (gpt-6-luna) | 1,050,000 | 128,000 | >272K, whole request | $0.10 | $0.20 | $0.06 | GA, OpenAI API | Model page |
Claude Opus 5.5 (claude-opus-5-5) | 1M | 128,000 | None | $4.00 | n/a | $1.20 | Current, Claude API | Models · Pricing |
Claude Sonnet 5.5 (claude-sonnet-5-5) | 1M | 128,000 | None | $2.00 | n/a | $0.60 | Current | Same as above |
Claude Haiku 5.5 (claude-haiku-5-5) | 1M | 128,000 | >100,000 | $0.10 | $0.50 | $0.15 | Current | Same as above |
Gemini 3.1 Pro (gemini-3.1-pro-preview) | 1,048,576 | 65,536 | >200K | $2.00 | $4.00 | $1.20 | Preview | Model · Pricing |
Gemini 3.8 Flash (gemini-3.8-flash) | 1,048,576 | 65,536 | None | $0.75 (to Dec 31, 2026; $1.50 from Jan 1, 2027) | n/a | $0.225 | Stable | Model |
Gemini 3.5 Flash-Lite (gemini-3.5-flash-lite) | 1,048,576 | 65,536 | None | $0.30 | n/a | $0.09 | Stable | Model |
Mistral Large 4 (mistral-large-4) | 1M | Not publicly documented | None documented | $0.68 sale ($1.36 list) | n/a | $0.204 sale | Public Preview, open-weight | Model page |
| Llama 4 Maverick (Together AI) | 1M per model card; host lists 1,048K and 524,288 | Not publicly documented | None documented | $0.27 | n/a | $0.081 | Hosted endpoint | Model card · Host |
| Qwen3.8-2.4T-A95B (Together AI) | 262,144 native; 1M served | 131,072 | None documented | $2.00 | n/a | $0.60 | Hosted endpoint | Model card · Host |
Whole-request rules apply where stated. OpenAI says prompts above 272K are “priced at 2x input and cache rates and 1.5x output for the full request.” Anthropic says a Haiku 5.5 request over 100,000 tokens “pays the higher prices,” counting cache reads and writes toward prompt length. Google’s table selects the rate by prompt size (“prompts > 200k tokens”) but does not explicitly say the whole prompt is repriced. This article assumes it is, and that is an interpretation of Google’s wording.
The open-weight rows describe one host’s endpoint, not the model. Qwen3.8’s model card gives 262,144 tokens natively, extensible to about 1M. A 300K request on Together therefore runs in the extended range, where quality can differ from native-length behaviour.
Context window versus output limit
The context window caps what goes in. The output limit caps what comes out in a single response. They are documented separately for every proprietary model here, and they constrain different workloads.
Output limits bind harder than input limits. A model that reads a 400-page contract can only write 65,536 tokens back if it is Gemini 3.1 Pro, or 128,000 if it is GPT-6.1 Sol or Claude Opus 5.5. That is roughly 50,000 versus 100,000 words, before any reasoning tokens. Google bills thinking as output (“output price including thinking tokens”), so whether reasoning also draws on the output cap matters for long reasoning tasks. Check each provider’s documentation for that point, because accounting differs.
Some providers also treat input and output as one shared budget, so a large prompt leaves less room to answer. Qwen’s model card illustrates the general point: it recommends allowing 262,144 tokens for reasoning and 131,072 for the final answer, figures that only make sense if the request budget is planned as a whole.
Where long-context pricing start
Three of the providers checked charge more once a prompt gets long. Each draws the line in a different place and handles it a little differently.
- OpenAI, 272K, whole request. For GPT-6.1 Sol and GPT-6 Luna, prompts above 272K input tokens pay double the input and cache rates and 1.5 times the output rate, on every token in the request. OpenAI’s pricing page lists the long-context column, and the threshold and the “full request” rule appear on each model page.
- Google, 200K, by prompt size. Gemini 3.1 Pro charges $2.00 input and $12.00 output for “prompts <= 200k tokens”, and $4.00 and $18.00 for larger prompts. Context caching moves from $0.20 to $0.40. Gemini 3.8 Flash and 3.5 Flash-Lite have no split.
- Anthropic, 100K, Haiku only. Anthropic’s pricing documentation states that its current models other than Claude Haiku 5.5 “include the full 1M token context window at standard pricing”, adding that “a 900k-token request is billed at the same per-token rate as a 9k-token request.” Haiku 5.5 moves from $0.10 to $0.50 per million input tokens above 100,000 prompt tokens, a fivefold jump, and cache reads count toward that total.
Mistral and the two open-weight hosts publish no threshold.
One ambiguity matters for anyone sizing prompts close to a boundary. Neither OpenAI nor Google says whether “272K” or “200K” means thousands or multiples of 1,024 tokens. The calculations below avoid the gap by testing well clear of either reading.
What a 300K-token request costs
The scenario: one request with 300,000 input tokens, zero output and no caching. It isolates the input-side effect of each pricing rule. These are author calculations from the official prices above, in USD.
Formula, where the provider reprices the whole request once a prompt crosses threshold T:
\text{Input cost} = \frac{N}{1{,}000{,}000} \times \begin{cases} r_{\text{standard}} & N \le T \\ r_{\text{long}} & N > T \end{cases}Just below and just above each threshold
| Model | Below threshold | Cost | Above threshold | Cost | Jump |
|---|---|---|---|---|---|
| GPT-6.1 Sol | 270,000 tokens | $0.540 | 280,000 tokens | $1.120 | +$0.58 for 10K more tokens |
| GPT-6 Luna | 270,000 | $0.027 | 280,000 | $0.056 | +$0.029 |
| Gemini 3.1 Pro | 190,000 | $0.380 | 210,000 | $0.840 | +$0.46 for 20K more tokens |
| Claude Haiku 5.5 | 99,000 | $0.0099 | 101,000 | $0.0505 | 5.1x for 2% more tokens |
At 300,000 tokens
| Model | Rate applied | 300K input cost |
|---|---|---|
| GPT-6.1 Sol | $4.00 (long-context) | $1.20 |
| Claude Opus 5.5 | $4.00 (standard) | $1.20 |
| Gemini 3.1 Pro (preview) | $4.00 (long-context, assumed whole prompt) | $1.20 |
| Claude Sonnet 5.5 | $2.00 | $0.60 |
| Qwen3.8-2.4T-A95B on Together | $2.00 | $0.60 |
| Gemini 3.8 Flash | $0.75 (2026 rate) | $0.225 |
| Mistral Large 4 (preview) | $0.68 sale / $1.36 list | $0.204 / $0.408 |
| Claude Haiku 5.5 | $0.50 (long-context) | $0.15 |
| Gemini 3.5 Flash-Lite | $0.30 | $0.09 |
| Llama 4 Maverick on Together | $0.27 | $0.081 |
| GPT-6 Luna | $0.20 (long-context) | $0.06 |
The three-way tie at the top is the central finding. On list prices, Claude Opus 5.5 costs twice as much as GPT-6.1 Sol per input token. At 300K tokens, OpenAI’s threshold has already doubled Sol’s rate and Google’s has doubled Gemini 3.1 Pro’s, while Opus stays flat. All three land at $1.20. Below 200K, Opus costs twice as much as either. Above 272K, the gap disappears.
Separate scenario: adding an 8,000-token answer
Keep the 300K prompt and add 8,000 output tokens. OpenAI’s long-context rule raises Sol’s output rate to $15.00 per million, and Google’s raises Gemini 3.1 Pro’s to $18.00.
- GPT-6.1 Sol: $1.20 + (8,000 / 1M × $15) = $1.32
- Gemini 3.1 Pro: $1.20 + (8,000 / 1M × $18) = $1.344
- Claude Opus 5.5: $1.20 + (8,000 / 1M × $20) = $1.36
- GPT-6.1 Sol at 270,000 input tokens instead: $0.54 + (8,000 / 1M × $10) = $0.62
Trimming 30,000 tokens from the prompt halves Sol’s bill. For Opus, the same trim saves about 9%.
Context window choices for RAG, coding and agents
- RAG pipelines. Retrieval systems control their own prompt size, which makes them the easiest place to exploit a threshold. A pipeline that routinely sends 250,000 to 300,000 tokens to GPT-6.1 Sol is paying the long-context rate on a share of requests that a retrieval cap of about 260,000 would remove. On Claude Opus 5.5 there is no such boundary to manage.
- Long-document analysis. Reading a large filing and returning a short summary is the case where big windows pay off most cleanly: input-heavy, output-light. The output cap rarely matters here, and the threshold often decides the bill.
- Coding agents. Consider an illustrative repository-aware agent that resends 300,000 tokens of code context on every turn. Without caching, 20 turns on GPT-6.1 Sol cost 20 × $1.20 = $24 in input alone. If the repository context is a stable prefix, OpenAI’s long-context cached rate of $0.20 per million drops each turn’s input to $0.06. That is why caching usually changes these comparisons more than the threshold does.
- Multi-agent systems. When several agents each carry a copy of a shared history, every copy is billed separately and pushed toward the threshold on its own. Summarising or pruning shared state before handoff can keep each call below a boundary that the combined history would cross.
- Long-running agents. Tool results accumulate. An agent that starts at 50,000 tokens and appends 10,000 per step crosses Gemini 3.1 Pro’s 200K line at step 16 and Sol’s 272K line at step 23. From that point every turn is billed at the higher rate. Compaction policies are cost controls, not just memory management.
- Prompt caching. Caching narrows the gap between providers on repeated context. At long-context rates, a fully cached 300K prefix costs $0.06 on GPT-6.1 Sol ($0.20 per million) and $0.06 on Claude Opus 5.5 ($0.20 per million cache hit). UniverseBlend’s earlier analysis of why a 50% price cut doesn’t halve agent bills made the same point for shorter contexts: once cache reads dominate, list-price gaps shrink. Note that Anthropic counts cache reads toward Haiku 5.5’s 100K threshold, and OpenAI doubles cache rates above 272K, so caching does not exempt a request from repricing.
- Splitting requests. Two 150,000-token GPT-6.1 Sol calls cost $0.60 in input, half the price of one 300,000-token call. That only works if the task decomposes. Cross-document reasoning does not split cleanly, and any shared instructions are paid twice. For Opus 5.5, splitting saves nothing on price.
A usable context budget is smaller than the advertised window. Rate limits measured in tokens per minute fill faster with long prompts, which UniverseBlend covered in AI API rate limits in 2026. This article makes no latency claims, but longer prompts add processing time before the first token.
A context window checklist before you choose
- Measure your real prompt-size distribution, including p95, not just the average
- Find each candidate’s threshold and whether it reprices the whole request
- Check the output cap against your longest required answer, including reasoning tokens
- Price the workload with your actual cache-hit rate
- Confirm the hosted endpoint’s served context for open-weight models, not just the model card
- Note preview status (Gemini 3.1 Pro, Mistral Large 4) and dated price changes (Gemini 3.8 Flash on January 1, 2027)
- Check tokens-per-minute limits at your prompt size
- Test quality at your real context length; a model accepting 1M tokens says nothing about how well it uses them
Conclusion
This LLM context window comparison shows the window itself has stopped being a differentiator. Nearly everything accepts about a million tokens. What separates the models is the output cap, whether the model is still in preview, and above all the pricing rule waiting at 100K, 200K or 272K tokens.
For workloads that sit under 200K tokens, list prices are a fair guide. For workloads that regularly cross 272K, a model with no surcharge can match one with half its base rate, and trimming a prompt by 10% can halve the bill. Price your real prompt distribution against each provider’s rule before trusting the headline number.
Frequently Asked Questions
What is the difference between an LLM context window and an output token limit?
The context window is the maximum input a model accepts in one request. The output limit is the maximum it can generate in one response. As of October 2026, most leading models accept about 1M input tokens, but output caps range from 65,536 (Gemini) to 128,000 (GPT-6.1 Sol, Claude Opus 5.5).
Does a larger context window always mean a better model?
No. Capacity says nothing about how well a model uses long context, and the largest windows now look nearly identical across providers. Output limits, pricing thresholds and quality at your real prompt length matter more.
What happens when a request exceeds the context window?
The API generally rejects it or requires you to shorten the input. Exact error behaviour varies by provider. Applications should count tokens before sending and trim, summarise or split oversized inputs.
How does long-context pricing work?
Some providers charge a higher per-token rate once a prompt passes a set size. In October 2026 that meant 272K for OpenAI’s GPT-6.1 Sol and GPT-6 Luna, 200K for Google’s Gemini 3.1 Pro, and 100K for Anthropic’s Claude Haiku 5.5. Claude Opus 5.5 and Sonnet 5.5 have no surcharge.
Does crossing a pricing threshold reprice the entire request?
For OpenAI, yes: the documentation says the higher rates apply “for the full request.” Anthropic’s Haiku 5.5 rule also applies the higher price to any request over the threshold. Google selects the rate by total prompt size but does not state the whole-request rule as explicitly.
Can prompt caching reduce long-context costs?
Yes, often by more than avoiding a threshold. A fully cached 300K prefix costs $0.06 on GPT-6.1 Sol or Claude Opus 5.5, against $1.20 uncached. Caching does not exempt a request from long-context repricing, though.
How should developers compare proprietary and open-weight models?
Compare the specific hosted endpoint, not the model card. A host may serve a different context length than the paper describes. Qwen3.8’s native 262,144-token context is extended to 1M on Together AI, for example.
What should an AI agent developer measure before choosing a model?
Prompt-size growth per step, the step at which each provider’s threshold is crossed, output needs per turn, cache-hit rate and tokens-per-minute limits. Then test answer quality at the context length the agent actually reaches.
Keep reading
Here are the latest posts from the blog.
LLM Context Window Comparison 2026: Limits and Costs
LLM Inference Latency by Model and Provider: Real Numbers
GPU Cloud Pricing 2026: What an Hour Actually Costs