AI Infrastructure Spending: What $145 Billion and a Sold-Out AWS Actually Buy

AI capex

Published 25 October 2026 · Last verified 25 October 2026 · By the UniverseBlend editorial desk

On 21 October, Meta set the latest marker for AI infrastructure spending, telling investors it expects to spend $135 billion to $145 billion on capital expenditure in 2026, a figure that includes principal payments on finance leases.

Side by side, the two statements describe one problem from opposite ends. Meta shows how much money is going in. Amazon shows how little of that money has yet become compute that a customer can rent.

In this story, AI infrastructure spending means cash spent on long-lived assets — land, buildings, electrical and cooling plant, servers, accelerators, memory and networking — that hyperscalers expect to run AI and cloud workloads.

Key Takeaways
  • Meta’s 21 October guidance narrowed its 2026 range to $135–145 billion; the $145 billion ceiling has stood since April. With $85.8 billion spent by September, the range implies $49–59 billion of fourth-quarter capex, 41–70% above the third quarter.
  • Amazon has not raised its ~$220 billion forecast since 30 July. Jassy’s 23 October remarks described capacity commitments and an appetite to spend more, not a new budget.
  • “Sold out” applies to large, committed blocks of AWS capacity. Jassy said Amazon still keeps capacity back for on-demand EC2 and its Bedrock inference service.
  • Estimates of 2026 hyperscaler spending run from about $794 billion (consensus cited by Goldman Sachs, all capex, US) to about $900 billion (J.P. Morgan, AI capex, five US firms) to $957 billion (TrendForce, nine global cloud providers). They measure different things and cannot be added together.
  • Memory prices are inflating the dollar figures. Jassy attributed most of Amazon’s $20 billion increase to memory costs, and TrendForce estimates DRAM and NAND will take 47% of large cloud providers’ capex this year.
  • AWS’s $496 billion backlog equals roughly 2.9 years of its current revenue run rate. Its duration, pricing and margin are not disclosed.
  • Utilisation of new capacity, contract pricing, and price versus volume inside capex would show whether the spending works. None is disclosed.

Quick Navigation


The AI infrastructure spending ledger

The headline numbers come in three kinds: what companies have spent, what they say they will spend, and what analysts think the sector will spend. They should never share a column without labels.

WhoFigure and periodStatusWhat it does not establish
Meta$135–145bn, 2026, incl. finance-lease principalGuidance, 21 Oct 2026AI share; price inflation within it
Amazon~$220bn cash capex, 2026Management expectation, 30 Jul 2026; unchanged at 25 OctAWS share (includes retail, logistics, satellites)
Alphabet$195–205bn, 2026Guidance, 22 Jul 2026Split between Cloud customers and Google’s own use
Microsoft~$175bn, calendar 2026Guidance as reported, 29 Jul 2026Lower than April’s ~$190bn because of lease accounting, not cuts
Five US hyperscalers incl. Oracle~$900bn AI capex, 2026J.P. Morgan estimate, 19 Oct 2026Company disclosure; uses J.P. Morgan’s AI definition
US hyperscalers~$794bn total capex, 2026Consensus cited by Goldman Sachs, 7 Aug 2026AI share; Goldman says it overstates US AI investment by ~$200bn
Nine global cloud providers$957bn, 2026TrendForce estimate, 14 Oct 2026Includes ByteDance, Tencent, Alibaba, Baidu; not additive to the rows above

The “$700 billion” figure that circulated in July is out of date. Reuters used it on 30 July for Big Tech’s AI investment; by October the narrowest comparable estimate had passed $790 billion.

Meta’s guidance reads like a raise, but only the floor moved, from $130 billion to $135 billion. The $145 billion ceiling dates from 29 April, when Meta cited higher component prices. What the new floor establishes is that Meta expects to spend at least $49 billion in the fourth quarter. (Calculation: $135bn minimum guidance minus $85.82bn spent from January to September, using purchases of property and equipment plus finance-lease principal from Meta’s third-quarter cash-flow statement.)

Microsoft’s row shows why a lower number need not mean a smaller programme. CFO Dive reported that Microsoft extended the estimated useful life of its data centres from 15 to 25 years. Chief financial officer Amy Hood said the change moves some future data-centre leases from finance leases, which count as capex, to operating leases, which do not. The buildings are the same. The reported capex is lower.

The money arrives before the compute

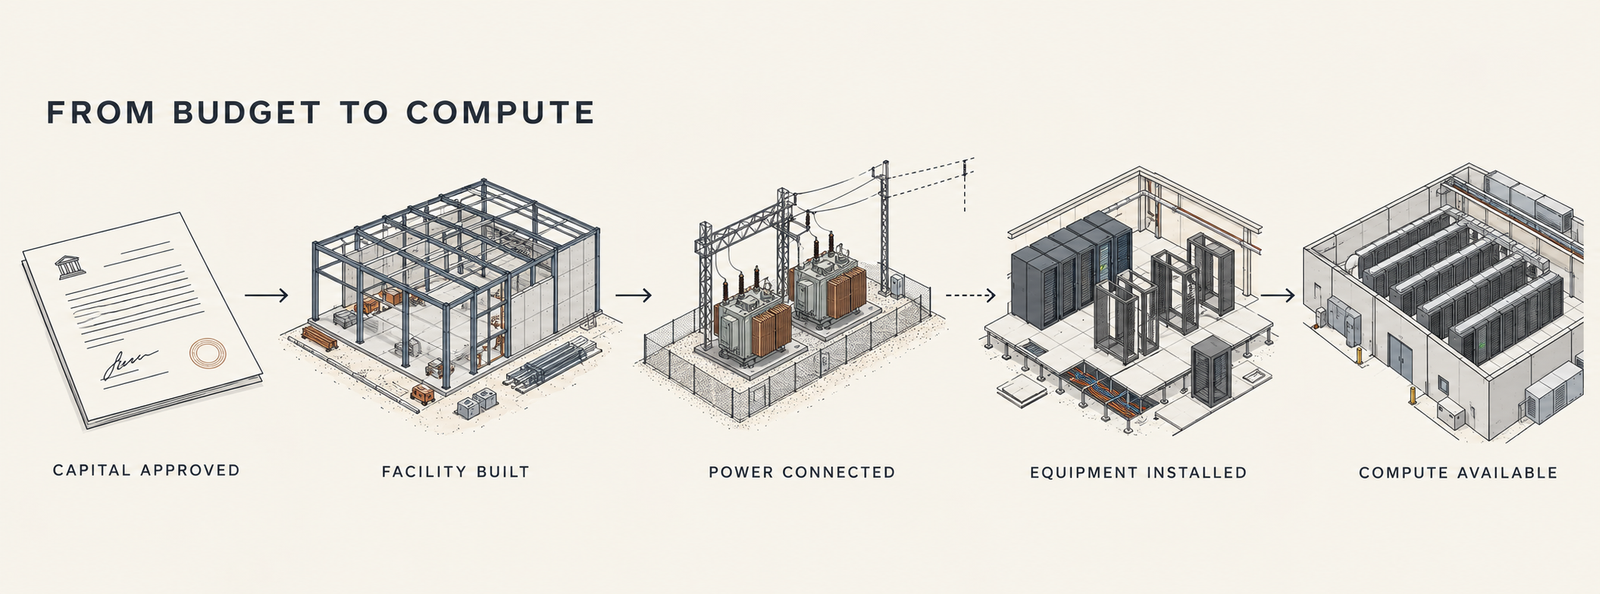
A capex dollar buys assets that come online in a fixed order, and the earliest spending earns nothing.

In his April shareholder letter, Jassy listed what AWS pays for up front: land, power, buildings, chips, servers and networking gear. The cash goes out “typically 6-24 months before we start billing customers,” depending on the component. The same letter puts data-centre lives at 30-plus years and chips, servers and networking at five to six.

That timing suggests a framework for reading any capex announcement. Track the money through six states:

  1. Committed — approved budget or guidance. Meta’s $135–145 billion sits here.
  2. Procured — equipment ordered or paid for. TrendForce reports that some component suppliers now want payment in advance, which pulls cash forward.
  3. Installed — racks in a building. This needs a finished shell and cooling.
  4. Available — energised, networked and commissioned capacity that can take a workload. This needs a grid connection.
  5. Contracted — capacity sold under commitment. AWS’s $496 billion backlog lives here, and it can run ahead of state 4.
  6. Monetised — capacity billing at a price that covers its depreciation and running costs.

Companies disclose the first and fifth states and, in aggregate, the sixth. The states in between are where the time goes.

Power is the slowest of them. UniverseBlend’s analysis of transformer lead times and interconnection queues found transformers averaging about 128 weeks and US interconnection waits of three to seven years, longer than the buildings they serve. J.P. Morgan’s 19 October note puts data-centre construction at 18–30 months and names power as the primary bottleneck.

Amazon’s own metric points the same way. AWS added 3.9 gigawatts of power capacity in 2025 and expects to double total power capacity by the end of 2027, according to the shareholder letter. When the constraint is energised megawatts, capex can outrun capacity for a long time without anything having gone wrong.

That is why Meta’s fourth quarter deserves attention. Its guidance implies quarterly spending 41–70% above the third quarter’s $34.91 billion. (Calculation: implied fourth quarter of $49.2–59.2bn divided by the third-quarter actual.) A late-year surge of that size buys assets that will mostly enter service in 2027.
AI capex

The memory allocation problem

Memory changed the arithmetic more than any other component in 2026, because it raises the price of AI servers and ordinary cloud servers at the same time.

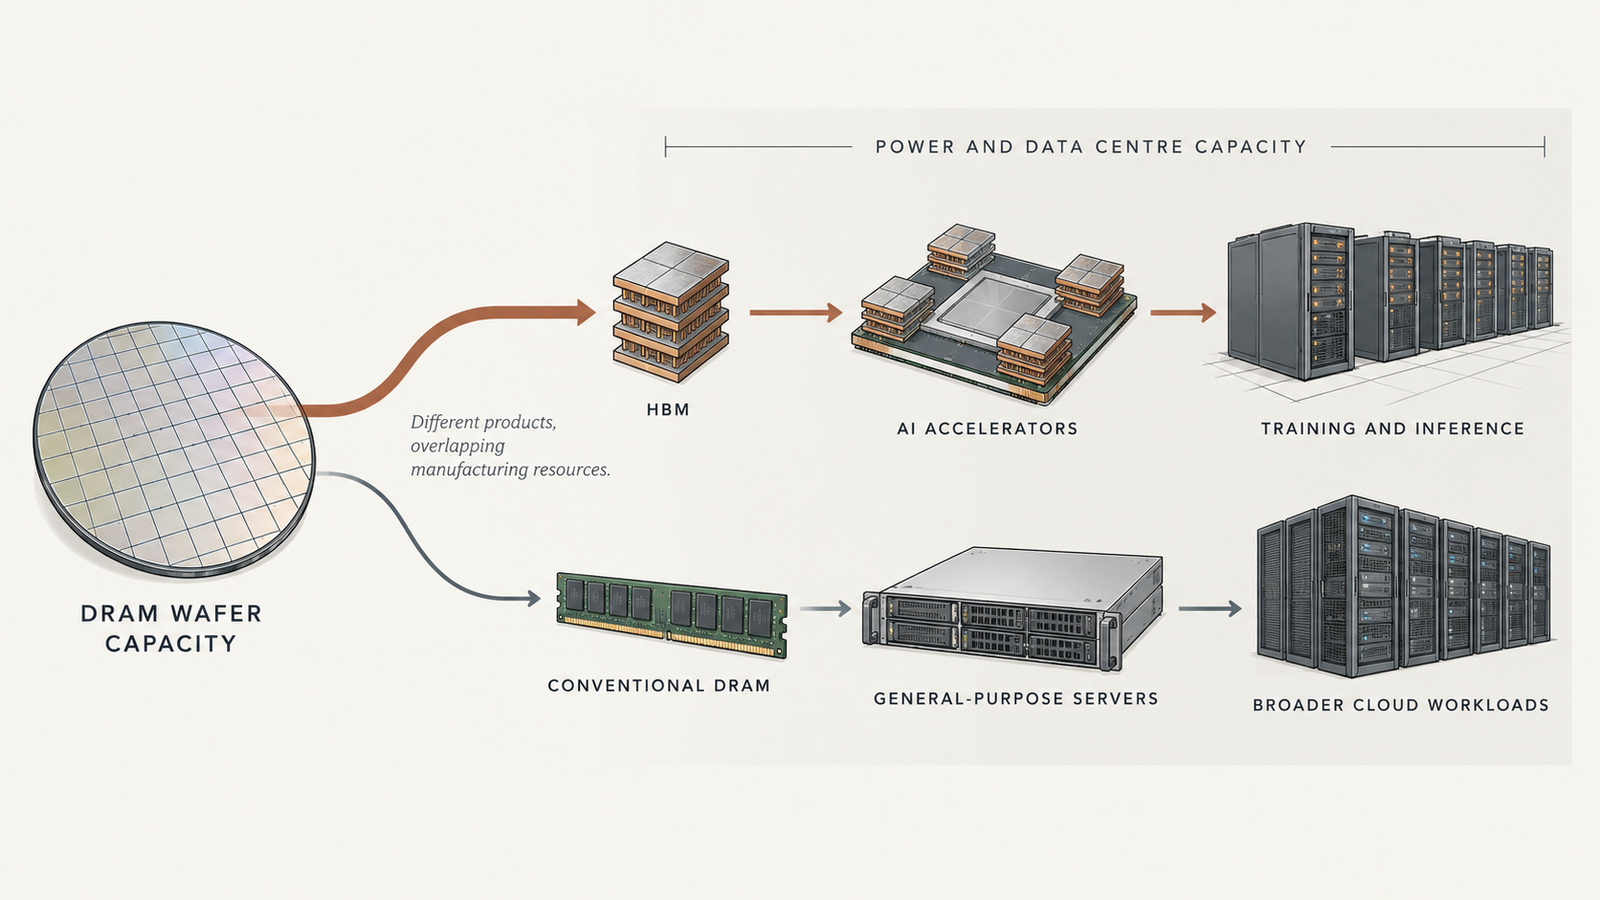
Two products are involved. Conventional server DRAM, sold as DDR5 registered modules (RDIMMs), sits beside CPUs in general-purpose servers. High-bandwidth memory (HBM) is also made from DRAM dies, but they are stacked, linked by through-silicon vias and packaged beside an accelerator to deliver very high bandwidth. An operator cannot plug HBM into a CPU server or fit DDR5 into a GPU package.

They compete upstream, for wafers. Micron chief executive Sanjay Mehrotra has said HBM3E needs about three times the silicon of DDR5 to produce the same number of bits. He expects that ratio to exceed 4-to-1 with HBM4E. Every wafer turned over to HBM yields fewer bits than it would as DDR5. UniverseBlend covered how HBM crowds out conventional DRAM wafers in September.

Amazon has tied this to its budget. On its 30 July earnings call, Jassy attributed most of the increase from about $200 billion to about $220 billion to higher memory costs, which J.P. Morgan’s research also records. He returned to the point on the 23 October podcast. According to several reports of the interview, he described splitting constrained memory between HBM for accelerators and DRAM for AWS’s core, non-AI services, both of which are growing.

The analyst figures show the scale. TrendForce estimates that server DRAM contract prices rose 64% in the second half of 2025 and will rise about 270% over 2026. It expects DRAM and NAND flash together to account for 47% of large cloud providers’ capex in 2026 and 68% in 2027. These are one research firm’s estimates, not company disclosures, but they point the same way as what Amazon and Meta have told investors.

Demand is coming from the CPU side as well. A 22 October TrendForce report expects server CPU shipments to grow 31% in 2026 and more than 40% in 2027, partly because agentic AI workloads need more CPU orchestration. It sees planned CPU-to-accelerator ratios moving from 1:8 toward 1:2 or even 1:1. Those CPUs need memory of their own, mostly DDR5 server modules, so AI demand also lifts conventional DRAM demand directly.

Part of 2026’s capex growth is therefore a price effect: a larger budget buys fewer servers per dollar than it did a year ago. No hyperscaler splits capex into price and volume, so outsiders cannot tell how much extra compute each additional billion buys.
AI capex

Training and inference compete for the same buildout

Accelerator counts say little on their own, because training and inference ask different things of the same hardware budget.

Training a frontier model needs thousands of accelerators working in lockstep for weeks, high-bandwidth interconnect between them and enough HBM to hold model state. Models are retrained and new ones begun, so a training cluster is a recurring claim on capacity, not a one-off cost.

Inference runs continuously and follows user demand. Generating each token means reading the model’s weights and its key-value (KV) cache from memory. Throughput is therefore usually limited by memory bandwidth, as UniverseBlend explained in why memory bandwidth, not FLOPS, caps inference throughput. The KV cache grows with context length and with the number of concurrent requests, so longer contexts cut how many users one accelerator can serve. Operators batch requests to raise utilisation, and pay for it in latency.

These differences turn into capex decisions. A cluster built for training carries a networking fabric that an inference fleet may not need. Hardware built for fast or cheap inference may be poorly suited to frontier training, and UniverseBlend has argued that specialised inference chips win only a narrow slice of the market. Capacity can move between workloads, though not always efficiently.

Meta and Amazon make this choice from different positions. Meta is its own customer. Its release says current and scheduled capacity gives it “flexibility to allocate resources across model training, core business growth” and new products. Its return arrives mainly through advertising: third-quarter ad revenue rose 26%, with impressions up 10% and price per ad up 14%. That growth cannot be credited wholly to AI infrastructure, although Meta says its AI investments are already delivering substantial incremental ad revenue.

Amazon sells capacity. Jassy said 2027 is “largely sold out all the big chunks,” according to Reuters, with some capacity held back for on-demand EC2 and Bedrock. Large commitments take long blocks; on-demand and managed-inference customers buy in small pieces at different prices. The same gigawatt can earn very different returns depending on who fills it.

Sold-out capacity versus profitable capacity

Sold-out capacity shows that demand at current prices exceeds deliverable supply. It does not show that the next dollar of capex earns an attractive return.

The disclosures establish three things. Customers have signed commitments: AWS’s backlog reached $496 billion at the end of June, up from $364 billion three months earlier. AWS is profitable now, with $16.6 billion of operating income on $42.2 billion of second-quarter revenue, according to Amazon’s second-quarter release. And Jassy wrote in April that Amazon already had commitments for a substantial portion of its 2026 AWS capex.

They do not establish duration, pricing or concentration. The backlog is about 2.9 years of AWS’s $169 billion annualised run rate (calculation: backlog divided by run rate), but Amazon does not say how long the contracts run, what margins they carry or how much comes from a few AI laboratories; OpenAI alone has committed more than $100 billion, according to the shareholder letter. Regional mix and utilisation are also undisclosed.

Costs are rising too. Meta’s depreciation and amortisation rose 44% year on year in the third quarter to $7.15 billion, and its free cash flow was negative $2.12 billion. Meta also announced a non-voting Class C share class, partly to give it a way to raise capital, effective 19 January 2027. J.P. Morgan notes that hyperscalers are increasingly funding the buildout with debt and equity rather than free cash flow.

Useful-life assumptions sit beneath all of this. Amazon depreciates chips and servers over five to six years. J.P. Morgan’s chief US economist, Michael Feroli, has warned that AI hardware may lose economic value faster than conventional equipment as each generation lowers the cost per unit of compute. If he is right, current depreciation schedules could overstate profits.

The strongest counterargument is Amazon’s. Jassy’s letter argues that data centres last 30-plus years and that returns become cumulatively attractive a couple of years after assets enter service. That holds well for buildings and power, the long-lived part. It says less about the five-year assets, which are where memory inflation lands.

What to watch next

Scheduled disclosures:

  • 28 October 2026 — Alphabet third-quarter results and Microsoft fiscal first-quarter 2027 results, both after the US close. Watch Alphabet’s $195–205 billion range and Microsoft’s capex including finance leases.
  • 29 October 2026 — Amazon third-quarter results, as reported by Reuters. Watch whether the ~$220 billion expectation changes, the AWS backlog and margins, and any memory commentary.
  • 19 January 2027 — Meta’s Class C stock takes effect, an indication of how Meta intends to fund 2027.

Not yet scheduled: Meta’s 2027 capex range, which management says it is still developing, and 2027 HBM contract prices, which TrendForce expects to rise 70–140%.

A scorecard for the quarters that follow:

IndicatorTypeDisclosed?
Backlog growth versus revenue growthLeadingYes (AWS, Google Cloud, Microsoft)
Capex growth versus cloud revenue growthLeadingYes
Price versus volume within capexLeadingNo
Utilisation of newly deployed capacityLeadingNo
Segment margin after depreciationLaggingPartly (AWS yes; Meta’s AI no)
Free cash flow and external financingLaggingYes
Return on invested capital for AI assetsLaggingNo

If backlog keeps outpacing revenue while margins hold after depreciation, the spending is converting. If capex keeps rising while margins fall and financing needs grow, it is not, whatever the backlog says.

Conclusion

Treat AI infrastructure spending in 2026 as a measure of intent. Meta’s range tells you how much it is prepared to put in; Amazon’s sold-out remark tells you how far delivery is lagging demand. Neither tells you about returns.

Three questions separate a credible announcement from a merely large one. How much of the increase is price? How long until the spending becomes energised capacity? And who has contracted to use it, at what margin? Today companies answer the third only in aggregate and the first two not at all. Until that changes, a rising capex number is evidence of demand and of component inflation, in proportions that nobody outside these companies can see.

FAQ

What is AI capex in 2026?

It is capital spending on data centres, power, cooling, servers, accelerators, memory and networking intended to run AI and cloud workloads. Estimates for 2026 range from about $794 billion (US hyperscaler consensus, all capex) to about $900 billion (J.P. Morgan, AI capex at five US firms), depending on scope.

Why is Meta spending up to $145 billion on capital expenditure?

Meta guided on 21 October 2026 to $135–145 billion, including finance-lease principal, to support its advertising business and its AI work. When it raised the range in April, it cited higher component prices. Its 2027 plans are not yet set.

Why is Amazon’s AWS capacity sold out through 2027?

Jassy said on 23 October 2026 that customers have committed to most large blocks of 2027 capacity because demand from AI labs and enterprises exceeds what Amazon can build. Some capacity is kept for on-demand EC2 and Bedrock, so not every service or region is unavailable.

How do HBM and conventional DRAM affect AI infrastructure costs?

HBM is stacked memory packaged with accelerators; conventional DRAM serves CPU servers. They are not interchangeable, but both come from DRAM wafers, and HBM uses about three times as much silicon per bit. Rising prices for both have pushed up capex budgets, including Amazon’s.

Does higher AI capex guarantee higher cloud profits?

No. Capex creates depreciation, over five to six years for chips and servers, and returns depend on utilisation and pricing. No company discloses margins on its new AI capacity.

How can businesses tell whether AI infrastructure spending is producing returns?

Compare backlog and revenue growth with capex growth, then check margin after depreciation and free cash flow. For a buyer, the test is utilisation: reserved but idle capacity earns nothing.

Editorial note: Figures are as disclosed or reported up to 25 October 2026. Alphabet and Microsoft report on 28 October and Amazon on 29 October; if those results change any figure here, this article will carry a dated update. Report errors through the contact page.


Keep reading

AGI vs superintelligence

AGI vs Superintelligence: A New Name Isn’t a New Intelligence
Facts checked against official documents and reporting on 18 November 2026. On 29 September, the White House told federal agencies to stop writing “artificial intelligence” …
AI Coding Agent

AI Coding Agents Are Getting Expensive. Who’s Paying for the Tokens?
Pricing checked on official vendor pages on 17 November 2026. All USD. Cost scenarios are illustrative and labelled as such. On 28 October, TechCrunch published …
Model Weights

Verify Model Weights: 7 Checks Before You Download
Checked against the burner22/numbat repository and its discussions, Hugging Face and PyTorch documentation, and Moonshot AI’s announcement on 2 November 2026. On 1 November, a …
Agentic AI Statistics

30 Agentic AI Statistics for 2026: Adoption, Spending and Risk

Last updated: 15 November 2026. This page is updated monthly; each figure keeps its original publication date. Agent traffic at one healthcare booking platform rose …

AI Accelerator Depreciation: The Assumption Nobody Audits

AI accelerator depreciation

An A100 with 80GB of HBM2e still computes exactly as well in 2026 as it did when it was installed. Nothing has degraded. It passes every diagnostic.

It is also increasingly hard to justify running, and the reason has almost nothing to do with its arithmetic throughput. A model that fits comfortably in 141GB on an H200 must be sharded across two A100s, halving effective utilisation and doubling the interconnect traffic. A context window that one newer accelerator holds in its KV cache does not fit at all.

The hardware works. The workload moved.

That gap — between an accelerator that functions and one that earns — is the subject of this article, and it sits directly on top of an accounting assumption that carries tens of billions of dollars of reported profit across the industry. AI accelerator depreciation is the allocation of an accelerator’s cost across its estimated useful life, and the estimate is exactly that: an estimate, chosen by management, disclosed in a sentence, and rarely examined against the physics of the workloads the hardware actually has to serve.

Key takeaways
  • AI accelerator depreciation is an accounting allocation, not a measurement of hardware lifespan. The disclosed figure is an estimate of economic benefit, and the hyperscalers apply it to “servers and network equipment” as a category rather than to accelerators specifically.
  • Four different lifetimes hide inside one number: physical, accounting, economic and competitive. They rarely coincide, and the shortest one determines when replacement actually happens.
  • The hyperscalers no longer agree. Microsoft and Alphabet moved servers to six years in 2022–23 and have held there; Amazon shortened a subset back to five effective January 2025, citing the pace of AI development; Meta extended to 5.5 years the same month.
  • Changing a four-year assumption to three raises annual depreciation on the same asset by roughly a third, which flows straight into cost per accelerator-hour and cost per token.
  • Memory capacity is the underexamined obsolescence driver. Accelerator HBM has gone from 40–80GB on A100 to 141GB on H200, 192GB on B200 and up to 288GB on B300-class parts, while models, context windows and KV caches grew to match.
  • An accelerator becomes economically obsolete when the workload outgrows its memory envelope, not when it stops computing. We call this obsolescence by memory footprint — an analytical framing, not an accounting term.

Quick Navigation


AI Accelerator Depreciation Starts With an Accounting Assumption

Depreciation spreads the cost of a long-lived asset across the periods that benefit from it. For an accelerator bought outright, the mechanics are simple:

Annual depreciation = (asset cost − salvage value) ÷ estimated useful life

The cost is known. Salvage value for accelerators is usually assumed to be small or zero. Useful life is the judgement call, and it is the only input management chooses.

That choice does three things at once. It sets reported operating income, because depreciation is an expense. It sets the capital recovery burden built into internal transfer pricing and cloud rate cards. And it signals to investors how long management believes the hardware will produce economic benefit.

One structural point deserves emphasis before any of the numbers below. None of the major operators discloses a useful life specifically for AI accelerators. They disclose useful lives for categories such as “servers and network equipment” or “technical infrastructure”, which bundle accelerators with CPUs, memory, storage, chassis and switches. Treating a disclosed six-year server life as a statement about GPU lifespan is an inference, not a reading of the filing.


AI Accelerator Depreciation Hides Four Different Lifetimes

The same physical accelerator has four expiry dates, and they are set by different forces.

LifetimeWhat ends itWho decides
PhysicalComponent failure — HBM faults, VRM degradation, thermal damagePhysics and operating conditions
AccountingThe end of the disclosed useful lifeManagement estimate, audited for reasonableness
EconomicThe point at which running it costs more than the value it producesPower prices, utilisation, alternatives
CompetitiveThe point at which it cannot serve the workload at acceptable throughput, latency or memoryModel architecture and customer requirements

Physical life is usually the longest. Well-cooled data-centre hardware runs for many years, and the secondary market for previous-generation accelerators exists precisely because they still work.

Accounting life sits in the middle by construction, since auditors want an estimate that reflects expected economic benefit rather than either extreme.

Economic life turns on operating cost against output. An older accelerator drawing 400W to produce a fraction of what a newer part produces at 700W can lose on performance per watt badly enough that electricity alone justifies replacement, before any capital consideration.

Competitive life is usually the shortest, and it is the one nobody discloses. It ends when the accelerator can no longer hold what the workload needs it to hold.

The practical consequence: a fleet can be fully depreciated and still valuable, or carry substantial book value while being commercially unusable for current workloads. Neither situation is visible from the depreciation schedule.


What Major Operators Disclose About AI Accelerator Depreciation

Between 2022 and 2024 the major operators moved in one direction. In January 2025 they stopped agreeing.

CompanyDisclosed changeStated scopeReported effect
Microsoft4 → 6 years, effective FY2023 (July 2022)Servers and network equipment~$3.7bn lower depreciation, ~$3.0bn higher net income in FY23
AlphabetServers 4 → 6 years; certain network equipment 5 → 6, effective January 2023Servers and certain network equipment~$3.9bn lower 2023 depreciation, ~$3.0bn higher net income
Amazon5 → 6 years, effective January 2024Servers~$3.2bn lower 2024 depreciation, ~$2.5bn higher net income
Amazon6 → 5 years, effective January 2025A subset of servers and networking equipmentRoughly $0.7bn lower operating income, with accelerated depreciation on early retirements
MetaMost assets → 5.5 years, effective January 2025Servers and network assets~$2.9bn lower 2025 depreciation, ~$2.6bn higher net income
OracleExtended to 5 years, 2023Servers and related equipmentDisclosed in that year’s filing

Four points about how to read that table.

  1. The direction reversed, once. Amazon is the only operator in the group to have shortened, and its stated reason is specific: the increased pace of technology development, particularly in artificial intelligence and machine learning. That is a company statement about AI hardware turnover, from the operator with the largest cloud footprint.
  2. The categories are not comparable. Microsoft’s disclosure covers servers and network equipment together as a range of two to six years. Alphabet separates servers from certain network equipment. Amazon’s January 2025 change applies to a subset it does not size. Lining these up in one column is convenient and slightly misleading, which is why the scope column is there.
  3. Sources disagree on some figures. Alphabet’s 2023 effect appears in coverage as both a ~$3.9bn actual reduction and a ~$3.4bn estimate made at the time of the change. Those are different things — an estimate disclosed in the 2022 10-K versus the outcome reported later — and the difference is a good illustration of why the primary filing matters more than the summary.
  4. Nothing here is about GPUs. No line in that table tells you how long a specific accelerator generation remains useful. It tells you what period management chose to spread the cost over for a category of equipment.

The analyst commentary around these disclosures has been vocal, and it should be labelled as commentary. In November 2025, investor Michael Burry argued publicly that hyperscalers were overstating earnings by extending useful lives beyond what two-to-three-year product cycles justify, putting the understatement at $176bn across 2026–2028. That is an outside estimate built on assumptions about true economic life, not a company disclosure, and it depends entirely on whether the accelerators concerned really do lose their economic value that fast.

Management has not been entirely silent on the tension. Satya Nadella has described not wanting to be “stuck with four or five years of depreciation on one generation” when a supplier’s migration pace increases — an acknowledgement that generational turnover, not hardware failure, is the pressure on useful life.


Why AI Accelerator Depreciation at Three Years Differs From Four

The arithmetic is simple enough to do in your head, which is part of why the assumption escapes scrutiny. The consequences are not simple at all.

The figures below are illustrative assumptions chosen for round numbers, not vendor prices or disclosed costs.

Take an accelerator server costing $300,000, assume zero salvage value, and assume 8,760 hours in a year at 100% availability.

Useful lifeAnnual depreciationDepreciation per hourChange vs 6 years
6 years$50,000$5.71—
5 years$60,000$6.85+20%
4 years$75,000$8.56+50%
3 years$100,000$11.42+100%

Moving from four years to three raises the hourly capital recovery burden by a third. Moving from six to three doubles it. No hardware changed, no electricity was consumed differently, and no workload got slower.

Now push it through to the number that matters operationally. Depreciation is only part of the cost of an accelerator-hour, but it is the largest part for recently purchased hardware. Assume power, cooling, networking and facility costs add $4.00 per hour:

Useful lifeDepreciation/hrOther costs/hrTotal/hrAt 60% utilisation, cost per useful hour
6 years$5.71$4.00$9.71$16.18
4 years$8.56$4.00$12.56$20.93
3 years$11.42$4.00$15.42$25.70

The last column is the one to sit with. Two variables — an accounting estimate and a utilisation rate — move the cost of an hour of useful compute by roughly 60% between the top and bottom rows. Neither is a property of the hardware.

This is why the assumption is not a footnote. It determines the floor under every internal chargeback rate, every cloud price built on cost-plus logic, and every build-versus-rent comparison. A team that models its costs on a six-year life and then replaces hardware after three has been systematically understating what its inference actually costs.

The converse is equally true, and worth saying because the commentary rarely does: an operator that depreciates over three years and then runs the hardware profitably for six has been overcharging its own product teams and understating its own margins. Conservative is not automatically correct.


The Accelerator Can Still Compute, But the Workload Has Moved

Everything above concerns the numerator of the cost equation. The rest of this article is about the denominator, which is where the interesting failure happens.

An accelerator becomes economically difficult long before it becomes technically incapable, and several forces push in the same direction at once:

  • Performance per watt. Newer parts do more work for the same power. In a facility with a fixed power envelope — which is most facilities now — every rack slot occupied by older hardware has an opportunity cost measured in the throughput a newer part would have produced from the same watts.
  • Rack density and cooling. Older air-cooled deployments cannot always be upgraded in place, so the constraint is the building, not the card.
  • Interconnect. Model and tensor parallelism depend on inter-GPU bandwidth. An older interconnect generation caps how effectively multiple accelerators can be combined, which matters most precisely when you are combining them to compensate for insufficient memory.
  • Software support. Kernel optimisation follows the current generation. New attention implementations, quantisation formats and serving features arrive tuned for recent hardware, and older parts receive them late, partially, or not at all.
  • Numerical formats. FP8 and FP4 support is architectural. An accelerator that cannot execute the format a model was quantised for either runs a less efficient variant or does not run it.

None of these makes the hardware stop working. They make it progressively less attractive than the alternative, which is what economic obsolescence means.


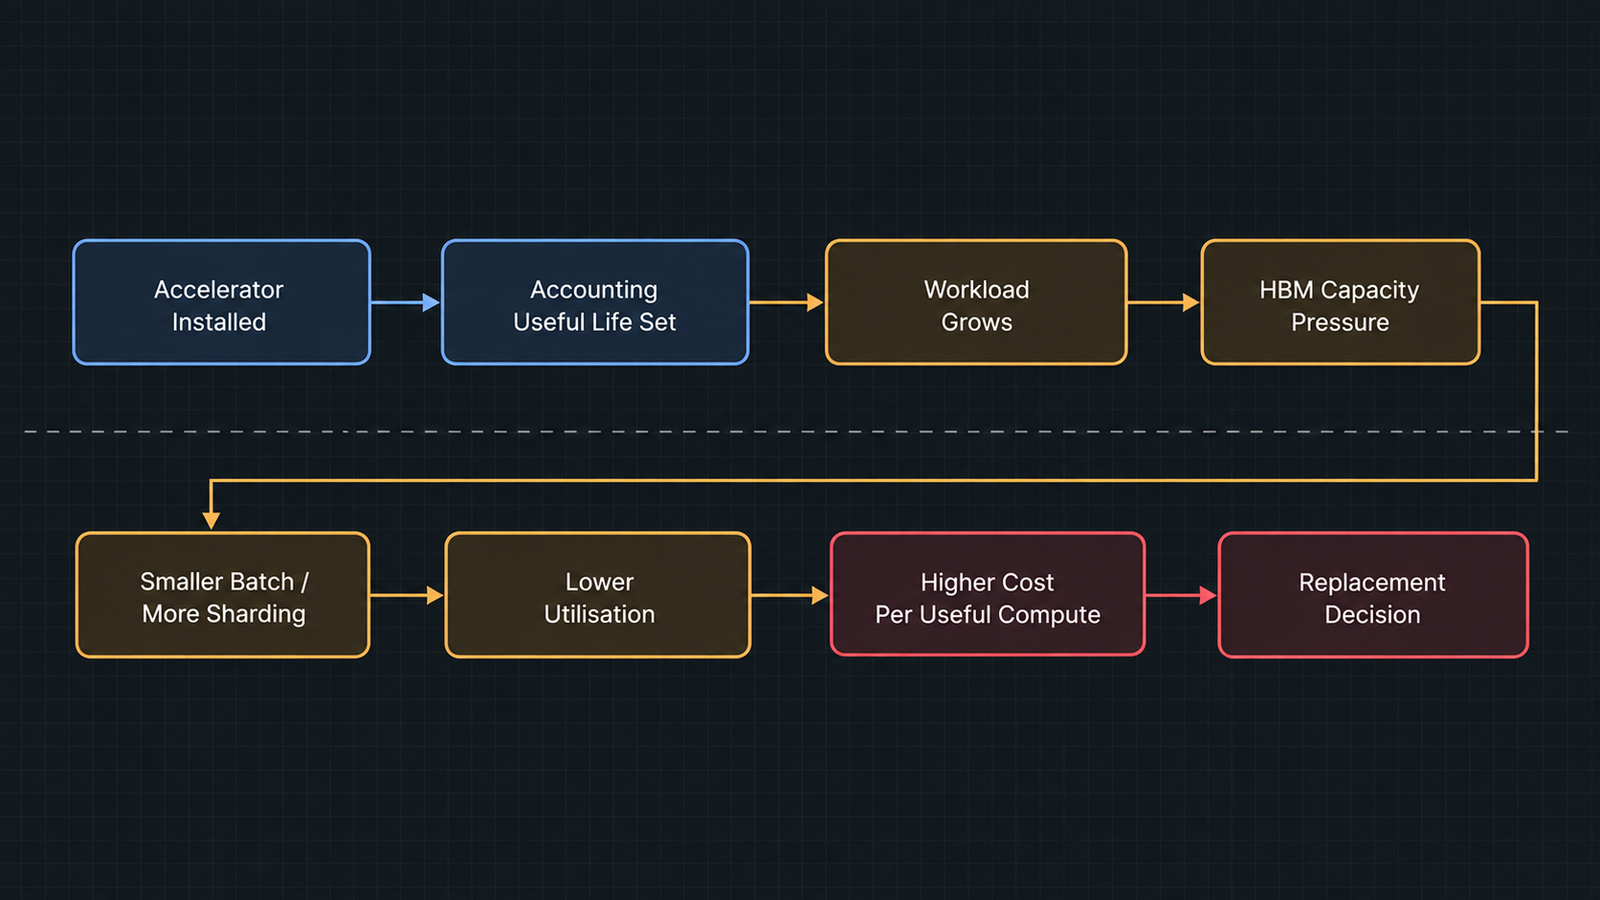
HBM Changes the AI Accelerator Depreciation Clock

The memory story is the one that deserves more attention than it gets, because it produces a hard boundary rather than a gradual decline.

Here is how accelerator memory has moved across generations, using vendor-published specifications:

AcceleratorMemoryTypeBandwidth
A100 (2020)40GB or 80GBHBM2e1.55–2.0 TB/s
H100 SXM (2022)80GBHBM33.35 TB/s
H200 (2023)141GBHBM3e4.8 TB/s
B200 (2024)192GBHBM3e8 TB/s
B300-classup to 288GBHBM3e~8 TB/s

Capacity roughly tripled from A100’s 80GB to B200’s 192GB, and bandwidth rose about fourfold. Compute throughput rose faster still in raw terms, but compute and memory are not interchangeable, and that is the point.

Three things compete for accelerator memory during inference:

  1. Model weights. A 70B-parameter model at FP16 needs roughly 140GB before anything else — which is why the H200’s 141GB is frequently described as the point where 70B-class models fit on a single accelerator, and why the same model on 80GB parts requires either quantisation or sharding across two.
  2. KV cache. Attention state for every token in every active sequence, growing linearly with context length and with batch size. Long-context serving is a KV cache problem before it is anything else. We went through the economics of this memory in our breakdown of AI memory costs.
  3. Activations and working space. Intermediate results, communication buffers, and whatever the serving framework reserves.

Memory capacity is therefore a feasibility constraint, while compute throughput is a speed constraint. Insufficient compute makes a workload slow. Insufficient memory makes it impossible without changing the deployment — and the changes available all cost something.


Obsolescence by Memory Footprint

Hardware does not need to stop computing to become obsolete. The workload can simply outgrow its memory envelope.

Obsolescence by memory footprint is our analytical framing, not an accounting term or an industry standard. It describes the case where an accelerator retains sufficient compute capability for a workload but lacks the memory capacity to hold that workload efficiently — and where every available workaround degrades the economics rather than restoring them.

The workarounds, and what each costs:

WorkaroundImmediate effectEconomic consequence
Reduce batch sizeFits in memoryLower throughput per accelerator; weights re-read for fewer tokens
Shard across more acceleratorsModel fitsTwo devices doing one device’s work; interconnect traffic and synchronisation overhead
Shorten contextFits in KV cacheA product limitation, not a technical fix
Offload to host memoryFitsPCIe-bound transfers at a fraction of HBM bandwidth
Quantise more aggressivelySmaller footprintPossible quality loss; may need formats the hardware lacks

Each of those paths ends in the same place: more accelerator-hours per unit of useful output, and therefore a higher cost per token on hardware whose hourly cost was fixed the day it was installed.

Work through the arithmetic informally. If a model requires two 80GB accelerators where one 141GB accelerator would serve it, the older deployment needs twice the devices, pays two sets of hourly costs, and absorbs the interconnect overhead of tensor parallelism. Even if the older accelerators were fully depreciated and cost nothing in capital terms, they still consume power, rack space and operational attention — and in a power-constrained facility, they consume the scarcest resource of all.

What makes this form of obsolescence distinctive is that it arrives as a step, not a slope. Performance-per-watt disadvantages accumulate gradually. Memory capacity either holds the model or it does not, and the moment a workload crosses the boundary, everything downstream changes at once: the parallelism strategy, the device count, the utilisation, the cost per token.

Four trends push workloads across that boundary, and all four are moving in the same direction:

  • Context windows lengthened. Frontier models moved from tens of thousands of tokens to hundreds of thousands and beyond, and KV cache scales linearly with context.
  • Reasoning models generate more tokens per task, which means longer sequences held in cache for longer.
  • Agentic workloads accumulate context across many turns within a single task.
  • Multimodal inputs consume far more tokens per unit of content than text.
AI accelerator depreciation

None of these trends required more FLOPS specifically. All of them required more memory, and the demand pressure this creates across the accelerator market is part of what we examined in our analysis of what pacing the frontier does to AI chip demand.

The implication for depreciation policy is uncomfortable. An accounting useful life is chosen partly on the assumption that the hardware remains productive across the period. Memory-footprint obsolescence means that productivity can end abruptly, for reasons entirely external to the asset, when the models being served grow past what it can hold.


A Practical Test for an Aging AI Accelerator

There is no universal answer to how long an accelerator lasts, and anyone offering one is selling something. Useful life depends on workload, generation, memory capacity, utilisation, electricity price, cooling efficiency, whether the work is training or inference, software support and what the replacement would cost.

What can be built is a test. Five layers, in order — and the accelerator’s economic life ends at the first layer it fails.

Layer 1 — Can it still run the workload? Does the model fit, with its KV cache, at the context length your product promises? A no here is memory-footprint obsolescence, and it is binary.

Layer 2 — Can it run it efficiently? What batch size does it sustain? How much sharding is required? Every extra device is an efficiency tax on the older generation.

Layer 3 — Can it hit the required throughput and latency? Tokens per second, TTFT and p95 against your actual SLA rather than a benchmark.

Layer 4 — Does it compete economically? Cost per useful token, including power, cooling and rack space, against the same figure for current hardware. Fully depreciated hardware often wins this comparison, which is exactly why it stays in service.

Layer 5 — Does replacement create enough additional capacity to justify the capital? The relevant question is not whether new hardware is better but whether the throughput gain per watt and per rack unit, in a facility with fixed power, repays the spend.

The metrics to gather for that test:

SignalWhat indicates approaching obsolescence
HBM capacity pressureFrequent OOM, forced sharding, capped batch sizes
Memory bandwidth utilisationSustained near ceiling while compute sits idle
Achieved throughputFalling well short of what newer parts deliver per watt
Batch size ceilingConstrained by memory rather than by latency targets
Context length supportedBelow what the product now requires
Power per useful tokenRising against the current generation
UtilisationFalling because the hardware cannot take the current workload mix
Replacement cost per unit of added capacityThe decision variable at layer 5

A fleet failing at layer 1 or 2 should be redeployed rather than retired — older accelerators remain genuinely useful for smaller models, embeddings, batch scoring, fine-tuning and development environments. Economic obsolescence for one workload is not obsolescence generally, which is the strongest argument the hyperscalers have for longer useful lives.


What AI Accelerator Depreciation Should and Should Not Tell You

Depreciation tells you how a company has chosen to allocate cost across periods, and by extension what management believes about the duration of economic benefit. Read across a group of filings, it tells you whether that belief is converging or diverging — and since January 2025 it has been diverging.

It does not tell you how long the hardware physically lasts, how long a specific accelerator generation stays competitive, what the fleet would fetch on the secondary market, or whether the assets are impaired. Those are separate questions with separate evidence, and the disclosure of useful life answers none of them.

The most useful reading of a change in useful life is as a signal about management’s expectations rather than as a fact about hardware. Amazon shortening a subset while Meta extended, in the same month, tells you two large operators looked at similar hardware and reached different conclusions about how long it would keep earning.

For anyone reading filings closely, the disclosures worth tracking are the scope statements rather than the headline numbers — what equipment the estimate covers, and whether the company breaks out accelerators at all. We looked at how much a detailed filing can reveal about AI cost structure in our analysis of what an Anthropic S-1 would disclose; the same reading applies here, and the answer is usually that the category is broader than the question.


Conclusion: Useful Life Is Not Competitive Life

An accelerator’s accounting life is a management estimate applied to a broad equipment category. Its competitive life is set by model architecture, context length and memory capacity, and nobody discloses it.

The gap between them is where the risk sits. If competitive life is shorter than accounting life, depreciation is understated and the reported cost of AI compute is too low. If it is longer — because older accelerators find second lives serving smaller models — the schedules are conservative and the hardware keeps earning after its book value reaches zero.

Both outcomes are happening simultaneously, on different parts of the same fleets. That is the honest answer, and it is why a single industry number has never made sense.

What operators can do is stop treating depreciation as the measure of how long hardware stays useful. It was never that. Measure the memory envelope against the workload, and you will know when an accelerator’s competitive life is ending long before its depreciation schedule notices.


FAQ

How long does an AI accelerator typically last?

Physically, well beyond the period it is depreciated over — data-centre accelerators commonly run for many years without failure. Economically, it depends on workload, memory capacity, power costs and what replaces it. There is no single industry figure, and the disclosed accounting lives of five to six years are estimates for equipment categories rather than measurements of accelerator lifespan.

Why do companies depreciate AI accelerators over different periods?

Because useful life is an estimate of expected economic benefit, and companies have different fleets, workloads, refresh patterns and judgements. Amazon cited the increased pace of technology development in AI when shortening; Microsoft cited software efficiency improvements when extending.

Can an older GPU still be economically useful?

Yes, frequently. Fully depreciated accelerators carry no capital cost, and older parts remain well suited to smaller models, embeddings, batch scoring, fine-tuning and development. Obsolescence for frontier inference is not obsolescence for every workload.

How does HBM affect GPU obsolescence?

Memory capacity determines whether a model, its KV cache and its activations fit on the device. When they do not, the workload must be sharded, batched smaller or offloaded, each of which raises cost per token. Capacity has risen from 40–80GB on A100 to 141GB on H200, 192GB on B200 and up to 288GB on B300-class parts.

What is the difference between GPU depreciation and GPU obsolescence?

Depreciation is an accounting allocation of cost over an estimated period. Obsolescence is the economic event of hardware no longer being worth operating relative to alternatives. They are independent: an accelerator can be fully depreciated and still productive, or carry book value and be commercially unusable.

Does more GPU memory increase useful life?

It extends competitive life, which is usually the binding constraint. A higher-memory accelerator stays able to hold larger models, longer contexts and bigger batches as workloads grow, which is why capacity has become a differentiator independent of compute throughput.

How can companies determine when to replace AI accelerators?

Test in order: does the workload fit in memory, does it run efficiently, does it meet throughput and latency targets, does it compete on cost per useful token, and does replacement add enough capacity per watt to justify the capital. The first failure in that sequence marks the end of economic life for that workload.


Keep reading

AGI vs superintelligence

AGI vs Superintelligence: A New Name Isn’t a New Intelligence

Facts checked against official documents and reporting on 18 November 2026. On 29 September, the White House told federal agencies to stop writing “artificial intelligence” …
AI Coding Agent

AI Coding Agents Are Getting Expensive. Who’s Paying for the Tokens?

Pricing checked on official vendor pages on 17 November 2026. All USD. Cost scenarios are illustrative and labelled as such. On 28 October, TechCrunch published …
Model Weights

Verify Model Weights: 7 Checks Before You Download
Checked against the burner22/numbat repository and its discussions, Hugging Face and PyTorch documentation, and Moonshot AI’s announcement on 2 November 2026. On 1 November, a …
Agentic AI Statistics

30 Agentic AI Statistics for 2026: Adoption, Spending and Risk

Last updated: 15 November 2026. This page is updated monthly; each figure keeps its original publication date. Agent traffic at one healthcare booking platform rose …