The number everyone repeated last week was $518 billion. The number that actually matters is 80%.
That is the share of Anthropic’s future compute and infrastructure commitments described as non-cancelable or payable regardless of usage, according to a confidential IPO prospectus reviewed by Reuters. Strip out the second number and the first is just a large purchase order from a company that needs a lot of chips. Keep it, and the commitment changes category: from a plan to spend into an obligation to pay.
Those are different things, and the difference is the whole story.
Having access to compute solves what has been the binding constraint on frontier AI development for three years. Being contractually obligated to pay for compute, on a schedule set in advance, converts a supply problem into a utilisation problem — and utilisation is something a company controls only partly, because it depends on customers showing up on the timetable the contracts assumed.
Key takeaways
- A confidential IPO prospectus reviewed by Reuters shows Anthropic committed to at least $518 billion over roughly a decade across six infrastructure partners, with about 80% non-cancelable or payable regardless of usage.
- The largest reported components: approximately $161.2bn in Broadcom-related equipment leases, $111.1bn with Google, $110bn with Amazon, $31.4bn with Microsoft, about $84.5bn for Nvidia-based capacity and about $20bn with AMD.
- The commitments are not uniform. Reporting describes shortfall payments for Google and Amazon, cancellation only on uncured material breach for Microsoft, and leases cancelable only on default for Broadcom. One percentage covers four different contract types.
- Anthropic spent $7.33 billion on compute and infrastructure in 2025 — more than half of $12.65 billion in total operating expenses — against revenue of $4.59 billion and $20.28 billion of cash and short-term investments.
- Broadcom has reportedly agreed to lend up to $42 billion through a convertible note that could fund about a third of a five-year, $125.2 billion TPU lease, making one company supplier, lessor and lender at once.
- Long-term commitments buy capacity certainty in a market where capacity has been the constraint. The cost of that certainty is financial rigidity if demand arrives later or smaller than contracted.
- The exact terms remain unverifiable while the prospectus is confidential. That uncertainty is part of the story, not a gap in it.
Quick Navigation
- What the $518 Billion Actually Represents
- The Obligation Hidden Inside the Headline
- Take-or-Pay Changes the Utilisation Equation
- Why Compute Certainty Can Be Worth Paying For
- The Partners Behind the Anthropic Compute Commitments
- Leases, Depreciation and the Technology Risk in a Long Contract
- What Could Make the Anthropic Compute Commitments Work
- What Could Make Them Expensive
- The Valuation Connection
- A Note on Governance
- What AI Infrastructure Buyers Should Take From This
- FAQ
- What are Anthropic's compute commitments?
- What is the $518 billion figure?
- What does take-or-pay mean here?
- What happens if Anthropic does not use the contracted compute?
- Why would a company commit so much compute?
- Who provides Anthropic's compute?
- What is the Broadcom financing arrangement?
- How do compute commitments affect AI company economics?
What the $518 Billion Actually Represents
Anthropic’s compute commitments are contractual obligations to buy cloud services, computing capacity and AI infrastructure from named partners over a defined period. They are not a debt balance, not a cash payment, and not a single contract.
The reported breakdown, all from the prospectus as described by Reuters:
| Partner | Reported amount | What it covers | Period |
|---|---|---|---|
| Broadcom | ~$161.2bn | Equipment lease obligations, largely non-cancelable | Includes a five-year TPU capacity lease of $125.2bn |
| ~$111.1bn | Infrastructure services | April 2026 – July 2033 | |
| Amazon | $110bn | Infrastructure services | May 2026 – April 2036 |
| Nvidia-based capacity | ~$84.5bn | Compute capacity | Through 2029 |
| Microsoft | $31.4bn | Infrastructure services | November 2026 – May 2033 |
| AMD | ~$20bn | AI compute | Not reported |
Those six figures sum to roughly $518 billion, which matches the headline. Note the composition: the single largest line is not a cloud contract at all but equipment leases, which behave differently from service agreements in both accounting and cancellation terms.
Three distinctions matter before anyone compares this to a balance sheet.
- Commitment is not cash. A ten-year obligation is paid over ten years. Spread evenly — which it will not be, since these ramp — $518 billion is roughly $50 billion a year, against the $7.33 billion Anthropic actually spent on compute and infrastructure in 2025.
- Commitment is not debt. It does not sit on the balance sheet as borrowing, though lease obligations are capitalised under current accounting. It is a future purchase obligation, disclosed in the commitments note rather than counted as leverage.
- The period is long and the ramp is steep. Contracts running to 2033, 2036 and beyond assume a company much larger than today’s. Reuters reported an annualised revenue run rate above $65 billion by the end of July and earlier reporting put Anthropic’s own 2028 revenue projection at roughly $190–200 billion. Those projections are the company’s, not forecasts anyone has validated.
The useful comparison is not $518 billion against $4.59 billion of 2025 revenue — that ratio is dramatic and tells you almost nothing. It is annual contracted spend against annual revenue in each future year, which is where the question of whether the commitments are comfortable or binding actually gets settled.
The Obligation Hidden Inside the Headline
The 80% figure is a summary statistic covering several different contractual mechanisms, and the mechanisms matter more than the average.
From the reporting:
- Google and Amazon: Anthropic must pay the difference if its actual spending falls short of the minimum commitment. This is a shortfall provision — you can buy less, but you pay the same.
- Microsoft: the agreement is described as non-cancelable through May 2033 absent an uncured material breach.
- Broadcom: the equipment leases are largely non-cancelable except after default, and certain payment or performance defaults could make a substantial portion of the lease obligations immediately payable.
- The Nvidia-based capacity arrangement: described as giving Anthropic more room to retreat than the others.
So “80% non-cancelable” bundles a minimum-volume commitment, a breach-only termination clause, a lease default provision and at least one more flexible arrangement under a single number.
That distinction has a practical consequence. A shortfall provision caps your downside at the committed spend — you lose the optionality, not more. A lease acceleration clause is different in kind: default can pull future payments forward into the present, which turns a long-dated obligation into an immediate one at exactly the moment a company would least be able to meet it.
The prospectus itself flags this. Reporting describes a warning that certain defaults could accelerate a substantial portion of lease obligations while also restricting Anthropic’s ability to draw on the $42 billion Broadcom facility to cover them. A financing facility that becomes unavailable precisely when it is needed is a standard credit structure and a real risk factor.
What cannot be verified: the actual contract language, the ramp schedules, the definitions of “minimum commitment”, any price-adjustment or technology-refresh provisions, and whether the agreements contain renegotiation mechanisms that reporting has not described. The prospectus remains confidential. Anyone asserting precision about these terms is working from the same journalism everyone else is.
Take-or-Pay Changes the Utilisation Equation
Take-or-pay means the buyer pays for a contracted quantity whether or not it takes delivery. The structure comes from energy and shipping, where suppliers build expensive dedicated capacity and need revenue certainty to justify it. It is appearing in AI infrastructure for exactly the same reason: someone has to fund the data centre before the demand shows up.
For the buyer, take-or-pay converts a variable cost into a fixed one. That is the entire economic consequence, and it cuts both ways.
Here is what it does to the unit economics. The following is a hypothetical illustration, not a description of any Anthropic contract or price.
Suppose a company commits to $10 billion of compute capacity for a year under a take-or-pay arrangement.
| Scenario | Capacity used | Cost incurred | Effective cost per unit used |
|---|---|---|---|
| Demand as planned | 100% | $10bn | 1.0x |
| Demand arrives late | 70% | $10bn | 1.43x |
| Demand disappoints | 50% | $10bn | 2.0x |
| Usage-based contract, same shortfall | 50% | $5bn | 1.0x |
Under a usage-based contract, a demand shortfall is a revenue problem. Under take-or-pay, the same shortfall is a revenue problem and a margin problem, because the denominator shrinks while the numerator does not.
This is why utilisation stops being an engineering concern and becomes a financial one. When capacity is elastic, running accelerators at 60% is an optimisation question — you are leaving efficiency on the table. When capacity is committed and paid for regardless, 60% utilisation means 40% of a contracted dollar produced nothing, and that gap flows directly into gross margin. We worked through the mechanics of where idle capacity comes from in our analysis of accelerator utilisation, and every source of idle time in that piece becomes more expensive under this contract structure.
The pressure this creates is directional and predictable. A company with committed capacity has strong incentives to fill it: push inference volume, expand enterprise contracts, launch workloads that consume compute, price aggressively to drive usage. None of those are irrational responses. They are what the contract structure rewards.
The honest caveat: none of this establishes that Anthropic is underutilising anything. Its reported run-rate growth suggests demand has been the easier half of the equation so far. The point is structural — take-or-pay raises the cost of being wrong about timing, for anyone who signs it.
Why Compute Certainty Can Be Worth Paying For
It would be easy to write this as a cautionary tale. That reading ignores why a competent management team signs these contracts, and the reasons are good ones.
For the past three years, the binding constraint on frontier AI has been access to compute, not demand for it. Accelerators have been allocated rather than sold. Memory has been contracted years ahead. Data-centre power has become a multi-year procurement problem. In that environment, a company without secured capacity does not get to choose how fast it grows.
What a long-term commitment buys:
- Capacity that exists. Suppliers build against contracted demand. An uncommitted buyer competes for whatever is left.
- Price certainty in a rising market. If compute costs rise, a fixed contract becomes an asset. The hedge runs both directions.
- Planning horizon. Model development schedules depend on knowing what hardware will be available and when.
- Priority on new generations. Being a large committed customer affects allocation when the next accelerator ships short.
- Scale economics. Volume commitments buy better unit pricing than spot purchasing.
There is also a competitive dimension. If frontier capability tracks compute, then capacity secured is capability secured, and capacity your competitor cannot buy is capability they cannot build. Commitments of this size take supply off the market.
The trade-off is clean enough to state in one sentence: Anthropic has exchanged financial flexibility for compute certainty. Whether that was a good trade depends entirely on which constraint turns out to bind — and that will not be clear for years.
The Partners Behind the Anthropic Compute Commitments
The prospectus, as reported, identifies Amazon, Google and Microsoft as simultaneously investors, customers, cloud providers, distributors and competitors. That is not a conflict the company is hiding; it is one it is disclosing as a risk.
Each role pulls differently. As an investor, a partner benefits from Anthropic’s success. As a supplier, it benefits from Anthropic’s spending. As a distributor, it takes a margin on Anthropic’s models. As a competitor, it builds models that compete with them. The same counterparty occupies all four positions at once.
The Broadcom structure is the sharpest version. Reuters reported on October 1 that Broadcom agreed to lend Anthropic up to $42 billion through a convertible note that could fund roughly a third of the five-year, $125.2 billion TPU compute lease, with Broadcom permitted to designate a financing partner and the debt convertible into Anthropic equity. Anthropic is expected to become the largest customer in Broadcom’s chip design business next year.
So one company supplies the hardware, leases it, lends the money to pay for the lease, and may end up holding equity. The prospectus reportedly flags potential conflicts of interest directly, warning that Broadcom’s decisions on pricing and hardware could affect Anthropic’s ability to procure enough computing infrastructure.
Broadcom’s own public filings describe a structure of this shape without naming a customer. Its 10-Q for the quarter ended August 2, 2026 discloses an “AI XPV platform” launched in June 2026 with an initial $35 billion tranche led by a financial partner, enabling deployment of more than a gigawatt of compute infrastructure for a customer, with Broadcom providing a backstop on that customer’s five-year lease obligations and maximum potential liability of roughly $29 billion. Broadcom does not identify the customer, and no public source establishes that these are the same arrangement.
The economic observation, offered as analysis: vendor financing linked to future demand for the vendor’s own product is not new — it is how equipment vendors have supported large customers for decades, and Nvidia has done versions of it recently. What is different here is the concentration. The same relationship carries supply risk, credit risk and equity exposure, and a stress event in one leg propagates to the others. Rothschild’s Robert Leitao put the market’s version of this concern plainly, questioning whether the revenue base can keep pace with the scale of financing that has been arranged.
Leases, Depreciation and the Technology Risk in a Long Contract
Three concepts get conflated whenever AI infrastructure costs come up, and they are related but not interchangeable.
| Concept | What it is | Where it shows up |
|---|---|---|
| Contractual commitment | A promise to buy capacity or services in future periods | Commitments note; lease liabilities on the balance sheet |
| Depreciation | Allocation of an owned asset’s cost across its useful life | Operating expenses, for hardware you own |
| Operating expense | Cash cost of running the business in a period | Income statement |
For a company leasing capacity rather than buying accelerators, depreciation largely sits with whoever owns the hardware — but the economics do not disappear. They arrive embedded in the lease rate, because the lessor priced in the asset’s expected useful life when setting it.
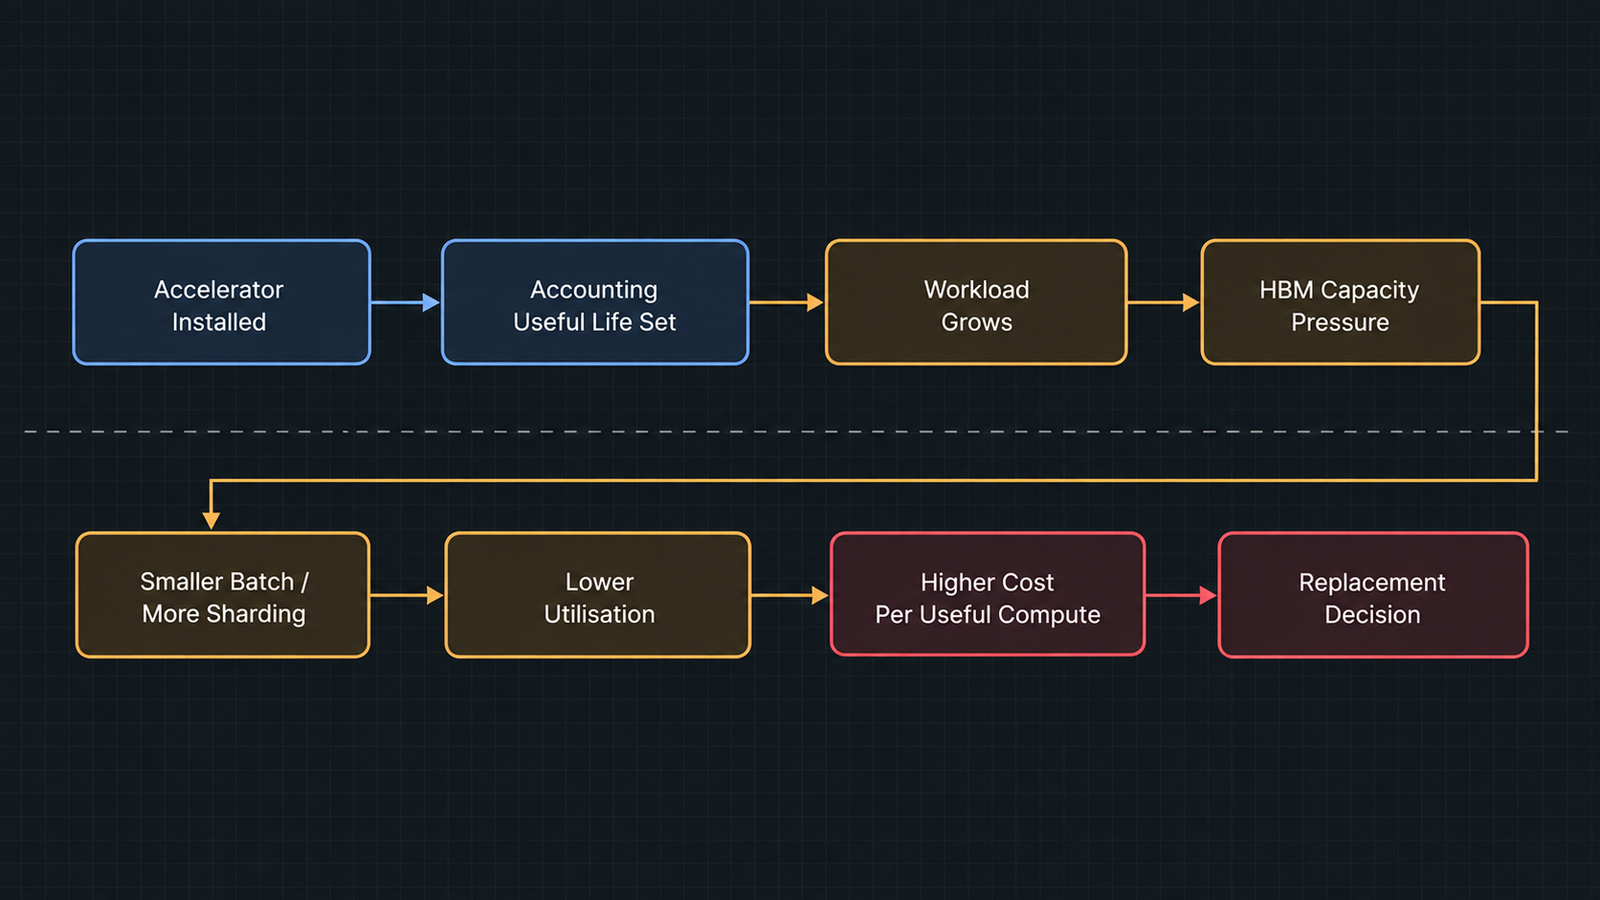
That is where the technology risk lives. A five-year lease on a specific accelerator generation assumes that generation stays economically competitive for five years. Hardware improves on a roughly annual cadence now, and what ends an accelerator’s economic life is usually not failure but the arrival of something that does more per watt and holds more memory — the pattern we examined in our piece on AI accelerator depreciation.
Follow that through. If performance per dollar improves sharply in 2029, a lease signed in 2027 at 2027 rates becomes expensive relative to what the market then offers. The capacity still works. It is simply worth less than it costs, and the contract does not care.
This is the structural reason long compute contracts carry risk that long property leases do not. A building is still a building in year seven. An accelerator generation may be two or three generations behind by then, and the memory capacity that made it viable for a given model size may no longer fit the models being served.
The counterweight, in fairness: the TPU capacity in question reportedly starts coming online in 2027 and the lease runs five years from there, which is roughly in line with how hyperscalers depreciate their own fleets. These are not exotic terms. They are standard terms applied at an unusual scale, and the scale is what makes the technology-refresh assumption consequential.
What Could Make the Anthropic Compute Commitments Work
The bull case is not complicated, and it is mostly about one variable arriving on schedule.
If enterprise AI demand grows as projected, contracted capacity gets consumed, and the commitments look like foresight rather than exposure. Reuters reported an annualised revenue run rate above $65 billion by the end of July, against $4.59 billion for full-year 2025. A company growing at that rate does not have a utilisation problem; it has a capacity problem, which is what the contracts solve.
Several things reinforce that outcome:
- Compute stays scarce. If accelerators, memory and power remain constrained, fixed-price contracts signed earlier look cheap later.
- Agentic and reasoning workloads consume more per task. Demand per customer rises without needing more customers.
- Enterprise contracts lengthen. Multi-year customer commitments on the revenue side offset multi-year obligations on the cost side, which is the natural hedge.
- Scale lowers unit cost. Large committed volumes buy better pricing than anyone purchasing on demand.
The cleanest version of the bull case: the commitments convert an unpredictable supply risk into a predictable cost, in a business where supply has been the thing that limited growth.
What Could Make Them Expensive
The bear case does not require AI demand to collapse. It only requires the economics of compute to move faster than the contracts.
- Efficiency improves faster than demand grows. Better quantisation, more efficient architectures and cheaper serving reduce compute per unit of output. The same revenue then needs less capacity, and contracted capacity goes unused.
- Performance per dollar jumps. A new accelerator generation that is substantially more efficient makes older contracted capacity expensive relative to what is available, exactly as described above.
- Price competition compresses margins. If model API prices keep falling — and they have fallen steeply — revenue per unit of compute falls with them, while the cost per unit is fixed by contract.
- Demand arrives late rather than never. This is the underrated scenario. Contracts ramp on a schedule. If adoption lands two years behind the schedule, the capacity is paid for during the gap.
- Customer concentration bites. Reporting indicates two customers supplied nearly a quarter of 2025 revenue. Concentrated revenue against distributed fixed obligations is an asymmetry worth noting.
- Capital markets tighten. Much of this structure assumes continued access to financing, including the Broadcom facility. The prospectus reportedly warns that certain defaults could both accelerate lease obligations and restrict access to that facility.
None of these is a prediction. They are the variables that would determine whether a commitment of this size reads as strategic or as overextended, and they are the ones worth tracking.
The Valuation Connection
A valuation above $2 trillion — against a self-estimated $965 billion in May — is a statement about future cash flows. Those cash flows depend on revenue growth, gross margin, capital intensity and how much compute each dollar of revenue requires.
What the $518 billion does is make one of those variables visible. Infrastructure spending is normally a forecast assumption that investors argue about. Here, a large portion of it is contracted, dated and disclosed. The spending is no longer a question mark; what remains uncertain is the revenue that has to arrive alongside it.
This is not an argument that the valuation is right or wrong, and this article offers no view on that. The structural observation is narrower: when costs are contractually fixed and revenues are not, the equity absorbs the variance. That is true of any capital-intensive business, and it is unusual to see it at this scale in a company five years old.
The 2025 figures give a sense of the starting point. Revenue of $4.59 billion, operating loss of $8.06 billion, compute and infrastructure spending of $7.33 billion within $12.65 billion of total operating expenses, and $20.28 billion of cash and short-term investments at year end. The headline $42 billion net loss is mostly a non-cash charge of roughly $34 billion tied to the rising estimated value of convertible financing instruments — a number that grows precisely because the company’s valuation grew, and which tells you nothing about operations.
A Note on Governance
Briefly, because it is a separate question from the economics.
Reporting describes a newly created “Founder LLC” comprising Anthropic’s seven co-founders, holding a single Class F share carrying 50.1% of voting power on certain matters including some director elections. The founders direct that share by majority vote. The structure is not permanent: a founder who leaves, dies, sells below a threshold or is removed for cause drops out, and the super-voting class begins to sunset once few enough founders remain.
That is the factual position. Dual-class structures are common in technology listings, and whether this one is appropriate is a judgement for investors rather than for this article. The relevant connection to the rest of the piece is simply that financial scale and governance structure are independent: the commitments would have the same economics under any voting arrangement.
What AI Infrastructure Buyers Should Take From This
Most organisations will never sign a contract with nine zeros. The structural lessons scale down anyway.
- Know which of your compute spend is committed. Reserved instances, savings plans, minimum commitments and capacity reservations all behave like small take-or-pay contracts. The percentage of your bill that is committed is the percentage where utilisation becomes a margin issue.
- Model the shortfall, not just the spend. The question is not what the commitment costs. It is what it costs if you use 60% of it.
- Match contract duration to demand visibility. A three-year commitment against six months of demand visibility is a bet, however good the discount.
- Price the flexibility you are selling. Vendors discount committed volume because certainty is worth something to them. Work out what it is worth to you before trading it away.
- Watch counterparty concentration. If the same vendor supplies, finances and distributes, your exposure to them is larger than any single contract suggests.
- Treat utilisation as a financial metric. Once capacity is committed, the operations team’s efficiency work shows up in gross margin. That changes who should be in the room when it is discussed.
The question this story leaves open is a genuine one. Does committing $518 billion remove Anthropic’s biggest risk — not being able to get compute — or substitute a different one, being obligated to pay for compute whether or not demand arrives on schedule? The answer is that it does both, and which dominates depends on variables that will take years to resolve: utilisation, revenue growth, contract terms nobody outside has seen, compute prices, model efficiency and how quickly hardware generations turn over.
Anyone offering a confident verdict today is working from the same confidential document nobody has read.
FAQ
What are Anthropic’s compute commitments?
Contractual obligations to purchase cloud services, computing capacity and AI infrastructure from named partners over fixed periods. According to a confidential IPO prospectus reviewed by Reuters, they total at least $518 billion over roughly a decade across six partners.
What is the $518 billion figure?
The sum of Anthropic’s disclosed infrastructure commitments: approximately $161.2bn in Broadcom-related equipment leases, $111.1bn with Google, $110bn with Amazon, about $84.5bn for Nvidia-based capacity, $31.4bn with Microsoft and about $20bn with AMD. It is a multi-year obligation, not a current debt or a cash payment.
What does take-or-pay mean here?
That the buyer pays for contracted capacity whether or not it is used. Reuters reported that about 80% of Anthropic’s commitments are non-cancelable or payable regardless of usage, though the specific mechanisms differ by counterparty.
What happens if Anthropic does not use the contracted compute?
Based on the reported terms, it would still owe the money in most cases — through shortfall payments to Google and Amazon, or through lease obligations to Broadcom. The exact provisions cannot be verified while the prospectus stays confidential.
Why would a company commit so much compute?
Because compute availability, not demand, has been the binding constraint on frontier AI development. Long-term commitments secure capacity, lock in pricing, support planning and give priority on new hardware generations — at the cost of financial flexibility.
Who provides Anthropic’s compute?
Six partners per the reported prospectus: Broadcom, Google, Amazon, a provider of Nvidia-based capacity, Microsoft and AMD. Amazon, Google and Microsoft are described as simultaneously investors, customers, cloud providers, distributors and competitors.
What is the Broadcom financing arrangement?
Reuters reported that Broadcom agreed to lend Anthropic up to $42 billion via a convertible note that could fund roughly a third of a five-year, $125.2 billion TPU compute lease. Broadcom may designate a financing partner, and the debt could convert into Anthropic equity.
How do compute commitments affect AI company economics?
They convert a variable cost into a fixed one. That reduces supply risk and increases operating leverage: if capacity is fully used, unit economics improve with scale; if it is not, the unused portion still has to be paid for and effective cost per unit rises.
Keep reading
Here are the latest posts from the blog.
AGI vs Superintelligence: A New Name Isn’t a New Intelligence
AI Coding Agents Are Getting Expensive. Who’s Paying for the Tokens?
Verify Model Weights: 7 Checks Before You Download